\* Another pipeline \`P2\`, may support only following Tasks and Task Sequences:\\ \`\[NMT\]\`\\ \`\[TTS\]\`\\ \`\[NMT+TTS\]\` ## When to use which Pipeline ID? Consider Bhashini provides a few pipelines \`(pipeline ID: P1, P2, etc.)\` that supports some Tasks and Task Sequences. \*\*Case 1:\*\*\\ If the use case is to do only Translation where an integrator wants to translate a given sentence from one language to another in their app/project. For this use case, a pipeline which supports \`\[NMT\]\` shall be used. Since pipeline \`P1\` and \`P2\` both supports \`\[NMT\]\` task, either \`P1\` or \`P2\` can be used.\\ \\ \*\*Case 2:\*\*\\ Consider another use case, where integrator would also want its users to be able to hear the output along with reading which would require both \`NMT\` and \`TTS\` to be done on the input text, integrator will need a pipeline that supports \`\[NMT+TTS\]\`. Since pipeline \`P1\` and \`P2\` both supports \`\[NMT+TTS\]\`, either \`P1\` or \`P2\` can be used.\\ \\ \*\*Case 3:\*\*\\ Consider yet another use case, where integrator wants to take the input in the form of voice and provide a translated text from one language to another. Integrator will, in this case, needs a pipeline which supports \`\[ASR+NMT\]\`. Since only Pipeline \`P1\` supports \`ASR\` and \`NMT\` together, only \`P1\` can be used. \*\*Case 4:\*\*\\ Consider yet another use case, where the integrator wants to utilize ASR from Pipeline \`P1\` and \`\[NMT\]\` from Pipeline \`P2\`. The integrator can achieve this as long as both pipelines point to the same API endpoint and are accessible with the same Authorization Keys.\\ \\ Now, from Case 1 and 2, question arises, which one to use, since both are able to do the required task?\\ Integrators will have a detailed description of the capabilities of the pipeline, the models used in those pipelines, domains to which this pipeline may cater well. e.g. Certain pipelines are made for Medical Domain compared to some other pipeline which may cater to Agriculture domain better.\\ Along with description, there is a Search Pipeline API call as well which provides similar information for automation purposes.\\ Based on the understanding obtained from the portal as well as information obtained from the API, the integrator shall be able to determine which pipeline ID to use if multiple pipelines are available which does the same Tasks/Task Sequences. {% hint style="info" %} Each of these pipelines are uniquely identified by Pipeline ID. Each pipeline can support multiple and/or combination of tasks. {% endhint %} {% hint style="info" %} In each of the Task Sequences, order/sequence of tasks is important. e.g. If a pipeline supports \`\[ASR+NMT+TTS\]\`, it will mean that on the input received, first speech recognition will be done, then it will be translated to another language following which Speech in the target language will be generated. {% endhint %} ## Flow of API calls Integrator shall do following calls to get the output. #### \[Pipeline Search API Call \\\[Optional\\\] \](https://dibd-bhashini.gitbook.io/bhashini-apis/pipeline-search-call) Pipeline Search API Call helps the integrator to search for pipelines that are available to do specific Tasks or Task Sequences and can be used to filter pipeline search based on different parameters.\\ \\ Integrators will be able to obtain \`Pipeline IDs\` required for their project using this call. #### Pipeline Config Call \\\[Mandatory\] Once the integrator obtains the Pipeline ID either via Search Call or ULCA web portal, Pipeline Config call shall be sent to Bhashini along with the specific Task/Task Sequence that integrator want to do using this pipeline. Integrator should make sure that the sequence they are sending shall be supported by this pipeline.\\ There are additional configuration parameters which integrators may or may not send to further filter the response of this config call. #### Pipeline Compute Call \\\[Mandatory\] Pipeline Compute Call is the final call that will help the integrator to obtain the output of the pipeline task sent. ## Language Codes Throughout the APIs, Integrators will see that languages are referred by their language codes. For ex. Language Code for Hindi is hi, English is en, and so on.
{% hint style="info" %} Bhashini follows \[ISO-639 series\](https://www.loc.gov/standards/iso639-2/php/code\_list.php) of language codes. {% endhint %} {% hint style="info" %} Usage of these APIs shall be for the purposes of PoC only. If the Bhashini Sahyogi, Bhashini App Mitra or Bhashini Udyat Mitra wants to use the same on production systems or integrators are charging end-users, please reach out to Bhashini team for the paid version of the APIs and exploring Pricing Plans. {% endhint %} --- # Response Payload | Bhashini APIs For the complete documentation index, see [llms.txt](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt) . This page is also available as [Markdown](https://dibd-bhashini.gitbook.io/bhashini-apis/speaker-diarization-compute-call/response-payload.md) . **Complete payload** Speaker Diarization response[](https://dibd-bhashini.gitbook.io/bhashini-apis/speaker-diarization-compute-call/response-payload#speaker-diarization-response) Copy { "taskType": "speaker-diarization", "output": [\ {\ "speaker_labels": [\ {\ "speaker1": [\ {\ "start_time": 5.44,\ "duration": 1.58\ }\ ]\ }\ ]\ }\ ] } The above JSON Response shows the output of the Speaker Diarization task requested by the integrator in that order. [PreviousRequest Payload](https://dibd-bhashini.gitbook.io/bhashini-apis/speaker-diarization-compute-call/request-payload) [NextPossible Errors](https://dibd-bhashini.gitbook.io/bhashini-apis/possible-errors) Last updated 1 year ago --- # Unknown \> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/pre-requisites-and-onboarding.md). # Pre-requisites and Onboarding This page will help the integrator to get themselves onboarded on Bhashini and get the required API Keys. ## Account Creation Integrator shall onboard themselves on Bhashini via the link below:\\ \\ Registration:

| Sl. No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iitm/asr-dravidian--gpu--t4 | Telugu, Kannada, Malayalam, Tamil | IIT Madras |
| 2 | ai4bharat/conformer-hi-gpu--t4 | Hindi | AI4Bharat |
| 3 | ai4bharat/conformer-multilingual-dravidian-gpu--t4 | Kannada, Malayalam, Tamil, Telugu | AI4Bharat |
| 4 | ai4bharat/conformer-multilingual-indo\_aryan-gpu--t4 | Hindi, Bengali, Marathi, Urdu, Odia, Punjabi, Gujarati, Sanskrit | AI4Bharat |
| 5 | ai4bharat/whisper-medium-en--gpu--t4 | English | AI4Bharat |
| 6 | bhashini/ai4bharat/conformer-multilingual-asr | Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmir, Goan Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Odia, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu, Urdu | AI4Bharat |
| 7 | bhashini/iitm/asr-indoaryan--gpu--t4 | Gujarati, Odia, Hindi, Marathi, Punjabi, Bengali | IIT Madras |
| 8 | bhashini/iitm/asr-misc--gpu--t4 | Bhojpuri, Urdu | IIT Madras |
| 9 | bhashini/iisc/asr-mai-t4 | Maithili | IISC |
| 10 | bhashini/iisc/asr-bho-t4 | Bhojpuri | IISC |
| 11 | bhashini/bodhan/asr-transcribe-flex | English, Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Odia, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu, Urdu, Bhojpuri, Chhattisgarhi, Haryanvi, Bhili | Bodhan.AI |
| 12 | bhashini/bodhan/asr-transcribe-core | English, Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Odia, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu, Urdu, Bhojpuri, Bhili | Bodhan.AI |
| Sl. No | Service ID | Source Language(s) Supported | Target Language(s) Supported | Model Provider |
|---|---|---|---|---|
| 1 | bhashini/iiith/nmt-all | Hindi, English, Assamese, Awadhi, Bengali, Bhojpuri, Braj, Bodo, Dogri, Konkani, Gondi, Gujarati, Hinglish, Ho, Kannada, Kashmiri, Khasi, Mizo, Maithili, Magahi, Malayalam, Marathi, Manipuri, Nepali, Oriya, Punjabi, Sanskrit, Santali, Sinhala, Sindhi, Tamil, Tulu, Telugu, Urdu, Kangri, Kashmiri | Hindi, English, Assamese, Awadhi, Bengali, Bhojpuri, Braj, Bodo, Dogri, Konkani, Gondi, Gujarati, Hinglish, Ho, Kannada, Kashmiri, Khasi, Mizo, Maithili, Magahi, Malayalam, Marathi, Manipuri, Nepali, Oriya, Punjabi, Sanskrit, Santali, Sinhala, Sindhi, Tamil, Tulu, Telugu, Urdu, Kangri, Kashmiri | IIIT Hyderabad |
| 2 | ai4bharat/indictrans-v2-all-gpu--t4 | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali | AI4Bharat |
| 3 | Bhashini/IIITH/Trans/V1 | Hindi, English, Telugu, Odia, Gujarati, Urdu, | Punjabi, Hindi, English, Telugu, Urdu, Gujarati, Odia, Sindhi, Dogri, Kashmiri | IIIT Hyderabad |
| 4 | iitb/trilingual-en\_hi\_mr-v1-gpu--t4 | English, Assamese, Marathi, Hindi | Assamese, Hindi, Bodo, Nepali, English, Marathi, Maithili, Goan Konkani | IIT Bombay |
| 5 | bhashini/aukbc/disco-nmt | Malayalam, Hindi, Tamil | Malayalam, Hindi, Tamil | AUKBC |
| 6 | bhashini/cdac-noida/nmt | English, Hindi, Tamil, Odia , Bengali | English, Hindi, Tamil, Odia , Bengali | CDAC-Noida |
| 7 | bhashini/cdac-pune/nmt | English, Kannada, Gujarati,Malayalam | English, Kannada, Gujarati, Malayalam | CDAC-Pune |
| 8 | bhashini/iitkhg/nmt | Hindi | Sanskrit | IIT Kharagpur |
| 9 | bhashini/bodhan/Indic-trans-v4 | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali | Bodhan.AI |
| 10 | bhashini/iiith/santham/nmt | Sanskrit | Tamil | IIITH |
| Sl. No | Service ID | Source Language(s) Supported | Target Language(s) Supported | Model Provider |
|---|---|---|---|---|
| 1 | ai4bharat/indicxlit--cpu-fsv2 | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali, Punjabi, Maithili, Urdu, Sinhala, Bodo, | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali, Punjabi, Maithili, Urdu, Sinhala, Bodo | AI4Bharat |
| Sl. No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | Bhashini/IITM/TTS | Assamese, Bengali, Bodo, Dogri, English, Gujarati, Hindi, Kannada, Goan Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Odia, Punjabi, Rajasthani, Sanskrit, Tamil, Telugu, Urdu, Santali (Devanagari Script), Sindhi(Devanagari Script), Kashmiri(Devanagari Script) | IIT Madras |
| 2 | ai4bharat/indic-tts-coqui-dravidian-gpu--t4 | Malayalam, Kannada, Tamil, Telugu | AI4Bharat |
| 3 | ai4bharat/indic-tts-coqui-indo\_aryan-gpu--t4 | Hindi, Marathi, Assamese, Bengali, Gujarat, Odia, Rajasthani, Punjabi | AI4Bharat |
| 4 | ai4bharat/indic-tts-coqui-misc-gpu--t4 | English, Manipuri, Bodo | AI4Bharat |
| 5 | Bhashini/IISC/TTS | Kannada, Telugu, English, Hindi, Marathi, Bengali, Gujarati, Maithili, Bhojpuri, Chhattisgarhi, Magahi | IISC (SYSPIN) |
| 6 | bhashini/iisc/sourashtra/tts | Sourashtra, Tamil | IISC |
| 7 | bhashini/bodhan/indic-tts | English, Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali | Bodhan.AI |
| Sl. No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iitmandi/audio-lang-detection/gpu | Assamese, Bengali, English, Hindi, Kannada, Gujarati, Malayalam, Marathi, Odia, Punjabi, Tamil, Telugu | IIT Mandi |
| 2 | bhashini/ald | Goan Konkani, Gujarati, Sanskrit, Telugu, Marathi, Hindi, Odia, Manipuri, Malayalam, Assamese, Dogri, Santali, Tamil, Sindhi, Bengali, Kashmiri, Kannada, Nepali | - |
| Sl. No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/indic-lang-detection-all | Assamese, Bengali, Bodo, Dogri, English, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Oriya, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu, Urdu | AI4Bharat |
| 2 | bhashini/iiiith/indic-lang-detection-all | Assamese, Bengali, English, Gujarati, Hindi, Kannada, Malayalam, Manipuri, Marathi, Oriya, Punjabi, Tamil, Telugu, Urdu | IIIT Hyderabad |
| 3 | bhashini/indic/tld | Assamese(bng script), Bodo, Bangla, Dogri, English, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Odia, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu, Urdu | - |
| Sl. No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iiith/ner | Hindi, Urdu, Odia, Telugu | IIIT Hyderabad |
| 2 | bhashini/ai4bharat/indic-ner | Assamese, Bengali, Gujarati, Hindi, Kannada, Malayalam, Telugu, Marathi, Oriya, Punjabi, Tamil | AI4Bharat |
| 3 | bhashini/aukbc/ner | Hindi, Bengali, Marathi, Punjabi, Kannada, Malayalam, Tamil, English | AUKBC |
| Sl. No | Service ID | Language(s) Supported | Modality | Model Provider |
|---|---|---|---|---|
| 1 | bhashini/iiith-ocr-sceneText-all | Assamese, Bengali, Gujarati, Hindi, Kannada, Malayalam, Manipuri, Marathi, Oriya, Punjabi, Tamil, Telugu, Urdu | Scene Text | IIIT Hyderabad |
| 2 | bhashini/iiith/ocr-hw-bhaasha | Bengali, Hindi, Malayalam, Marathi, Punjabi, Telugu, Kannada, Tamil | Handwritten | IIIT Hyderabad |
| 3 | bhashini/iiith-bhasha-ocr | Assamese, Bengali, Bodo, Dogri, English, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithali, Nepali, Malayalam, Manipuri, Marathi, Oriya, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu | Printed Text | IIIT Hyderabad |
| 4 | bhashini/bodhan/indic-doc/ocr | English, Assamese, Bengali, Bodo, Dogri, Gujarati, Hindi, Kannada, Kashmiri, Konkani, Maithili, Malayalam, Manipuri, Marathi, Nepali, Odia, Punjabi, Sanskrit, Santali, Sindhi, Tamil, Telugu, Urdu. | Printed Text | Bodhan.AI |
| 5 | bhashini/bodhan/indic-doc/ocr | English, Hindi, Bengali, Telugu, Marathi, Tamil, Gujarati, Kannada, Malayalam, Odia, Punjabi, Assamese, Urdu. | Handwritten Text | Bodhan.AI |
| SI.No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iitdharwad/speaker-enrollment | All Languages | IIT Dharwad |
| 2 | bhashini/iitdharwad/speaker-verification | All Languages | IIT Dharwad |
| SI.No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iisc/speaker-diarization | All Languages | IISC |
| 2 | bhashini/speaker-diarization | All Languages | Open Source |
| S.No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/nitk/language-diarization | All Languages | NITK |
| S.No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/ai4b/indicf5-tts | Assamese, Bengali, Gujarati, Hindi, Kannada, Malayalam, Marathi, Odia, Punjabi, Tamil, Telugu. | AI4Bharat |
| S.No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iitm/lip-sync | All Languages | IIT Madras |
| S.No | Service ID | Language(s) Supported | Model Provider |
|---|---|---|---|
| 1 | bhashini/iitg/kws | Bengali, Manipuri, Mizo | IIT Guwahati |
 Both userID and ulcaApiKey can be obtained from the \*\*My Profile\*\* section after logging in.
---
# Unknown
\> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/pipeline-compute-call.md).
# Pipeline Compute Call
This page will help the integrator to get the output of the task sequence requested. This page will detail out the API call, its parameters, understanding of the Input and Output Payloads.
\*\*Endpoint:\*\* Endpoint is obtained from the \*\*\`callbackURL\`\*\* parameter under \[\*\*\`pipelineInferenceAPIEnfPoint\`\*\*\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint) parameter from the Response Payload of \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) as shown \[here.\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint)
\*\*Additional Headers:\*\*\\
auth parameter key\\
auth parameter value
\*\*Payload:\*\*
\* ASR
\* Translation
\* TTS
\* ASR+Translation
\* Translation+TTS
\* ASR+Translation+TTS
## Additional Headers
Below is the understanding and process of obtaining the additional Headers that shall be sent to make the Pipeline Compute API Call. These headers are used for uniquely identifying each integrator for a particular application and authenticate them for the API usage.\\
\\
\*\*auth parameter key\*\*: This value is obtained from \*\*\`name\`\*\* parameter under \*\*\`inferenceApiKey\`\*\* under \[\*\*\`pipelineInferenceAPIEnfPoint\`\*\*\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint).
\*\*auth parameter value\*\*: This value is obtained from \*\*\`value\`\*\* parameter under \*\*\`inferenceApiKey\`\*\* under \[\*\*\`pipelineInferenceAPIEnfPoint\`\*\*\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint).

Complete Payload
{% code lineNumbers="true" %} \`\`\`json { "languages": \[\ {\ "sourceLanguage": "bn",\ "targetLanguageList": \[\ "en",\ "as",\ "gu",\ "hi" \ \]\ },\ {\ "sourceLanguage": "en",\ "targetLanguageList": \[ \ "ml",\ "mr",\ "or",\ "pa",\ "ta",\ "te"\ \]\ }, \ {\ "sourceLanguage": "hi",\ "targetLanguageList": \[\ "en",\ "as",\ "bn",\ "gu",\ "kn"\ \]\ }\ \], "pipelineResponseConfig": \[\ {\ "taskType": "asr",\ "config": \[\ {\ "serviceId": "ai4bharat/conformer-multilingual-indo\_aryan-gpu--t4",\ "modelId": "6411746956e9de23f65b5426",\ "language": {\ "sourceLanguage": "bn"\ },\ "domain": \[\ "general"\ \]\ },\ {\ "serviceId": "ai4bharat/conformer-en-gpu--t4",\ "modelId": "63ee09c3b95268521c70cd7c",\ "language": {\ "sourceLanguage": "en"\ },\ "domain": \[\ "general"\ \]\ },\ {\ "serviceId": "ai4bharat/conformer-multilingual-indo\_aryan-gpu--t4",\ "modelId": "64117455b1463435d2fbaec4",\ "language": {\ "sourceLanguage": "hi"\ },\ "domain": \[\ "general"\ \]\ }\ \]\ },\ {\ "taskType": "tts",\ "config": \[\ {\ "serviceId": "ai4bharat/indic-tts-coqui-misc-gpu--t4",\ "modelId": "63f7384c2ff3ab138f88c64e",\ "language": {\ "sourceLanguage": "en"\ },\ "supportedVoices": \[\ "male",\ "female"\ \]\ },\ {\ "serviceId": "ai4bharat/indic-tts-coqui-indo\_aryan-gpu--t4",\ "modelId": "6348db0bfd966563f61bc2c0",\ "language": {\ "sourceLanguage": "as"\ },\ "supportedVoices": \[\ "male",\ "female"\ \]\ }\ \]\ },\ {\ "taskType": "translation",\ "config": \[\ {\ "serviceId": "ai4bharat/indictrans-fairseq-i2e-gpu--t4",\ "modelId": "6110f7bc014fa35d5e767c3b",\ "language": {\ "sourceLanguage": "bn",\ "targetLanguage": "en"\ }\ },\ {\ "serviceId": "ai4bharat/indictrans-fairseq-i2i-gpu--t4",\ "modelId": "6214b148751fc8007d24084c",\ "language": {\ "sourceLanguage": "bn",\ "targetLanguage": "as"\ }\ },\ {\ "serviceId": "ai4bharat/indictrans-fairseq-e2i-gpu--t4",\ "modelId": "6110f7ce014fa35d5e767c3c",\ "language": {\ "sourceLanguage": "en",\ "targetLanguage": "as"\ }\ },\ {\ "serviceId": "ai4bharat/indictrans-fairseq-e2i-gpu--t4",\ "modelId": "6110f7da014fa35d5e767c3d",\ "language": {\ "sourceLanguage": "en",\ "targetLanguage": "bn"\ }\ }\ \]\ }\ \], "pipelineInferenceAPIEndPoint": { "callbackUrl": "https://dhruva-api.bhashini.gov.in/services/inference/pipeline", "inferenceApiKey": { "name": "Authorization", "value": "cZVqccgm-LTAzxQVp6jjznmSR5RgKM" }, "isMultilingualEnabled": true, "isSyncApi": true } } \`\`\` {% endcode %}Supported Languages for requested Pipeline.
{% code lineNumbers="true" %} \`\`\`json "languages": \[\ {\ "sourceLanguage": "bn",\ "targetLanguageList": \[\ "bn" \ \]\ },\ {\ "sourceLanguage": "en",\ "targetLanguageList": \[ \ "en"\ \]\ }, \ {\ "sourceLanguage": "hi",\ "targetLanguageList": \[\ "hi"\ \]\ }\ \] \`\`\` {% endcode %}Supported Languages for requested Pipeline.
{% code lineNumbers="true" %} \`\`\`json "languages": \[\ {\ "sourceLanguage": "bn",\ "targetLanguageList": \[\ "en",\ "as",\ "gu",\ "hi" \ \]\ },\ {\ "sourceLanguage": "en",\ "targetLanguageList": \[ \ "ml",\ "mr",\ "or",\ "pa",\ "ta",\ "te"\ \]\ }, \ {\ "sourceLanguage": "hi",\ "targetLanguageList": \[\ "en",\ "as",\ "bn",\ "gu",\ "kn"\ \]\ }\ \] \`\`\` {% endcode %}Configuration Details and Service IDs for requested pipeline tasks.
{% code lineNumbers="true" %} \`\`\`json "pipelineResponseConfig": \[\ {\ "taskType": "asr",\ "config": \[\ {\ "serviceId": "ai4bharat/conformer-multilingual-indo\_aryan-gpu--t4",\ "modelId": "6411746956e9de23f65b5426",\ "language": {\ "sourceLanguage": "bn"\ },\ "domain": \[\ "general"\ \]\ },\ {\ "serviceId": "ai4bharat/conformer-en-gpu--t4",\ "modelId": "63ee09c3b95268521c70cd7c",\ "language": {\ "sourceLanguage": "en"\ },\ "domain": \[\ "general"\ \]\ },\ {\ "serviceId": "ai4bharat/conformer-multilingual-indo\_aryan-gpu--t4",\ "modelId": "64117455b1463435d2fbaec4",\ "language": {\ "sourceLanguage": "hi"\ },\ "domain": \[\ "general"\ \]\ }\ \]\ },\ {\ "taskType": "translation",\ "config": \[\ {\ "serviceId": "ai4bharat/indictrans-fairseq-i2e-gpu--t4",\ "modelId": "6110f7bc014fa35d5e767c3b",\ "language": {\ "sourceLanguage": "bn",\ "targetLanguage": "en"\ }\ },\ {\ "serviceId": "ai4bharat/indictrans-fairseq-i2i-gpu--t4",\ "modelId": "6214b148751fc8007d24084c",\ "language": {\ "sourceLanguage": "bn",\ "targetLanguage": "as"\ }\ },\ {\ "serviceId": "ai4bharat/indictrans-fairseq-e2i-gpu--t4",\ "modelId": "6110f7ce014fa35d5e767c3c",\ "language": {\ "sourceLanguage": "en",\ "targetLanguage": "as"\ }\ },\ {\ "serviceId": "ai4bharat/indictrans-fairseq-e2i-gpu--t4",\ "modelId": "6110f7da014fa35d5e767c3d",\ "language": {\ "sourceLanguage": "en",\ "targetLanguage": "bn"\ }\ }\ \]\ },\ {\ "taskType": "tts",\ "config": \[\ {\ "serviceId": "ai4bharat/indic-tts-coqui-misc-gpu--t4",\ "modelId": "63f7384c2ff3ab138f88c64e",\ "language": {\ "sourceLanguage": "en"\ },\ "supportedVoices": \[\ "male",\ "female"\ \]\ },\ {\ "serviceId": "ai4bharat/indic-tts-coqui-indo\_aryan-gpu--t4",\ "modelId": "6348db0bfd966563f61bc2c0",\ "language": {\ "sourceLanguage": "as"\ },\ "supportedVoices": \[\ "male",\ "female"\ \]\ }\ \]\ }\ \] \`\`\` {% endcode %}Details for Actual Inferencing.
{% code lineNumbers="true" %} \`\`\`json "pipelineInferenceAPIEndPoint": { "callbackUrl": "https://dhruva-api.bhashini.gov.in/services/inference/pipeline", "inferenceApiKey": { "name": "Authorization", "value": "cZVqccgm-LTAzxQVp6jjznmSR5RgKM" }, "isMultilingualEnabled": true, "isSyncApi": true } \`\`\` {% endcode %}Complete Payload
{% code lineNumbers="true" %} \`\`\`json { "languages": \[\ {\ "sourceLanguage": "gu",\ "targetLanguageList": \[\ "bn"\ \]\ }\ \], "pipelineResponseConfig": \[\ {\ "taskType": "asr",\ "config": \[\ {\ "serviceId": "ai4bharat/conformer-multilingual-indo\_aryan-gpu--t4",\ "modelId": "6411746056e9de23f65b5425",\ "language": {\ "sourceLanguage": "gu"\ },\ "domain": \[\ "general"\ \]\ }\ \]\ },\ {\ "taskType": "translation",\ "config": \[\ {\ "serviceId": "ai4bharat/indictrans-fairseq-i2i-gpu--t4",\ "modelId": "62023eeb3fc51c3fe32b8c5b",\ "language": {\ "sourceLanguage": "gu",\ "targetLanguage": "bn"\ }\ }\ \]\ },\ {\ "taskType": "tts",\ "config": \[\ {\ "serviceId": "ai4bharat/indic-tts-coqui-indo\_aryan-gpu--t4",\ "modelId": "636e60e586369150cb00432a",\ "language": {\ "sourceLanguage": "bn"\ },\ "supportedVoices": \[\ "male",\ "female"\ \]\ }\ \]\ }\ \], "pipelineInferenceAPIEndPoint": { "callbackUrl": "https://dhruva-api.bhashini.gov.in/services/inference/pipeline", "inferenceApiKey": { "name": "Authorization", "value": "m-LTAzxQVp6jjznmSR5RgKM" }, "isMultilingualEnabled": true, "isSyncApi": true } } \`\`\` {% endcode %}
Both userID and ulcaApiKey can be obtained from the \*\*My Profile\*\* section after logging in.
---
# Unknown
\> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/transliteration-compute-call.md).
# Transliteration Compute Call
- \[Request Payload\](https://dibd-bhashini.gitbook.io/bhashini-apis/transliteration-compute-call/request-payload.md): This sub-page helps the integrator to understand various different types of request payload based on the individual task or combination of tasks in that sequence that integrator wants to do.
- \[Response Payload\](https://dibd-bhashini.gitbook.io/bhashini-apis/transliteration-compute-call/response-payload.md): This sub-page lets the integrator to actually be able to obtain the inference response with the output of individual tasks or tasks sequence in the order requested by the integrator.
---
# Unknown
\> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/pipeline-config-call/request-payload.md).
# Request Payload
This sub-page helps the integrator to understand two different types of request payload, one without any additional configuration parameters, and one with additional configuration parameters.
{% tabs %}
{% tab title="Without configuration parameters" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks" : \[\
{\
"taskType" : "asr"\
},\
{\
"taskType": "translation"\
},\
{ \
"taskType": "tts"\
},\
\
\],
"pipelineRequestConfig" : {
"pipelineId" : "xxxx8d51ae52cxxxxxxxx"
}
}
\`\`\`
{% endcode %}
### Parameters
We will now understand about each parameter available as a part of this payload.\\
\\
\*\*taskType\*\*
\*\*Type:\*\* String
\* Line 3-5 for ASR
\* Line 6-8 for Translation
\* Line 9-11 for TTS
#### pipelineTasks
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* as defined above, that are to be done by the integrator. The sequence of tasks matter. In the above example, the configuration that will be returned back in the response will be for tasks ASR, Translation and TTS in that order.\\
\\
Each \`pipelineId\` (discussed below), may support few individual or task sequences as explained \[here\](/bhashini-apis/overall-understanding-of-the-api-calls.md) and \[here\](/bhashini-apis/overall-understanding-of-the-api-calls.md) and detailed out below.
#### pipelineId
\*\*Type:\*\* String\\
\\
\`pipelineId\` takes a string value of the specific pipeline integrator wants to use. The pipeline ID can be obtained either via Pipeline Search Call or via ULCA Web based on the description which helps the integrator to understand what a pipeline can or cannot do.\\
Each pipeline ID may support multiple task and task sequences.
The same has been explained \[here\](/bhashini-apis/pipeline-search-call.md) and \[here\](/bhashini-apis/overall-understanding-of-the-api-calls.md).
#### pipelineRequestConfig
\*\*Type:\*\* Dictionary\\
\\
This parameter takes in the configuration requested to do the sequence of tasks defined under parameter \[pipelineTasks\](#pipelinetasks).
### Integrators want to do individual tasks
{% tabs %}
{% tab title="Payload for Only ASR" %}
\*\*\`pipelineTasks\`\*\* array takes only one dictionary with \*\*\`taskType\`\*\* as \*\*\`asr\`\*\*
{% code lineNumbers="true" %}
\`\`\`json
"pipelineTasks" : \[\
{\
"taskType" : "asr"\
}\
\]
\`\`\`
{% endcode %}
{% endtab %}
{% tab title="Payload for Only Translation" %}
\*\*\`pipelineTasks\`\*\* array takes only one dictionary with \*\*\`taskType\`\*\* as \*\*\`translation\`\*\*
{% code lineNumbers="true" %}
\`\`\`json
"pipelineTasks" : \[\
{\
"taskType" : "translation"\
}\
\]
\`\`\`
{% endcode %}
{% endtab %}
{% tab title="Payload for Only TTS" %}
\*\*\`pipelineTasks\`\*\* array takes only one dictionary with \*\*\`taskType\`\*\* as \*\*\`tts\`\*\*
{% code lineNumbers="true" %}
\`\`\`json
"pipelineTasks" : \[\
{\
"taskType" : "tts"\
}\
\]
\`\`\`
{% endcode %}
{% endtab %}
{% endtabs %}
### Integrators want to do combination of tasks in that order
{% tabs %}
{% tab title="ASR then Translation" %}
\*\*\`pipelineTasks\`\*\* array takes two dictionaries with \*\*\`taskType\`\*\* as \*\*\`asr\`\*\* and \*\*\`translation\`\*\* in that sequence.
Requesting Server with this in the \*\*\`pipelineTasks\`\*\* parameter would mean that integrator wants to ask the server to give the configuration details where server will be able to perform \*\*\`ASR\`\*\* and \*\*\`Translation\`\*\* together by first doing ASR on the input audio, generating digital text of that audio and then also able to generate translation on the output of that ASR.
{% code lineNumbers="true" %}
\`\`\`json
"pipelineTasks" : \[\
{\
"taskType" : "asr"\
},\
{\
"taskType" : "translation"\
}\
\]
\`\`\`
{% endcode %}
{% endtab %}
{% tab title="Translation then TTS" %}
\*\*\`pipelineTasks\`\*\* array takes two dictionaries with \*\*\`taskType\`\*\* as \*\*\`translation\`\*\* and \*\*\`tts\`\*\* in that sequence.
Requesting Server with this in the \*\*\`pipelineTasks\`\*\* parameter would mean that integrator wants to ask the server to give the configuration details where server will be able to perform \*\*\`Translation\`\*\* and \*\*\`TTS\`\*\* together by first doing Translation on the input text, generating translated text in another language and then also able to generate Speech on the output of that translation.
{% code lineNumbers="true" %}
\`\`\`json
"pipelineTasks" : \[\
{\
"taskType" : "translation"\
},\
{\
"taskType" : "tts"\
}\
\]
\`\`\`
{% endcode %}
{% endtab %}
{% tab title="ASR Then Translation then TTS " %}
\*\*\`pipelineTasks\`\*\* array takes three dictionaries with \*\*\`taskType\`\*\* as \*\*\`asr\`\*\*, \*\*\`translation\`\*\* and \*\*\`tts\`\*\* in that sequence.
Requesting Server with this in the \*\*\`pipelineTasks\`\*\* parameter would mean that integrator wants to ask the server to give the configuration details where server will be able to perform \*\*\`ASR\`\*\*, \*\*\`Translation\`\*\* and \*\*\`TTS\`\*\* together by first performing \*\*\`ASR\`\*\*, thereby generating digital text from the input audio, then doing \*\*\`Translation\`\*\* on the output of previous ASR, thereby generating digital text in another language and finally doing \*\*\`TTS\`\*\* on the output of previous Translation, thereby generating Speech in the required language.
{% code lineNumbers="true" %}
\`\`\`json
"pipelineTasks" : \[\
{\
"taskType" : "asr"\
},\
{\
"taskType" : "translation"\
},\
{\
"taskType" : "tts"\
}\
\]
\`\`\`
{% endcode %}
{% endtab %}
{% endtabs %}
{% endtab %}
{% tab title="With Configuration Parameters" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "asr",\
"config": {\
"language": {\
"sourceLanguage": "xx"\
}\
}\
},\
{\
"taskType": "translation",\
"config": {\
"language": {\
"sourceLanguage": "xx",\
"targetLanguage": "yy"\
}\
}\
},\
{\
"taskType": "tts",\
"config": {\
"language": {\
"sourceLanguage": "yy"\
}\
}\
},\
\
\],
"pipelineRequestConfig": {
"pipelineId" : "xxxx8d51ae52cxxxxxxxx"
}
}
\`\`\`
{% endcode %}
### Parameters
Only additional parameter \`config\` is detailed out below. Rest of the parameters' understanding remains the same as \[#without-configuration-parameters\](#without-configuration-parameters "mention").
#### config
\*\*Type:\*\* dictionary\\
\\
\`config\` parameter is used for sending configuration parameters to the server for each \`taskType\`. Each \`taskType\` may have some common parameters such as \`language\` and some parameters which are specific to each \`taskType\`.
{% hint style="info" %}
Currently, there are no additional \`taskType\` specific parameters. Once added, they will be described here.
{% endhint %}
#### config
{% tabs %}
{% tab title="ASR" %}
\*\*Type:\*\* dictionary
contains:\\
\\
\*\*language\*\*\\
\*\*Type:\*\* dictionary\\
\\
contains:\\
\\
\*\*sourceLanguage\*\*\\
\*\*Type:\*\* String\\
\\
Source Language will take the \[ISO-639 code\](https://bhashini.gitbook.io/bhashini-apis/) of the language as the input. This parameter will tell the server that integrator wants to receive the information and details about Speech Recognition in this specific language.
{% endtab %}
{% tab title="Translation" %}
\*\*Type:\*\* dictionary
contains:\\
\\
\*\*language\*\*\\
\*\*Type:\*\* dictionary\\
\\
contains:\\
\\
\*\*sourceLanguage\*\*\\
\*\*Type:\*\* String\\
\\
Source Language will take the \[ISO-639 code\](https://bhashini.gitbook.io/bhashini-apis/) of the language as the input. This parameter will tell the server that integrator wants to receive the \`Translation\` information where the input can be translated \*\*\`FROM\`\*\* this language to another language specified in the \`targetLanguage\` below.\\
\\
and\\
\\
\*\*targetLanguage\*\*\\
\*\*Type:\*\* String\\
\\
Target Language will also take the \[ISO-639 code\](https://bhashini.gitbook.io/bhashini-apis/) of the language as the input. This parameter will tell the server that integrator wants to receive the \`Translation\` information where the input can be translated \*\*\`TO\`\*\* this language from another language specified un the \`sourceLanguage\` above.
{% hint style="info" %}
If Translation comes after ASR, and ASR is done in, say \`Marathi\`, then Source Language of Translation should be \`Marathi\` (ISO Code \`mr\`) because the output of ASR (Digital text in Marathi) will be fed to Translation Model.\\
\\
However, if Translation is the first task or the only task, integrator shall provide appropriate Source Language based on the use case.
{% endhint %}
{% endtab %}
{% tab title="TTS" %}
\*\*Type:\*\* dictionary
contains:\\
\\
\*\*language\*\*\\
\*\*Type:\*\* dictionary\\
\\
contains:\\
\\
\*\*sourceLanguage\*\*\\
\*\*Type:\*\* String\\
\\
Source Language will take the \[ISO-639 code\](https://bhashini.gitbook.io/bhashini-apis/) of the language as the input. This parameter will tell the server that integrator wants to receive the information and details about converting text to speech for this specific language.
{% hint style="info" %}
If TTS comes after Translation, and Translation is done, say from \`Marathi\` to \`Hindi\`, then Source Language of TTS should be \`Hindi\` (ISO Code \`hi\`) because the output of Translation (Translated text in Hindi) will be fed to Translation Model.\\
\\
However, if Translation is the first task or the only task, integrator shall provide appropriate Source Language based on the use case.
{% endhint %}
{% endtab %}
{% endtabs %}
{% endtab %}
{% endtabs %}
---
# Unknown
\> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/pipeline-compute-call/request-payload.md).
# Request Payload
This sub-page helps the integrator to understand various different types of request payload based on the individual task or combination of tasks in that sequence that integrator wants to do.
## Request Payload for Individual Task
{% tabs %}
{% tab title="ASR" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "asr",\
"config": {\
"language": {\
"sourceLanguage": "xx"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--dddd",\
"audioFormat": "wav",\
"samplingRate": 16000,\
"preProcessors": \[\
"vad"\
\],\
"postProcessors": \[\
"itn"\
\]\
}\
}\
\],
"inputData": {
"input": \[\
{\
"source": null\
}\
\],
"audio": \[\
{\
"audioContent": "{{generated\_base64\_content}}"\
}\
\]
}
}
\`\`\`
{% endcode %}
This response contains 2 major parameters listed below and detailed further down the section:
1. pipelineTasks
2. inputData
### Parameter: \`pipelineTasks\`
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. \\
In the above example, \*\*\`pipelineTasks\`\*\* takes only one dictionary (line 3-13) because integrator wants to do only ASR.\\
\\
\*\*\`taskType\`\*\* parameter takes \`String\` that takes the value \*\*\`asr\`\*\*
\*\*\`config\`\*\* parameter takes a \*\*\`Dictionary\`\*\* that contains following parameters:
{% tabs %}
{% tab title="Language" %}
For ASR, \*\*\`language\`\*\* parameter only takes \*\*\`sourceLanguage\`\*\* which accepts \[ISO-639 Series Code\](/bhashini-apis/overall-understanding-of-the-api-calls.md) of the language.
{% endtab %}
{% tab title="Service ID" %}
serviceId parameter is obtained from the \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) \[response\](/bhashini-apis/pipeline-config-call/response-payload.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineresponseconfig).
{% endtab %}
{% tab title="Audio Format" %}
\*\*\`audioFormat\`\*\* parameter accepts format of the audio which was recorded by the application.
\* For Android, \*\*\`wav\`\*\* is preferred and
\* For iOS, \*\*\`wav\`\*\* or \*\*\`flac\`\*\* is preferred.
However, the Server also accepts other well -known formats such as \*\*\`mp3\`\*\*.
{% endtab %}
{% tab title="Sampling Rate" %}
Sampling Rate is determined by the application at which the audio is recorded. The Server accepts a minimum value of \*\*\`8000\`\*\* for \*\*\`samplingRate\`\*\* parameter.
{% endtab %}
{% endtabs %}
{% hint style="info" %}
Parameters other than \*\*\`taskType\`\*\*, \*\*\`serviceId\`\*\* and \*\*\`config\`\*\* are optional.
{% endhint %}
### Parameter: \`inputData\`
inputData Parameter takes the actual input from the integrator on which the individual task has to be done. It can take the input either via \*\*\`input\`\*\* parameter or \*\*\`audio\`\*\* parameter depending on the task to be done.\\
Since ASR is done on audio input data, for ASR,
\* \*\*\`input\`\*\* parameter is optional, of no use for ASR but
\* \*\*\`audio\`\*\* parameter is mandatory.
\*\*audio\*\* parameter takes \*\*\`audioContent\`\*\* parameter which accepts \*\*\`base64 String\`\*\* of the actual audio captured.
{% hint style="info" %}
If \*\*\`audioFormat\`\*\* or/and \*\*\`samplingRate\`\*\* parameter is/are sent, integrator should make sure that these values correspond to the actual recorded audio.
{% endhint %}
{% endtab %}
{% tab title="Translation" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "translation",\
"config": {\
"language": {\
"sourceLanguage": "hi",\
"targetLanguage": "en"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--dddd",\
"numTranslation": "True"\
}\
}\
\],
"inputData": {
"input": \[\
{\
"source": "मेरा नाम विहिर है और मैं भाषाावर्ष यूज कर रहा हूँ"\
}\
\],
"audio": \[\
{\
"audioContent": null\
}\
\]
}
}
\`\`\`
{% endcode %}
This response contains 2 major parameters listed below and detailed further down the section:
1. pipelineTasks
2. inputData
### Parameter: \`pipelineTasks\`
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. \\
In the above example, \*\*\`pipelineTasks\`\*\* takes only one dictionary (line 3-12) because integrator wants to do only Translation.\\
\\
\*\*\`taskType\`\*\* parameter takes \`String\` that takes the value \*\*\`translation\`\*\*
\*\*\`config\`\*\* parameter takes a \*\*\`Dictionary\`\*\* that contains following parameters:
{% tabs %}
{% tab title="Language" %}
For Translation, \*\*\`language\`\*\* parameter takes both \*\*\`sourceLanguage\`\*\* and \*\*\`targetLanguage\`\*\* which accepts \[ISO-639 Series Code\](https://bhashini.gitbook.io/bhashini-apis/)\[ \](/bhashini-apis/overall-understanding-of-the-api-calls.md)of the language.
{% endtab %}
{% tab title="Service ID" %}
serviceId parameter is obtained from the \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) \[response\](/bhashini-apis/pipeline-config-call/response-payload.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineresponseconfig).
{% endtab %}
{% tab title="numTranslation" %}
numTranslation is a optional parameter which enable the API to translate the numerical data/digit into the respective target language.
this feature is currently enabled only in \*\*ai4bharat/indictrans-v2-all-gpu--t4\*\* service Id and for devanagari script supported languages. Default value is False.
{% endtab %}
{% endtabs %}
### Parameter: \`inputData\`
inputData Parameter takes the actual input from the integrator on which the individual task has to be done. It can take the input either via \*\*\`input\`\*\* parameter or \*\*\`audio\`\*\* parameter depending on the task to be done.\\
Since Transaltion is done on digital text input data, for Translation,
\* \*\*\`input\`\*\* parameter is mandatory and
\* \*\*\`audio\`\*\* parameter is optional and of no use for Translation.
\*\*input\*\* parameter takes \*\*\`source\`\*\* parameter which accepts \*\*\`digital text string\`\*\*.
{% endtab %}
{% tab title="TTS" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[ \
{\
"taskType": "tts",\
"config": {\
"language": {\
"sourceLanguage": "gu"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--dddd",\
"gender": "female",\
"speed": 1.0, // range between 0.1 to 1.99\
"samplingRate": 48000 \
}\
}\
\],
"inputData": {
"input": \[\
{\
"source": "મારું નામ વિહીર છે અને હું ભાષાવર્ષનો ઉપયોગ કરી રહ્યો છું"\
}\
\],
"audio": \[\
{\
"audioContent": null\
}\
\]
}
}
\`\`\`
{% endcode %}
This response contains 2 major parameters listed below and detailed further down the section:
1. pipelineTasks
2. inputData
### Parameter: \`pipelineTasks\`
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. \\
In the above example, \*\*\`pipelineTasks\`\*\* takes only one dictionary (line 3-12) because integrator wants to do only TTS.\\
\\
\*\*\`taskType\`\*\* parameter takes \`String\` that takes the value \*\*\`tts\`\*\*
\*\*\`config\`\*\* parameter takes a \*\*\`Dictionary\`\*\* that contains following parameters:
{% tabs %}
{% tab title="Language" %}
For TTS, \*\*\`language\`\*\* parameter only takes \*\*\`sourceLanguage\`\*\* which accepts \[ISO-639 Series Code\](/bhashini-apis/overall-understanding-of-the-api-calls.md) of the language.
{% endtab %}
{% tab title="Service ID" %}
serviceId parameter is obtained from the \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) \[response\](/bhashini-apis/pipeline-config-call/response-payload.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineresponseconfig).
{% endtab %}
{% tab title="gender" %}
gender parameter takes a string input which can either be:
\* male
\* female
gender parameter tells the server that integrator is requesting the generated speech in either male or female voice.
{% endtab %}
{% tab title="speed" %}
speed parameter takes a integer input which helps in controlling on how fast the synthesized voice speaks. Range between 0.1 to 1.99
\* Increased speed makes the speech sounds quicker, useful for fast-paced content like alerts or summaries.
\* Decreased speed makes the speech is slower and more deliberate, ideal for accessibility or language learning.
{% endtab %}
{% tab title="samplingRate" %}
samplingRate parameter takes a integer value which helps in determining the number of audio samples per second in the generated speech output, measured in Hertz (Hz). It's a key parameter that affects both audio quality and file size.
{% endtab %}
{% endtabs %}
### Parameter: \`inputData\`
inputData Parameter takes the actual input from the integrator on which the individual task has to be done. It can take the input either via \*\*\`input\`\*\* parameter or \*\*\`audio\`\*\* parameter depending on the task to be done.\\
Since TTS is done on digital text input data, for TTS,
\* \*\*\`input\`\*\* parameter is mandatory and
\* \*\*\`audio\`\*\* parameter is optional and of no use for TTS.
\*\*input\*\* parameter takes \*\*\`source\`\*\* parameter which accepts \*\*\`digital text string\`\*\*.
{% endtab %}
{% endtabs %}
## Request Payload for Combination of Tasks in specific sequence
{% tabs %}
{% tab title="ASR+Translation" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "asr",\
"config": {\
"language": {\
"sourceLanguage": "xx"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--dddd",\
"audioFormat": "flac",\
"samplingRate": 16000\
}\
},\
{\
"taskType": "translation",\
"config": {\
"language": {\
"sourceLanguage": "xx",\
"targetLanguage": "yy"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--mfkds"\
}\
}\
\],
"inputData": {
"input": \[\
{\
"source": null\
}\
\],
"audio": \[\
{\
"audioContent": "{{generated\_base64\_content}}"\
}\
\]
}
}
\`\`\`
{% endcode %}
### Parameter: \`pipelineTasks\`
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. \\
In the above example, \*\*\`pipelineTasks\`\*\* takes two dictionaries:
\* Line 3 to 13 i.e., \*\*\`ASR Dictionary\`\*\*
\* Line 14 to 23 i.e., \*\*\`Translation Dictionary\`\*\*
because integrator wants to do \*\*\`ASR\`\*\* of the input voice followed by \*\*\`Translation\`\*\* of the digital text.
\*\*\`Line Number 7\`\*\* and \*\*\`Line Number 18\`\*\* are connected with below understanding. Consider a use-case described below:
Integrator wants to \*\*speak\*\* in say \*\*\`Hindi\`\*\* language and wants to \*\*see\*\* the \*\*translated output\*\* in \*\*\`Marathi\`\*\*. For this to happen, integrator has to:
\* Convert the Audio integrator has spoken to digital text i.e., ASR of Hindi
\* Translate this digital Hindi text to Marathi digital text i.e., Translation from Hindi to Marathi
{% hint style="info" %}
Therefore, the \*\*language code\*\* for \*\*\`ASR\`\*\* that is to be inserted in \*\*Line 7\*\*, shall be \*\*\`hi\`\*\*, i.e., \[ISO 639 series\](/bhashini-apis/overall-understanding-of-the-api-calls.md) code for Hindi. Once this Hindi digital text is generated, the same shall be translated to Marathi, therefore the \*\*source language code\*\* for \*\*\`Translation\`\*\* that is to be inserted in \*\*Line 18\*\*, shall also be \*\*\`hi\`\*\*, which means that \*\*language code\*\* in \*\*Line 7\*\* and \*\*Line 18\*\* shall be same.
For Target Language the code to be inserted in Line 19 shall be \*\*\`mr\`\*\*, i.e., \[ISO 639 series\](/bhashini-apis/overall-understanding-of-the-api-calls.md) code for Marathi.
{% endhint %}
{% hint style="info" %}
Understanding of all other parameters remains same as described above in \[\*\*\`Request Payload for Individual Task\`\*\*\](#request-payload-for-individual-task).
{% endhint %}
{% endtab %}
{% tab title="Translation+TTS" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "translation",\
"config": {\
"language": {\
"sourceLanguage": "hi",\
"targetLanguage": "yy"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--dddd"\
}\
},\
{\
"taskType": "tts",\
"config": {\
"language": {\
"sourceLanguage": "yy"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--csdcxsa",\
"gender": "female"\
}\
}\
\],
"inputData": {
"input": \[\
{\
"source": "मेरा नाम विहिर है और मैं भाषाावर्ष यूज कर रहा हूँ"\
}\
\],
"audio": \[\
{\
"audioContent": null\
}\
\]
}
}
\`\`\`
{% endcode %}
### Parameter: \`pipelineTasks\`
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. \\
In the above example, \*\*\`pipelineTasks\`\*\* takes two dictionaries:
\* Line 3 to 12 i.e., \*\*\`Translation Dictionary\`\*\*
\* Line 13 to 22 i.e., \*\*\`TTS Dictionary\`\*\*
because integrator wants to do \*\*\`Translation\`\*\* of a digital text followed by \*\*\`TTS\`\*\*.
\*\*\`Line Number 8\`\*\* and \*\*\`Line Number 17\`\*\* are connected with below understanding. Consider a use-case described below:
Integrator wants to \*\*translate\*\* say from \*\*\`Hindi\`\*\* to \*\*\`Marathi\`\*\* language and wants to \*\*hear\*\* the \*\*output\*\* in \*\*\`Marathi\`\*\*. For this to happen, integrator has to:
\* Translate this digital Hindi text to Marathi digital text i.e., Translation from Hindi to Marathi
\* Generate this Marathi text speech i.e., TTS of the Marathi digital text.
{% hint style="info" %}
Therefore, the \*\*source language code\*\* for \*\*\`Translation\`\*\* that is to be inserted in \*\*Line 7\*\*, shall be \*\*\`hi\`\*\*, i.e., \[ISO 639 series\](/bhashini-apis/overall-understanding-of-the-api-calls.md) code for Hindi. The \*\*target language code\*\* to be inserted in Line 8 shall be \*\*\`mr\`\*\*, i.e., \[ISO 639 series\](/bhashini-apis/overall-understanding-of-the-api-calls.md) code for Marathi.
Speech shall be generated in Marathi which means the language code to be inserted in \*\*Line 17\*\* shall be \*\*\`mr\`\*\*, same as \*\*Line 8.\*\*
{% endhint %}
{% hint style="info" %}
Understanding of all other parameters remains same as described above in \[\*\*\`Request Payload for Individual Task\`\*\*\](#request-payload-for-individual-task).
{% endhint %}
{% endtab %}
{% tab title="ASR+Translation+TTS" %}
{% code lineNumbers="true" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "asr",\
"config": {\
"language": {\
"sourceLanguage": "xx"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--dddd",\
"audioFormat": "flac",\
"samplingRate": 16000\
}\
},\
{\
"taskType": "translation",\
"config": {\
"language": {\
"sourceLanguage": "xx",\
"targetLanguage": "yy"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--fwsd"\
}\
},\
{\
"taskType": "tts",\
"config": {\
"language": {\
"sourceLanguage": "yy"\
},\
"serviceId": "xxxxx--ssssss-d-ddd--fvdfg",\
"gender": "female"\
}\
}\
\],
"inputData": {
"input": \[\
{\
"source": null\
}\
\],
"audio": \[\
{\
"audioContent": "{{generated\_base64\_content}}"\
}\
\]
}
}
\`\`\`
{% endcode %}
### Parameter: \`pipelineTasks\`
\*\*Type:\*\* Array\\
\\
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator.\\
In the above example, \*\*\`pipelineTasks\`\*\* takes two dictionaries:
\* Line 3 to 13 i.e., \*\*\`ASR Dictionary\`\*\*
\* Line 14 to 23 i.e., \*\*\`Translation Dictionary\`\*\*
\* Line 24 to 33 i.e., \*\*\`TTS Dictionary\`\*\*
because integrator wants to do \*\*\`ASR\`\*\* of the voice input, then \*\*\`Translation\`\*\* of a digital text followed by \*\*\`TTS\`\*\*.
\*\*\`Line Number 7\`\*\* and \*\*\`Line Number 18\`\*\* are connected and \*\*\`Line Number 19\`\*\* and \*\*\`Line Number 28\`\*\* with below understanding. Consider a use-case described below:
Integrator wants to \*\*speak\*\* in say \*\*\`Hindi\`\*\* language and wants to \*\*hear\*\* the \*\*translated output\*\* in \*\*\`Marathi\`\*\*. For this to happen, integrator has to:
\* Convert the Audio integrator has spoken to digital text i.e., ASR of Hindi
\* Translate this digital Hindi text to Marathi digital text i.e., Translation from Hindi to Marathi
\* Generate this Marathi text speech i.e., TTS of the Marathi digital text.
{% hint style="info" %}
Therefore, the \*\*language code\*\* for \*\*\`ASR\`\*\* that is to be inserted in \*\*Line 7\*\*, shall be \*\*\`hi\`\*\*, i.e., \[ISO 639 series\](/bhashini-apis/overall-understanding-of-the-api-calls.md) code for Hindi. Once this Hindi digital text is generated, the same shall be translated to Marathi, therefore the \*\*source language code\*\* for \*\*\`Translation\`\*\* that is to be inserted in \*\*Line 18\*\*, shall also be \*\*\`hi\`\*\*, which means that \*\*language code\*\* in \*\*Line 7\*\* and \*\*Line 18\*\* shall be same.
The \*\*target language code\*\* to be inserted in \*\*Line 19\*\* shall be \*\*\`mr\`\*\*, i.e., \[ISO 639 series\](/bhashini-apis/overall-understanding-of-the-api-calls.md) code for Marathi.
Speech shall be generated in Marathi which means the language code to be inserted in \*\*Line 28\*\* shall be \*\*\`mr\`\*\*, same as \*\*Line 19.\*\*
{% endhint %}
{% hint style="info" %}
Understanding of all other parameters remains same as described above in \[\*\*\`Request Payload for Individual Task\`\*\*\](https://bhashini.gitbook.io/bhashini-apis/)\[.\](#request-payload-for-individual-task)
{% endhint %}
{% endtab %}
{% endtabs %}
## Pre-Processors and Post-Processors within Compute Request
{% tabs %}
{% tab title="ASR" %}
In Automatic Speech Recognition (ASR) systems, preprocessors and postprocessors play a crucial role in refining the audio input and enhancing the textual output, respectively. Below, we provide details on the available preprocessors and postprocessors, along with an example of how to configure them in your request body.
\*\*Preprocessors\*\*
\*\*Voice Activity Detection (VAD)\*\*
\* \*\*Syntax:\*\* \`"preProcessors": \["vad"\]\`
\* \*\*Function:\*\* VAD allows audio content longer than 30 seconds to be passed and processed. It helps identify voice activity to ensure that only the detected voice activity is processed, reducing the load and improving the efficiency of the ASR system.
\*\*Denoiser\*\*
\* \*\*Syntax:\*\* \`"preProcessors": \["denoiser"\]\`
\* \*\*Function:\*\* Denoiser helps in improving the accuracy of speech recognition by reducing background noise from audio inputs.
\*\*Postprocessors\*\*
\*\*Hotwords\*\*
\* \*\*Syntax:\*\* \`"postProcessors": \[{"hotword\_list":\["\`पत्रिका\`"\]}\]\`
\* \*\*Function:\*\* A hotword is postprocessor allows users to share a list of keyword or phrase in which the system is trained to recognize with higher priority or accuracy. This helps in enhancing the ASR performance. This feature is only applicable for Hindi and for service Id "bhashini/ai4bharat/conformer-multilingual-asr".
\*\*Example:\*\* a Hindi news broadcast where words like "पत्रिका" (Magazine) are frequently mentioned. Adding these as hotwords ensures they are transcribed correctly rather than being replaced by phonetically similar but incorrect words
\*\*Inverse Text Normalization (ITN)\*\*
\* \*\*Syntax:\*\* \`"postProcessors": \["itn"\]\`
\* \*\*Function:\*\* ITN converts spoken numbers and dates into their written forms. For example, the ASR would output "two thousand and twenty three" as "2023".
\*\*Punctuation\*\*
\* \*\*Syntax:\*\* \`"postProcessors": \["punctuation"\]\`
\* \*\*Function:\*\* This postprocessor adds punctuations to the ASR output, making the text more readable and closer to natural written language.
\*\*Example:\*\*
\* ASR Output: "hello how are you"
\* Punctuation Output: "Hello, how are you?"
The configuration of preprocessors and postprocessors can be included within the \`config\` section of the request body as shown below:
{% code lineNumbers="true" %}
\`\`\`json
"config": {
"language": {
"sourceLanguage": "xx"
},
"serviceId": "xxxxx--ssssss-d-ddd--dddd",
"audioFormat": "flac",
"samplingRate": 16000,
"preProcessors": \["vad"\],
"postProcessors": \[{\
"hotword\_list": \["पत्रिका", "रंगकर्म", "फिक्र"\]\
}, "itn", "punctuation"\]
}
\`\`\`
{% endcode %}
{% endtab %}
{% tab title="Translation" %}
In translation (NMT) systems, postprocessors play a crucial role in refining the textual output to meet specific needs. Below, we provide details on the postprocessor available for translation, along with an example of how to configure it in your request body.
\*\*Postprocessors\*\*
\*\*Glossary\*\*
\* \*\*Syntax:\*\* \`"postProcessors": \["glossary"\]\`
\* \*\*Function:\*\* The glossary postprocessor allows users to create a list of glossary terms within Bhashini Udyat under the My Profile Section once logged in. Glossary terms created are unique for each Bhashini Inference API Key generated under app names. This postprocessor ensures that specific nouns and noun phrases have their translations overridden as per the user's glossary.
\*\*Example:\*\*
\* Default Translation: "Digital India Bhashini Division" is translated to "डिजिटल इंडिया भैसिनी प्रभाग".
\* With Glossary Term: If the glossary term between English and Hindi is entered as "डिजिटल इंडिया भाषिणी डिवीज़न", this will override the default translation.
\*\*Link to Access My Profile Page and Generate Keys and Glossary:\*\* \[Bhashini Udyat Profile Page\](https://bhashini.gov.in/ulca/profile)
\*\*Glossary Terms Usage:\*\* Glossary terms help provide customized solutions for domain-specific translations, ensuring accuracy and context relevance in the translated output.
\*\*Example of Glossary Usage:\*\*
\* Case sensitivity handling (Ex: Glossary entry - English to Hindi as IPO -> आईपीओ).
\* Glossary entries will work by default for:
1. Entered noun/noun phrase (e.g., IPO)
2. Capitalized case (Ipo)
3. Lower case (ipo)
4. Upper case ( IPO)
5. Reverse case (if आईपीओ is the source, the target is IPO when translating from Hindi to English).
#### Configuration Example
The configuration of the glossary postprocessor can be included within the \`config\` section of the request body as shown below:
{% code lineNumbers="true" %}
\`\`\`json
"config": {
"language": {
"sourceLanguage": "hi",
"targetLanguage": "xx"
},
"postProcessors": \["glossary"\]
"serviceId": "xxxxx--ssssss-d-ddd--dddd"
}
\`\`\`
{% endcode %}
{% endtab %}
{% tab title="TTS" %}
In Text to Speech (TTS) systems, preprocessor, postprocessors play a crucial role in refining the audio output and enhancing the audio quality respectively. Below, we have provide details on the available preprocessor, postprocessors, along with an format of how to configure them in your request body.
\*\*Preprocessors\*\*
\*\*Text Normalization (TN)\*\*
\* \*\*Syntax:\*\* \`"preProcessors": \["text-normalization"\]\`
\* \*\*Function:\*\* It converts numbers and dates into their name forms. For example, the TTS would output "2025" as "two thousand twenty five".
\*\*Postprocessors\*\*
\*\*High Compression\*\*
\* \*\*Syntax:\*\* \`"postProcessors": \["high-compression"\]\`
\* \*\*Function:\*\* This helps minimize audio file size during download without compromising quality, making it suitable for low-bandwidth(network) environment and applications where storage is a primary concern It also speeds up transmission and playback by reducing latency. It gives 64kbps audio.
\*\*Low Compression\*\*
\* \*\*Syntax:\*\* \`"postProcessors": \["low-compression"\]\`
\* \*\*Function:\*\* This helps minimize audio file size during download without a significant loss in audio quality, making it suitable for low-bandwidth(network) environments. It also speeds up transmission and playback by reducing latency. It gives 128kbps audio.
{% endtab %}
{% endtabs %}
---
# Unknown
\> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/pipeline-compute-call/response-payload.md).
# Response Payload
This sub-page lets the integrator to actually be able to obtain the inference response with the output of individual tasks or tasks sequence in the order requested by the integrator.
## Complete Payload
ASR+Translate+TTS
{% code lineNumbers="true" %} \`\`\`json { "pipelineResponse": \[\ {\ "taskType": "asr",\ "config": {\ "serviceId": "ai4bharat/conformer-hi-gpu--t4",\ "language": {\ "sourceLanguage": "hi",\ "sourceScriptCode": ""\ },\ "audioFormat": "flac",\ "encoding": null,\ "samplingRate": 16000,\ "postProcessors": null\ },\ "output": \[\ {\ "source": "मेरा नाम महीर है और मैं भाषा यूज़ कर रहा हूँ"\ }\ \],\ "audio": null\ },\ {\ "taskType": "translation",\ "config": null,\ "output": \[\ {\ "source": "मेरा नाम महीर है और मैं भाषा यूज़ कर रहा हूँ",\ "target": "माझे नाव माहिर आहे आणि मी भाषेच वापरत आहे"\ }\ \],\ "audio": null\ },\ {\ "taskType": "tts",\ "config": {\ "language": {\ "sourceLanguage": "mr",\ "sourceScriptCode": ""\ },\ "audioFormat": "wav",\ "encoding": "base64",\ "samplingRate": 22050,\ "postProcessors": null\ },\ "output": null,\ "audio": \[\ {\ "audioContent": "{{returned\_base64\_content}}",\ "audioUri": null\ }\ \]\ }\ \] } \`\`\` {% endcode %}
{% hint style="info" %} input text content can be added as a value for \*\*source\*\* paramater under \*\*inputData\*\* complex tag {% endhint %} --- # Unknown \> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/transliteration-compute-call/request-payload.md). # Request Payload This sub-page helps the integrator to understand various different types of request payload based on the individual task or combination of tasks in that sequence that integrator wants to do. ## Request Payload for Transliteration Task {% tabs %} {% tab title="Transliteration" %} {% code lineNumbers="true" %} \`\`\`json { "pipelineTasks": \[\ {\ "taskType": "transliteration",\ "config": {\ "language": {\ "sourceLanguage": "en",\ "targetLanguage": "hi"\ },\ "serviceId": "{{trans\_service\_id}}",\ "isSentence": false,\ "numSuggestions": 7\ }\ }\ \], "inputData": { "input": \[\ {\ "source": "ki"\ }\ \] } } \`\`\` {% endcode %} This response contains 2 major parameters listed below and detailed further down the section: 1. pipelineTasks 2. inputData ### Parameter: \`pipelineTasks\` \*\*Type:\*\* Array\\ \\ This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. \\ In the above example, \*\*\`pipelineTasks\`\*\* takes only one dictionary (line 3-13) because integrator wants to do only ASR.\\ \\ \*\*\`taskType\`\*\* parameter takes \`String\` that takes the value \*\*\`asr\`\*\* \*\*\`config\`\*\* parameter takes a \*\*\`Dictionary\`\*\* that contains following parameters: {% tabs %} {% tab title="Language" %} For ASR, \*\*\`language\`\*\* parameter only takes \*\*\`sourceLanguage\`\*\* which accepts \[ISO-639 Series Code\](/bhashini-apis/overall-understanding-of-the-api-calls.md) of the language. {% endtab %} {% tab title="Service ID" %} serviceId parameter is obtained from the \[Transliteration Config Call\](/bhashini-apis/transliteration-config-call.md) \[response\](/bhashini-apis/pipeline-config-call/response-payload.md) as described \[here\](/bhashini-apis/transliteration-config-call/response-payload.md). {% endtab %} {% tab title="isSentence" %} isSentence set to true and false for getting response in sentence. {% endtab %} {% tab title="numSuggestions" %} In the given request, the "numSuggestions" parameter is used in the "transliteration" task configuration. It is used to specify the number of transliteration suggestions that the task should provide. {% endtab %} {% endtabs %} {% hint style="info" %} Parameters other than \*\*\`taskType\`\*\*, \*\*\`serviceId\`\*\* and \*\*\`config\`\*\* are optional. {% endhint %} ### Parameter: \`inputData\` inputData Parameter takes the actual input from the integrator on which the individual task has to be done. It can take the input either via \*\*\`input\`\*\* parameter .
\* \*\*\`input\`\*\* parameter takes the text in source key {% endtab %} {% endtabs %} --- # Unknown \> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/text-language-detection-compute-call.md). # Text Language Detection Compute Call This page will help the integrator to identify the language in an input texts. This page will detail out the API call, its parameters, understanding of the Input and Output Payloads. \*\*Endpoint:\*\* \[\*\*https://dhruva-api.bhashini.gov.in/services/inference/pipeline\*\*\](https://dhruva-api.bhashini.gov.in/services/inference/pipeline) \*\*Additional Headers:\*\* Below is the understanding and process of obtaining the additional Headers that shall be sent to make the Pipeline Config API Call. These headers are used for uniquely identifying each integrator for a particular application and authenticate them for the API usage. \* Accept: \\\*/\\\* \* Authorization: INSERT\\\_API\\\_KEY\\\_HERE \* Content-Type: application/json Authorization : it is a HTTP header which is used to authenticate the user and permission of the requester to use protected resources. Authorization key value can be obtained from the My Profile section under the App name -> inference API key value after logging in to Bhashini-Udyat. Accept : it is a HTTP header which is used to specify the types of content they can process. This helps the server understand what kind of response to send back. Content-Type : it is HTTP header which is used to indicate the media type of the resource being sent. This helps the user understand how to process the content. Below is a screenshot from the Postman. Along with standard headers that are sent automatically, \*\*Authorization, Accept\*\* and \*\*Content-Type\*\* are the additional parameters sent.

 Fill out the details required and click \*\*\`Create Workspace\`\*\* Button.
 Go to a browser window (preferable Chromium based), and open the below URL:
{% hint style="info" %}
 In the box that appears, drag and drop the \*\*\`collection.json\`\*\* file created above.
 Once imported, the collection will look something like below:
 {% hint style="info" %}
The collection is developed directly by Bhashini team and the same may change as per new changes that will be introduced over time.
{% endhint %}
## Accessing Variables
The postman collection has automation done for easy understanding of the integrators. For the same, variables are defined on Collection level.
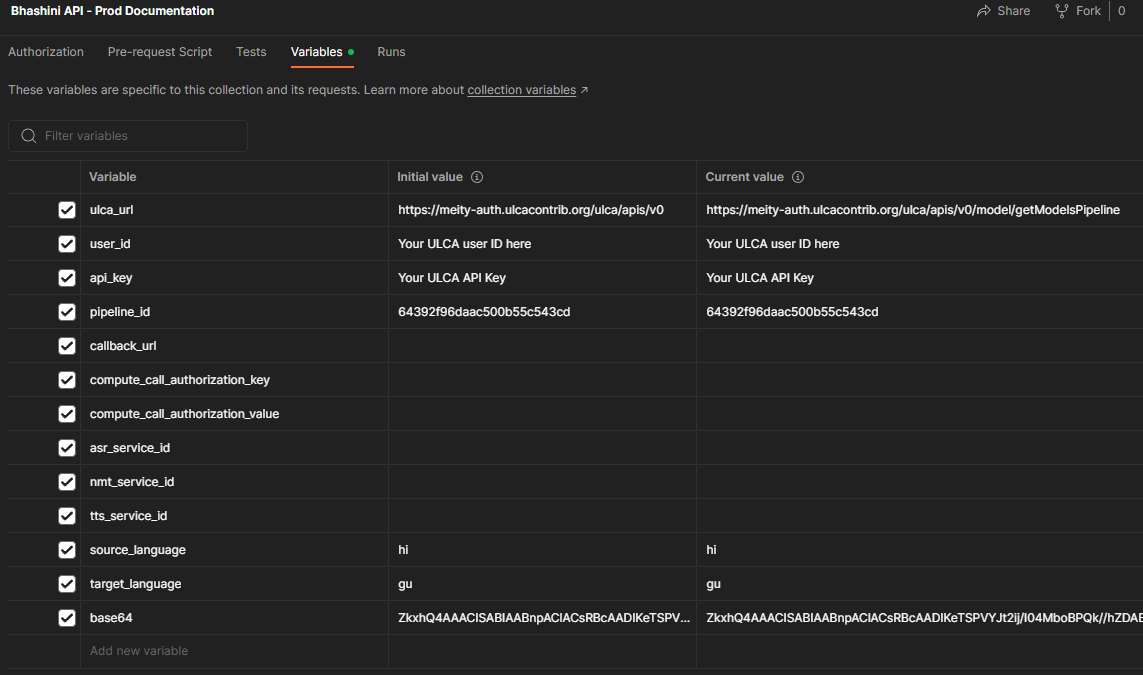
To access these variables, click the \*\*\`Collection Name\`\*\* and then click on \*\*\`Variables\`\*\*.
 This will list down all the variables that are used as a part of different API calls. Details of each variables is given below:
 {% hint style="info" %}
These variables might change as and when new features will be avaiable as a part of different calls. The collection will have to be imported again to receive the updates.
{% endhint %}
\* \*\*\`ulca\_url:\`\*\* ULCA Endpoint to send the \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md)
\* \*\*\`user\_id:\`\*\* ID to uniquely identify each integrator as defined \[here\](/bhashini-apis/pre-requisites-and-onboarding.md#obtaining-user-id).
\* \*\*\`api\_key:\`\*\* API Key as generated by the integrator for a specific application as described \[here\](/bhashini-apis/pre-requisites-and-onboarding.md#api-key-creation).
\* \*\*\`pipeline\_id:\`\*\* Pipeline ID obtained by the integrator either via discussion with Bhashini team, ULCA Web, or \[Pipeline Search Call\](/bhashini-apis/pipeline-search-call.md)
\* \*\*\`callback\_url:\`\*\* URL that is obtained from the response of \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint). This parameter is dynamically allocated with the value as discussed later in this page.
\* \*\*\`callback\_url\_feedback:\`\*\* Feedback URL that is obtained from the response of \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint). This parameter is dynamically allocated with the value as discussed later in this page.
\* \*\*\`compute\_call\_authorization\_key:\`\*\* This is a key parameter which is used for authorization of the \[Pipeline Compute Call\](/bhashini-apis/pipeline-compute-call.md) and is obtained from the response of \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint). This parameter is dynamically allocated with the value as discussed later in this page.
\* \*\*\`compute\_call\_authorization\_value:\`\*\* This is the value of the key above used for authorization of the \[Pipeline Compute Call\](/bhashini-apis/pipeline-compute-call.md) and is obtained from the response of \[Pipeline Config Call\](/bhashini-apis/pipeline-config-call.md) as described \[here\](/bhashini-apis/pipeline-config-call/response-payload.md#parameter-pipelineinferenceapiendpoint). This parameter is dynamically allocated with the value as discussed later in this page.
\* \*\*\`asr\_service\_id:\`\*\* ASR Service ID is the service ID allocated if \*\*ASR\*\* task is requested by the integrator either in individual task or as a combination of tasks and is dynamically allocated either via running \*\*\`With Config Request\`\*\* or \*\*\`Without Config Request\`\*\* as described in \[Request Payload\](/bhashini-apis/pipeline-config-call/request-payload.md).
\* \*\*\`nmt\_service\_id:\`\*\* NMT Service ID is the service ID allocated if \*\*Translation\*\* task is requested by the integrator either in individual task or as a combination of tasks and is dynamically allocated either via running \*\*\`With Config Request\`\*\* or \*\*\`Without Config Request\`\*\* as described in \[Request Payload\](/bhashini-apis/pipeline-config-call/request-payload.md).
\* \*\*\`tts\_service\_id:\`\*\* TTS Service ID is the service ID allocated if TTS task is requested by the integrator either in individual task or as a combination of tasks and is dynamically allocated either via running \*\*\`With Config Request\`\*\* or \*\*\`Without Config Request\`\*\* as described in \[Request Payload\](/bhashini-apis/pipeline-config-call/request-payload.md).
\* \*\*\`source\_language:\`\*\* Source Language takes in \[ISO 639 Series code\](/bhashini-apis/overall-understanding-of-the-api-calls.md) of the source language. Integrator defines this language so that the automation scripts written in Postman find appropriate Service IDs and allocated the \*\*\`asr\_service\_id\`\*\*, \*\*\`nmt\_service\_id\`\*\* and \*\*\`tts\_service\_id\`\*\*.
\* \*\*\`target\_language:\`\*\* Target Language takes in \[ISO 639 Series code\](/bhashini-apis/overall-understanding-of-the-api-calls.md) of the target language. Integrator defines this language so that the automation scripts written in Postman find appropriate Service IDs and allocated the \*\*\`asr\_service\_id\`\*\*, \*\*\`nmt\_service\_id\`\*\* and \*\*\`tts\_service\_id\`\*\*.
\* \*\*\`base64:\`\*\* This is an exemplary base64 content which is used for demo purposes. It can be replaced by the integrator as per their requirements.
\* \*\*\`inference\_input\_payload:\`\*\* This variable will be allocated with a value automatically after execution of the \*\*Postman Tests\*\* associated with and successful execution of \*\*\`Compute Request ASR\`\*\*. This is the input payload that is sent for making the \*\*\`Compute Request ASR\`\*\* API call. This variable will be used in \*\*\`Feedback Submission\`\*\* API Call. This is used for demo of Feedback Submission for \*\*ASR only\*\*. If any other Compute API call is made, developer should use the same input payload used for that particular Compute API which is then to be used for feedback submission.
\* \*\*\`inference\_output\_payload:\`\*\* This variable will be allocated with a value automatically after execution of the \*\*Postman Tests\*\* associated with and successful execution of \*\*\`Compute Request ASR\`\*\*. This is the output/response payload that is received after making a successful \*\*\`Compute Request ASR\`\*\* API call. This variable will be used in \*\*\`Feedback Submission\`\*\* API Call. This is used for demo of Feedback Submission for \*\*ASR only\*\*. If any other Compute API call is made, developer should use the same output/response payload received for that particular Compute API which is then to be used for feedback submission.
\* \*\*\`suggested\_inference\_output\_payload:\`\*\* This variable will have exact same structure as \*\*inference\\\_output\\\_payload\*\* along with the modified values. The concept is that developer is letting the sever know what should have been the response instead of what has currently being received. For ex. Developer send \*\*Compute Request NMT\*\* API call for doing a translation from \*\*English\*\* to \*\*Hindi\*\*. Developer receives a response which contains \*\*Hindi\*\* text somewhere in that response JSON, but the translated text is slightly incorrect. The incorrect part is corrected in the same place in the output response JSON and this new JSON (with edited and corrected \*\*Hindi\*\* text) is sent back to the server as a part of this variable.
### Accessing Automation Scripts
The Automation Scripts are written for \*\*\`With Config Request\`\*\* and \*\*\`Without Config Request\`\*\* API calls so that appropriate collection variables as described above can be allocated.
Once the Integrator clicks either of the API Call mentioned above, Automation Scripts can be accessed in the \*\*\`Tests Tab\`\*\* of that API Call as shown below:
 ### Accessing Individual Calls and Combination Calls
 Each individual as well as combination of tasks can be accessed easily.
---
# Unknown
\> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/speaker-diarization-compute-call/request-payload.md).
# Request Payload
This sub-page helps the integrator to understand various different types of request payload based on the individual task or combination of tasks in that sequence that integrator wants to do.
{% tabs %}
{% tab title="Speaker Diarization" %}
\`\`\`json
{
"pipelineTasks": \[\
{\
"taskType": "speaker-diarization",\
"config": {\
"serviceId": "{{speaker-diarization\_service\_id}}"\
}\
}\
\],
"inputData": {
"audio": \[\
{\
"audioUri": "INSERT\_AUDIO\_URL\_HERE"\
// "audioContent": "INSERT\_BASE64\_AUDIO\_HERE" \
}\
\]
}
}
\`\`\`
{% endtab %}
{% endtabs %}
This request contains 2 major parameters listed below and detailed further down the section:
1. pipelineTasks
2. inputData
\*\*Parameter: \`pipelineTasks\`\*\*
\*\*Type:\*\* Array
This parameter takes an array of tasks, in the form of dictionary of \*\*\`taskType\`\*\* and \*\*\`config\`\*\*, that are to be done by the integrator. In the above example, \*\*\`pipelineTasks\`\*\* takes only one dictionary (line 2-9) because integrator wants to do only Audio language detection. \*\*\`taskType\`\*\* parameter takes \`String\` that takes the value \*\*speaker-diarization.\*\*
\*\*\`config\`\*\* is a single key parameter which maps to another object called \*\*serviceId\*\*
The \*\*\`serviceId\`\*\* parameter is essential for invoking the backend model endpoint for the specified \*\*taskType\*\* with its authentication key. For supported \*\*\`serviceId\`\*\* and \*\*languages\*\* of the Speaker Diarization service, please visit this link.
{% embed url="
Text language Detection response
{% code lineNumbers="true" %} \`\`\`json { "pipelineResponse": \[\ {\ "taskType": "txt-lang-detection",\ "config": null,\ "output": \[\ {\ "source": "INPUT\_TEXT",\ "langPrediction": \[\ {\ "langCode": "LANGUAGE\_CODE",\ "scriptCode": "SCRIPT\_CODE",\ "langScore": "LANGUAGE\_SCORE"\ }\ \]\ }\ \],\ "audio": null\ }\ \] } \`\`\` {% endcode %}{% hint style="info" %} either user can pass \*\*audioUri\*\* as input or \*\*audioContent\*\* as input. {% endhint %} --- # Unknown \> For the complete documentation index, see \[llms.txt\](https://dibd-bhashini.gitbook.io/bhashini-apis/llms.txt). Markdown versions of documentation pages are available by appending \`.md\` to page URLs; this page is available as \[Markdown\](https://dibd-bhashini.gitbook.io/bhashini-apis/audio-language-detection-compute-call.md). # Audio Language Detection Compute Call This page will help the integrator to identify the language spoken in an audio recording. This page will detail out the API call, its parameters, understanding of the Input and Output Payloads. \*\*Endpoint:\*\* \[\*\*https://dhruva-api.bhashini.gov.in/services/inference/pipeline\*\*\](https://dhruva-api.bhashini.gov.in/services/inference/pipeline) \*\*Additional Headers:\*\* Below is the understanding and process of obtaining the additional Headers that shall be sent to make the Pipeline Config API Call. These headers are used for uniquely identifying each integrator for a particular application and authenticate them for the API usage. \* Accept: \\\*/\\\* \* Authorization: INSERT\\\_API\\\_KEY\\\_HERE \* Content-Type: application/json Authorization : it is a HTTP header which is used to authenticate the user and permission of the requester to use protected resources. Authorization key value can be obtained from the My Profile section under the App name -> inference API key value after logging in to Bhashini-Udyat. Accept : it is a HTTP header which is used to specify the types of content they can process. This helps the server understand what kind of response to send back. Content-Type : it is HTTP header which is used to indicate the media type of the resource being sent. This helps the user understand how to process the content. Below is a screenshot from the Postman. Along with standard headers that are sent automatically, \*\*Authorization, Accept\*\* and \*\*Content-Type\*\* are the additional parameters sent.

Transliteration
{% code lineNumbers="true" %} \`\`\`json { "pipelineResponse": \[\ {\ "taskType": "transliteration",\ "config": null,\ "output": \[\ {\ "source": "ki",\ "target": \[\ "की",\ "कि",\ "काई",\ "कीई",\ "काइ",\ "कीइ",\ "कै"\ \]\ }\ \],\ "audio": null\ }\ \] } \`\`\` {% endcode %}