# Table of Contents
- [Welcome | Pathway](#welcome-pathway)
- [Pathway - The first post-transformer frontier model that solved continual learning](#pathway-the-first-post-transformer-frontier-model-that-solved-continual-learning)
- [Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason](#pathway-building-ai-architectures-and-models-that-autonomously-and-continually-learn-evolve-and-reason)
- [Licensing Terms and Conditions | Pathway](#licensing-terms-and-conditions-pathway)
- [Pathway Live Data Framework: Kafka Streams alternative for stream processing](#pathway-live-data-framework-kafka-streams-alternative-for-stream-processing)
- [Privacy policy - GDPR compliance - Equal opportunity employer | Pathway](#privacy-policy-gdpr-compliance-equal-opportunity-employer-pathway)
- [Media Kit | Pathway](#media-kit-pathway)
- [Flink alternative for stream processing with Python - Pathway Live Data Framework](#flink-alternative-for-stream-processing-with-python-pathway-live-data-framework)
- [Pathway Live Data Framework: Spark Streaming alternative for stream processing](#pathway-live-data-framework-spark-streaming-alternative-for-stream-processing)
- [Pathway - Power Your AI with Live Data](#pathway-power-your-ai-with-live-data)
- [Pathway’s BDH solves Sudoku Extreme with 97.4% accuracy, while leading LLMs are close to 0](#pathway-s-bdh-solves-sudoku-extreme-with-97-4-accuracy-while-leading-llms-are-close-to-0)
- [Success Stories | Pathway](#success-stories-pathway)
- [The next Transformer moment for AI - read in Forbes | Pathway](#the-next-transformer-moment-for-ai-read-in-forbes-pathway)
- [License settings | Pathway](#license-settings-pathway)
- [Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason](#pathway-building-ai-architectures-and-models-that-autonomously-and-continually-learn-evolve-and-reason)
- [Pathway Live Data Framework License Key](#pathway-live-data-framework-license-key)
- [Pathway to the Silicon Valley](#pathway-to-the-silicon-valley)
- [WSJ: Pathway marks the beginning of the post-transformer era](#wsj-pathway-marks-the-beginning-of-the-post-transformer-era)
- [Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](#transdev-and-pathway-partner-to-improve-mobility-and-public-transport-performance-through-liveai-)
- [Pathway quoted in the FT: The skeptical case on generative AI](#pathway-quoted-in-the-ft-the-skeptical-case-on-generative-ai)
- [Pathway is featured as a best-suited vendor candidate for Analytics and Decision Intelligence solutions for Supply Chain by Gartner](#pathway-is-featured-as-a-best-suited-vendor-candidate-for-analytics-and-decision-intelligence-solutions-for-supply-chain-by-gartner)
- [Pathway Looks Toward the Post-Transformer Era](#pathway-looks-toward-the-post-transformer-era)
- [As Cohere and Writer mine the ‘LiveAI™’ arena, Pathway joins the pack with a $10M round](#as-cohere-and-writer-mine-the-liveai-arena-pathway-joins-the-pack-with-a-10m-round)
- [AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans | Pathway](#aws-re-invent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans-pathway)
- [How Businesses Can Create Data Frameworks for Real-world AI | Pathway](#how-businesses-can-create-data-frameworks-for-real-world-ai-pathway)
- [Pathway raises $10 million in seed funding round](#pathway-raises-10-million-in-seed-funding-round)
- [Pathway named among the Top Startups Transforming the European business landscape](#pathway-named-among-the-top-startups-transforming-the-european-business-landscape)
- [Pathway is a Representative Vendor in Gartner 2023 Market Guide for Analytics and Decision Intelligence Platforms in Supply Chain](#pathway-is-a-representative-vendor-in-gartner-2023-market-guide-for-analytics-and-decision-intelligence-platforms-in-supply-chain)
- [How 'Neolabs' Are Betting Against the OpenAI Model and What It Means for Founders | Pathway](#how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders-pathway)
- [Industry Leaders Comment On Biggest Lessons From ChatGPT’s Journey So Far | Pathway](#industry-leaders-comment-on-biggest-lessons-from-chatgpt-s-journey-so-far-pathway)
- [CNBC India spotlighting Pathway](#cnbc-india-spotlighting-pathway)
- [100 Women in Tech | Pathway](#100-women-in-tech-pathway)
- [Building Data Frameworks for Real-time AI Applications | Pathway](#building-data-frameworks-for-real-time-ai-applications-pathway)
- [Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929) | Pathway](#dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski-sds-929-pathway)
- [The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain | Pathway](#the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain-pathway)
- [AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency | Pathway](#ai-should-think-like-the-human-brain-dragon-hatchling-bdh-copies-neurons-for-unlimited-context-and-higher-efficiency-pathway)
- [Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](#pathway-ceo-featured-in-the-ranking-of-the-next-generation-of-geniuses-by-the-french-national-weekly-le-point)
- [Interview for Paris-Saclay | Pathway](#interview-for-paris-saclay-pathway)
- [Pathway on BFM Business - the French Business TV channel](#pathway-on-bfm-business-the-french-business-tv-channel)
- [Pathway in Les Echos - CEO Portrait](#pathway-in-les-echos-ceo-portrait)
- [AI startup launches ‘fastest data processing engine’ on the market | Pathway](#ai-startup-launches-fastest-data-processing-engine-on-the-market-pathway)
- [Revealing the First Biological AI: A Step Closer to Singularity | Pathway](#revealing-the-first-biological-ai-a-step-closer-to-singularity-pathway)
- [Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](#pathway-ceo-and-co-founder-predicts-2025-ai-trends-will-your-startup-survive-the-shift-)
- [Tech That Will Change Your Life in 2026 | Pathway](#tech-that-will-change-your-life-in-2026-pathway)
- [Pathway featured in Maddyness 2025 Insights and Predictions](#pathway-featured-in-maddyness-2025-insights-and-predictions)
- [Pathway's BDH: a new post-transformer approach to enterprise AI, on AWS](#pathway-s-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws)
- [CMA CGM Success Story | Pathway](#cma-cgm-success-story-pathway)
- [Formula 1 Team & Pathway success story](#formula-1-team-pathway-success-story)
- [Benchmarks: Fundamental Unlocks for AI | Pathway](#benchmarks-fundamental-unlocks-for-ai-pathway)
- [Opinion: EU could be epicenter of AI academia as US cuts funding | Pathway](#opinion-eu-could-be-epicenter-of-ai-academia-as-us-cuts-funding-pathway)
- [La Poste partners with Pathway to create digital twin of fleet](#la-poste-partners-with-pathway-to-create-digital-twin-of-fleet)
- [Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](#pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
- [LLM series - Pathway: Taking LLMs out of pilot into production](#llm-series-pathway-taking-llms-out-of-pilot-into-production)
- [Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](#joint-support-and-enabling-command-collaborates-with-ai-company-pathway-to-combine-industry-and-military-expertise)
- [ETCIO Southeast Asia covers Pathway Seed Round](#etcio-southeast-asia-covers-pathway-seed-round)
- [A coffee with… Zuzanna Stamirowska | Pathway](#a-coffee-with-zuzanna-stamirowska-pathway)
- [Parisian AI startup Pathway on moving to the US: 'We need to be in the room where it happens, and it happens in the Bay Area](#parisian-ai-startup-pathway-on-moving-to-the-us-we-need-to-be-in-the-room-where-it-happens-and-it-happens-in-the-bay-area)
- [BDH is the second most popular AI paper of 2025 | Pathway](#bdh-is-the-second-most-popular-ai-paper-of-2025-pathway)
- [Pathway launches new post-transformer architecture paving the way for autonomous AI](#pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
- [What the Transformer vs. Post-Transformer debate revealed about AI's next architecture | Pathway](#what-the-transformer-vs-post-transformer-debate-revealed-about-ai-s-next-architecture-pathway)
- [Forbes: Pathway Navigates Next Road For AI Foundational Models](#forbes-pathway-navigates-next-road-for-ai-foundational-models)
- [Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](#pathway-awarded-at-vivatech-by-the-french-prime-minister-elisabeth-borne)
- [Why the Future of AI Will Go Beyond Transformers | Pathway](#why-the-future-of-ai-will-go-beyond-transformers-pathway)
- [The Post-Transformer Era: AI's Next Frontier | NYU x Pathway](#the-post-transformer-era-ai-s-next-frontier-nyu-x-pathway)
- [Victor Szczerba assumes CCO role at Pathway post funding](#victor-szczerba-assumes-cco-role-at-pathway-post-funding)
- [Enabling AI to unlearn and self-correct like a human | Pathway](#enabling-ai-to-unlearn-and-self-correct-like-a-human-pathway)
- [Financial institution & Pathway success story](#financial-institution-pathway-success-story)
- [This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](#this-ai-grows-a-brain-during-training-pathway-s-ai-w-zuzanna-stamirowska-)
- [Embracing Modern Live Data Pipelines is Key to Scaling Enterprise AI | Pathway](#embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai-pathway)
- [Becoming AI-savvy: going beyond data smarts for business transformation | Pathway](#becoming-ai-savvy-going-beyond-data-smarts-for-business-transformation-pathway)
- [Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](#inside-pathway-s-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
- [Female-led deeptech startup Pathway announces its $4.5m pre-seed round](#female-led-deeptech-startup-pathway-announces-its-4-5m-pre-seed-round)
- [From Data-sure To AI-savvy: Unlocking The Next Stage Of Business Transformation | Pathway](#from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation-pathway)
- [Forbes Poland: CEO profile (in Polish) | Pathway](#forbes-poland-ceo-profile-in-polish-pathway)
- [Can an artificial intelligence learn like a human brain does? A startup believes it has achieved this | Pathway](#can-an-artificial-intelligence-learn-like-a-human-brain-does-a-startup-believes-it-has-achieved-this-pathway)
- [Client Testimonial: La Poste at Modern Data Stack | Pathway](#client-testimonial-la-poste-at-modern-data-stack-pathway)
- [Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](#pathway-quoted-in-les-echos-deeptech-the-answer-to-tomorrow-s-challenges)
- [French deep tech start-up announces the general launch of its data processing engine | Pathway](#french-deep-tech-start-up-announces-the-general-launch-of-its-data-processing-engine-pathway)
- [New podcast: Europe’s AI opportunity | Pathway](#new-podcast-europe-s-ai-opportunity-pathway)
- [La Poste Optimizes Colissimo Flows in Real Time - Modern Data Stack Recording available | Pathway](#la-poste-optimizes-colissimo-flows-in-real-time-modern-data-stack-recording-available-pathway)
- [Brain-inspired AI model 'BDH' may surpass the limits of Transformers | Pathway](#brain-inspired-ai-model-bdh-may-surpass-the-limits-of-transformers-pathway)
- [Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](#pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
- [That Hint Where AI Is Heading | Pathway](#that-hint-where-ai-is-heading-pathway)
- [Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](#palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
- [The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain | Pathway](#the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain-pathway)
- [Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series](#zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series)
- [Why today’s AI struggles with the real world, and what comes next | Pathway](#why-today-s-ai-struggles-with-the-real-world-and-what-comes-next-pathway)
- [What Sudoku reveals about the limits of LLMs | Pathway](#what-sudoku-reveals-about-the-limits-of-llms-pathway)
- [DB Schenker & Pathway success story](#db-schenker-pathway-success-story)
- [La Poste & Pathway success story](#la-poste-pathway-success-story)
- [New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim | Pathway](#new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim-pathway)
- [Pathway named as a promising Generative AI leader (in French)](#pathway-named-as-a-promising-generative-ai-leader-in-french-)
- [New AI research claims to be getting closer to modeling human brain | Pathway](#new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain-pathway)
- [BDH: The Missing Link between the Transformer and Models of the Brain | Pathway](#bdh-the-missing-link-between-the-transformer-and-models-of-the-brain-pathway)
- [OpenAI claims AI is making coding jobs better, not worse. Is it true? | Pathway](#openai-claims-ai-is-making-coding-jobs-better-not-worse-is-it-true-pathway)
- [The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski | Pathway](#the-future-of-large-language-models-by-lukasz-kaiser-and-jan-chorowski-pathway)
- [NATO & Pathway success story](#nato-pathway-success-story)
- [Why continual learning and memory matters more than data in the next generation of AI | Pathway](#why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai-pathway)
- [Transdev & Pathway success story](#transdev-pathway-success-story)
- [Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](#transdev-and-pathway-partner-to-improve-mobility-and-public-transport-performance-through-liveai-)
- [Run a template | Pathway](#run-a-template-pathway)
- [How to Use Your Own Components in YAML Configuration | Pathway](#how-to-use-your-own-components-in-yaml-configuration-pathway)
- [Licensing Guide | Pathway](#licensing-guide-pathway)
- [Solutions | Pathway](#solutions-pathway)
- [pathway.persistence package](#pathway-persistence-package)
- [AI Paper Reviewer | LiveAI™ for Conference Classification | Pathway](#ai-paper-reviewer-liveai-for-conference-classification-pathway)
- [Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason](#pathway-building-ai-architectures-and-models-that-autonomously-and-continually-learn-evolve-and-reason)
- [pw.debug | Pathway](#pw-debug-pathway)
- [Adaptive Agents for Real-Time RAG: Domain-Specific AI for Legal, Finance & Healthcare | Pathway](#adaptive-agents-for-real-time-rag-domain-specific-ai-for-legal-finance-healthcare-pathway)
- [pw.demo | Pathway](#pw-demo-pathway)
- [Pathway joins Agoranov, French Science and Tech incubator - in Paris, France](#pathway-joins-agoranov-french-science-and-tech-incubator-in-paris-france)
- [Customizing a RAG Template with YAML | Pathway](#customizing-a-rag-template-with-yaml-pathway)
- [pw.xpacks.connectors | Pathway](#pw-xpacks-connectors-pathway)
- [Financial Report Analysis with LiveAI™ | Pathway](#financial-report-analysis-with-liveai-pathway)
- [How AI Agents in Finance Are Transforming Financial Due Diligence: FA3STER | Pathway](#how-ai-agents-in-finance-are-transforming-financial-due-diligence-fa3ster-pathway)
- [LiveAI™ for SEC Filings Analysis | Pathway](#liveai-for-sec-filings-analysis-pathway)
- [Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason](#pathway-building-ai-architectures-and-models-that-autonomously-and-continually-learn-evolve-and-reason)
- [Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](#can-ai-learn-and-evolve-like-a-brain-pathway-s-bold-research-thinks-so)
- [pw.xpacks.llm | Pathway](#pw-xpacks-llm-pathway)
- [pw.sql | Pathway](#pw-sql-pathway)
- [pw.indexing | Pathway](#pw-indexing-pathway)
- [pw.persistence | Pathway](#pw-persistence-pathway)
- [pw.reducers | Pathway](#pw-reducers-pathway)
- [pw.ml | Pathway](#pw-ml-pathway)
- [pw.udfs | Pathway](#pw-udfs-pathway)
- [Pathway Live Data Framework Templates](#pathway-live-data-framework-templates)
- [pathway.stdlib.indexing package](#pathway-stdlib-indexing-package)
- [Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason](#pathway-building-ai-architectures-and-models-that-autonomously-and-continually-learn-evolve-and-reason)
- [pw.io.null | Pathway](#pw-io-null-pathway)
- [pw.io.slack | Pathway](#pw-io-slack-pathway)
- [pw.io.pubsub | Pathway](#pw-io-pubsub-pathway)
- [pw.io.logstash | Pathway](#pw-io-logstash-pathway)
- [pw.io | Pathway](#pw-io-pathway)
- [pw.io.minio | Pathway](#pw-io-minio-pathway)
- [pw.io.pyfilesystem | Pathway](#pw-io-pyfilesystem-pathway)
- [pw.io.plaintext | Pathway](#pw-io-plaintext-pathway)
- [pw.io.gdrive | Pathway](#pw-io-gdrive-pathway)
- [pw.io.leann | Pathway](#pw-io-leann-pathway)
- [pw.io.milvus | Pathway](#pw-io-milvus-pathway)
- [pw.io.bigquery | Pathway](#pw-io-bigquery-pathway)
- [pw.io.debezium | Pathway](#pw-io-debezium-pathway)
- [pw.io.qdrant | Pathway](#pw-io-qdrant-pathway)
- [pw.io.mqtt | Pathway](#pw-io-mqtt-pathway)
- [pw.io.redpanda | Pathway](#pw-io-redpanda-pathway)
- [pw.io.nats | Pathway](#pw-io-nats-pathway)
- [pw.io.questdb | Pathway](#pw-io-questdb-pathway)
- [pw.io.airbyte | Pathway](#pw-io-airbyte-pathway)
- [pw.io.kinesis | Pathway](#pw-io-kinesis-pathway)
- [pw.io.weaviate | Pathway](#pw-io-weaviate-pathway)
- [pw.io.csv | Pathway](#pw-io-csv-pathway)
- [pw.io.jsonlines | Pathway](#pw-io-jsonlines-pathway)
- [pw.io.pinecone | Pathway](#pw-io-pinecone-pathway)
- [pw.io.chroma | Pathway](#pw-io-chroma-pathway)
- [pw.io.dynamodb | Pathway](#pw-io-dynamodb-pathway)
- [Unknown](#unknown)
- [pw.io.duckdb | Pathway](#pw-io-duckdb-pathway)
- [pw.io.kafka | Pathway](#pw-io-kafka-pathway)
- [pw.io.fs | Pathway](#pw-io-fs-pathway)
- [pw.io.elasticsearch | Pathway](#pw-io-elasticsearch-pathway)
- [pw.io.rabbitmq | Pathway](#pw-io-rabbitmq-pathway)
- [pw.io.clickhouse | Pathway](#pw-io-clickhouse-pathway)
- [pw.io.python | Pathway](#pw-io-python-pathway)
- [pw.io.http | Pathway](#pw-io-http-pathway)
- [pw.io.s3 | Pathway](#pw-io-s3-pathway)
- [pw.io.iceberg | Pathway](#pw-io-iceberg-pathway)
- [pw.io.deltalake | Pathway](#pw-io-deltalake-pathway)
- [pw.io.mssql | Pathway](#pw-io-mssql-pathway)
- [pw.io.mysql | Pathway](#pw-io-mysql-pathway)
- [pw.io.sqlite | Pathway](#pw-io-sqlite-pathway)
- [pw.Table | Pathway](#pw-table-pathway)
- [pw.temporal | Pathway](#pw-temporal-pathway)
- [pw.io.mongodb | Pathway](#pw-io-mongodb-pathway)
- [pw.io.postgres | Pathway](#pw-io-postgres-pathway)
---
# Welcome | Pathway
Welcome to Pathway Live Data Framework Developer Documentation!
===============================================================
The Pathway Live Data Framework is a Python data processing framework for analytics and AI pipelines over data streams. It's the ideal solution for real-time processing use cases like streaming ETL or RAG pipelines for unstructured data.
Getting Started
Install Pathway using `pip`:
`pip install pathway`
[Starting examples](https://pathway.com/developers/user-guide/introduction/first-realtime-app)
Try Our Templates
Pathway offers ready-to-go templates for RAG and ETL pipelines. Run Pathway on your data in minutes.
[Pathway Live Data Framework Templates](https://pathway.com/developers/templates)
[Key Features:](https://pathway.com/developers/#key-features)
--------------------------------------------------------------
* **Easy-to-use Python API**: Pathway Live Data Framework is fully compatible with Python. Use your favorite Python tools and ML libraries.
* **Scalable Rust engine**: your Python code is run by a powerful Rust engine with multithreading and multiprocessing. No JVM and no GIL!
* **Stateful operations**: use stateful and temporal operations such as groupby and windows.
* **Incremental computations**: using Differential Dataflow, Pathway Live Data Framework takes care of out-of-order data points for you, in real time.
* **Batch and streaming alike**: use the same pipeline on static data and live data streams.
* **In-memory data processing**: real-time updates, reduced latency, and higher throughput.
* **Easy to deploy** with Docker or Kubernetes. The Pathway Live Data Framework comes with an orchestrator and is fully compatible with OpenTelemetry.
* **Exactly once consistency**: obtain the same results in both batch and streaming.
* **Persistence and backfilling**: save the state of the computation to quickly resume after a failure or a pipeline update.
* **LLM tooling**: online ML, RAG pipelines, vector indexes... With Pathway Live Data Framework, your ML pipeline works on fresh data.
* **Connect to any data source**: Pathway Live Data Framework comes with 350+ connectors, including SharePoint. Or implement your own.

[What's next?](https://pathway.com/developers/#whats-next)
-----------------------------------------------------------
* [Installation](https://pathway.com/developers/user-guide/introduction/installation)
* [Pathway Overview](https://pathway.com/developers/user-guide/introduction/live-data-framework-overview)
* [Examples](https://pathway.com/developers/user-guide/introduction/first-realtime-app)
* [Core concepts](https://pathway.com/developers/user-guide/introduction/concepts)
* [Why Pathway](https://pathway.com/developers/user-guide/introduction/why-live-data-framework)
* [Streaming and Static Modes](https://pathway.com/developers/user-guide/introduction/streaming-and-static-modes)
* [Batch Processing](https://pathway.com/developers/user-guide/introduction/batch-processing)
* [Deployment](https://pathway.com/developers/user-guide/deployment/cloud-deployment)
* [LLM tooling](https://pathway.com/developers/user-guide/llm-xpack/overview)
[GitHub repository](https://pathway.com/developers/#github-repository)
-----------------------------------------------------------------------
The Pathway Live Data Framework sources are available on GitHub. Don't hesitate to clone the repo and contribute!
[See the sources](https://github.com/pathwaycom/pathway)
[License key](https://pathway.com/developers/#license-key)
-----------------------------------------------------------
Some features of Pathway Live Data Framework such as monitoring or advanced connectors (e.g., SharePoint) require a free license key. To obtain a free license key, you need to register [here](https://pathway.com/get-license)
.
[Introduction\
\
Installation](https://pathway.com/developers/user-guide/introduction/installation)
SearchK
---
# Pathway - The first post-transformer frontier model that solved continual learning
Introducing
BDH
The Dragon Hatchling
==========================
The Post-Transformer frontier model finally delivering on **long-horizon reasoning** and **continual learning**.
Join the waitlist
[Read the paper](https://arxiv.org/abs/2509.26507)
Benchmarks: Fundamental
Unlocks for AI
----------------------------------------
Created by scientists & researchers
-----------------------------------
Neo-lab headed by co-founder & CEO, Zuzanna Stamirowska, CTO Jan Chorowski, and CSO Adrian Kosowski. The team has already built AI tooling, amassing 62k stars on Github. Access our research [here](https://pathway.com/news?tag=research)
×Zuzanna StamirowskaCEO
* Former researcher at the Institute of Complex Systems of Paris
* Researched emergent phenomena and large-scale system evolution
* Recognized by the US National Academy of Sciences for work on emergent behavior in dynamic networks
* On the cover of Le Point as one of the "100 geniuses whose innovation will change the world"
* Graduate of Ecole Polytechnique, PhD in Complex Systems, and expert in Game Theory on graphs

×Adrian KosowskiCSO
* Theoretical computer scientist, mathematician, and quantum physicist
* PhD at 20, tenured at 23 at Inria, former professor at Ecole Polytechnique
* 100+ scientific papers with top contributions to numerous scientific fields
* h-index of 29
* Pioneer of navigable small-world search
* Competitive programmer and coach

×Jan ChorowskiCTO
* First person to apply attention to speech
* Co-author of Nobel Prize Winner Geoff Hinton
* Ex-MILA, ex-Google Brain (Sami Bengio's team)
* Coauthor of Theano
* 14k+ citations, h-index of 24 (Google Scholar)

Neo-lab headed by co-founder & CEO, Zuzanna Stamirowska, CTO Jan Chorowski, and CSO Adrian Kosowski. The team has already built AI tooling, amassing 62k stars on Github. Access our research [here](https://pathway.com/news?tag=research)
Pathway has
continuous backing from
-------------------------------------
Lukasz Kaiser: co-inventor of Transformers, the key researcher behind reasoning breakthroughs from OpenAI.
Martin Farach-Colton: Computer Science and Engineering Chair, NYU. ACM, IEEE, SIAM Fellow.
Jacques Attali: Economist, writer, State Councilor. Founded institutions such as the European Bank for Reconstruction and Development.

---
# Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason
Pathway Careers
===============
---
# Licensing Terms and Conditions | Pathway
Pathway Live Data Framework Licensing Terms and Conditions
==========================================================
The Pathway Live Data Framework comes in three offerings: Community, Scale, and Enterprise.
[Pathway Live Data Framework Community](https://pathway.com/license#pathway-live-data-framework-community)
-----------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework Community is distributed under a free and source-available license: the [**Pathway Live Data Framework Business Source License (BSL)**](https://pathway.com/license#pathway-business-source-license-bsl)
, converting to the open-source Apache 2.0 license after 4 years.
This core product is free for production use, with the exclusion of providers of "Stream Data Processing Services" mentioned in the license, such as cloud hosting providers reselling products to others.
On a historical note, the BSL license originates from [MariaDB](https://mariadb.com/bsl11/)
, and has been adopted by companies such as CockroachDB, Redpanda, ReadySet, and numerous other organizations.
[Pathway Live Data Framework Scale](https://pathway.com/license#pathway-live-data-framework-scale)
---------------------------------------------------------------------------------------------------
The Pathway Live Data Framework Scale is intended for demanding users who need extra features not covered by Pathway Live Data Framework Community, or need to use more resources.
The Pathway Live Data Framework Scale is distributed under the same [**Pathway Live Data Framework Business Source License (BSL)**](https://pathway.com/license#pathway-business-source-license-bsl)
as Pathway Live Data Framework Community. Production use of Pathway Live Data Framework Scale can be activated in source code by using a special function (`pathway.set_license_key`) and requires that the user [obtains a license key](https://pathway.com/framework/get-license)
. License keys come in several tiers, each with different resource limits, and may be free or paid.
By using the Pathway Live Data Framework Scale license key, you additionally acknowledge and agree that anonymized product usage data is sent to Pathway (the company) via an OpenTelemetry collector. This data helps us improve the product and provide better support. All data collected is subject to [Pathway's Privacy Policy](https://pathway.com/privacy_gdpr_di)
. You have the right to review Pathway's Privacy Policy to understand how your data is handled.
[Pathway Live Data Framework Enterprise](https://pathway.com/license#pathway-live-data-framework-enterprise)
-------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework Enterprise includes extensions of Pathway Live Data Framework functionalities particularly useful in enterprise deployments: please take a look at our [feature comparison](https://pathway.com/pricing)
. Use of Pathway Live Data Framework Enterprise is governed by separate commercial licenses. Do not hesitate to reach out to us for more information.
[Learn more](https://pathway.com/developers/user-guide/introduction/installation#pathway-enterprise-package-installation)
about how to install Pathway Live Data Framework Enterprise Package.
[Pathway Live Data Framework Business Source License (BSL)](https://pathway.com/license#pathway-live-data-framework-business-source-license-bsl)
-------------------------------------------------------------------------------------------------------------------------------------------------
`License: BSL 1.1 Licensor: Pathway Technology Inc. and its affiliates, including NavAlgo SAS Licensed Work: Pathway Live Data Framework Releases of Pathway Live Data Framework covered by this License contain a copy of this License as their license file, and are made available by the Licensor at pathway.com, github.com/pathwaycom/, and by way of other distribution channels. The Licensed Work is © 2024 NavAlgo SAS Additional Use Grant: The Licensor grants you (the licensee) additional rights to the Licensed Work, whereby you are entitled to run the Licensed Work in production use, at no cost, subject to all of the following conditions: (a) in a single installation of the Licensed Work you may run the Licensed Work on only one machine, physical or virtual, and without exceeding the number of worker threads and processes allowed by the configuration of the software runner of the distribution; and (b) the additional right to use granted herein applies to the exclusion of use of the Licensed Work for a Stream Data Processing Service, as well as to the exclusion of use of any modified or derivative Licensed Work, in particular: - you may not move, change, disable, or circumvent any license key or resource limiting functionality that may be present in the software, and you may not remove or obscure any functionality in the software that is protected by the license key or circumvent resource limits, - you may not alter, remove, or obscure any licensing, copyright, or other notices of the licensor in the software; (c) the production use of modified Licensed Work is permitted only where the modifications of the Licensed Work are indispensable to fix bugs or vulnerabilities which might otherwise alter the scope of functionalities of the Licensed Work, as described in API documentation available at https://pathway.com/developers/api-docs/pathway; and (d) this entire License including its Additional Use Grant shall remain in full force and effect for any use under this Additional Use Grant, thus covering the Licensed Work and also binding any and all users of the Licensed Work. A “Stream Data Processing Service” is defined as any offering that allows third parties (other than your employees or individual contractors) to access the functionality of the Licensed Work by performing an action directly or indirectly that causes the deployment, creation, or change to the structure of a running computation graph of Pathway on any machine. For the sake of clarity, a Stream Data Processing Service would include providers of infrastructure services, such as cloud services, hosting services, data center services and similarly situated third parties (including affiliates of such entities) that would offer the Licensed Work, possibly in connection with a broader service offering, to their customers or subscribers. Change Date: Change date is four years from the date of code merge into the main release branch of Pathway in the GitHub repo (and in no case earlier than July 20, 2027). Please see GitHub commit history for exact dates. Change License: Apache License, Version 2.0, as published by the Apache Foundation. The Licensor hereby grants you the right to copy, modify, create derivative works, redistribute, and make non-production use of the Licensed Work. The Licensor may make an Additional Use Grant, above, permitting limited production use. Effective on the Change Date, or the fifth anniversary of the first publicly available distribution of a specific version of the Licensed Work under this License, whichever comes first, the Licensor hereby grants you rights under the terms of the Change License, and the rights granted in the paragraph above terminate. If your use of the Licensed Work does not comply with the requirements currently in effect as described in this License, you must purchase a commercial license from the Licensor, its affiliated entities, or authorized resellers, or you must refrain from using the Licensed Work. All copies of the original and modified Licensed Work, and derivative works of the Licensed Work, are subject to this License. This License applies separately for each version of the Licensed Work and the Change Date may vary for each version of the Licensed Work released by Licensor. You must conspicuously display this License on each original or modified copy of the Licensed Work. If you receive the Licensed Work in original or modified form from a third party, the terms and conditions set forth in this License apply to your use of that work. Any use of the Licensed Work in violation of this License will automatically terminate your rights under this License for the current and all other versions of the Licensed Work. This License does not grant you any right in any trademark or logo of Licensor or its affiliates (provided that you may use a trademark or logo of Licensor as expressly required by this License). TO THE EXTENT PERMITTED BY APPLICABLE LAW, THE LICENSED WORK IS PROVIDED ON AN “AS IS” BASIS. LICENSOR HEREBY DISCLAIMS ALL WARRANTIES AND CONDITIONS, EXPRESS OR IMPLIED, INCLUDING (WITHOUT LIMITATION) WARRANTIES OF MERCHANTABILITY, FITNESS FOR A PARTICULAR PURPOSE, NON-INFRINGEMENT, AND TITLE.`
---
# Pathway Live Data Framework: Kafka Streams alternative for stream processing
Kafka Streams vs. Pathway Live Data Framework
=============================================
Explore Pathway Live Data Framework, a source-available Stream Processing Framework, as an alternative to Kafka Streams.
Compare their features, and more to understand their distinctions and benefits.
[Deploy Pathway Live Data Framework](https://pathway.com/developers/user-guide/introduction/welcome)
[Check the comparison spreadsheet](https://docs.google.com/spreadsheets/d/1MZ_ym_LjRKpKNRMLy3Ic9khajAubqJn1fYvXWeqfZ-I/edit?usp=sharing)
[About Pathway Live Data Framework](https://pathway.com/kafka-streams-alternative#about-pathway-live-data-framework)
---------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework is a data processing framework that handles streaming data in a way easily accessible to Python and AI developers. It is a light, next-generation technology developed since 2020, made available for download as a Python-native package from [GitHub](https://github.com/pathwaycom)
and as a Docker image on Dockerhub. The Pathway Live Data Framework handles advanced algorithms in deep pipelines, connects to data sources like Kafka and S3, and enables real-time ML model and API integration for new AI use cases. It is powered by Rust, while maintaining the joy of interactive development with Python. Our Pathway Live Data Framework's performance enables it to process millions of data points per second, scaling to multiple workers, while staying consistent and predictable. The Pathway Live Data Framework covers a spectrum of use cases between classical streaming and data indexing for knowledge management, bringing in powerful transformations, speed, and scale.
[About Kafka Streams](https://pathway.com/kafka-streams-alternative#about-kafka-streams)
-----------------------------------------------------------------------------------------
Kafka Streams is a client library for building applications and microservices, where the input and output data are stored in Kafka clusters. It combines the approach of writing and deploying standard Java and Scala applications on the client side with the benefits of Kafka's server-side cluster technology.
[Feature comparison: Pathway Live Data Framework vs. Kafka Streams](https://pathway.com/kafka-streams-alternative#feature-comparison-pathway-live-data-framework-vs-kafka-streams)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
| | Stream Processing Frameworks | |
| --- | --- | --- |
| Pathway Live Data Framework | Kafka Streams |
| --- | --- | --- |
| Data processing & transformation | | |
| PUSH - data pipelines | | |
| Batch - for SQL use cases | ✅ | ⚠️2 🐌 |
| Batch - for ML/AI use cases | ✅ | ❌ |
| Streaming / live data for SQL use cases | ✅ | ⚠️2 🐌 |
| Streaming / live data for ML/AI use cases | ✅ | ❌ |
| PULL - real-time request serving | | |
| Basic (Real-time feature store) | ✅ | ❌ |
| Advanced (Query API / on-demand API) | ✅ | ❌ |
| Development & deployment effort | | |
| INTERACTIVE DEVELOPMENT - notebooks, data experimentation | | |
| Batch / local data files | ✅ | ❌ |
| Streaming | ✅ | ❌ |
| DEPLOYMENT | | |
| Tests and CI/CD: Local - in process, without cluster | ✅ | ❌ |
| Job management directly through containerized deployment (Kubernetes / Docker) | ✅ | ❌ |
| Horizontal + vertical scaling | ✅ | ✅ |
| Streaming Consistency | | |
| STREAMING CONSISTENCY | ✅ | 😠 |
* ⚠️2: Limited to a subset of SQL, limited JOIN complexity
* 🐌: Not scalable (e.g., local single-threaded only) or posing blocking performance issues
* 😠: Eventual consistency only.
[Key Distinctions Between Pathway Live Data Framework & Kafka Streams](https://pathway.com/kafka-streams-alternative#key-distinctions-between-pathway-live-data-framework-kafka-streams)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [Data processing & transformation](https://pathway.com/kafka-streams-alternative#data-processing-transformation)
* Pathway Live Data Framework supports both PUSH and PULL models for data pipelines, including batch processing for SQL and ML/AI use cases and streaming/live data for SQL and deep computations for ML/AI use cases. Kafka Streams supports similar functionality for SQL use cases but with limitations on JOIN complexity. It does not deliver for AI/ ML use cases. [Read](https://pathway.com/blog/streaming-benchmarks-pathway-fastest-engine-on-the-market#benchmark-results)
our 2023 WordCount and PageRank Benchmarks to learn more.
* Pathway Live Data Framework provides basic and advanced real-time request serving capabilities, including a real-time feature store and advanced query APIs. Kafka Streams lacks support for real-time request serving.
### [Development & deployment effort](https://pathway.com/kafka-streams-alternative#development-deployment-effort)
The Pathway Live Data Framework allows [interactive development](https://pathway.com/developers/user-guide/deployment/from-jupyter-to-deploy#introduction)
with support for both batch and streaming data. Deployment is supported through tests, CI/CD, and containerized deployment with Kubernetes/Docker. Kafka Streams lacks interactive development support and has limited deployment options.
### [Streaming Consistency](https://pathway.com/kafka-streams-alternative#streaming-consistency)
Both Pathway Live Data Framework and Kafka Streams provide streaming consistency, but our Pathway Live Data Framework complies with internal consistency, while Kafka Streams is limited to eventual consistency, potentially not meeting user expectations. We strongly recommend O'Reilly 2024 edition of [Streaming Databases](https://www.oreilly.com/library/view/streaming-databases/9781098154820/)
, and specifically Chapter 6 on Streaming Consistency.
[Benefits of Pathway Live Data Framework](https://pathway.com/kafka-streams-alternative#benefits-of-pathway-live-data-framework)
---------------------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework is used to create Python code which seamlessly combines batch processing, streaming, and real-time APIs for LLM apps. Its distributed runtime (🦀-🐍) provides fresh results for your data pipelines whenever new inputs and requests are received.
The Pathway Live Data Framework was initially designed to be a life-saver (or at least a time-saver) for Python developers and ML/AI engineers faced with live data sources, where you need to react quickly to fresh data. Our Pathway Live Data Framework provides a high-level programming interface in Python for defining data transformations, aggregations, and other operations on data streams. With Pathway Live Data Framework, you can effortlessly design and deploy sophisticated data workflows that efficiently handle high volumes of data in real-time.
The Pathway Live Data Framework is interoperable with various data sources and sinks such as Kafka, CSV files, SQL/NoSQL databases, and REST APIs, allowing you to connect and process data from different storage systems. Typical use-cases include real-time data processing, ETL (Extract, Transform, Load) pipelines, data analytics, monitoring, anomaly detection, and recommendation. The Pathway Live Data Framework can also independently provide the backbone of a light LLMops stack for [real-time LLM applications](https://github.com/pathwaycom/llm-app)
.
The Pathway Live Data Framework excels in offering a comprehensive set of features for data processing and transformation, with relatively lower development and deployment effort.
[Limitations of Kafka Streams](https://pathway.com/kafka-streams-alternative#limitations-of-kafka-streams)
-----------------------------------------------------------------------------------------------------------
* The use of the JVM: Like any Java application, Kafka Streams relies on the Java Virtual Machine (JVM), which leads to performance overhead and resource utilization concerns. The JVM's garbage collection mechanism can introduce latency and memory management issues, impacting the overall efficiency of Kafka Streams applications, especially in high-throughput scenarios. Additionally, the JVM's memory requirements and runtime overhead may lead to higher resource consumption and increased operational costs.
* Complexity of State Management: Handling stateful operations in Kafka Streams can be complex, especially when dealing with state stores that need to be fault-tolerant and scalable.
* Limited Integration with External Systems: While Kafka Streams integrates seamlessly with Apache Kafka, its integration with external systems may not be as robust. Connecting to non-Kafka data sources or sinks might require additional workarounds or custom solutions.
* Lack of Built-in Windowing Support: Although Kafka Streams offers windowing operations for processing time-based or session-based data, its windowing capabilities may not be as advanced or flexible as some other stream processing frameworks.
* Complex Event Processing: Kafka Streams primarily focuses on stream processing tasks such as filtering, mapping, and aggregating events. It may not be well-suited for complex event processing scenarios that require sophisticated event pattern matching or temporal reasoning.
[FAQs](https://pathway.com/kafka-streams-alternative#faqs)
-----------------------------------------------------------
What would you say is the main differentiation between Pathway Live Data Framework and Kafka Streams?
Running machine learning (ML) models in a streaming environment presents a myriad of challenges that can quickly turn into headaches for data scientists and ML engineers. Kafka Streams is not optimized for streaming ML/AI workloads, leading to bottlenecks and inefficiencies. Kafka Streams’ stack components fail to keep up with the high velocity of incoming data, resulting in lagging processing times and increased latency. Handling multiple joins, transformations, and model updates in real-time can also quickly overwhelm the system, leading to resource contention and degraded performance. For data scientists and ML engineers accustomed to interactive development environments and Python-based ML tooling, transitioning to a streaming environment can be a jarring experience. Debugging pipelines becomes a painstaking process, exacerbated by the lack of real-time feedback and visibility into the streaming data flow. The journey from development to scaling is fraught with challenges, often resulting in unpredictable results and consistency issues. Without years of experience with a particular analytics engine such as Kafka Streams, predicting the running speed and resource utilization of ML workloads in a streaming context is difficult. Unforeseen bottlenecks and performance quirks can derail even the most carefully crafted ML pipelines, leading to frustration and delays in deployment. Additionally, Kafka Stream's dependence on the Java ecosystem may limit flexibility and introduce compatibility challenges.
The Pathway Live Data Framework as a high-throughput, low-latency data processing framework solves those problems for Python & ML/AI developers.
---
# Privacy policy - GDPR compliance - Equal opportunity employer | Pathway
Privacy policy - GDPR compliance - Equal opportunity employer
=============================================================
Pathway is a registered trademark. For general inquiries, please write to [contact@pathway.com](mailto:contact@pathway.com)
.
This website is operated by Pathway Technology, 418 Florence Street, Palo Alto, CA 94301, USA.
* * *
[Privacy Policy](https://pathway.com/privacy_gdpr_di#privacy-policy)
---------------------------------------------------------------------
We are committed to protecting your privacy and handling your personal data in compliance with the California Consumer Privacy Act (CCPA), the EU-U.S. Data Privacy Framework Principles, the European Union General Data Protection Regulation (GDPR), and other applicable international regulations. By providing us with your personal data, you are giving us your permission to process it on Pathway’s secure cloud, to manage our customer database, to improve the quality of our services and to inform you about our product. You may request us to delete your personal data at any time.
[Types of Personal Data We Collect](https://pathway.com/privacy_gdpr_di#types-of-personal-data-we-collect)
-----------------------------------------------------------------------------------------------------------
We collect the following types of personal data:
* **Contact Information**: Name, email address, phone number
* **Technical Data**: Cookies
* **Communication Data**: Messages and inquiries sent to us
[Purposes of Data Processing](https://pathway.com/privacy_gdpr_di#purposes-of-data-processing)
-----------------------------------------------------------------------------------------------
We process your personal data for the following purposes:
* **Service Delivery**: To manage our customer database, book meetings, process requests and invoices.
* **Service Improvement**: To improve the quality of our services
* **Communication**: To respond to your inquiries and provide customer support
* **Marketing**: To inform you about our products and services
We use Calendly, LLC to manage meeting bookings. Calendly, LLC collects and processes personal data on our behalf, the processing of this data is limited to scheduling purposes. Calendly, LLC complies with the EU-U.S. Data Privacy Framework (EU-U.S. DPF).
[Your Rights and Choices](https://pathway.com/privacy_gdpr_di#your-rights-and-choices)
---------------------------------------------------------------------------------------
### [Right to Access and Control](https://pathway.com/privacy_gdpr_di#right-to-access-and-control)
You have the right to:
* **Access**: Request a copy of the personal data we hold about you
* **Correction**: Request correction of inaccurate, incomplete, or irrelevant personal data
* **Deletion**: Request deletion of your personal data at any time
* **Opt-Out**: Limit the use and disclosure of your personal data
* **Object**: Object to processing of your personal data for certain purposes
To exercise any of these rights, please contact us at [contact@pathway.com](mailto:contact@pathway.com)
with a written, signed, and dated request, along with proof of your identity. We will respond to your request within fifteen (15) business days.
### [Right to Be Informed](https://pathway.com/privacy_gdpr_di#right-to-be-informed)
You may send any questions about the storage and processing of your data to [contact@pathway.com](mailto:contact@pathway.com)
.
**Data Retention**
* Data transmitted via our contact form is stored on our database for a maximum period of one (1) year, then deleted
* When you make a booking, your data is stored to process your request and is deleted one (1) year after your last booking
* A confirmation email sent to you contains a link to delete your personal data with one click
[Cookies](https://pathway.com/privacy_gdpr_di#cookies)
-------------------------------------------------------
We occasionally use cookies on our website to help us improve our service. A cookie is a small file that is saved to your computer by a website: it can be recovered on future visits to the same website. A cookie can only be read by the website that created it. Most cookies only work during a single browsing session or visit. None of the cookies we use contain information that could lead to you being contacted by telephone, email or post. You can set your web browser to tell you every time a cookie is created or to prevent them from being created.
[Publication and sharing of your personal data - Legal Requirements](https://pathway.com/privacy_gdpr_di#publication-and-sharing-of-your-personal-data-legal-requirements)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Pathway Technology Inc. may be required to disclose personal data:
* In response to lawful requests by public authorities, including to meet national security or law enforcement requirements
* To comply with a request from a legal authority or current legislation or regulations
* As part of legal proceedings initiated by Pathway Technology Inc. to protect or defend our rights, assets, or those of our customers
* In exceptional circumstances to protect the personal safety of users of our products and/or website or the general public
We do not sell, share, or otherwise disclose personal information obtained through meeting bookings to any third parties for their own marketing purposes.
[International Transfers](https://pathway.com/privacy_gdpr_di#international-transfers)
---------------------------------------------------------------------------------------
Personal data from the European Union may be transferred to and processed in the United States in accordance with the EU-U.S. DPF Principles.
[Recourse, Enforcement, and Liability](https://pathway.com/privacy_gdpr_di#recourse-enforcement-and-liability)
---------------------------------------------------------------------------------------------------------------
### [Complaints and Inquiries](https://pathway.com/privacy_gdpr_di#complaints-and-inquiries)
In compliance with the EU-U.S. DPF, Pathway Technology Inc. commits to resolve DPF Principles-related complaints about our collection and use of your personal information. EU individuals with inquiries or complaints regarding our handling of personal information received in reliance on the EU-U.S. DPF should first contact Pathway Technology Inc. at: [contact@pathway.com](mailto:contact@pathway.com)
.
Please allow a reasonable amount of time to respond to your request.
### [Independent Dispute Resolution](https://pathway.com/privacy_gdpr_di#independent-dispute-resolution)
Pathway Technology Inc. commits to resolve complaints about our collection or use of your personal information. Individuals in the European Union with inquiries or complaints regarding our handling of personal data under the EU-U.S. Data Privacy Framework should first contact Pathway Technology Inc. at [contact@pathway.com](mailto:contact@pathway.com)
.
Pathway Technology Inc. has further committed to cooperate with the European Data Protection Authorities (DPAs) with regard to unresolved complaints concerning data transferred from the EU under the DPF Principles. EU individuals may refer unresolved complaints to the panel established by the European DPAs. This independent dispute resolution mechanism is provided free of charge to you.
Pathway Technology Inc. will comply with the advice given by the DPAs with respect to non-human resources data transferred from the EU.
### [Additional Recourse Options](https://pathway.com/privacy_gdpr_di#additional-recourse-options)
If these processes do not result in a resolution, you may contact your local data protection authority, the U.S. Department of Commerce, and/or the Federal Trade Commission for assistance.
### [Binding Arbitration](https://pathway.com/privacy_gdpr_di#binding-arbitration)
Under certain circumstances, you may invoke binding arbitration for complaints regarding EU-U.S. DPF compliance not resolved by any of the other DPF mechanisms. This binding arbitration option is available to you to determine, for residual claims, whether Pathway Technology Inc. has violated its obligations to you under the EU-U.S. DPF Principles, and whether any such violation remains fully or partially unremedied. This option is available only for these purposes. Please be advised that the arbitrator(s) may only impose individual-specific, non-monetary, equitable relief necessary to remedy any violation of the EU-U.S. DPF Principles with respect to you. For additional information about the arbitration process, please visit: [https://www.dataprivacyframework.gov/s/article/ANNEX-I-introduction-dpf?tabset-35584=2](https://www.dataprivacyframework.gov/s/article/ANNEX-I-introduction-dpf?tabset-35584=2)
.
[Data Security](https://pathway.com/privacy_gdpr_di#data-security)
-------------------------------------------------------------------
Your personal data is processed and stored on Pathway's secure cloud infrastructure. We implement appropriate technical and organizational measures to protect your personal data against unauthorized access, alteration, disclosure, or destruction.
[Breach of Privacy](https://pathway.com/privacy_gdpr_di#breach-of-privacy)
---------------------------------------------------------------------------
If, at any time, you think that our website has breached your privacy, please tell us at [contact@pathway.com](mailto:contact@pathway.com)
. We will then take all necessary steps to investigate and correct this problem.
[EU-U.S. Data Privacy Framework Principles](https://pathway.com/privacy_gdpr_di#eu-us-data-privacy-framework-principles)
-------------------------------------------------------------------------------------------------------------------------
Pathway Technology Inc. complies with the EU-U.S. Data Privacy Framework (EU-U.S. DPF) as set forth by the U.S. Department of Commerce. Pathway Technology Inc. has certified to the U.S. Department of Commerce that it adheres to the EU-U.S. Data Privacy Framework Principles (EU-U.S. DPF Principles) with regard to the processing of personal information received from the European Union in reliance on the EU-U.S. DPF. If there is any conflict between the terms in this privacy policy and the EU-U.S. DPF Principles, the Principles shall govern. To learn more about the Data Privacy Framework (DPF) program, and to view our certification, please visit [https://www.dataprivacyframework.gov/](https://www.dataprivacyframework.gov/)
.
Pathway Technology Inc. is responsible for the processing of personal information we receive, and subsequently transfer to a third party acting as an agent on our behalf. Pathway Technology Inc. complies with the EU-U.S. DPF Principles for all onward transfers of personal information from the EU, including the onward transfer liability provisions.
Pathway Technology Inc. is subject to the investigatory and enforcement powers of the U.S. Federal Trade Commission (FTC). In certain situations, Pathway Technology Inc. may be required to disclose personal information in response to lawful requests by public authorities, including to meet national security or law enforcement requirements.
[Equal Opportunity Employer](https://pathway.com/privacy_gdpr_di#equal-opportunity-employer)
---------------------------------------------------------------------------------------------
Pathway Technology Inc. is an equal opportunity employer committed to diversity and inclusion in the workplace.
---
# Media Kit | Pathway
Media kit
=========
[About Pathway](https://pathway.com/media-kit#about-pathway)
-------------------------------------------------------------
Pathway is building AI architectures and models that autonomously and continually learn, evolve, and reason.
[About BDH](https://pathway.com/media-kit#about-bdh)
-----------------------------------------------------
BDH is a post-Transformer AI architecture built around one premise: intelligence should not have to choose between reasoning and memory. Rather than bolting memory onto a language model from the outside, BDH makes memory, adaptation, and inference part of the same computational fabric.
The design is brain-inspired, but not brain-imitative. It draws on principles biology got right, namely local interaction, sparse activity, persistent state, and continual adjustment, and applies them to a modern sequence model.
The result is a different path forward for AI. BDH keeps the strengths of language models, but pushes beyond token-by-token processing toward parallel latent reasoning, the kind of internal structure needed for models that do not just generate answers, but work through problems.
[About the Team](https://pathway.com/media-kit#about-the-team)
---------------------------------------------------------------
Pathway is led by co-founder & CEO Zuzanna Stamirowska, a complexity scientist who created a team consisting of AI pioneers, including CTO Jan Chorowski who was the first person to apply Attention to speech and worked with Nobel laureate Geoff Hinton at Google Brain, as well as CSO Adrian Kosowski, a leading computer scientist and quantum physicist who obtained his PhD at the age of 20.
The company is backed by leading investors and advisors, including Lukasz Kaiser, co-author of the Transformer (“the T” in ChatGPT). Pathway is headquartered in Palo Alto, CA.
[Pathway logo](https://pathway.com/media-kit#pathway-logo)
-----------------------------------------------------------

Black
[svg](https://pathway.com/assets/design/logo/pathway-logo-dark.svg)
[ai](https://pathway.com/assets/design/logo/pathway-logo-black.ai)
[png](https://pathway.com/assets/design/logo/pathway-logo-black.png)
[jpg](https://pathway.com/assets/design/logo/pathway-logo-black.jpg)

White
[svg](https://pathway.com/assets/design/logo/pathway-logo-white.svg)
[png](https://pathway.com/assets/design/logo/pathway-logo-white.png)
[ai](https://pathway.com/assets/design/logo/pathway-logo-white.ai)

Favicon - Profile image
[png](https://pathway.com/assets/design/logo/Profile-image.png)
[ico](https://pathway.com/favicon.ico)
[Headshots](https://pathway.com/media-kit#headshots)
-----------------------------------------------------

Zuzanna Stamirowska (CEO) - Vertical[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Zuzanna-Stamirowska-CEO_1.jpg)

Zuzanna Stamirowska (CEO) - Vertical[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Zuzanna-Stamirowska-CEO_2.jpg)

Zuzanna Stamirowska (CEO) - Vertical[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Zuzanna-Stamirowska-CEO_3-(Vertical).jpg)

Zuzanna Stamirowska (CEO) - Horizontal[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Zuzanna-Stamirowska-CEO_4-(Horizontal).jpg)

Zuzanna Stamirowska (CEO) - Horizontal[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Zuzanna-Stamirowska-CEO_5.jpg)

Zuzanna Stamirowska (CEO) - Horizontal[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Zuzanna-Stamirowska-CEO_6.jpg)
[Pathway members](https://pathway.com/media-kit#pathway-members)
-----------------------------------------------------------------
### [Founder Headshots - Vertical](https://pathway.com/media-kit#founder-headshots-vertical)

Zuzanna Stamirowska (CEO) - Vertical[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Pathway-Zuzanna-Stamirowska-(CEO)-Vertical-2.jpg)

Claire Nouet (COO) - Vertical[](https://www.linkedin.com/in/clairenouet/)
[jpg](https://pathway.com/assets/design/Pathway-Claire-Nouet-(COO)-Vertical.jog.jpg)

Jan Chorowski (CTO)- Vertical[](https://www.linkedin.com/in/janchorowski/)
[jpg](https://pathway.com/assets/design/Pathway-Jan-Chorowski-(CTO)-Vertical.jpg)

Adrian Kosowski (CSO) Vertical[](https://www.linkedin.com/in/kosowski/)
[jpg](https://pathway.com/assets/design/Pathway-Adrian-Kosowski-(CSO)-Vertical.jpg)
### [Founder Headshots - Horizontal](https://pathway.com/media-kit#founder-headshots-horizontal)

Zuzanna Stamirowska (CEO) - Horizontal[](https://www.linkedin.com/in/stamirowska/)
[jpg](https://pathway.com/assets/design/Pathway-Zuzanna-Stamirowska-(CEO)-Horizontal-2.jpg)

Zuzanna (CEO) and Claire (COO) - Horizontal
[jpg](https://pathway.com/assets/design/Pathway-Zuzanna-(CEO)-and-Claire-(COO)-Horizontal.jpg)

Adrian Kosowski (CSO) Horizontal[](https://www.linkedin.com/in/kosowski/)
[jpg](https://pathway.com/assets/design/Pathway-Adrian-Kosowski-(CSO)-Horizontal.jpg)
* * *
---
# Flink alternative for stream processing with Python - Pathway Live Data Framework
Flink vs. Pathway Live Data Framework
=====================================
Explore Pathway Live Data Framework, a source-available Stream Processing Framework, as an alternative to Flink.
Compare their features, and more to understand their distinctions and benefits.
[Deploy Pathway Live Data Framework](https://pathway.com/developers/user-guide/introduction/welcome)
[Check the comparison spreadsheet](https://docs.google.com/spreadsheets/d/1MZ_ym_LjRKpKNRMLy3Ic9khajAubqJn1fYvXWeqfZ-I/edit?usp=sharing)
[About Pathway Live Data Framework](https://pathway.com/flink-alternative#about-pathway-live-data-framework)
-------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework is a data processing framework that handles streaming data in a way easily accessible to Python and AI developers. It is a light, next-generation technology developed since 2020, made available for download as a Python-native package from [GitHub](https://github.com/pathwaycom)
and as a Docker image on Dockerhub. The Pathway Live Data Framework handles advanced algorithms in deep pipelines, connects to data sources like Kafka and S3, and enables real-time ML model and API integration for new AI use cases. It is powered by Rust, while maintaining the joy of interactive development with Python. The Pathway Live Data Framework's performance enables it to process millions of data points per second, scaling to multiple workers, while staying consistent and predictable. The Pathway Live Data Framework covers a spectrum of use cases between classical streaming and data indexing for knowledge management, bringing in powerful transformations, speed, and scale.
[About Flink](https://pathway.com/flink-alternative#about-flink)
-----------------------------------------------------------------
Apache Flink is a framework and distributed processing engine for stateful computations over unbounded and bounded data streams. Flink has been designed to run in clustered environments, performing computations in-memory at speed and at any scale. With its long history and active community support, Flink remains a top choice for organizations seeking to unlock insights from their streaming data sources.
[Feature comparison: Pathway Live Data Framework vs. Flink](https://pathway.com/flink-alternative#feature-comparison-pathway-live-data-framework-vs-flink)
-----------------------------------------------------------------------------------------------------------------------------------------------------------
| Feature | Pathway Live Data Framework | Apache Flink |
| --- | --- | --- |
| General | | |
| Processing Type | Stream and batch (with the same engine).
Guarantees of same results returned whether running in batch or streaming.
Capacity for asynchronous stream processing and API integration. | Stream and batch (with different engines). |
| Programming language APIs | Python, SQL | JVM (Java, Kotlin, Scala), SQL, Python |
| Programming API | Table API | DataStream API and Table API, with partial compatibility |
| Software integration ecosystems/plugin formats. | Python,
C binary interface (C, C++, Rust),
REST API. | JVM |
| Ease of development | | |
| How to QuickStart | Get Python.
Do \`pip install pathway\`.
Run directly. | Get Java.
Download and unpack Flink packages.
Start a local Flink Cluster with \`./bin/start-local.sh\`.
Use netcat to start a local server.
Submit your program to the server for running. |
| Running local experiments with data | Use Pathway Live Data Framework locally in VS Code, Jupyter, etc. | Based on local Flink clusters |
| CI/CD and Testing | Usual CI/CD setup for Python (use GitHub Actions, Jenkins etc.)
Simulated stream library for easy stream testing from file sources. | Based on local Flink cluster integration into CI/CD pipelines |
| Interactive work possible? | Yes, data manipulation routines can be interactively created in notebooks and the Python REPL | Compilation is necessary, breaking data-scientist's flow of work |
| Performance | | |
| Scalability | Horizontal\* and vertical scaling.
Scales to thousands of cores and terabytes of application state.
Standard and custom libraries (including ML library) are scalable. | Horizontal and vertical scaling.
Scales to thousands of cores and terabytes of application state.
Most standard libraries (including ML library) do not parallelize in streaming mode. |
| Performance for basic tasks (groupby, filter, single join) | Delivers high throughput and low latency. | Slower than Pathway Live Data Framework in benchmarks. |
| Transformation chain length in batch computing | 1000+ transformations possible, iteration loops possible | Max. 40 transformations recommended (in both batch and streaming mode). |
| Fast advanced data transformation (iterative graph algorithms, machine learning) | In batch and streaming mode. | No; restricted subset possible in batch mode only. |
| Parameter tuning required | Instance sizing only.
Possibility to set window cut-off times for late data. | Considerable tuning required for streaming jobs. |
| Architecture and deployment | | |
| Distributed Deployment (for Kubernetes or bare metal clusters) | Pool of identical workers (pods).\*
Sharded by data. | Includes a JobManager and pool of TaskManagers.
Work divided by operation and/or sharded by data. |
| Dataflow handling and communication | Entire dataflow handled by each worker on a data shard, with asynchronous communication when data needs routing between workers.
Backpressure built-in. | Multiple communication mechanisms depending on configuration.
Backpressure handling mechanisms needed across multiple workers. |
| Internal Incremental Processing Paradigm | Commutative
(based on record count deltas) | Idempotent
(upsert) |
| Primary data structure for state | Multi-temporal Log-structured merge-tree (shared arrangements).
In-memory state. | Log-structured merge-tree.
In-memory state. |
| State Management | Integrated with computation.
Cold-storage persistence layer optional.
Low checkpointing overhead.\* | Integrated with computation.
Cold-storage persistence layer optional. |
| Semantics of stream connectors | Insert / Upsert | Insert / Upsert |
| Message Delivery Guarantees | Ensures exactly-once delivery guarantees for state and outputs (if enabled) | Ensures exactly-once delivery guarantees for state and outputs (if enabled) |
| Consistency | Consistent, with exact progress tracking. Outputs reflect all data contained in a prefix of the source streams. All messages are atomically processed, if downstream systems have a notion of transaction no intermediate states are sent out of the system. | Eventually consistent, with approximate progress tracking using watermarks. Outputs may reflect partially processed messages and transient inconsistent outputs may be sent out of the system. |
| Processing out-of-order data | Supported by default.
Outputs of built-in operations do not depend on data arrival order (unless they are configured to ignore very late data).
Event times used for windowing and temporal operations. | Supported or fragile, depending on the scenario. Event time processing supported in addition to arrival time and approximate watermarking semantics. |
| Fault tolerance | Rewind-to-snapshot.
Partial failover handled transparently in hot replica setups.\* | Rewind-to-snapshot.
Support for partial failover present or not depending on scheduler. |
| Monitoring system | Prometheus-compatible endpoint on each pod | |
| Logging system | Integrates with Docker and Kubernetes Container logs | |
| Machine Learning support | | |
| Language of ML library implementation | Python / Pathway Live Data Framework | JVM / Flink |
| Parallelism support by ML libraries | ML libraries scale vertically and horizontally | Most ML libraries are not built for parallelization |
| Supported modes of ML inference | CPU Inference on worker nodes.
Asynchronous Inference (GPU/CPU).
Alerting of results updates after model change. | CPU Inference on worker nodes. |
| Supported modes of ML learning | Add data to the training set.
Update or delete data in the training set.
Revise past classification decisions. | Add data to the training set. |
| Representative real-time Machine Learning libraries. | Classification (including kNN), Clusterings, graph clustering, graph algorithms, vector indexes, signal processing.
Geospatial libraries, spatio-temporal data, GPS and trajectories.\*
Possibility to integrate external Python real-time ML libraries. | Classification (including kNN), Clusterings, vector indexes. |
| Support for iterative algorithms (iterate until convergence, gradient descent, etc.) | Yes | No |
| API Integration with external Machine Learning models and LLMs | Yes | No / fragile |
| Typical Analytics and Machine Learning use cases | Data fusion
Monitoring and alerting (rule-based or ML-powered)
IoT and logs data observability (rule-based or ML-powered)
Trajectory mining\*
Graph learning
Recommender systems
Ontologies and dynamic knowledge graphs.
Real-time data indexing (vector indexes).
LLM-enabled data pipelines and RAG services.
Low-latency feature stores. | Monitoring and alerting (rule-based)
IoT and logs data observability (rule-based) |
| API and HTTP microservices | | |
| REST/HTTP API integration | Non-blocking (Asynchronous API calls) supported in addition to Synchronous calls. | Blocking (Synchronous calls) |
| Acting as microservice host | Provides API endpoint mechanism for user queries.
Supports registered queries (API session mechanism, alerting). | No |
| Use as low-latency feature store | Yes, standalone. From 1ms latency. | Possible in combination with Key-value store like Redis. From 5ms latency.
Requires manual versioning/consistency checks. |
[Key Distinctions Between Pathway Live Data Framework & Flink](https://pathway.com/flink-alternative#key-distinctions-between-pathway-live-data-framework-flink)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------
### [Data processing & transformation](https://pathway.com/flink-alternative#data-processing-transformation)
* **Data Pipelines**: Pathway Live Data Framework offers both batch and streaming/live data processing capabilities, for SQL use cases and ML/AI use cases. While Flink provides robust data processing and transformation functionalities for SQL use cases, it is slow on ML/AI use cases in batch and hardly delivers on streaming ML/AI use cases. Read our 2023 [WordCount and PageRank Benchmarks](https://pathway.com/blog/streaming-benchmarks-pathway-fastest-engine-on-the-market#benchmark-results)
to learn more.
* Pathway Live Data Framework supports real-time feature store functionalities, whereas Flink alone does not. Flink can be integrated with other tools such as Redis or Druid to obtain such functionality. The Pathway Live Data Framework enables Query API and on-demand API with minimal effort, while Flink alone does not. Further combining Flink with Druid would allow for External ML integration (SQL-first processing).
### [Development & deployment effort](https://pathway.com/flink-alternative#development-deployment-effort)
* **Interactive Development**: Pathway Live Data Framework supports [interactive development](https://pathway.com/developers/user-guide/deployment/from-jupyter-to-deploy#introduction)
through notebooks and data experimentation with ease, while Flink's development and deployment is good for batch / local data files but is lacking in this area for streaming.
* **Deployment**: Tests and CI/CD can be done with Pathway Live Data Framework in a local Python environment, without launching a cluster. Job management in the framework can be done directly through containerized deployment (with Kubernetes or Docker). Flink, either as a standalone stream processing framework or combined with Druid or Redis, requires the launching of a Flink cluster to which jobs are sent.
* Both frameworks support horizontal and vertical scaling effectively.
### [Streaming Consistency](https://pathway.com/flink-alternative#streaming-consistency)
Flink does not support data consistency. As written in the great 2024 O'Reilly [Streaming Databases](https://www.oreilly.com/library/view/streaming-databases/9781098154820/)
book, and more specifically in Chapter 6 - “classical stream processors `[like Flink] (...)` guarantee only a weaker form of consistency called eventual consistency.”
The Pathway Live Data Framework, on the other side, supports a “stronger form of consistency where every output is the correct output for a subset of the inputs” - also called internal consistency.
### [Usability](https://pathway.com/flink-alternative#usability)
The native development stack for Flink is based on the Java Virtual Machine, so it provides excellent support for code developed in Java or Scala. The Support for Python in Flink is based on a wrapper API's which is not considered a roadmap priority, is often incomplete and lags in features compared to the Java version. Flink has very limited schema and type validation, and provides very limited syntax help in Visual Studio Code and other development environments. Pathway is natively Python and provides advanced Python library integration, full schema and type validation at the time of job preparation, and a python-native integration experience for syntax help with Visual Studio Code and other development environments. Both Pathway Live Data Framework and Flink provide a layer for expressing data transformations in SQL.
[Benefits of Pathway Live Data Framework](https://pathway.com/flink-alternative#benefits-of-pathway-live-data-framework)
-------------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework is used to create Python code which seamlessly combines batch processing, streaming, and real-time APIs for LLM apps. Its distributed runtime (🦀-🐍) provides fresh results for your data pipelines whenever new inputs and requests are received.
The Pathway Live Data Framework was initially designed to be a life-saver (or at least a time-saver) for Python developers and ML/AI engineers faced with live data sources, where you need to react quickly to fresh data. The Pathway Live Data Framework provides a high-level programming interface in Python for defining data transformations, aggregations, and other operations on data streams. With Pathway Live Data Framework, you can effortlessly design and deploy sophisticated data workflows that efficiently handle high volumes of data in real-time.
The Pathway Live Data Framework is interoperable with various data sources and sinks such as Kafka, CSV files, SQL/NoSQL databases, and REST APIs, allowing you to connect and process data from different storage systems. Typical use-cases include real-time data processing, ETL (Extract, Transform, Load) pipelines, data analytics, monitoring, anomaly detection, and recommendation. The framework can also independently provide the backbone of a light LLMops stack for [real-time LLM applications](https://github.com/pathwaycom/llm-app)
.
The Pathway Live Data Framework excels in offering a comprehensive set of features for data processing and transformation, with relatively lower development and deployment effort.
[Limitations of Flink](https://pathway.com/flink-alternative#limitations-of-flink)
-----------------------------------------------------------------------------------
Flink presents strong data processing capabilities but lags in deployment ease and interactive development support.
Developing applications in Flink can be more complex compared to some other stream processing frameworks due to its focus on low-level APIs and concepts like state management. This complexity may require developers to invest more time in understanding Flink's architecture and APIs.
Flink's support for interactive development, such as interactive notebooks or REPL (Read-Eval-Print Loop) environments, is not as mature as some other frameworks. This can make it challenging for developers to rapidly prototype and experiment with their code.
Although Flink can be used for machine learning and AI tasks, its support for these use cases may not be as extensive as dedicated ML/AI frameworks. The support for ML/AI with streaming data is extremely slow and limited. Integrating Flink with ML/AI libraries and tools may require additional effort and customization.
[FAQs](https://pathway.com/flink-alternative#faqs)
---------------------------------------------------
What would you say is the main differentiation between Pathway Live Data Framework and Flink?
The Pathway Live Data Framework's strongest long-term differentiation lies in the use cases that our framework opens up, compared to incumbent streaming technologies. The Pathway Live Data Framework enables real-time machine learning, unlearning, graph algorithms, and other advanced transformations, all on live data. It is a fundamental shift compared to what was possible until now. In fact, the [logistics and moving assets](https://pathway.com/framework/solutions/logistics)
use cases are great examples of this, so are [RAG pipelines](https://pathway.com/framework/solutions)
for document streams and data intelligence. The Pathway Live Data Framework effectively pushes the AI field forward.
---
# Pathway Live Data Framework: Spark Streaming alternative for stream processing
Spark Streaming vs. Pathway Live Data Framework
===============================================
Explore Pathway Live Data Framework, a source-available Stream Processing Framework, as an alternative to Spark Streaming.
Compare their features, and more to understand their distinctions and benefits.
[Deploy Pathway Live Data Framework](https://pathway.com/developers/user-guide/introduction/welcome)
[Check the comparison spreadsheet](https://docs.google.com/spreadsheets/d/1MZ_ym_LjRKpKNRMLy3Ic9khajAubqJn1fYvXWeqfZ-I/edit?usp=sharing)
[About Pathway Live Data Framework](https://pathway.com/spark-streaming-alternative#about-pathway-live-data-framework)
-----------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework is a data processing framework that handles streaming data in a way easily accessible to Python and AI developers. It is a light, next-generation technology developed since 2020, made available for download as a Python-native package from [GitHub](https://github.com/pathwaycom)
and as a Docker image on Dockerhub. The Pathway Live Data Framework handles advanced algorithms in deep pipelines, connects to data sources like Kafka and S3, and enables real-time ML model and API integration for new AI use cases. It is powered by Rust, while maintaining the joy of interactive development with Python. The Pathway Live Data Framework's performance enables it to process millions of data points per second, scaling to multiple workers, while staying consistent and predictable. The Pathway Live Data Framework covers a spectrum of use cases between classical streaming and data indexing for knowledge management, bringing in powerful transformations, speed, and scale.
[About Spark Streaming](https://pathway.com/spark-streaming-alternative#about-spark-streaming)
-----------------------------------------------------------------------------------------------
Spark Streaming is an extension of the core Spark API that enables scalable, high-throughput, fault-tolerant stream processing of live data streams. Data can be ingested from many sources like Kafka, Kinesis, or TCP sockets, and can be processed using complex algorithms that can be expressed with high-level functions like map, reduce, join and window. Finally, processed data can be pushed out to filesystems, databases, and live dashboards.
[Feature comparison: Pathway Live Data Framework vs. Spark Streaming](https://pathway.com/spark-streaming-alternative#feature-comparison-pathway-live-data-framework-vs-spark-streaming)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [Key Distinctions](https://pathway.com/spark-streaming-alternative#key-distinctions)
| | Stream Processing Frameworks | |
| --- | --- | --- |
| Pathway Live Data Framework | Spark / Databricks |
| --- | --- | --- |
| Data processing & transformation | | |
| PUSH - data pipelines | | |
| Batch - for SQL use cases | ✅ | ✅ |
| Batch - for ML/AI use cases | ✅ | ✅ |
| Streaming / live data for SQL use cases | ✅ | ⚠️2 |
| Streaming / live data for ML/AI use cases | ✅ | ❌ |
| PULL - real-time request serving | | |
| Basic (Real-time feature store) | ✅ | ✅ |
| Advanced (Query API / on-demand API) | ✅ | ❌ |
| Development & deployment effort | | |
| INTERACTIVE DEVELOPMENT - notebooks, data experimentation | | |
| Batch / local data files | ✅ | ✅ |
| Streaming | ✅ | ❌ |
| DEPLOYMENT | | |
| Tests and CI/CD: Local - in process, without cluster | ✅ | ✅🐌 |
| Job management directly through containerized deployment (Kubernetes / Docker) | ✅ | ❌ |
| Horizontal + vertical scaling | ✅ | ✅ |
| Streaming Consistency | | |
| STREAMING CONSISTENCY | ✅ | 😠 |
* ⚠️2: Limited to a subset of SQL, limited JOIN complexity
* 🐌: Not scalable (e.g., local single-threaded only) or posing blocking performance issues
* 😠: Does not comply with user expectation.
### [Data processing & transformation](https://pathway.com/spark-streaming-alternative#data-processing-transformation)
* Pathway Live Data Framework and Spark both support data processing and transformation for various use cases. They both offer good batch processing for both SQL and ML/AI use cases. The Pathway Live Data Framework does so equally for streaming/ live data. However, Spark Streaming has limitations regarding JOIN complexity and extensiveness (Limited to a subset of SQL use cases) compared to our framework. In Spark, running batch jobs requires switching to a different Spark engine. In Pathway Live Data Framework, all jobs are handled with the same engine.
* Pathway Live Data Framework provides real-time request serving capabilities, including a real-time feature store. Spark Streaming does not support real-time request serving but can be extended to have request serving capabilities by querying Delta Tables, and relying on tools such as Presto. However, Spark Streaming may not support advanced features like query APIs or on-demand API as comprehensively as our Pathway Live Data Framework.
### [Development & deployment effort](https://pathway.com/spark-streaming-alternative#development-deployment-effort)
The Pathway Live Data Framework supports [interactive development](https://pathway.com/developers/user-guide/deployment/from-jupyter-to-deploy#introduction)
with Jupyter notebooks and data experimentation for both batch and streaming data. Deployment is facilitated through tests, CI/CD, and containerized deployment with Kubernetes/Docker. In contrast, Spark Streaming has limited support for interactive development and limited deployment options.
### [Streaming Consistency](https://pathway.com/spark-streaming-alternative#streaming-consistency)
Both Pathway Live Data Framework and Spark Streaming provide streaming consistency, but our Pathway Live Data Framework complies with internal consistency while Spark Streaming is limited to eventual consistency. We strongly recommend O'Reilly 2024 edition of [Streaming Databases](https://www.oreilly.com/library/view/streaming-databases/9781098154820/)
, and specifically Chapter 6 on Streaming Consistency.
### [Usability](https://pathway.com/spark-streaming-alternative#usability)
The native development stack for Spark Streaming is based on the Java Virtual Machine, so it provides excellent support for code developed in Java or Scala. The Support for Python in Spark Streaming is based on a number of wrapper API's, which provides a moderately integrated Python environment, allowing limited possibility of integrating external Python libraries. Spark Streaming has very limited schema and type validation, and provides very limited syntax help in Visual Studio Code and other development environments. The Pathway Live Data Framework is natively Python and provides advanced Python library integration, full schema and type validation at the time of job preparation, and a python-native integration experience for syntax help with Visual Studio Code and other development environments. Both Pathway Live Data Framework and Spark Streaming provide a layer for expressing data transformations in SQL.
[Benefits of Pathway Live Data Framework](https://pathway.com/spark-streaming-alternative#benefits-of-pathway-live-data-framework)
-----------------------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework is used to create Python code which seamlessly combines batch processing, streaming, and real-time APIs for LLM apps. Our Pathway Live Data Framework's distributed runtime (🦀-🐍) provides fresh results for your data pipelines whenever new inputs and requests are received.
The Pathway Live Data Framework was initially designed to be a life-saver (or at least a time-saver) for Python developers and ML/AI engineers faced with live data sources, where you need to react quickly to fresh data. The Pathway Live Data Framework provides a high-level programming interface in Python for defining data transformations, aggregations, and other operations on data streams. With our framework, you can effortlessly design and deploy sophisticated data workflows that efficiently handle high volumes of data in real-time.
The Pathway Live Data Framework is interoperable with various data sources and sinks such as Kafka, CSV files, SQL/NoSQL databases, and REST APIs, allowing you to connect and process data from different storage systems. Typical use-cases include real-time data processing, ETL (Extract, Transform, Load) pipelines, data analytics, monitoring, anomaly detection, and recommendation. The Pathway Live Data Framework can also independently provide the backbone of a light LLMops stack for [real-time LLM applications](https://github.com/pathwaycom/llm-app)
.
The Pathway Live Data Framework excels in offering a comprehensive set of features for data processing and transformation, with relatively lower development and deployment effort.
[Limitations of Spark Streaming](https://pathway.com/spark-streaming-alternative#limitations-of-spark-streaming)
-----------------------------------------------------------------------------------------------------------------
* The use of the JVM: The use of the Java Virtual Machine (JVM) in Spark presents drawbacks compared to Rust-based frameworks due to performance overhead, memory management issues, and higher resource utilization associated with the JVM's garbage collection mechanism.
* Limited State Management: Spark Streaming's state management capabilities are limited compared to other stream processing frameworks like Apache Flink or Kafka Streams. Managing and updating state across multiple processing stages can be challenging, especially for complex stateful operations.
* Complexity of Windowing Operations: While Spark Streaming supports windowing operations for aggregating data over time or other criteria, its windowing capabilities may not be as flexible or efficient as some other stream processing frameworks. Handling late data or out-of-order events within windows can be complex.
* Integration with External Systems: While Spark Streaming integrates well with the broader Spark ecosystem, its integration with external systems may be limited. Connecting to non-Spark data sources or sinks may require additional effort or custom development.
[FAQs](https://pathway.com/spark-streaming-alternative#faqs)
-------------------------------------------------------------
What would you say is the main differentiation between Pathway Live Data Framework and Spark Streaming?
Running machine learning (ML) models in a streaming environment presents a myriad of challenges that can quickly turn into headaches for data scientists and ML engineers. Spark Streaming is not optimized for streaming ML/AI workloads, leading to bottlenecks and inefficiencies. Spark Streaming stack components fail to keep up with the high velocity of incoming data, resulting in lagging processing times and increased latency compared to other stream processing systems. Handling multiple joins, transformations, and model updates in real-time can quickly overwhelm the system, leading to resource contention and degraded performance. For data scientists and ML engineers accustomed to interactive development environments and Python-based ML tooling, transitioning to a streaming environment can be a jarring experience. Debugging pipelines becomes a painstaking process, exacerbated by the lack of real-time feedback and visibility into the streaming data flow. The journey from development to scaling is fraught with challenges, often resulting in unpredictable results and consistency issues. Without years of experience with a particular analytics engine such as Spark Streaming, predicting the running speed and resource utilization of ML workloads in a streaming context is difficult. Unforeseen bottlenecks and performance quirks can derail even the most carefully crafted ML pipelines, leading to frustration and delays in deployment. Additionally, Spark's dependence on the Java ecosystem may limit flexibility and introduce compatibility challenges.
The Pathway Live Data Framework, as a high-throughput, low-latency data processing framework, solves those problems for Python & ML/AI developers.
---
# Pathway - Power Your AI with Live Data

AI, with Live Data
==================
Powering your RAG and ETL at scale
Easily set up data ingest from 300+ sources with automatic synchronization.
Build apps that serve real-time features, live vector search, and anomaly alerts.
Get accurate AI insights from terabytes of connected documents and data tables.
[Setup guide](https://pathway.com/developers/user-guide/introduction/installation)
[App templates](https://pathway.com/developers/templates)
Trusted by
----------
[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


Testimonials
Stories from our Users
----------------------
I got the Pathway Live Data Framework's AI pipelines to run on my work laptop - 11TH gen Core CPU, fully locally, within 1h.
Séverine Habert, AI Engineering Manager

Robust and innovative data processing technology such as delivered by Pathway, unlocks new capabilities for critical use cases at scale.
Major General Gerry Ewart-Brookes, Deputy Chief of Staff Plans

Pathway Live Data Framework shows that real-time data processing and AI integrate seamlessly into our chain of business tools, without adding complexity or implementation delays, while guaranteeing reliable results.
Edouard Hénaut, CEO France at Transdev

Whenever I think about new data pipelines projects or real time ones, I think about Pathway Live Data Framework before Flink.
Jakub Czerwonka, Data Engineer

Pathway Live Data Framework’s ability to process real-time data is truly impressive. Thanks to Pathway Live Data Framework we implemented our data pipelines for applied observability in production. If you’re looking for a top-notch data processing solutions, be sure to check out Pathway!
Priyam Kumar

Pathway Live Data Framework corrects the answers of LLMs in real time! Incrementally as well!
Hubert DulayAuthor of “Streaming Databases”
What sets this apart is its ability to deliver such impressive performance without the need for a separate vector database. This ingenious approach avoids the complexity and fragmentation commonly associated with LLM stacks.
Jaiyesh Chahar, ML Engineer

Kafka and Flink are based on outdated tech which results in underperformance. Their paradigm simply is not suited to AI/ML use cases. Pathway Live Data Framework is fast and built for the AI era.
Leading Streaming authorEnterprise Kafka Engineer at major retail chain
Going from streaming to batch and vice-versa is cumbersome for Flink or Spark. You usually end up designing and building from scratch a hybrid infra, which is unreliable. Pathway Live Data Framework is built to resolve this pain.
Member of Apache Pulsar core team

I’m really into Pathway Live Data Framework! It has a way lower learning curve than Flink, with way stronger consistency guarantees.
Flink developerStaff Data Engineer at a leading mobility scaleup
Here comes an update on the input data source, and we get alerted that the LLM has changed its answer to my question. Just set a web hook, create a reactive application with Pathway Live Data Framework, and never need to care about synchronizing data again ❤️
Pau Labarto BajoCreator of Real World ML
Want to create an #LLM app that can fetch real-time data? Without the need for vector databases or a complex stack? You should try Pathway Live Data Framework.
Snowflake Team

One blue box
Serving your AI apps & real-time dashboards
-------------------------------------------

Recognized by 

Gartner's Emerging Market Quadrant for Generative AI Technologies [Read More](https://pathway.com/framework/blog/gartner-gen-ai-engineering)

Gartner's Market Guide for Event Stream Processing [Read More](https://pathway.com/framework/blog/market-guide-event-stream-processing#pathway-is-featured-in-gartners-market-guide-for-event-stream-processing)

Gartner's Market Guide for Data Analytics and Intelligence Platforms in Supply Chain [Read More](https://pathway.com/news/gartner-market-guide-supply-chain)
---
# Pathway’s BDH solves Sudoku Extreme with 97.4% accuracy, while leading LLMs are close to 0
Table of Contents
[The Canary in the Coal Mine](https://pathway.com/research/beyond-transformers-sudoku-bench#the-canary-in-the-coal-mine)
-------------------------------------------------------------------------------------------------------------------------
Some breakthroughs look flashy. Others look like a humble puzzle grid.
At Pathway, we believe Sudoku matters because it exposes a gap that much of today's AI conversation prefers to ignore. The strongest language models can write essays, generate code, and sound uncannily fluent, yet they still struggle with a task that many humans treat as a morning warm-up: solving a hard Sudoku. This isn’t a quirky benchmark failure. It’s a signal that current large language models face a deeper architectural limit.
Sudoku is not "just a game." It is a tightly structured constraint-satisfaction problem, where every move must satisfy multiple rules at once across rows, columns, and boxes. A finished grid is easy to verify: anyone can check whether the numbers one through nine appear exactly once in each row, column, and square. But producing that grid from an incomplete board is much harder, because the solver has to search through interacting possibilities without breaking the rules. That combination makes Sudoku a clean way to test whether a system can truly reason under constraints rather than merely describe them.
This is where today's transformers start to show their limitations, and why the post-transformer era is critical for the path to artificial superintelligence.

Extreme Sudoku. Yes, this is what transformer-based models cannot solve. Source: Extreme Sudoku. [https://www.extremesudoku.info/.](https://www.extremesudoku.info/)
Accessed: 2026-03-11.
[Why Transformers Struggle With Sudoku](https://pathway.com/research/beyond-transformers-sudoku-bench#why-transformers-struggle-with-sudoku)
---------------------------------------------------------------------------------------------------------------------------------------------
Large language models turn problems into text and then solve them by predicting the next token, one step at a time. While it works brilliantly when language is the right medium for a task, Sudoku does not live in language. So forcing it into a chain of text can be painfully inefficient.
The transformer architecture behind most of today’s large language models is built on the idea that thinking happens at the same speed as writing (in language). The transformer processes information token by token, with a limited internal state for each step, which makes search-heavy, non-linguistic reasoning unusually awkward.
The latent space, also understood as the internal representation where the model "thinks", is constrained to roughly a thousand floating-point values per token, and each decision gets locked in as text is generated. Transformers simply cannot hold multiple candidate strategies in parallel, meaning they do not have the ability to step back and reconsider earlier moves without verbalizing every intermediate thought.
You can see the workaround already: if prompted cleverly enough, an LLM may try to write a Sudoku solver in Python and outsource the puzzle to code. But this exposes the difference between understanding a game (native reasoning) and escaping it, a distinction that matters far beyond the Sudoku grid.
[Why Games Matter for Artificial Superintelligence](https://pathway.com/research/beyond-transformers-sudoku-bench#why-games-matter-for-artificial-superintelligence)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------
For decades, games have been one of AI's clearest stress tests because they reveal whether a system can plan, search, adapt, and act under rules, rather than just imitate surface patterns.
Before the LLM era, major milestones in AI were measured through games such as Go, chess, and the Atari 2600 games, such as Breakout or Montezuma’s Revenge, precisely because games compress important ingredients of intelligence into benchmarks that are hard to fake.

Intense moment during the historic Go match between Lee Sedol and Google DeepMind's AI, AlphaGo, in March 2016. Handout/Getty Images.
Think of DeepMind's AlphaGo moment: it was never about simply winning a board game, but rather a proof that machines could master domains requiring deep strategic thinking, long-term planning, and adaptive search. Despite these breakthroughs, each game came with a cost: one architecture per game or, at best, one architecture per narrow family of games. The neural networks were trained separately for each challenge.
Then came language models, and suddenly we had generalist systems that could attempt everything from travel planning to writing poetry to solving math problems. The promise was one model to rule them all. But as reasoning capabilities scaled, especially with models designed for explicit reasoning, like OpenAI's O1, we started to see the limitations of what chain-of-thought reasoning can do.
After all, transformer reasoning was an afterthought glued on top and is fundamentally constrained by language.
[Language is not enough for intelligence](https://pathway.com/research/beyond-transformers-sudoku-bench#language-is-not-enough-for-intelligence)
-------------------------------------------------------------------------------------------------------------------------------------------------
For AI to move forward, we need to free our thoughts from the constraints of language. Current reasoning research is moving toward latent or continuous reasoning spaces, where models can preserve and compare multiple options internally, instead of committing too early in text.
This shift is necessary to enable systems that can become truly autonomous. Fluency in language is not enough for AI. AI needs a reasoning substrate that can navigate constraints, hold alternatives in mind, and converge on a strategy without verbalizing every intermediate thought.
Recent research from NYU Tandon Associate Professor of Computer Science and Engineering and Director of the Game Innovation Lab, [Julian Togelius](https://www.youtube.com/watch?v=o9o7fU_ZSIE)
, and others has made a similar point: scaling current reasoning models may help, but some limits are fundamental enough that brute-force scaling alone is unlikely to erase them soon. The road to more general intelligence probably does not run through ever-longer text monologues.
[How BDH Changes the Equation](https://pathway.com/research/beyond-transformers-sudoku-bench#how-bdh-changes-the-equation)
---------------------------------------------------------------------------------------------------------------------------
At Pathway, we built [BDH (Dragon Hatchling)](https://arxiv.org/abs/2509.26507)
as a truly native reasoning model. By creating a larger internal reasoning space called the latent reasoning space, it has intrinsic memory mechanisms that support learning and adaptation during use.
This is key. BDH keeps what transformers are great at, specifically language understanding and generation, while adding the ability to solve non-language problems that stump standard LLMs. A model based on BDH is not a model that can only play games, nor is it a language model that can only write text. It is a model based on a single architecture that excels at both.
Here is what that looks like in practice:
| Model | Sudoku Extreme Accuracy | Relative Cost |
| --- | --- | --- |
| Pathway BDH | 97.4% | 10x lower, No chain-of-thought |
| Leading LLMs (O3-mini, Deepseek R1, Claude 3.7 8K) | 0% | High (chain-of-thought) |
> Table 1: Performance comparison on extreme Sudoku benchmarks (approximately 250,000 difficult puzzles).
> **Source**: Pathway internal data and [https://arxiv.org/pdf/2506.21734](https://arxiv.org/pdf/2506.21734)
> for the Leading LLMs’ accuracy score. Pathway’s approach reflects top-1 accuracy and does not rely on chain-of-thought nor solution backtracking.
BDH reaches 97.4 percent accuracy on Extreme Sudoku benchmarks, a collection of roughly 250,000 of the toughest Sudoku puzzles available, while leading LLMs struggle to perform at all.
This mastery doesn't just come from static pre-training. BDH achieves continual learning, where it learns from every interaction and internalizes that learning over time for reasoning. As such, it can pick up the rules of a new game and reach an advanced-beginner level in as little as 20 minutes. From there, it improves its skills through repeated attempts, gaining expertise in the specific domains and problems the user presents.
In line with this experiential learning, BDH also reasons in a richer internal space before committing to output. Think of it like a chess grandmaster who can play twenty simultaneous games with their eyes closed. A grandmaster is not verbalizing each move in each game; rather, she has internalized the patterns and can navigate the search space seamlessly, the kind of mastery BDH enables.
Finally, BDH achieves this at a materially lower cost. By relying on this internalized reasoning rather than forced language outputs, BDH does not rely on chain-of-thought reasoning that burns GPU by verbalizing every step.
[Why Sudoku Is Useful in R&D - the litmus test for AI](https://pathway.com/research/beyond-transformers-sudoku-bench#why-sudoku-is-useful-in-rd-the-litmus-test-for-ai)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Sudoku is an ideal diagnostic for AI researchers, as it is hard enough to reveal genuine weaknesses, easy to verify with zero ambiguity, and benchmarkable at scale across very large sets of difficult puzzles. For us, that makes Sudoku less of a parlor trick and more of a litmus test for AI.
Sudoku Extreme, the specific benchmark we used, contains about 250,000 extremely difficult instances of Sudoku boards. Progress is measurable in a way that vague "reasoning" demos are not.
More interestingly, this approach generalizes. The ability to solve Sudoku is really about the ability to navigate constraint-satisfaction problems, hold multiple possibilities in parallel, backtrack when needed, and converge on solutions that satisfy all rules simultaneously, which are precisely the skills needed for many real-world challenges.
[From Sudoku to Strategy](https://pathway.com/research/beyond-transformers-sudoku-bench#from-sudoku-to-strategy)
-----------------------------------------------------------------------------------------------------------------
Many real workflows in medicine, law, operations, and planning are really constraint problems in disguise: they involve many variables, many rules, many possible paths, and high costs for wrong turns.
* In medicine, professionals choose therapies that must balance efficacy, side effects, drug interactions, and patient history.
* In the legal field, practitioners must navigate changing regulatory constraints, potentially contradictory case precedents, and strategic trade-offs in a specific client context.
* In operations, teams face competing demands to optimize schedules, supply chains, and resource allocation in an often dynamic environment.
* In planning, a professional designing a city’s emergency response plan during a major event must balance limited personnel and equipment, road closures, traffic patterns, weather forecasts, and shifting priorities - like which areas need help first - all while ensuring that response times stay within acceptable limits and that no critical area is left uncovered.
A system that can reason through those spaces more natively could eventually do more than summarize information. It could help generate the strategy.
We call this _generative strategy_: the ability to look at a problem, understand the constraints, and creatively propose what should be done, instead of merely remembering what has been done before.
That is why this breakthrough matters: Sudoku is the proof point, but the prize is much stronger decision-making.
[What This Means for the Future of AI](https://pathway.com/research/beyond-transformers-sudoku-bench#what-this-means-for-the-future-of-ai)
-------------------------------------------------------------------------------------------------------------------------------------------
The real unlock on the path towards artificial superintelligence is not an AI that is only good at puzzles, and not an AI that is only good at language, but one architecture that can do both. We need systems that can think before they speak.
When we force AI to verbalize every thought or formalize every step, we constrain its ability to genuinely invent. Human problem-solving often operates less like a rigorous, step-by-step whiteboard proof and more like an unstructured mental "soup" where ideas freely interact until a solution simply hits you.
These "Eureka" moments are the true engine of creativity. Richard Feynman, for instance, arrived at his Nobel Prize-winning breakthroughs not by grinding through mathematical dilemmas, but through sudden inspiration while watching a student spinning a plate at a cafeteria. And to achieve this level of genuine invention, AI must possess a latent reasoning space that allows for unstructured reasoning and intuitive leaps.
We believe that the future of AI will belong to systems that can reason natively across domains, that can hold multiple possibilities in a rich latent space, and that can converge on solutions without needing to verbalize every step.
BDH is our answer to that challenge. It is designed to be a universal reasoning system that can speak our language without being trapped inside it. And yes, it solves Sudoku.
[Looking Ahead](https://pathway.com/research/beyond-transformers-sudoku-bench#looking-ahead)
---------------------------------------------------------------------------------------------
We are actively exploring how this reasoning capacity translates to other tasks and domains, and the early signs are promising. The ability to solve abstract constraint problems appears to help with strategic thinking and planning in contexts far removed from puzzle grids, though there is still work to be done.
Validating that a model can discover things beyond its training data; this would be considered true creativity and that ultimately requires demonstrating something no human has done before. That is the frontier of science that now lies on our horizon.
For now, we have a clear milestone: we solved Sudoku puzzles that stump today's leading LLMs. We did it with [an architecture that maintains language fluency](https://arxiv.org/abs/2509.26507)
, without relying on chain-of-thought, and we did it in a way that points toward something bigger.
This is the beginning of what post-transformer reasoning can look like.
_At Pathway, we believe that memory and the ability to learn on the fly is the single biggest limitation facing current transformer-based AI models. Pathway is a post-transformer neo-lab that has solved that problem. We are delivering a faster path to AGI through true continuous learning and long horizon reasoning. To learn more about BDH, visit [pathway.com](http://pathway.com/)
._
* * *
---
# Success Stories | Pathway
Success Stories
Read in-depth examples of how major organizations use Pathway Live Data Framework
=================================================================================
[\
\
Banking and Financial services\
\
Providing customer service representatives with timely and accurate answers to client inquiries is costly and resource draining for retail banks.\
\
Providing customer service representatives with timely and accurate answers to client inquiries is costly and resource draining for retail banks.](https://pathway.com/success-stories/bank)
[\
\
NATO\
\
Discover how NATO and the Joint Support and Enabling Command (JSEC) collaborates with AI company Pathway during Steadfast Foxtrot 2024 to advance NATO's data processing and simulation capabilities, enhancing military operations and resilience in Eastern Europe.\
\
Discover how NATO and the Joint Support and Enabling Command (JSEC) collaborates with AI company Pathway during Steadfast Foxtrot 2024 to advance NATO's data processing and simulation capabilities, enhancing military operations and resilience in Eastern Europe.](https://pathway.com/success-stories/nato)
[\
\
La Poste\
\
Reduced the cost of their IoT deployment by 50%. And got analytics on a click for La Poste’ containers to enhance their operations.\
\
Reduced the cost of their IoT deployment by 50%. And got analytics on a click for La Poste’ containers to enhance their operations.](https://pathway.com/success-stories/la-poste)
[\
\
Transdev\
\
Pathway Live Data Framework enables Transdev to share reliable and accurate passenger information with their users, informing about bus deviations and ETAs.\
\
Pathway Live Data Framework enables Transdev to share reliable and accurate passenger information with their users, informing about bus deviations and ETAs.](https://pathway.com/success-stories/transdev)
[\
\
Formula 1\
\
Power real-time streaming use cases, through a fast, flexible, and user-friendly data processing system, enable end-users to create their User-Defined Functions (UDFs) independently, to feed the various business needs\
\
Power real-time streaming use cases, through a fast, flexible, and user-friendly data processing system, enable end-users to create their User-Defined Functions (UDFs) independently, to feed the various business needs](https://pathway.com/success-stories/formula-1-team)
[\
\
CMA CGM\
\
Pathway Live Data Framework improved significantly the precision of container gate-out ETAs (Estimated Time of Arrival). The optimization of individual terminal operations contributed to a speed-up in handling times of containers and reduced business and environmental costs.\
\
Pathway Live Data Framework improved significantly the precision of container gate-out ETAs (Estimated Time of Arrival). The optimization of individual terminal operations contributed to a speed-up in handling times of containers and reduced business and environmental costs.](https://pathway.com/success-stories/cma-cgm)
[\
\
DB Schenker\
\
One-stop-shop cloud-based application to provide immediately actionable insights on top of data for logistic assets, including IoT data and status data. The Logistics Application is Pathway's lighthouse data product, built in Pathway's own technology.\
\
One-stop-shop cloud-based application to provide immediately actionable insights on top of data for logistic assets, including IoT data and status data. The Logistics Application is Pathway's lighthouse data product, built in Pathway's own technology.](https://pathway.com/success-stories/db-schenker)
[\
\
Intel\
\
Pathway Slide Search is the most efficient way to find the slides you are looking for, and its fully compatible with Intel!\
\
Pathway Slide Search is the most efficient way to find the slides you are looking for, and its fully compatible with Intel!](https://pathway.com/framework/blog/intel-summit)
Trusted by
----------
[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


---
# The next Transformer moment for AI - read in Forbes | Pathway
Table of Contents
* * *
Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Pathway Team\
\
newsletterFeb 25, 2025\
\
Pathway to the Silicon Valley](https://pathway.com/news/newsletter-2025-02-25)
* [\
\
\
\
Pathway Team\
\
newsletterJan 15, 2026\
\
WSJ: Pathway marks the beginning of the post-transformer era](https://pathway.com/news/newsletter-2026-01-15)
* [\
\
\
\
Express Computer\
\
bdhMay 14, 2026\
\
Why continual learning and memory matters more than data in the next generation of AI](https://pathway.com/news/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai)
[News\
\
Pathway to the Silicon Valley](https://pathway.com/news/newsletter-2025-02-25)
[News\
\
WSJ: Pathway marks the beginning of the post-transformer era](https://pathway.com/news/newsletter-2026-01-15)
---
# License settings | Pathway
Pathway license settings
========================
Manage your license settings
* * *
License key
Copy key
[What is this key?](https://pathway.com/user/license#what-is-this-key)
-----------------------------------------------------------------------
This license key grants you access to [Pathway Live Data Framework Scale features](https://pathway.com/pricing)
that are not available in the Community version. It is available to you **free of charge**.
[How to use this key?](https://pathway.com/user/license#how-to-use-this-key)
-----------------------------------------------------------------------------
To activate Pathway Live Data Framework Scale features with your key, install the Pathway Live Data Framework package [as you normally would](https://pathway.com/developers/user-guide/introduction/welcome)
. Then, add the following lines to your source code:
`import pathway as pwpw.set_license_key("loading...")`
[Data Privacy and Terms of Use](https://pathway.com/user/license#data-privacy-and-terms-of-use)
------------------------------------------------------------------------------------------------
All use of the Pathway Live Data Framework is subject to [Licensing Terms and Conditions](https://pathway.com/license)
. By using this key, you additionally acknowledge and agree that anonymized product usage data is sent to Pathway (the company) via an OpenTelemetry collector. This data help us improve the product and provide better support.
All data collected is subject to [Pathway's Privacy Policy](https://pathway.com/privacy_gdpr_di)
. You have the right to review Pathway's Privacy Policy to understand how your data is handled.
Reach out to usto upgrade to a paid plan or to opt out of telemetry at any time.
[Your feedback matters!](https://pathway.com/user/license#your-feedback-matters)
---------------------------------------------------------------------------------
We are currently rolling out a new license key mechanism and are excited to hear about your onboarding experience. Drop us a line at [hello@pathway.com](mailto:hello@pathway.com)
, tell us how it went, and let us know which Pathway Live Data Framework Scale functionalities you are using in your project!
---
# Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason
Pathway Live Data Framework Features
====================================
All you need for your ETL and AI pipelines
------------------------------------------
**Pathway Live Data Framework** is a scalable and robust data processing framework. Use it to build and power AI/ML applications with live data and real-time pipelines.
Community
Scale
Enterprise
Supported up to8 GB RAM - 4 cores
Supported up to16 GB RAM - 4 cores (Free)
Supported up to24 TB RAM - 128 coresx 40 nodes
[Install it](https://pathway.com/developers/user-guide/introduction/installation)
[Get License](https://pathway.com/get-license)
Free and open under BSL 1.1.Self-hosted only.Packaged for pip, poetry, docker.
Free or paid, with license key.Self-hosted only.Packaged for pip, poetry, docker.
Pathway Live Data Framework Enterprise Licensing.Self-hosted and managed.Private package registry.
Deploy quickly on
[AWS](https://pathway.com/developers/user-guide/deployment/aws-fargate-deploy)
[Azure](https://pathway.com/developers/user-guide/deployment/azure-aci-deploy)
[GCP](https://pathway.com/developers/user-guide/deployment/gcp-deploy)
Deploy quickly on
[AWS](https://pathway.com/developers/user-guide/deployment/aws-fargate-deploy)
[Azure](https://pathway.com/developers/user-guide/deployment/azure-aci-deploy)
[GCP](https://pathway.com/developers/user-guide/deployment/gcp-deploy)
Deploy on cloud of choice
AWS Azure GCP Intel
What's included:
Everything in Community, plus:
Everything in Scale, plus:
20+ App templates
* basic RAG pipelines
* document pipelines
* log monitoring
* Kafka ETL
* social media sentiment analysis
Extra App templates
* high-accuracy RAG
* Sharepoint AI search
* Delta lake ETL
* monitored instances
Industry solutions
* real-time GPS data analytics
* logistics
* automotive
* IoT analytics
* fraud detection
* RAG for sales and marketing
* search in slide decks
Core features
* High-performance input/output connectors (Kafka, S3, cloud file systems, databases)
* Predefined API connectors to 300+ data sources
* REST API endpoint for serving query/answer and realtime features with sub-millisecond latency
* Python programming API (Table API)
* SQL programming API
* Incremental stream and table operations: join, filter, group-by, reduce
* Advanced join types, temporal joins, windows, and ranges
* Custom stateful reducers
* Incremental "apply" and "map-reduce"
* Support for pointer-based data structures: trees, graphs, event sequences
* User Defined Functions: call external libraries
* Make API calls from Pathway Live Data Framework data flows
* Async data processing: call APIs, libraries, LLM services
* Data schema support (Python/mypy compatible typing)
* True streaming data processing engine in Rust
* Same engine for streaming and batch workloads
* Same code logic for streaming and for backfilling
* Parallelization with multi-processing
* Data persistence with S3 storage
* Fully interactive execution with streaming & live data sources
* Develop and run in Jupyter notebooks (also in streaming)
* Data table introspection & debugging in streaming
* Out-of-the-box code completion supported by IDEs (VS Code, PyCharm, ...)
* Dataflow and schema validation at compile time
* Schema autodetection from data samples
* Exception handling at runtime
AI Toolkits
* Libraries for time-series operations, sampling, and filters
* LLM extension pack
* Unstructured data parsing toolkit (data source sync, parsing, extraction, indexing)
* Advanced data indexing built-in (vector with HNSW, BM24, hybrid)
* Support for custom indexing with knowledge graph and summarization techniques
* Support for fully local and API-based ML models
* Built-in support for temporal graph data
* Library for classification and clustering
Input connectors
* Kafka
* PostgreSQL
* http
* JSON Lines
* Redpanda
* Logstash
* Slack
* File System
* Google PubSub
* Custom Python connector (APIs and other destinations)
Support & Deployment
* Self hosted setup: Run Pathway Live Data Framework on your own machine or cloud
* Community support
Advanced features
* Enterprise data source connectors for Sharepoint, Delta Table, Iceberg, BigQuery, Elastic Search, Quest DB (more coming soon)
* Monitoring and traces for Pathway Live Data Framework Instances
* OpenTelemetry compatible
* Grafana integration
* Business Support with tickets1-business day reply time for paid tier customers
* Free 1st consultation call for pipeline design for your RAG, streaming and ETL use case
* #DeveloperAssist program
Enterprise features
* Horizontal Scalability
* High availability with hot failover
* Pathway Live Data Framework Helm Chart models
* Kubernetes deployment guides
* Connectors for custom messaging formats (MQTT/IoT, ...)
* Pathway Live Data Framework Visual Explorer: Live Dashboards with Pathway Live Data Framework, including geospatial data viz
* Queryable historical data snapshots
* Real-time geospatial & trajectory mining library (GPS traces)
* Support for data schema & code schema versioning
* Pathway Live Data Framework managed services and hosting
* Solutioning for industry use cases
* Made-to-measure data pipelines
* Access to professional services
* Multi-zone SLA
* 24/7 phone support
---
# Pathway Live Data Framework License Key
Pathway Live Data Framework License Key
=======================================
The Pathway Live Data Framework is an open-source framework, you can use easily install it and use its core features for free. However, for advanced use cases and access to Enterprise features, a Pathway Live Data Framework license key is required. This key unlocks enhanced capabilities designed to meet the needs of enterprise-grade applications and high-demand environments.
**Obtaining a Pathway Live Data Framework license key is free.**
[Why Do You Need a License Key?](https://pathway.com/framework/get-license#why-do-you-need-a-license-key)
----------------------------------------------------------------------------------------------------------
A Pathway Live Data Framework license key unlocks advanced capabilities for demanding use cases:
| Feature | Community version | With License |
| --- | --- | --- |
| **Free** | ✅ | ✅ |
| **RAM Usage Limit** | Up to 8GB | Up to 16GB |
| **Connectors** | Standard connectors | [SharePoint](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read)
, [Delta table](https://pathway.com/developers/api-docs/pathway-io/deltalake)
, and [Iceberg](https://pathway.com/developers/api-docs/pathway-io/iceberg)
connectors |
| **Functionalities** | Basic features | Advanced tools (e.g., `SlideParser`) |
| [**Full persistence**](https://pathway.com/developers/user-guide/deployment/persistence) | ❌ | ✅ |
| [**Monitoring**](https://pathway.com/developers/user-guide/deployment/live-data-framework-monitoring) | ❌ | ✅ |
For larger workloads or more custom functionalities, consider our [Enterprise version](https://pathway.com/pricing?tab=live-data-framework)
.
[Obtaining a License Key](https://pathway.com/framework/get-license#obtaining-a-license-key)
---------------------------------------------------------------------------------------------
To obtain a license key, you need to log in or create an account. We offer a simple login process using your GitHub or LinkedIn account.
Please click the button below to proceed:
Sign up for enterprise featuresAuthenticate with your Github or LinkedIn account to access additional features with Pathway Live Data Framework Scale for free.
* * *
GitHub LinkedIn
[How to Use the License Key](https://pathway.com/framework/get-license#how-to-use-the-license-key)
---------------------------------------------------------------------------------------------------
Once you have your license key, integrating it into your Pathway Live Data Framework application is simple. You can set the key in one of two ways:
### [1\. **As an Environment Variable**](https://pathway.com/framework/get-license#_1-as-an-environment-variable)
Define the license key as an environment variable in your system:
`export PATHWAY_LICENSE_KEY="your-license-key-here"`
This approach ensures the license key is available to your application without modifying your code.
### [2\. **Directly in Your Code**](https://pathway.com/framework/get-license#_2-directly-in-your-code)
Set the license key programmatically in your application using the [`pw.set_license_key`](https://pathway.com/developers/api-docs/pathway#pathway.set_license_key)
function:
`pw.set_license_key("your-license-key-here")`
### [Apply and Restart](https://pathway.com/framework/get-license#apply-and-restart)
After setting the license key, restart your application to activate the Enterprise features.
[Telemetry, Data Privacy, and Terms of Use](https://pathway.com/framework/get-license#telemetry-data-privacy-and-terms-of-use)
-------------------------------------------------------------------------------------------------------------------------------
All use of the Pathway Live Data Framework is subject to [Licensing Terms and Conditions](https://pathway.com/license)
. **By using this key, you additionally acknowledge and agree that anonymized product usage data is sent to Pathway (the company) via an OpenTelemetry collector.** This data help us improve the product and provide better support.
All data collected is subject to [Pathway's Privacy Policy](https://pathway.com/privacy_gdpr_di)
. You have the right to review Pathway's Privacy Policy to understand how your data is handled.
[Support](https://pathway.com/framework/get-license#support)
-------------------------------------------------------------
If you encounter issues with your license key or have questions about its use, our team is here to help. Contact us on [discord](https://discord.com/invite/pathway)
or on [GitHub](https://github.com/pathwaycom/)
.
---
# Pathway to the Silicon Valley
Table of Contents
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Pathway Team\
\
newsletterJan 15, 2026\
\
WSJ: Pathway marks the beginning of the post-transformer era](https://pathway.com/news/newsletter-2026-01-15)
* [\
\
\
\
Pathway Team\
\
newsletterOct 15, 2025\
\
The next Transformer moment for AI - read in Forbes](https://pathway.com/news/newsletter-2025-10-15)
* [\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
[News\
\
New podcast: Europe’s AI opportunity](https://pathway.com/news/new-podcast-europes-ai-opportunity-brand)
[News\
\
The next Transformer moment for AI - read in Forbes](https://pathway.com/news/newsletter-2025-10-15)
---
# WSJ: Pathway marks the beginning of the post-transformer era
Table of Contents
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Pathway Team\
\
newsletterFeb 25, 2025\
\
Pathway to the Silicon Valley](https://pathway.com/news/newsletter-2025-02-25)
* [\
\
\
\
Pathway Team\
\
newsletterOct 15, 2025\
\
The next Transformer moment for AI - read in Forbes](https://pathway.com/news/newsletter-2025-10-15)
* [\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
[News\
\
The next Transformer moment for AI - read in Forbes](https://pathway.com/news/newsletter-2025-10-15)
[News\
\
OpenAI claims AI is making coding jobs better, not worse. Is it true?](https://pathway.com/news/open-ai-coding-jobs-silicon-valley-google)
---
# Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.transdev.com/en/press-release/transdev-and-pathway-partner/](https://www.transdev.com/en/press-release/transdev-and-pathway-partner/)
in a moment.
* * *

transdev
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Pathway Team\
\
newsApr 17, 2025\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility)
* [\
\
\
\
Pathway Team\
\
news · case-studyNov 13, 2024\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
[News\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
[News\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility)
---
# Pathway quoted in the FT: The skeptical case on generative AI
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.ft.com/content/ed323f48-fe86-4d22-8151-eed15581c337](https://www.ft.com/content/ed323f48-fe86-4d22-8151-eed15581c337)
in a moment.
* * *

Financial Times
Worldʼs leading global business publication
[](https://www.ft.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [in French\
\
\
\
\
\
Les Echos\
\
newsAug 25, 2023\
\
Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](https://pathway.com/news/les-echos-deeptech)
* [\
\
\
\
BFM Business\
\
newsMay 30, 2022\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
* [\
\
\
\
The Next Web\
\
newsJul 26, 2023\
\
AI startup launches ‘fastest data processing engine’ on the market](https://pathway.com/news/nextweb-article)
[News\
\
Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](https://pathway.com/news/les-echos-deeptech)
[News\
\
Pathway named as a promising Generative AI leader (in French)](https://pathway.com/news/maddyness-gen-ai-mapping)
---
# Pathway is featured as a best-suited vendor candidate for Analytics and Decision Intelligence solutions for Supply Chain by Gartner
Table of Contents
Pathway was selected as a vendor candidate for analytics & decision intelligence (A&DI) for Supply Chain.
=========================================================================================================
This Tool released by Gartner has been designed to support supply chain technology leaders in identifying suitable and best-fit supply chain analytics and decision intelligence vendor candidates for their software evaluation process.
At Pathway we are proud to [enable real-time intelligence in Logistics](https://pathway.com/framework/solutions/logistics)
and Supply Chain. With Pathway, get value in under 24 hours: gather your data, get immediately a coherent data model you can work with, and access insights on the fly.
Read more about how Pathway has been designed for
* [Operations](https://pathway.com/framework/solutions/logistics#operations)
* [IoT deployment experts](https://pathway.com/framework/solutions/logistics#iot-deployment-experts)
* [Risk, Insurance and Security teams](https://pathway.com/framework/solutions/logistics#risk-insurance-security)
* [Digital & Data teams](https://pathway.com/framework/solutions/logistics#digital-data-teams)
… to address business problems in logistics and supply chain at scale.
Pathway already works with leaders in the market, such as CMA CGM, DB Schenker or La Poste.
For Gartner clients, feel free to download the full Excel spreadsheet [Tool: Identify A&DI Solutions for Supply Chain](https://bit.ly/3SqkBj0)
, and reach out!
* * *
Gartner
[](https://www.gartner.com/myhomepage)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

[News\
\
Pathway named among the Top Startups Transforming the European business landscape](https://pathway.com/news/eu-startup-news)
[News\
\
A coffee with… Zuzanna Stamirowska](https://pathway.com/news/tech-informed-article)
---
# Pathway Looks Toward the Post-Transformer Era
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.wsj.com/articles/an-ai-startup-looks-toward-the-post-transformer-era-4e362db8](https://www.wsj.com/articles/an-ai-startup-looks-toward-the-post-transformer-era-4e362db8)
in a moment.
* * *
Wall Street Journal
[](https://www.wsj.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [\
\
\
\
Quantum Zeitgeist\
\
news · bdhAug 3, 2025\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
[News\
\
AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency](https://pathway.com/news/ai-should-think-like-the-human-brain-dragon-hatchling-bdh-copies-neurons-for-unlimited-context-and-higher-efficiency)
[News\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/arxiv-bdh)
---
# As Cohere and Writer mine the ‘LiveAI™’ arena, Pathway joins the pack with a $10M round
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://techcrunch.com/2024/11/29/as-cohere-and-writer-mine-the-live-ai-arena-pathway-joins-the-pack-with-a-10m-round/](https://techcrunch.com/2024/11/29/as-cohere-and-writer-mine-the-live-ai-arena-pathway-joins-the-pack-with-a-10m-round/)
in a moment.
* * *
TechCrunch
[](https://www.techcrunch.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
ET Edge Insights\
\
news · bdhMar 12, 2026\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
[News\
\
Industry Leaders Comment On Biggest Lessons From ChatGPT’s Journey So Far](https://pathway.com/news/investors-ceos-founders-chatgpt-journey)
[News\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
---
# AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.youtube.com/watch?v=cnUSW0pLFVk](https://www.youtube.com/watch?v=cnUSW0pLFVk)
in a moment.
* * *
AWS Events
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Forbes\
\
news · bdhOct 8, 2025\
\
Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](https://pathway.com/news/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
[News\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/arxiv-bdh)
[News\
\
Benchmarks: Fundamental Unlocks for AI](https://pathway.com/news/benchmarks)
---
# How Businesses Can Create Data Frameworks for Real-world AI | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.cdomagazine.tech/aiml/how-businesses-can-create-data-frameworks-for-real-world-ai?utm\_content=277910962&utm\_medium=social&utm\_source=linkedin&hss\_channel=lcp-40830869](https://www.cdomagazine.tech/aiml/how-businesses-can-create-data-frameworks-for-real-world-ai?utm_content=277910962&utm_medium=social&utm_source=linkedin&hss_channel=lcp-40830869)
in a moment.
* * *
Zuzanna Stamirowska
CEO
[](https://www.linkedin.com/in/stamirowska/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
newsSep 24, 2023\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
* [\
\
\
\
TechInformed\
\
newsFeb 27, 2025\
\
Becoming AI-savvy: going beyond data smarts for business transformation](https://pathway.com/news/becoming-ai-savvy-for-transformation)
* [\
\
\
\
Forbes\
\
newsFeb 13, 2025\
\
Forbes: Pathway Navigates Next Road For AI Foundational Models](https://pathway.com/news/pathway-mentioned-in-the-financial-times)
[News\
\
The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski](https://pathway.com/news/pathway-meetup-2024)
[News\
\
Client Testimonial: La Poste at Modern Data Stack](https://pathway.com/news/modern-data-stack)
---
# Pathway raises $10 million in seed funding round
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.cnbctv18.com/business/startup/ai-startup-pathway-raises-10-million-dollar-seed-funding-19520684.htm](https://www.cnbctv18.com/business/startup/ai-startup-pathway-raises-10-million-dollar-seed-funding-19520684.htm)
in a moment.
* * *
cnbctv18
[](https://www.cnbctv18.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
ET CIOSEA\
\
newsDec 4, 2024\
\
ETCIO Southeast Asia covers Pathway Seed Round](https://pathway.com/news/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
[News\
\
CNBC India spotlighting Pathway](https://pathway.com/news/cnbc-india-spotlighting-pathway)
[News\
\
Parisian AI startup Pathway on moving to the US: 'We need to be in the room where it happens, and it happens in the Bay Area](https://pathway.com/news/pathway-10m-seed-round-news)
---
# Pathway named among the Top Startups Transforming the European business landscape
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://eustartup.news/which-french-b2b-startups-are-transforming-the-european-business-landscape/](https://eustartup.news/which-french-b2b-startups-are-transforming-the-european-business-landscape/)
in a moment.
* * *
EU Startup News
[](https://eustartup.news/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
BFM Business\
\
newsMay 30, 2022\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
* [\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
[News\
\
Client Testimonial: La Poste at Modern Data Stack](https://pathway.com/news/modern-data-stack)
[News\
\
Pathway is featured as a best-suited vendor candidate for Analytics and Decision Intelligence solutions for Supply Chain by Gartner](https://pathway.com/news/gartner-a-n-di-solutions)
---
# Pathway is a Representative Vendor in Gartner 2023 Market Guide for Analytics and Decision Intelligence Platforms in Supply Chain
Table of Contents
Pathway was selected as a Representative Vendor in the 2023 Gartner Market Guide for Analytics and Decision Intelligence Platforms in Supply Chain.
===================================================================================================================================================
According to Gartner analysts Christian Titze and Noha Tohamy, ”By 2026, 50% of organizations will have to evaluate analytics and business intelligence (ABI) and data science and machine learning (DSML) platforms as a single platform due to market convergence.”
We are proud to enable industry leaders to “achieve contextualized, connected, and continuous insights” through:
* **Pathway Live Data Framework**: the most powerful data processing framework, currently used for real-time anomaly detection, predictive analytics, IoT and logs data observability, recommender systems, and alerting, and which works particularly well with data in motion: data tables, live events data, etc.
* **Pathway Logistics App**: our lighthouse data platform built in the Pathway Live Data Framework. It is a one-stop-shop cloud-based application to provide immediately actionable insights on top of data for logistics assets, including IoT data and status data.
With “functional teams ... looking to speed up cross-functional decision making on the basis of more near-real-time and broader datasets”, Pathway is best positioned to deliver value to Enterprise clients
For Gartner clients, feel free to read the full [Gartner Market Guide](https://www.gartner.com/document/4478399?ref=solrAll&refval=374406409&)
for Analytics and Decision Intelligence Platforms in Supply Chain, and do reach out!
* * *

Gartner
[](https://www.gartner.com/account/signin?method=initialize&TARGET=https%3A%2F%2Fwww.gartner.com%2Fmyhomepage)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Gartner\
\
newsOct 23, 2023\
\
Pathway is featured as a best-suited vendor candidate for Analytics and Decision Intelligence solutions for Supply Chain by Gartner](https://pathway.com/news/gartner-a-n-di-solutions)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
[News\
\
Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](https://pathway.com/news/le-point)
[News\
\
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](https://pathway.com/news/vivatech-by-the-french-prime)
---
# How 'Neolabs' Are Betting Against the OpenAI Model and What It Means for Founders | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.inc.com/brett-farmiloe/how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders/91279024](https://www.inc.com/brett-farmiloe/how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders/91279024)
in a moment.
* * *
Inc.
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
ET Edge Insights\
\
news · bdhMar 12, 2026\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
* [in German\
\
\
\
\
\
Notebook Check\
\
news · bdhOct 21, 2025\
\
AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency](https://pathway.com/news/ai-should-think-like-the-human-brain-dragon-hatchling-bdh-copies-neurons-for-unlimited-context-and-higher-efficiency)
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[News\
\
From Data-sure To AI-savvy: Unlocking The Next Stage Of Business Transformation](https://pathway.com/news/from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation)
[News\
\
Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](https://pathway.com/news/inside-pathways-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
---
# Industry Leaders Comment On Biggest Lessons From ChatGPT’s Journey So Far | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://techround.co.uk/news/investors-ceos-founders-chatgpt-journey/](https://techround.co.uk/news/investors-ceos-founders-chatgpt-journey/)
in a moment.
* * *
TechRound
[](https://www.techround.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
BFM Business\
\
newsMay 30, 2022\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
* [\
\
\
\
The Next Web\
\
newsJul 26, 2023\
\
AI startup launches ‘fastest data processing engine’ on the market](https://pathway.com/news/nextweb-article)
[News\
\
LLM series - Pathway: Taking LLMs out of pilot into production](https://pathway.com/news/llm-series-pathway-taking-llms-out-of-pilot-into-production)
[News\
\
As Cohere and Writer mine the ‘LiveAI™’ arena, Pathway joins the pack with a $10M round](https://pathway.com/news/as-cohere-and-writer-mine-the-live-ai-arena-pathway-joins-the-pack-with-a-10m-round)
---
# CNBC India spotlighting Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.cnbctv18.com/business/startup/ai-startup-pathway-raises-10-million-dollar-seed-funding-19520684.htm](https://www.cnbctv18.com/business/startup/ai-startup-pathway-raises-10-million-dollar-seed-funding-19520684.htm)
in a moment.
* * *

cnbctv18
[](https://www.cnbctv18.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
* [\
\
\
\
ET CIOSEA\
\
newsDec 4, 2024\
\
ETCIO Southeast Asia covers Pathway Seed Round](https://pathway.com/news/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
[News\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
[News\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
---
# 100 Women in Tech | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://sifted.eu/list/100-women-in-tech-2025](https://sifted.eu/list/100-women-in-tech-2025)
in a moment.
* * *
sifted.eu
[](https://sifted.eu/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Wall Street Journal\
\
newsDec 26, 2025\
\
Tech That Will Change Your Life in 2026](https://pathway.com/news/tech-predictions-2026)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
[Success Stories\
\
Logistics: DB Schenker](https://pathway.com/success-stories/db-schenker)
[News\
\
La Poste Optimizes Colissimo Flows in Real Time - Modern Data Stack Recording available](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time)
---
# Building Data Frameworks for Real-time AI Applications | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.europeanfinancialreview.com/building-data-frameworks-for-real-time-ai-applications/](https://www.europeanfinancialreview.com/building-data-frameworks-for-real-time-ai-applications/)
in a moment.
* * *

Zuzanna Stamirowska
CEO
[](https://www.linkedin.com/in/stamirowska/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
newsFeb 9, 2024\
\
How Businesses Can Create Data Frameworks for Real-world AI](https://pathway.com/news/cdo-magazine)
* [\
\
\
\
TechInformed\
\
newsFeb 27, 2025\
\
Becoming AI-savvy: going beyond data smarts for business transformation](https://pathway.com/news/becoming-ai-savvy-for-transformation)
* [\
\
\
\
Forbes\
\
newsFeb 13, 2025\
\
Forbes: Pathway Navigates Next Road For AI Foundational Models](https://pathway.com/news/pathway-mentioned-in-the-financial-times)
[News\
\
A coffee with… Zuzanna Stamirowska](https://pathway.com/news/tech-informed-article)
[News\
\
Enabling AI to unlearn and self-correct like a human](https://pathway.com/news/wearewomen-article)
---
# Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929) | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.superdatascience.com/podcast/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski](https://www.superdatascience.com/podcast/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
in a moment.
* * *
SuperDataScience
[](https://superdatascience.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
MILA Tea Talk\
\
podcast · video · bdh · researchMar 10, 2026\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
* [\
\
\
\
This Is The World\
\
news · podcast · bdhOct 4, 2025\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
* [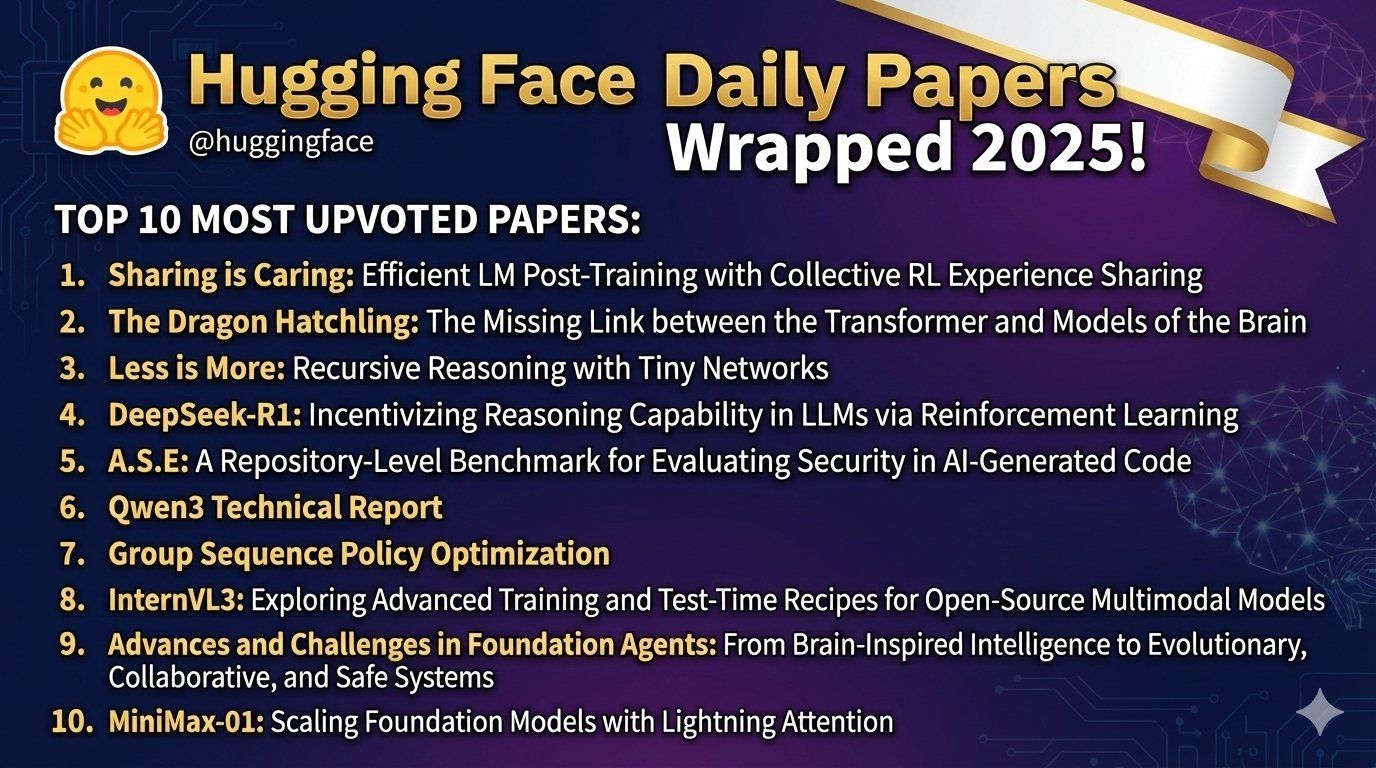\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
[News\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
[News\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
---
# The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://arxiv.org/abs/2509.26507](https://arxiv.org/abs/2509.26507)
in a moment.
* * *

Arxiv.org
[](https://pathway.com/news/arxiv.org)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
MILA Tea Talk\
\
podcast · video · bdh · researchMar 10, 2026\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
* [\
\
\
\
Hugging Face\
\
news · bdh · developerSep 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
[News\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
[News\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
---
# AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.notebookcheck.com/KI-soll-denken-wie-das-menschliche-Gehirn-Dragon-Hatchling-BDH-kopiert-Neuronen-fuer-unbegrenzten-Kontext-und-hoehere-Effizienz.1142453.0.html](https://www.notebookcheck.com/KI-soll-denken-wie-das-menschliche-Gehirn-Dragon-Hatchling-BDH-kopiert-Neuronen-fuer-unbegrenzten-Kontext-und-hoehere-Effizienz.1142453.0.html)
in a moment.
* * *

Notebook Check
[](https://pathway.com/news/notebookcheck.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [\
\
\
\
Hugging Face\
\
news · bdh · developerSep 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
* [\
\
\
\
ET Edge Insights\
\
news · bdhMar 12, 2026\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
[News\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
[News\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
---
# Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.lepoint.fr/sciences-nature/palmares-des-inventeurs-du-point-la-releve-du-genie-francais-22-06-2023-2525696\_1924.php](https://www.lepoint.fr/sciences-nature/palmares-des-inventeurs-du-point-la-releve-du-genie-francais-22-06-2023-2525696_1924.php)
in a moment.
* * *

Le Point
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
news · videoJun 16, 2023\
\
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](https://pathway.com/news/vivatech-by-the-french-prime)
* [\
\
\
\
Claire Nouet\
\
newsApr 17, 2025\
\
From Data-sure To AI-savvy: Unlocking The Next Stage Of Business Transformation](https://pathway.com/news/from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation)
* [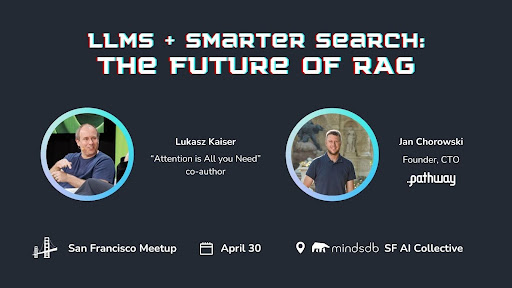\
\
\
\
Pathway Team\
\
newsApr 30, 2024\
\
The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski](https://pathway.com/news/pathway-meetup-2024)
[News\
\
AI startup launches ‘fastest data processing engine’ on the market](https://pathway.com/news/nextweb-article)
[News\
\
Pathway is a Representative Vendor in Gartner 2023 Market Guide for Analytics and Decision Intelligence Platforms in Supply Chain](https://pathway.com/news/gartner-market-guide-supply-chain)
---
# Interview for Paris-Saclay | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://epa-paris-saclay.fr/actualites-et-decryptages/toutes-nos-publications/traitement-de-donnees-en-temps-reel-la-voie-pathway/](https://epa-paris-saclay.fr/actualites-et-decryptages/toutes-nos-publications/traitement-de-donnees-en-temps-reel-la-voie-pathway/)
in a moment.
* * *

Paris-Saclay
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
newsSep 24, 2023\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
* [\
\
\
\
TechInformed\
\
newsFeb 27, 2025\
\
Becoming AI-savvy: going beyond data smarts for business transformation](https://pathway.com/news/becoming-ai-savvy-for-transformation)
* [\
\
\
\
Forbes\
\
newsFeb 13, 2025\
\
Forbes: Pathway Navigates Next Road For AI Foundational Models](https://pathway.com/news/pathway-mentioned-in-the-financial-times)
[News\
\
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](https://pathway.com/news/vivatech-by-the-french-prime)
[News\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
---
# Pathway on BFM Business - the French Business TV channel
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.bfmtv.com/economie/replay-emissions/tech-and-co/paris-saclay-spring-2022-quelles-sont-les-cinq-start-up-primees-19-05\_VN-202205190687.html](https://www.bfmtv.com/economie/replay-emissions/tech-and-co/paris-saclay-spring-2022-quelles-sont-les-cinq-start-up-primees-19-05_VN-202205190687.html)
in a moment.
* * *

BFM Business
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
EU Startup News\
\
newsOct 16, 2023\
\
Pathway named among the Top Startups Transforming the European business landscape](https://pathway.com/news/eu-startup-news)
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
* [\
\
\
\
Zuzanna Stamirowska\
\
news · videoJun 16, 2023\
\
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](https://pathway.com/news/vivatech-by-the-french-prime)
[News\
\
Female-led deeptech startup Pathway announces its $4.5m pre-seed round](https://pathway.com/news/female-led-deeptech-startup)
[News\
\
AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency](https://pathway.com/news/ai-should-think-like-the-human-brain-dragon-hatchling-bdh-copies-neurons-for-unlimited-context-and-higher-efficiency)
---
# Pathway in Les Echos - CEO Portrait
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.lesechos.fr/start-up/portraits/ces-chercheurs-qui-ont-decide-de-fonder-une-start-up-dans-la-deeptech-1895133in](https://www.lesechos.fr/start-up/portraits/ces-chercheurs-qui-ont-decide-de-fonder-une-start-up-dans-la-deeptech-1895133in)
a moment.
* * *

Les Echos
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [in French\
\
\
\
\
\
Les Echos\
\
newsAug 25, 2023\
\
Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](https://pathway.com/news/les-echos-deeptech)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
* [\
\
\
\
cnbctv18\
\
newsDec 2, 2024\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
[News\
\
Interview for Paris-Saclay](https://pathway.com/news/paris-saclay)
[News\
\
Female-led deeptech startup Pathway announces its $4.5m pre-seed round](https://pathway.com/news/female-led-deeptech-startup)
---
# AI startup launches ‘fastest data processing engine’ on the market | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://thenextweb.com/news/ai-startup-launches-fastest-data-processing-engine-market](https://thenextweb.com/news/ai-startup-launches-fastest-data-processing-engine-market)
in a moment.
* * *

The Next Web
[](https://thenextweb.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [in French\
\
\
\
\
\
Maddyness\
\
newsJul 26, 2023\
\
French deep tech start-up announces the general launch of its data processing engine](https://pathway.com/news/maddyness-article-about-pathway)
[News\
\
French deep tech start-up announces the general launch of its data processing engine](https://pathway.com/news/maddyness-article-about-pathway)
[News\
\
Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](https://pathway.com/news/le-point)
---
# Revealing the First Biological AI: A Step Closer to Singularity | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.youtube.com/watch?v=6\_v2HG8l9oA](https://www.youtube.com/watch?v=6_v2HG8l9oA)
in a moment.
* * *
This Is The World
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
The Neuron\
\
news · podcast · bdhJan 6, 2026\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
* [\
\
\
\
Live Science\
\
news · bdhNov 13, 2025\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
[News\
\
Pathway's BDH: a new post-transformer approach to enterprise AI, on AWS](https://pathway.com/news/pathways-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws)
[News\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
---
# Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://techfundingnews.com/pathway-ceo-and-co-founder-predicts-2025-ai-trends-will-your-startup-survive-the-shift/](https://techfundingnews.com/pathway-ceo-and-co-founder-predicts-2025-ai-trends-will-your-startup-survive-the-shift/)
in a moment.
* * *

Zuzanna Stamirowska
CEO
[](https://www.linkedin.com/in/stamirowska/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Unite AI\
\
newsSep 26, 2025\
\
Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series](https://pathway.com/news/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series)
* [\
\
\
\
sifted.eu\
\
newsDec 2, 2024\
\
Parisian AI startup Pathway on moving to the US: 'We need to be in the room where it happens, and it happens in the Bay Area](https://pathway.com/news/pathway-10m-seed-round-news)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
[News\
\
Forbes: Pathway Navigates Next Road For AI Foundational Models](https://pathway.com/news/pathway-mentioned-in-the-financial-times)
[News\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
---
# Tech That Will Change Your Life in 2026 | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.wsj.com/tech/ai/tech-predictions-2026-6884d6b0](https://www.wsj.com/tech/ai/tech-predictions-2026-6884d6b0)
in a moment.
* * *
Wall Street Journal
[](https://www.wsj.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
sifted.eu\
\
newsOct 10, 2025\
\
100 Women in Tech](https://pathway.com/news/100-women-in-tech-2025)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsDec 19, 2024\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
* [\
\
\
\
Turing Post\
\
news · bdhDec 29, 2025\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
[News\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
[News\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
---
# Pathway featured in Maddyness 2025 Insights and Predictions
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.maddyness.com/uk/2024/12/20/prompts-and-predictions-part-2-startup-founders-share-their-insights-and-ambitions-for-2025/](https://www.maddyness.com/uk/2024/12/20/prompts-and-predictions-part-2-startup-founders-share-their-insights-and-ambitions-for-2025/)
in a moment.
* * *
Maddyness
[](https://www.maddyness.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
newsDec 19, 2024\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
* [\
\
\
\
cnbctv18\
\
newsDec 2, 2024\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
[News\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
[News\
\
CNBC India spotlighting Pathway](https://pathway.com/news/cnbc-india-spotlighting-pathway)
---
# Pathway's BDH: a new post-transformer approach to enterprise AI, on AWS
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://aws.amazon.com/startups/learn/pathways-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws#overview](https://aws.amazon.com/startups/learn/pathways-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws#overview)
in a moment.
* * *

AWS Startups
[](https://pathway.com/news/aws.amazon.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
* [\
\
\
\
Eye on AI\
\
news · bdhMar 11, 2026\
\
Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](https://pathway.com/news/inside-pathways-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
* [\
\
\
\
This Is The World\
\
news · podcast · bdhOct 4, 2025\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
[News\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
[News\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
---
# CMA CGM Success Story | Pathway
Success stories: CMA CGM and Pathway
====================================
**Quick ROI**: Pathway improved significantly the precision of container gate-out ETAs (Estimated Time of Arrival). The optimization of individual terminal operations contributed to a speed-up in handling times of containers and reduced business and environmental costs.

[CMA CGM](https://pathway.com/success-stories/cma-cgm#cma-cgm)
---------------------------------------------------------------
CMA CGM is one of the largest shipping companies in the world, specializing in maritime transportation and logistics. It operates a vast network of shipping routes that connect major ports worldwide and provides comprehensive logistics solutions, including door-to-door transportation, customs clearance, warehousing, and distribution services. It also operates terminal facilities in key ports, providing efficient handling and storage solutions for cargo.
[The Business Case](https://pathway.com/success-stories/cma-cgm#the-business-case)
-----------------------------------------------------------------------------------
Pathway and CMA CGM initially started working together on a use case related to smart ports, and more specifically to container gate-out ETAs. The operational objectives were associated with improving the fluidity of gate-out containers, and truck traffic to contribute to the terminal's performance. The use case initially focused on France's leading port - Marseille Fos - which accommodates nearly 9,000 ships and handles 75 million tonnes of goods each year.
A key topic for companies like CMA CGM is to deliver the best customer experience possible. The growth of global maritime traffic has induced terminals’ saturation: with larger volumes being traded, waiting times at terminal gates have dramatically increased, and have introduced friction into the customers’ supply chains. Clients need to anticipate when to pick up their containers and they often are feeling a lack of transparency, visibility, and reliable information on the status and the estimated date for pickup of their containers, making proactive decision-making significantly harder.
> _Every day of delay in transit puts us in a little more trouble because we have all the resellers pushing us to always have even more stock._
> _It's vital for us to be able to anticipate as much as possible and iron out any kinks with our partners sufficiently in advance if we're faced with a delay._
The initial goal of the collaboration, before extending to other use cases, was thus related to visibility of supply chains for end clients of CMA CGM to enable them to anticipate changes by providing them with strategic, reliable, and real-time information, to better adapt to volatilities of transport. This was part of a larger ongoing initiative around more innovative supply chains and smart ports, integrating various technologies, such as the Internet of Things (IoT), artificial intelligence (AI), big data analytics, and automation.
The container shipping sector is a competitive industry and one of the major challenges is related to container flow optimization. The Pathway Live Data Framework was used to automatically process the data and to predict the container ETA forecasting at the container level.
* ETAs are calculated for containers, not ships
* Real-time evaluation of the chance of delay, with precision increasing during the journey
* Takes into account risks related to transshipments
* Uncovers and takes into account real-time port statistics
The ability to perform advanced data transformations, including machine learning with small latency makes it possible to unlock the massive value hidden in the logistics data. One of the key pain points of logistics tech leaders right now is the ability to align numerous event streams together to get a clear & up to date understanding of operations. When we asked some of logistics top executives "what's at stake", their answer was clear: the bottom line.
[Success Stories\
\
Formula 1 Team](https://pathway.com/success-stories/formula-1-team)
[Success Stories\
\
Logistics: DB Schenker](https://pathway.com/success-stories/db-schenker)
---
# Formula 1 Team & Pathway success story
Success stories: Formula 1 Team and Pathway
===========================================
An F1 team reduced their development time by 3x while **increasing autonomy across product lines**

90xFaster processing speed
< 2msData latency
Reconciling streaming data errors
Results
Challenge
A rigid framework not adapted to the many workflows coexisting within the company, leading to multiple development bottlenecks.
Issue
120HzData throughput
80+Streaming pipelines
Rigidity imposed by the previous tooling
Solution
The Pathway Live Data Framework enabled a platform approach for end-users to create User-Defined Functions (UDFs) independently, to feed the various business needs from e-sports/sim-racing, to cars and formula 1 racing.
Customer feedback
Pathway enables an end-to-end data platform approach and integrates easily in our architecture. The Python code can be maintained and versioned and is very easy to put in production.
Senior Data Architect and Former F1 Head of performance
**Pathway's Pathway Live Data Framework**
* Unified engine for batch and streaming
* Advanced data transformations, including ML with very low latency
* Freedom to create and operate their own solutions (architecture, data pipelines)
* Increased ease of use: for user-defined functions and putting code in production
Product
[Success Stories\
\
Mobility: Transdev](https://pathway.com/success-stories/transdev)
[Success Stories\
\
Shipping: CMA CGM](https://pathway.com/success-stories/cma-cgm)
---
# Benchmarks: Fundamental Unlocks for AI | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to pathway.com/#benchmarks in a moment.
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
* [\
\
\
\
Arxiv.org\
\
bdh · researchNov 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/arxiv-bdh)
* [\
\
\
\
MILA Tea Talk\
\
podcast · video · bdh · researchMar 10, 2026\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
[News\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
[News\
\
Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](https://pathway.com/news/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so)
---
# Opinion: EU could be epicenter of AI academia as US cuts funding | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.siliconrepublic.com/innovation/opinion-eu-could-be-epicentre-of-ai-academia-as-us-cuts-funding](https://www.siliconrepublic.com/innovation/opinion-eu-could-be-epicentre-of-ai-academia-as-us-cuts-funding)
in a moment.
* * *
SiliconRepublic.com
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Live Science\
\
news · bdhNov 13, 2025\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
* [\
\
\
\
Maddyness\
\
newsJul 26, 2023\
\
Pathway named as a promising Generative AI leader (in French)](https://pathway.com/news/maddyness-gen-ai-mapping)
* [in Japanese\
\
\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
[News\
\
OpenAI claims AI is making coding jobs better, not worse. Is it true?](https://pathway.com/news/open-ai-coding-jobs-silicon-valley-google)
[News\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
---
# La Poste partners with Pathway to create digital twin of fleet
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.iotinsider.com/news/la-poste-partners-with-pathway-to-create-digital-twin-of-fleet/](https://www.iotinsider.com/news/la-poste-partners-with-pathway-to-create-digital-twin-of-fleet/)
in a moment.
* * *
IoT Insider
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
* [\
\
\
\
Pathway Team\
\
news · case-studyNov 13, 2024\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
* [\
\
\
\
Modern Data Stack\
\
newsDec 1, 2023\
\
Client Testimonial: La Poste at Modern Data Stack](https://pathway.com/news/modern-data-stack)
[News\
\
Can an artificial intelligence learn like a human brain does? A startup believes it has achieved this](https://pathway.com/news/inteligencia-artificial-aprender-cerebro-humano)
[News\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
---
# Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://radicaldatascience.wordpress.com/2025/10/01/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai/](https://radicaldatascience.wordpress.com/2025/10/01/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai/)
in a moment.
* * *

Radical Data Science
[](https://pathway.com/news/radicaldatascience.wordpress.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [\
\
\
\
Quantum Zeitgeist\
\
news · bdhAug 3, 2025\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
* [\
\
\
\
Live Science\
\
news · bdhNov 13, 2025\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
[News\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
[News\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
---
# LLM series - Pathway: Taking LLMs out of pilot into production
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.computerweekly.com/blog/CW-Developer-Network/LLM-series-Pathway-Taking-LLMs-out-of-pilot-into-production](https://www.computerweekly.com/blog/CW-Developer-Network/LLM-series-Pathway-Taking-LLMs-out-of-pilot-into-production)
in a moment.
* * *
ComputerWeekly
[](https://www.computerweekly.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
* [\
\
\
\
Unite AI\
\
newsSep 26, 2025\
\
Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series](https://pathway.com/news/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
[News\
\
ETCIO Southeast Asia covers Pathway Seed Round](https://pathway.com/news/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai)
[News\
\
Industry Leaders Comment On Biggest Lessons From ChatGPT’s Journey So Far](https://pathway.com/news/investors-ceos-founders-chatgpt-journey)
---
# Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise
Table of Contents
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise
==================================================================================================================

**Ulm, Germany. 01 OCTOBER 2024** From 11 to 18 September, more than 250 participants from 24 nations and various NATO entities engaged in one of the largest military enablement exercises at the Joint Support and Enabling Command (JSEC).
Steadfast Foxtrot 2024 not only trained experts in enablement, reinforcement by forces and sustainment but also set the stage for unveiling NATO’s steps towards the next generation of data processing and simulation systems in close collaboration with the Artificial Intelligence (AI) company Pathway.
“Robust and innovative data processing technology such as delivered by Pathway, unlocks new capabilities for critical use cases at scale,” emphasizes Major General Gerry Ewart-Brookes, Deputy Chief of Staff Plans. The ability to combine military data sources and open-source information such as civil traffic, social media alerts, and media is crucial for the planning and execution of military operations.
With its functional demonstrator, the Reinforcement Enablement Simulation Tool (REST), Pathway developed the cornerstone for further development of AI-supported solutions to NATO.
According to Major General Dirk Kipper, Deputy Chief of Staff Operations, the smart combination of NATO and open source data will speed up situational awareness and bring it to the necessary level, required to successfully operate in the 21st century.
Exercise Steadfast Foxtrot 2024 tested NATO’s resilience in the face of a greater menace at the Eastern European borders. Military personnel from Allied nations together with NATO staff trained to strengthen mutual cooperation and test the sustainability of NATO forces. Anticipating the movement of troops and equipment from the east coast of North America across the Atlantic and the European continent has never been so critical for an effective deterrence of Allied territory.
This initiative is a great example of how NATO aims to bridge the gap between what the industry can offer, and the military expertise in order to further improve the safety of the Alliance’s one billion citizens.
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
transdev\
\
news · case-studyApr 23, 2025\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-and-pathway-partner)
* [\
\
\
\
We Are Tech Women\
\
newsAug 31, 2023\
\
Enabling AI to unlearn and self-correct like a human](https://pathway.com/news/wearewomen-article)
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
[News\
\
As Cohere and Writer mine the ‘LiveAI™’ arena, Pathway joins the pack with a $10M round](https://pathway.com/news/as-cohere-and-writer-mine-the-live-ai-arena-pathway-joins-the-pack-with-a-10m-round)
[News\
\
The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski](https://pathway.com/news/pathway-meetup-2024)
---
# ETCIO Southeast Asia covers Pathway Seed Round
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://ciosea.economictimes.indiatimes.com/amp/news/corporate/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai/115953873](https://ciosea.economictimes.indiatimes.com/amp/news/corporate/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai/115953873)
in a moment.
* * *
ET CIOSEA
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
cnbctv18\
\
newsDec 2, 2024\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
* [\
\
\
\
sifted.eu\
\
newsDec 6, 2022\
\
Female-led deeptech startup Pathway announces its $4.5m pre-seed round](https://pathway.com/news/female-led-deeptech-startup)
* [\
\
\
\
cnbctv18\
\
newsDec 6, 2024\
\
CNBC India spotlighting Pathway](https://pathway.com/news/cnbc-india-spotlighting-pathway)
[News\
\
Parisian AI startup Pathway on moving to the US: 'We need to be in the room where it happens, and it happens in the Bay Area](https://pathway.com/news/pathway-10m-seed-round-news)
[News\
\
LLM series - Pathway: Taking LLMs out of pilot into production](https://pathway.com/news/llm-series-pathway-taking-llms-out-of-pilot-into-production)
---
# A coffee with… Zuzanna Stamirowska | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://techinformed.com/a-coffee-with-zuzanna-stamirowska/](https://techinformed.com/a-coffee-with-zuzanna-stamirowska/)
in a moment.
* * *
TechInformed
[](https://techinformed.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
The Neuron\
\
news · podcast · bdhJan 6, 2026\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
* [\
\
\
\
We Are Tech Women\
\
newsAug 31, 2023\
\
Enabling AI to unlearn and self-correct like a human](https://pathway.com/news/wearewomen-article)
* [\
\
\
\
Maddyness\
\
newsJul 26, 2023\
\
Pathway named as a promising Generative AI leader (in French)](https://pathway.com/news/maddyness-gen-ai-mapping)
[News\
\
Pathway is featured as a best-suited vendor candidate for Analytics and Decision Intelligence solutions for Supply Chain by Gartner](https://pathway.com/news/gartner-a-n-di-solutions)
[News\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
---
# Parisian AI startup Pathway on moving to the US: 'We need to be in the room where it happens, and it happens in the Bay Area
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://sifted.eu/articles/pathway-10m-seed-round-news](https://sifted.eu/articles/pathway-10m-seed-round-news)
in a moment.
* * *

sifted.eu
[](https://sifted.eu/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
* [in French\
\
\
\
\
\
Les Echos\
\
newsAug 25, 2023\
\
Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](https://pathway.com/news/les-echos-deeptech)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsDec 19, 2024\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
[News\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
[News\
\
ETCIO Southeast Asia covers Pathway Seed Round](https://pathway.com/news/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai)
---
# BDH is the second most popular AI paper of 2025 | Pathway
Table of Contents
[The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://huggingface.co/papers/2509.26507)
ranked 2 in the Top 10 most upvoted papers on HuggingFace!
[View on X](https://x.com/HuggingPapers/status/2005312316829516222)
* * *

Hugging Face
[](https://pathway.com/news/huggingface.co)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
* [in Japanese\
\
\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
* [\
\
\
\
Turing Post\
\
news · bdhDec 29, 2025\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
[News\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
[News\
\
Tech That Will Change Your Life in 2026](https://pathway.com/news/tech-predictions-2026)
---
# Pathway launches new post-transformer architecture paving the way for autonomous AI
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.intelligentcio.com/eu/2025/10/03/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai/](https://www.intelligentcio.com/eu/2025/10/03/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai/)
in a moment.
* * *

Intelligent CIO
[](https://pathway.com/news/intelligentcio.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
Quantum Zeitgeist\
\
news · bdhAug 3, 2025\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
* [\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
[News\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
[News\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
---
# What the Transformer vs. Post-Transformer debate revealed about AI's next architecture | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.theneuron.ai/explainer-articles/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture/](https://www.theneuron.ai/explainer-articles/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture/)
in a moment.
* * *
The Neuron
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Pathway Team\
\
podcast · video · bdh · researchFeb 6, 2026\
\
The Post-Transformer Era: AI's Next Frontier | NYU x Pathway](https://pathway.com/news/the-post-transformer-era-ais-next-frontier-nyu-x-pathway)
* [\
\
\
\
MILA Tea Talk\
\
podcast · video · bdh · researchMar 10, 2026\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
[News\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[News\
\
Why continual learning and memory matters more than data in the next generation of AI](https://pathway.com/news/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai)
---
# Forbes: Pathway Navigates Next Road For AI Foundational Models
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.forbes.com/sites/adrianbridgwater/2025/02/13/pathway-navigates-next-road-for-ai-foundational-models/](https://www.forbes.com/sites/adrianbridgwater/2025/02/13/pathway-navigates-next-road-for-ai-foundational-models/)
in a moment.
* * *
Forbes
Adrian Bridgwater - Senior Contributor
[](https://www.forbes.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Quantum Zeitgeist\
\
news · bdhAug 3, 2025\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
[News\
\
Becoming AI-savvy: going beyond data smarts for business transformation](https://pathway.com/news/becoming-ai-savvy-for-transformation)
[News\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
---
# Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne
Table of Contents
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne
========================================================================
Pathway is proud to announce that Zuzanna Stamirowska, CEO at Pathway was awarded at Viva Technology, Europe’s biggest tech event, held in Paris, France.
Elisabeth Borne, the French Prime Minister awarded Zuzanna Stamirowska for her performance on stage and the achievements of Pathway as the most powerful data processing framework to power real-time data products and pipelines. This happened a few weeks after the CIO of Goldman Sachs declared that “going from batch to real-time (processing) was like going from printed newspapers to the Internet."
View on X
Pathway was brought to life by a stellar team: the CTO Jan Chorowski worked with the Godfathers of AI, Geoff Hinton, and Yoshua Bengio, the CSO Adrian Kosowski had his Ph.D. at 20 and is a world-class expert in high-scale distributed computing, and [Zuzanna Stamirowska](https://www.linkedin.com/in/stamirowska/)
is the author of the state of the art model for forecasting of maritime trade. Pathway is supported by business angels such as Lukasz Kaiser, known to be behind the “T” in GPT.
“Very soon real-time will become the norm for data processing and it’s a game changer for everybody starting from financial services, Formula 1, supply chains, online marketing, retail, energy… the list goes on.” declared Zuzanna Stamirowska during her pitch in front of the Viva Tech assembly.
Watch Pathway Winning Pitch

* * *

Zuzanna Stamirowska
CEO
[](https://www.linkedin.com/in/stamirowska/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Claire Nouet\
\
news · videoMar 4, 2025\
\
La Poste Optimizes Colissimo Flows in Real Time - Modern Data Stack Recording available](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time)
* [\
\
\
\
AWS Events\
\
news · bdh · videoDec 4, 2025\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
* [\
\
\
\
BFM Business\
\
newsMay 30, 2022\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
[News\
\
Pathway is a Representative Vendor in Gartner 2023 Market Guide for Analytics and Decision Intelligence Platforms in Supply Chain](https://pathway.com/news/gartner-market-guide-supply-chain)
[News\
\
Interview for Paris-Saclay](https://pathway.com/news/paris-saclay)
---
# Why the Future of AI Will Go Beyond Transformers | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://analyticsindiamag.com/ai-features/why-the-future-of-ai-will-go-beyond-transformers](https://analyticsindiamag.com/ai-features/why-the-future-of-ai-will-go-beyond-transformers)
in a moment.
* * *

Analytics India Magazine
[](https://pathway.com/news/analyticsindiamag.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [in Japanese\
\
\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
* [\
\
\
\
Express Computer\
\
bdhMay 14, 2026\
\
Why continual learning and memory matters more than data in the next generation of AI](https://pathway.com/news/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai)
* [\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
[News\
\
Why continual learning and memory matters more than data in the next generation of AI](https://pathway.com/news/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai)
[News\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
---
# The Post-Transformer Era: AI's Next Frontier | NYU x Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.youtube.com/watch?v=o9o7fU\_ZSIE](https://www.youtube.com/watch?v=o9o7fU_ZSIE)
in a moment.
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
The Neuron\
\
podcast · video · bdh · researchMay 19, 2026\
\
What the Transformer vs. Post-Transformer debate revealed about AI's next architecture](https://pathway.com/news/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture)
* [\
\
\
\
MILA Tea Talk\
\
podcast · video · bdh · researchMar 10, 2026\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
[News\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
[News\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
---
# Victor Szczerba assumes CCO role at Pathway post funding
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://itbrief.news/story/victor-szczerba-assumes-cco-role-at-pathway-post-funding](https://itbrief.news/story/victor-szczerba-assumes-cco-role-at-pathway-post-funding)
in a moment.
* * *
ITBrief
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
cnbctv18\
\
newsDec 2, 2024\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
* [\
\
\
\
Zuzanna Stamirowska\
\
news · videoJun 16, 2023\
\
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](https://pathway.com/news/vivatech-by-the-french-prime)
* [\
\
\
\
cnbctv18\
\
newsDec 6, 2024\
\
CNBC India spotlighting Pathway](https://pathway.com/news/cnbc-india-spotlighting-pathway)
[News\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility)
[News\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
---
# Enabling AI to unlearn and self-correct like a human | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://wearetechwomen.com/enabling-ai-to-unlearn-and-self-correct-iike-a-human/](https://wearetechwomen.com/enabling-ai-to-unlearn-and-self-correct-iike-a-human/)
in a moment.
* * *

We Are Tech Women
[](https://wearetechwomen.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Forbes\
\
news · bdhOct 8, 2025\
\
Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](https://pathway.com/news/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so)
* [\
\
\
\
Pathway Team\
\
news · case-studyNov 13, 2024\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
* [\
\
\
\
Semafor\
\
news · bdhOct 1, 2025\
\
New AI research claims to be getting closer to modeling human brain](https://pathway.com/news/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
[News\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
[News\
\
Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](https://pathway.com/news/les-echos-deeptech)
---
# Financial institution & Pathway success story
Success stories: Banking and Financial services with Pathway
============================================================
Scaled **high-accuracy** document answering for a European financial institution (~40B market cap)
50 minsEstimated daily productivity gain per customer representative
Customer reps reporting higher satisfaction
\-50%The anticipated cost of the solution in production
Results
Challenge
Providing customer service representatives with timely and accurate answers to client inquiries is costly and resource draining for retail banks. Documents are being updated constantly and it is hard for customer representatives to keep up with the pace of changes.
Issue
12-15kDaily queries
8k\# of documents
50+\# weekly changes to the database
Solution
Pathway offered a containerized solution to retrieve insights from the bank’s diverse data sources

**Pathway Live Data Framework's AI Pipeline**
* Live Data connectors: Ingested data from required sources
* Parsing: Extracted text, tables and metadata, from complex unstructured data
* Indexing: efficient in-memory index to adapt automatically to changing data
Product
[Pathway\
\
Success Stories](https://pathway.com/success-stories)
[Success Stories\
\
Defense: NATO](https://pathway.com/success-stories/nato)
---
# This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.youtube.com/watch?v=duw7RUif8hE](https://www.youtube.com/watch?v=duw7RUif8hE)
in a moment.
* * *
The Neuron
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
This Is The World\
\
news · podcast · bdhOct 4, 2025\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
* [\
\
\
\
Semafor\
\
news · bdhOct 1, 2025\
\
New AI research claims to be getting closer to modeling human brain](https://pathway.com/news/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
[News\
\
The Post-Transformer Era: AI's Next Frontier | NYU x Pathway](https://pathway.com/news/the-post-transformer-era-ais-next-frontier-nyu-x-pathway)
[News\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-and-pathway-partner)
---
# Embracing Modern Live Data Pipelines is Key to Scaling Enterprise AI | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.rtinsights.com/embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai/](https://www.rtinsights.com/embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai/)
in a moment.
* * *
RTInsights
[](https://www.rtinsights.com/author/three-amigos/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Saksham Goel\
\
newsNov 27, 2024\
\
Pathway Live Data Framework is Now Available on Microsoft Azure!](https://pathway.com/framework/blog/azure-aci-deploy)
* [\
\
\
\
Saksham Goel\
\
news · engineeringOct 29, 2024\
\
Build LLM/RAG pipelines with YAML templates by Pathway Live Data Framework](https://pathway.com/framework/blog/llm-yaml-templates)
* [\
\
\
\
Turing Post\
\
news · bdhDec 29, 2025\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
[News\
\
Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](https://pathway.com/news/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so)
[News\
\
Forbes Poland: CEO profile (in Polish)](https://pathway.com/news/forbes-poland-ceo-profile-in-polish)
---
# Becoming AI-savvy: going beyond data smarts for business transformation | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://techinformed.com/becoming-ai-savvy-for-transformation/](https://techinformed.com/becoming-ai-savvy-for-transformation/)
in a moment.
* * *

TechInformed
[](https://techinformed.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Claire Nouet\
\
newsApr 17, 2025\
\
From Data-sure To AI-savvy: Unlocking The Next Stage Of Business Transformation](https://pathway.com/news/from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsSep 24, 2023\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsFeb 9, 2024\
\
How Businesses Can Create Data Frameworks for Real-world AI](https://pathway.com/news/cdo-magazine)
[News\
\
La Poste Optimizes Colissimo Flows in Real Time - Modern Data Stack Recording available](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time)
[News\
\
Forbes: Pathway Navigates Next Road For AI Foundational Models](https://pathway.com/news/pathway-mentioned-in-the-financial-times)
---
# Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.youtube.com/watch?v=E6WmXnEFDgc](https://www.youtube.com/watch?v=E6WmXnEFDgc)
in a moment.
* * *

Eye on AI
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Quantum Zeitgeist\
\
news · bdhAug 3, 2025\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [\
\
\
\
AWS Startups\
\
news · bdhMay 3, 2026\
\
Pathway's BDH: a new post-transformer approach to enterprise AI, on AWS](https://pathway.com/news/pathways-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws)
[News\
\
How 'Neolabs' Are Betting Against the OpenAI Model and What It Means for Founders](https://pathway.com/news/how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders)
[News\
\
Can an artificial intelligence learn like a human brain does? A startup believes it has achieved this](https://pathway.com/news/inteligencia-artificial-aprender-cerebro-humano)
---
# Female-led deeptech startup Pathway announces its $4.5m pre-seed round
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://sifted.eu/articles/female-led-deeptech-pathway-ai/](https://sifted.eu/articles/female-led-deeptech-pathway-ai/)
in a moment.
* * *

sifted.eu
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
ET CIOSEA\
\
newsDec 4, 2024\
\
ETCIO Southeast Asia covers Pathway Seed Round](https://pathway.com/news/pathway-raises-10-million-in-funding-to-advance-the-development-of-live-ai)
* [\
\
\
\
cnbctv18\
\
newsDec 2, 2024\
\
Pathway raises $10 million in seed funding round](https://pathway.com/news/female-founded-pathway-raises-10m-to-power-future-of-live-ai-systems)
* [in French\
\
\
\
\
\
Les Echos\
\
newsAug 25, 2023\
\
Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges](https://pathway.com/news/les-echos-deeptech)
[News\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
[News\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
---
# From Data-sure To AI-savvy: Unlocking The Next Stage Of Business Transformation | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.techdogs.com/inspire/c-suite-scoops/from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation](https://www.techdogs.com/inspire/c-suite-scoops/from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation)
in a moment.
* * *
Claire Nouet
COO
[](https://www.linkedin.com/in/clairenouet/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
TechInformed\
\
newsFeb 27, 2025\
\
Becoming AI-savvy: going beyond data smarts for business transformation](https://pathway.com/news/becoming-ai-savvy-for-transformation)
* [in French\
\
\
\
\
\
Le Point\
\
newsJun 22, 2023\
\
Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](https://pathway.com/news/le-point)
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[News\
\
Forbes Poland: CEO profile (in Polish)](https://pathway.com/news/forbes-poland-ceo-profile-in-polish)
[News\
\
How 'Neolabs' Are Betting Against the OpenAI Model and What It Means for Founders](https://pathway.com/news/how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders)
---
# Forbes Poland: CEO profile (in Polish) | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.forbes.pl/polka-chce-wstrzasnac-dolina-krzemowa-z-jej-produktu-korzystaja-juz-intel-i-nato/7bmkk92](https://www.forbes.pl/polka-chce-wstrzasnac-dolina-krzemowa-z-jej-produktu-korzystaja-juz-intel-i-nato/7bmkk92)
in a moment.
* * *
Forbes
[](https://www.forbes.pl/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
* [\
\
\
\
Maddyness\
\
newsJul 26, 2023\
\
Pathway named as a promising Generative AI leader (in French)](https://pathway.com/news/maddyness-gen-ai-mapping)
* [\
\
\
\
Unite AI\
\
newsSep 26, 2025\
\
Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series](https://pathway.com/news/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series)
[News\
\
Embracing Modern Live Data Pipelines is Key to Scaling Enterprise AI](https://pathway.com/news/embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai)
[News\
\
From Data-sure To AI-savvy: Unlocking The Next Stage Of Business Transformation](https://pathway.com/news/from-data-sure-to-ai-savvy-unlocking-the-next-stage-of-business-transformation)
---
# Can an artificial intelligence learn like a human brain does? A startup believes it has achieved this | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://es-us.noticias.yahoo.com/inteligencia-artificial-aprender-cerebro-humano-231500859.html](https://es-us.noticias.yahoo.com/inteligencia-artificial-aprender-cerebro-humano-231500859.html)
in a moment.
* * *
Forbes Argentina
[](https://www.forbes.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Forbes\
\
news · bdhOct 8, 2025\
\
Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](https://pathway.com/news/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so)
* [\
\
\
\
The Neuron\
\
news · podcast · bdhJan 6, 2026\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
* [\
\
\
\
Live Science\
\
news · bdhNov 13, 2025\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
[News\
\
Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](https://pathway.com/news/inside-pathways-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
[News\
\
La Poste partners with Pathway to create digital twin of fleet](https://pathway.com/news/la-poste-partners-with-pathway-to-create-digital-twin-of-fleet)
---
# Client Testimonial: La Poste at Modern Data Stack | Pathway
Table of Contents
Client Testimonial: La Poste at Modern Data Stack
=================================================
Jean-Paul Fabre, Head of Technological Innovation at the Group La Poste, will present how several analytical use cases - network optimization, asset utilization improvement, flow management, Paris 2024 Olympic Games preparation, etc - are enabled by a digital twin and a data model that combines batch and streaming data thanks to Pathway unified engine.
[Modern Data Stack](https://www.linkedin.com/company/modern-data-stack-france/posts/?feedView=all)
is a community for knowledge-sharing and networking around data thanks to cutting-edge tech.
In January, [Modern Data Stack](https://www.linkedin.com/company/modern-data-stack-france/posts/?feedView=all)
will host in Criteo’s offices in Paris around streaming and the modern data stack.
In addition to La Poste, Decathlon, Michelin, BPCE, OVH Cloud and Christophe Blefari will also share their experience and use cases.
Sign up for the event on January 31st, in Paris - it’s free. Let us know if you are coming!
[Sign up for the event](https://docs.google.com/forms/d/e/1FAIpQLSd7R-EUtGDZtvknd5ImTrSE754XhY96KlZeY5Qd_8A9tfekkA/viewform)
* * *
Modern Data Stack
[](https://www.linkedin.com/company/modern-data-stack-france/)
[](https://www.meetup.com/fr-FR/modern-data-stack-france/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Claire Nouet\
\
news · videoMar 4, 2025\
\
La Poste Optimizes Colissimo Flows in Real Time - Modern Data Stack Recording available](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time)
* [\
\
\
\
RTInsights\
\
newsMar 19, 2025\
\
Embracing Modern Live Data Pipelines is Key to Scaling Enterprise AI](https://pathway.com/news/embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai)
* [\
\
\
\
IoT Insider\
\
newsJun 22, 2025\
\
La Poste partners with Pathway to create digital twin of fleet](https://pathway.com/news/la-poste-partners-with-pathway-to-create-digital-twin-of-fleet)
[News\
\
How Businesses Can Create Data Frameworks for Real-world AI](https://pathway.com/news/cdo-magazine)
[News\
\
Pathway named among the Top Startups Transforming the European business landscape](https://pathway.com/news/eu-startup-news)
---
# Pathway quoted in Les Echos: Deeptech - the answer to tomorrow's challenges
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.lesechos.fr/idees-debats/cercle/opinion-la-deeptech-est-la-reponse-aux-defis-de-demain-1972505](https://www.lesechos.fr/idees-debats/cercle/opinion-la-deeptech-est-la-reponse-aux-defis-de-demain-1972505)
in a moment.
* * *

Les Echos
Economic and financial news from France
[](https://www.lesechos.fr/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
* [\
\
\
\
BFM Business\
\
newsMay 30, 2022\
\
Pathway on BFM Business - the French Business TV channel](https://pathway.com/news/bfmtv)
[News\
\
Enabling AI to unlearn and self-correct like a human](https://pathway.com/news/wearewomen-article)
[News\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
---
# French deep tech start-up announces the general launch of its data processing engine | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.maddyness.com/2023/07/26/pathway-ia/](https://www.maddyness.com/2023/07/26/pathway-ia/)
in a moment.
* * *
Maddyness
[](https://www.maddyness.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
The Next Web\
\
newsJul 26, 2023\
\
AI startup launches ‘fastest data processing engine’ on the market](https://pathway.com/news/nextweb-article)
* [in French\
\
\
\
\
\
Le Point\
\
newsJun 22, 2023\
\
Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](https://pathway.com/news/le-point)
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[News\
\
Pathway named as a promising Generative AI leader (in French)](https://pathway.com/news/maddyness-gen-ai-mapping)
[News\
\
AI startup launches ‘fastest data processing engine’ on the market](https://pathway.com/news/nextweb-article)
---
# New podcast: Europe’s AI opportunity | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://sifted.eu/articles/new-podcast-europes-ai-opportunity-brnd](https://sifted.eu/articles/new-podcast-europes-ai-opportunity-brnd)
in a moment.
* * *

sifted.eu
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
The Neuron\
\
news · podcast · bdhJan 6, 2026\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
* [\
\
\
\
This Is The World\
\
news · podcast · bdhOct 4, 2025\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
[News\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
[News\
\
Pathway to the Silicon Valley](https://pathway.com/news/newsletter-2025-02-25)
---
# La Poste Optimizes Colissimo Flows in Real Time - Modern Data Stack Recording available | Pathway
Table of Contents
La Poste Group is using Pathway Live Data Framework real-time data processing capabilities to optimize the flows of its well-known Colissimo business line. Jean-Paul Fabre, the Head of Technological innovation at La Poste, and Claire Nouet, the co-founder of Pathway, discussed the collaboration during the Modern Data Stack summit in Paris.
Learn how [La Poste Group](https://www.linkedin.com/company/la-poste-groupe/)
deployed ‘operational speed’ AI to forecast more accurately, assess disruption and automate key processes, improving operations in a meaningful way! (The video is in French, recap below!)

[Read more about the case study](https://pathway.com/success-stories/la-poste)
[Challenges Faced by La Poste](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time#challenges-faced-by-la-poste)
--------------------------------------------------------------------------------------------------------------------------------------
* La Poste handles a high volume of packages across 17 industrial platforms, has more than 400 truck movements daily, and 16 million+ unused data points.
* Need to provide platform operators with real-time information on truck arrival times, origins, and destinations.
* Requirement to improve efficiency to avoid congestion and incidents.
* Need to identify anomalies in real-time
[Key Objectives and Benefits](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time#key-objectives-and-benefits)
------------------------------------------------------------------------------------------------------------------------------------
* **Reduce costs**: Pathway Live Data Framework is more cost-effective than existing outsourced solutions, with savings reinvested in functional improvements.
* **Leverage data**: La Poste generates approximately 16 million geolocation points annually but was not fully utilizing this data. Pathway helps make sense of this data and turn it into actionable insights.
* **Simplify infrastructure**: Pathway Live Data Framework enables easier integration of different acquisition platforms and sensors and facilitates predictive calculations and rapid prototyping.
[How Pathway Live Data Framework Works](https://pathway.com/news/la-poste-optimizes-colissimo-flows-in-real-time#how-pathway-live-data-framework-works)
--------------------------------------------------------------------------------------------------------------------------------------------------------
* **Network Identification**: Pathway Live Data Framework identifies nodes (e.g. locations where trucks stop for a significant time) within the network. It differentiates between relevant nodes (e.g., platforms) and irrelevant ones (e.g., driver rest stops).
* **Route Analysis**: Pathway Live Data Framework determines the primary routes between platforms and identifies alternative routes. This helps La Poste understand if drivers are using preferred (e.g., tolled) routes or opting for alternative routes.
* **Data Integration**: Pathway Live Data Framework concentrates real-time geolocation data and historical data on a single platform. This creates a digital twin of the network, which can be used for real-time monitoring and analysis.
* **Real-time data processing**: Data scientists can work with real-time data in Jupiter Notebooks, and code can be moved directly into production, improving productivity.
* **Anomaly Detection**: Uses machine learning to detect anomalies with security implications.
* **GPS Data Enhancement**: Pathway Live Data Framework automatically creates polygons based on GPS quality to filter out errors and false positives caused by signal fluctuations and metallic buildings.
* * *
Claire Nouet
COO
[](https://www.linkedin.com/in/clairenouet/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
news · videoJun 16, 2023\
\
Pathway awarded at VivaTech by the French Prime Minister Elisabeth Borne](https://pathway.com/news/vivatech-by-the-french-prime)
* [\
\
\
\
AWS Events\
\
news · bdh · videoDec 4, 2025\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
* [\
\
\
\
Modern Data Stack\
\
newsDec 1, 2023\
\
Client Testimonial: La Poste at Modern Data Stack](https://pathway.com/news/modern-data-stack)
[News\
\
100 Women in Tech](https://pathway.com/news/100-women-in-tech-2025)
[News\
\
Becoming AI-savvy: going beyond data smarts for business transformation](https://pathway.com/news/becoming-ai-savvy-for-transformation)
---
# Brain-inspired AI model 'BDH' may surpass the limits of Transformers | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://xenospectrum.com/pathway-bdh-brain-inspired-ai-architecture/](https://xenospectrum.com/pathway-bdh-brain-inspired-ai-architecture/)
in a moment.
* * *

Radical Data Science
[](https://pathway.com/news/xenospectrum.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
* [\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
[News\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
[News\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
---
# Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.businesswire.com/news/home/20251201914013/en/Pathway-to-Deliver-New-Class-of-Adaptive-and-Continuously-Learning-AI-Systems-with-AWS-and-NVIDIA-Technologies](https://www.businesswire.com/news/home/20251201914013/en/Pathway-to-Deliver-New-Class-of-Adaptive-and-Continuously-Learning-AI-Systems-with-AWS-and-NVIDIA-Technologies)
in a moment.
* * *

businesswire
[](https://pathway.com/news/businesswire.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
AWS Events\
\
news · bdh · videoDec 4, 2025\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
* [\
\
\
\
ET Edge Insights\
\
news · bdhMar 12, 2026\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
* [\
\
\
\
Eye on AI\
\
news · bdhMar 11, 2026\
\
Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](https://pathway.com/news/inside-pathways-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
[News\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
[News\
\
Pathway's BDH: a new post-transformer approach to enterprise AI, on AWS](https://pathway.com/news/pathways-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws)
---
# That Hint Where AI Is Heading | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.turingpost.com/p/fod133](https://www.turingpost.com/p/fod133)
in a moment.
* * *

Turing Post
[](https://pathway.com/news/turingpost.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
AWS Events\
\
news · bdh · videoDec 4, 2025\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
[News\
\
Tech That Will Change Your Life in 2026](https://pathway.com/news/tech-predictions-2026)
[News\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
---
# Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://quantumzeitgeist.com/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai/](https://quantumzeitgeist.com/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai/)
in a moment.
* * *

Quantum Zeitgeist
[](https://pathway.com/news/quantumzeitgeist.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
Eye on AI\
\
news · bdhMar 11, 2026\
\
Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](https://pathway.com/news/inside-pathways-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
[News\
\
Opinion: EU could be epicenter of AI academia as US cuts funding](https://pathway.com/news/opinion-eu-could-be-epicenter-of-ai-academia-as-us-cuts-funding)
[News\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
---
# The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://huggingface.co/papers/2509.26507](https://huggingface.co/papers/2509.26507)
in a moment.
* * *

Hugging Face
[](https://pathway.com/news/huggingface.co)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
* [\
\
\
\
Arxiv.org\
\
bdh · researchNov 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/arxiv-bdh)
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[News\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
[News\
\
The Post-Transformer Era: AI's Next Frontier | NYU x Pathway](https://pathway.com/news/the-post-transformer-era-ais-next-frontier-nyu-x-pathway)
---
# Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.unite.ai/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series/](https://www.unite.ai/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series/)
in a moment.
* * *

Unite AI
[](https://pathway.com/news/unite.ai)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Zuzanna Stamirowska\
\
newsDec 19, 2024\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
* [in French\
\
\
\
\
\
Les Echos\
\
newsJan 9, 2023\
\
Pathway in Les Echos - CEO Portrait](https://pathway.com/news/lesechosdeeptechportrait)
* [in French\
\
\
\
\
\
Le Point\
\
newsJun 22, 2023\
\
Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](https://pathway.com/news/le-point)
[News\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
[\_benchmarks\
\
Beyond State-of-the-Art Reasoning](https://pathway.com/_benchmarks/beyond-state-of-the-art-reasoning)
---
# Why today’s AI struggles with the real world, and what comes next | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://etedge-insights.com/technology/artificial-intelligence/why-todays-ai-struggles-with-the-real-world-and-what-comes-next/](https://etedge-insights.com/technology/artificial-intelligence/why-todays-ai-struggles-with-the-real-world-and-what-comes-next/)
in a moment.
* * *

ET Edge Insights
[](https://pathway.com/news/etedge-insights.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Inc.\
\
news · bdhDec 21, 2025\
\
How 'Neolabs' Are Betting Against the OpenAI Model and What It Means for Founders](https://pathway.com/news/how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
[News\
\
Why the Future of AI Will Go Beyond Transformers](https://pathway.com/news/why-the-future-of-ai-will-go-beyond-transformers)
[News\
\
Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series](https://pathway.com/news/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series)
---
# What Sudoku reveals about the limits of LLMs | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.techradar.com/pro/what-sudoku-reveals-about-the-limits-of-llms](https://www.techradar.com/pro/what-sudoku-reveals-about-the-limits-of-llms)
in a moment.
* * *

techradar
[](https://pathway.com/news/www.techradar.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [in Japanese\
\
\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
* [\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
* [\
\
\
\
Hugging Face\
\
news · bdh · developerSep 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
[News\
\
Victor Szczerba assumes CCO role at Pathway post funding](https://pathway.com/news/victor-szczerba-assumes-cco-role-at-pathway-post-funding)
[News\
\
What the Transformer vs. Post-Transformer debate revealed about AI's next architecture](https://pathway.com/news/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture)
---
# DB Schenker & Pathway success story
Success stories: DB Schenker and Pathway
========================================
**Quick ROI**: DB Schenker reduced the time-to-market of their analytics project from 3 months to 1 hour, for a fraction of the cost, and got the possibility to offer business insights faster to their clients, even for those who have not rolled-out any IoT hardware. 
[Business case](https://pathway.com/success-stories/db-schenker#business-case)
-------------------------------------------------------------------------------
DB Schenker offers a visibility platform to its clients. Until recently, the value of visibility was limited to tracking. Unlocking the value of this data meant expensive and lengthy projects. These turned out to be one-off data science projects which were expensive to run and hard to reproduce.

> _Pathway is a very clever, very dynamic company, focusing on algorithmics to prepare for better and smoother logistics and supply chains. Their talent and their knowledge is outstanding. We are very proud to launch a close collaboration._
### [How to increase OTIF?](https://pathway.com/success-stories/db-schenker#how-to-increase-otif)
DB Schenker was determined to answer the needs of its clients. Information about risks of damage to cargo or transport planning was missing. This inhibited the strategic decision process at DB Schenker.
[Road to intelligent logistics and peace of mind](https://pathway.com/success-stories/db-schenker#road-to-intelligent-logistics-and-peace-of-mind)
---------------------------------------------------------------------------------------------------------------------------------------------------
After feeding raw IoT data into the Pathway Live Data Framework Logistics App, DB Schenker received:
* **Anomaly detection**: sudden change of mode of transport, rerouting, idling, damage to cargo etc., without the need to pre-define alert rules
* **Automatic risk assessment**: highlighting places where transports accumulate delays & shocks, transport with significant shocks/vibrations
* **Automatic identification** of underperforming, and/or malfunctioning sensors
* **Automatic** detection and precise **mapping** of geofences
[Solving critical supply chain issues](https://pathway.com/success-stories/db-schenker#solving-critical-supply-chain-issues)
-----------------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework Logistics Application is a **one-stop-shop cloud-based application to provide immediately actionable insights on top of data for logistic assets**, including IoT data and status data. The Logistics Application is [Pathway's lighthouse data product](https://pathway.com/developers/templates/etl/logistics)
, built on the Pathway Live Data Framework.
[Success Stories\
\
Shipping: CMA CGM](https://pathway.com/success-stories/cma-cgm)
[News\
\
100 Women in Tech](https://pathway.com/news/100-women-in-tech-2025)
---
# La Poste & Pathway success story
Success stories: La Poste and Pathway
=====================================
La Poste reduced their data platform costs **by 50%**.

50%TCO reduction for their IoT data platform
16%Fleet CAPEX reduction
Results
Challenge
The high total cost of ownership, for both the IoT hardware and the associated legacy data platform, coupled with the inability to effectively analyze data at scale, prevents the company from realizing the full potential of its IoT investments.
Issue
Millionsof unusable data points
internal integration challenges
Solution
Improving processes related to transport units to anticipate operations automatically in real-time, and generating a live qualitative analysis of transport operations.
Customer feedback
It's a paradigm shift. We never thought something like this would be possible. We are getting a real dynamic, AI-powered digital twin out of pure IoT data. The ROI for our operations is enormous.
Jean-Paul Fabre - Head of Technological innovation
**Pathway's Pathway Live Data Framework**
* All mined from raw IoT location data streams, all in Pathway
* Uber-like live arrival information for La Poste's assets in motion
Product
Listen to La Poste talk about their use case at the Modern Data Stack Conference (in French)

[Business case](https://pathway.com/success-stories/la-poste#business-case)
----------------------------------------------------------------------------
La Poste wanted to move towards intelligent logistics by turning IoT data from postal containers into actionable business insights.
> _We wanted to conduct transportation analysis to find opportunities for improvement, optimization, and be able to identify **anomalies**._
[Goals](https://pathway.com/success-stories/la-poste#goals)
------------------------------------------------------------
* Improve geolocation of heavy transport.
* Improve asset utilization.
* Provide data-driven decision support for transport management.
* Predict operations in an automated way in real time.
* Future-proof the system’s architecture.
[Getting to intelligent logistics in a matter of days with the Pathway Live Data Framework](https://pathway.com/success-stories/la-poste#getting-to-intelligent-logistics-in-a-matter-of-days-with-the-pathway-live-data-framework)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
La Poste fed raw IoT data into the Pathway Live Data Framework. Thanks to the automatic analysis of sensor performance, La Poste was able to inform its purchasing strategy. The total cost of ownership was reduced because of the minimized hardware spend.
The Pathway Live Data Framework also provided them with a dynamic mapping of the transport process in an ever-changing context.
They were then able to advance to a mindset where the business can focus on routes, locations, and processes to be enhanced, rather than the per asset view delivered by the data source.
[The Pathway Live Data Framework is changing the paradigm for Enterprise clients](https://pathway.com/success-stories/la-poste#the-pathway-live-data-framework-is-changing-the-paradigm-for-enterprise-clients)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
> _In our previous solution, we were thinking about containers. Today we think of routes, platforms. The object being manipulated is much more **powerful**._
[Automatic structuring of La Poste’s operations: geofences, routes, depots](https://pathway.com/success-stories/la-poste#automatic-structuring-of-la-postes-operations-geofences-routes-depots)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
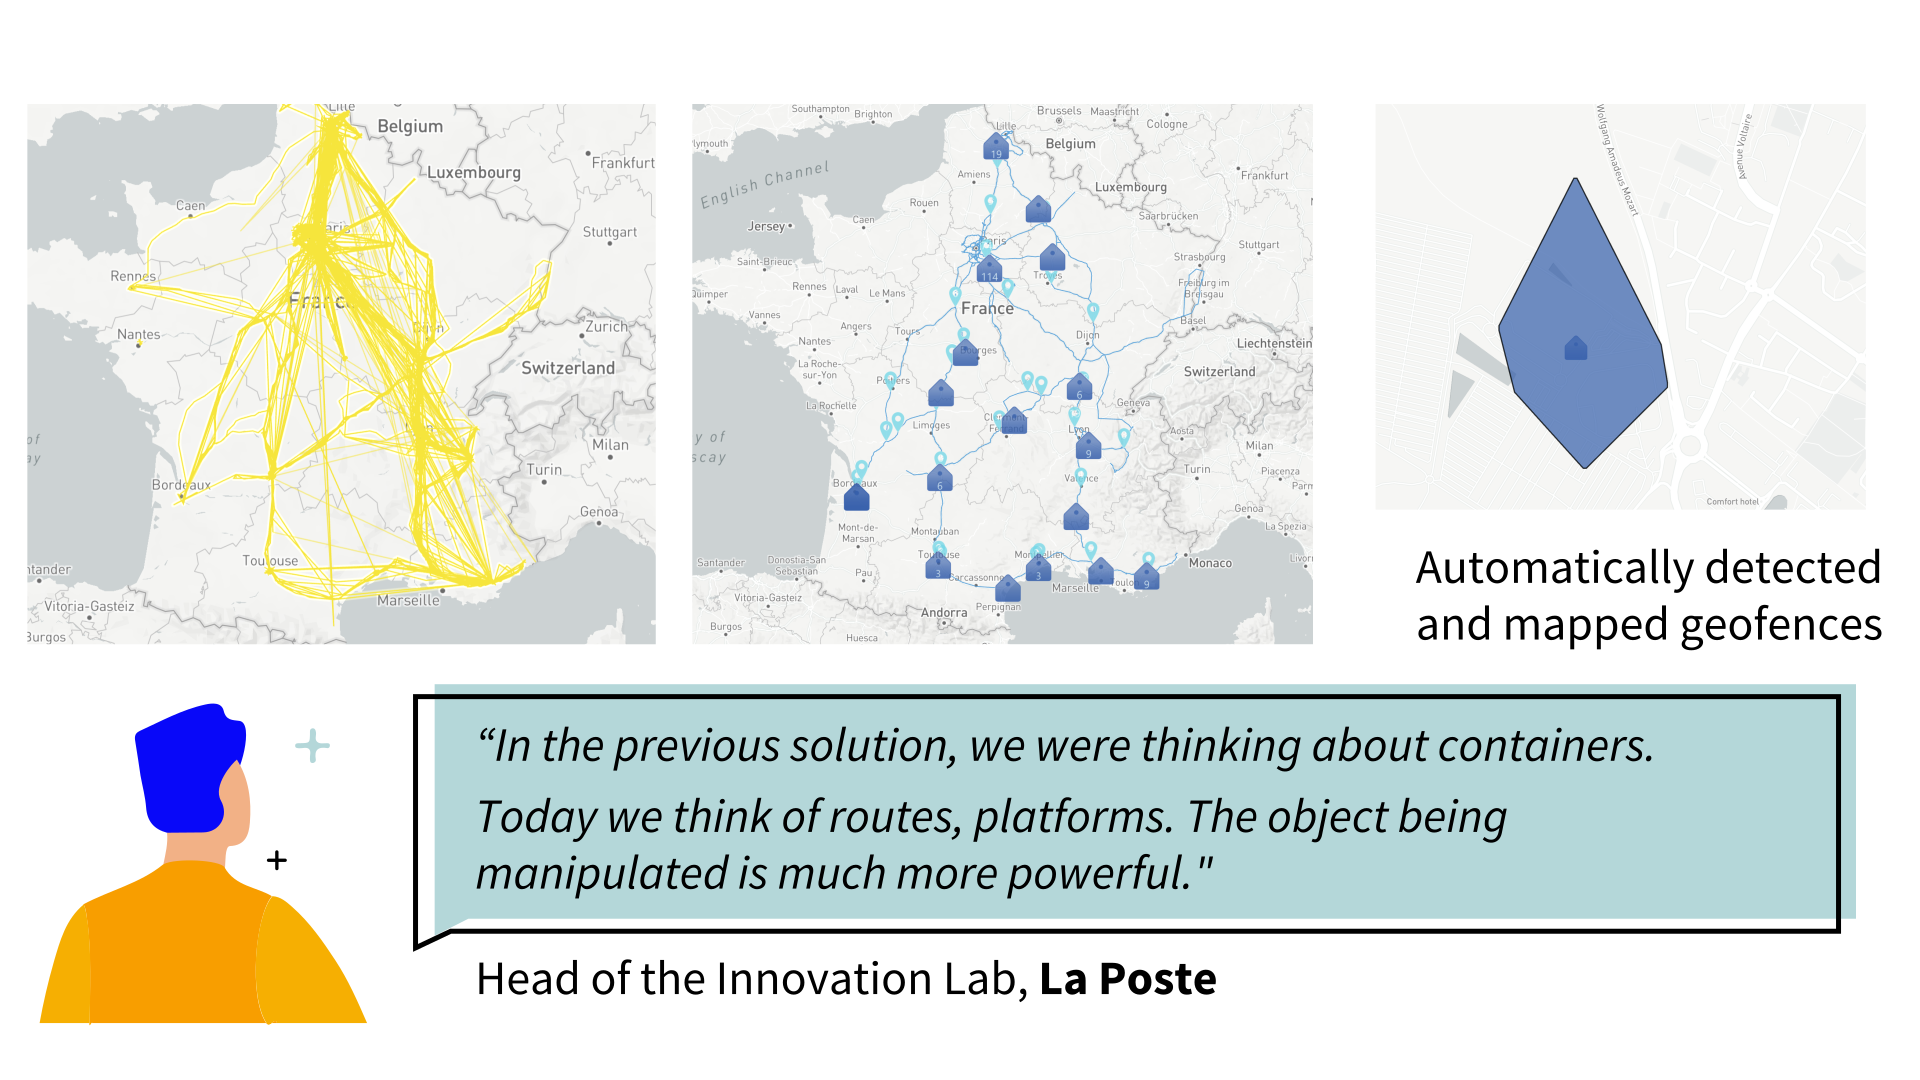
[Success Stories\
\
Defense: NATO](https://pathway.com/success-stories/nato)
[Success Stories\
\
Mobility: Transdev](https://pathway.com/success-stories/transdev)
---
# New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.livescience.com/technology/artificial-intelligence/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim](https://www.livescience.com/technology/artificial-intelligence/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
in a moment.
* * *

Live Science
[](https://pathway.com/news/livescience.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Semafor\
\
news · bdhOct 1, 2025\
\
New AI research claims to be getting closer to modeling human brain](https://pathway.com/news/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
[News\
\
New AI research claims to be getting closer to modeling human brain](https://pathway.com/news/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
[News\
\
New podcast: Europe’s AI opportunity](https://pathway.com/news/new-podcast-europes-ai-opportunity-brand)
---
# Pathway named as a promising Generative AI leader (in French)
Table of Contents
Pathway named as a promising Generative AI leader (in French)
=============================================================
The generative AI market was worth almost $40 billion in 2022 and should approach $70 billion by the end of this year, according to [Bloomberg Intelligence](https://www.bloomberg.com/company/press/generative-ai-to-become-a-1-3-trillion-market-by-2032-research-finds/)
. And this is just the beginning, as the market is expected to reach $1,300 billion by 2032 (Source: [Bloomberg: Generative AI to Become a $1.3 Trillion Market by 2032, Research Finds.](https://www.bloomberg.com/company/press/generative-ai-to-become-a-1-3-trillion-market-by-2032-research-finds/)
)
[Resonance Venture](https://www.resonance.vc/)
, a French Venture Capital, released a mapping of the main GenAI players in France, including established French companies such as Hugging Face.
[Pathway](https://pathway.com/)
is the single, integrated processing layer for real-time intelligence. It allows easy mix-and-match of batch, streaming, and LLM architectures - all within one engine.
Real-time learning is made possible by an effective and scalable engine, which powers LLMs and machine learning models. These models are automatically updated thanks to a framework that combines streaming and batch data, and which is user-friendly and flexible for developers, data engineers, and data scientists. Leading experts in the field of artificial intelligence make up the team, which is headed by Zuzanna Stamirowska. They include CTO Jan Chorowski, co-authors of Geoff Hinton and Yoshua Bengio, as well as Business Angel Lukasz Kaiser, who co-authored Tensor Flow and is also known as the "T" in ChatGPT.
**Zuzanna Stamirowska, CEO & Co-Founder of Pathway**, comments: “Our mission has been to enable real-time data processing, while giving developers a simple experience regardless of whether they work with batch, streaming, or LLM systems. Pathway is truly facilitating the convergence of historical and real-time data for the first time.”

Read the full article on Maddyness: [https://www.maddyness.com/2023/07/21/france-europe-ia-generative/](https://www.maddyness.com/2023/07/21/france-europe-ia-generative/)
* * *

Maddyness
[](https://www.maddyness.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
* [\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
* [\
\
\
\
TechCrunch\
\
newsNov 29, 2024\
\
As Cohere and Writer mine the ‘LiveAI™’ arena, Pathway joins the pack with a $10M round](https://pathway.com/news/as-cohere-and-writer-mine-the-live-ai-arena-pathway-joins-the-pack-with-a-10m-round)
[News\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
[News\
\
French deep tech start-up announces the general launch of its data processing engine](https://pathway.com/news/maddyness-article-about-pathway)
---
# New AI research claims to be getting closer to modeling human brain | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.semafor.com/article/10/01/2025/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain](https://www.semafor.com/article/10/01/2025/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
in a moment.
* * *

Semafor
[](https://pathway.com/news/semafor.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Live Science\
\
news · bdhNov 13, 2025\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
* [\
\
\
\
This Is The World\
\
news · podcast · bdhOct 4, 2025\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
[News\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
[News\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
---
# BDH: The Missing Link between the Transformer and Models of the Brain | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.youtube.com/watch?v=aCc5f16WDIg](https://www.youtube.com/watch?v=aCc5f16WDIg)
in a moment.
* * *

MILA Tea Talk
[](https://pathway.com/news/mila.quebec)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
The Neuron\
\
podcast · video · bdh · researchMay 19, 2026\
\
What the Transformer vs. Post-Transformer debate revealed about AI's next architecture](https://pathway.com/news/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture)
* [\
\
\
\
Pathway Team\
\
podcast · video · bdh · researchFeb 6, 2026\
\
The Post-Transformer Era: AI's Next Frontier | NYU x Pathway](https://pathway.com/news/the-post-transformer-era-ais-next-frontier-nyu-x-pathway)
* [\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
[News\
\
La Poste partners with Pathway to create digital twin of fleet](https://pathway.com/news/la-poste-partners-with-pathway-to-create-digital-twin-of-fleet)
[News\
\
New AI research claims to be getting closer to modeling human brain](https://pathway.com/news/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
---
# OpenAI claims AI is making coding jobs better, not worse. Is it true? | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.fastcompany.com/91411004/open-ai-coding-jobs-silicon-valley-google](https://www.fastcompany.com/91411004/open-ai-coding-jobs-silicon-valley-google)
in a moment.
* * *

Fast Company
[](https://pathway.com/news/fastcompany.com)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Turing Post\
\
news · bdhDec 29, 2025\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
* [\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
* [\
\
\
\
RTInsights\
\
newsMar 19, 2025\
\
Embracing Modern Live Data Pipelines is Key to Scaling Enterprise AI](https://pathway.com/news/embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai)
[News\
\
WSJ: Pathway marks the beginning of the post-transformer era](https://pathway.com/news/newsletter-2026-01-15)
[News\
\
Opinion: EU could be epicenter of AI academia as US cuts funding](https://pathway.com/news/opinion-eu-could-be-epicenter-of-ai-academia-as-us-cuts-funding)
---
# The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski | Pathway
Table of Contents
The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski
======================================================================
In April 2024, Pathway hosted an incredible meetup in San Francisco, bringing together some of the brightest minds in AI and data science.
We welcomed Łukasz Kaiser, co-author of ["Attention is All You Need"](https://arxiv.org/abs/1706.03762)
and Jan Chorowski, Pathway’s CTO, who shared their vision on the future of Large Language Models and the roadmap towards more intelligent foundational Large Language Models (LLMs). Joined by many senior developers, architects, and founders working on generative AI projects, they discussed the evolution of deep learning, the role of Reinforcement Learning with Human Feedback, the future of LLMs, and how achieving infinite LLM Context Windows can be made possible through innovative engineering and efficient retrieval mechanisms.
[Key Topics Covered by Lukasz Kaiser and Jan Chorowski:](https://pathway.com/news/pathway-meetup-2024#key-topics-covered-by-lukasz-kaiser-and-jan-chorowski)
-------------------------------------------------------------------------------------------------------------------------------------------------------------
1. Role of Retrievers in Reinforcement Learning for Intelligent LLMs Łukasz Kaiser, a renowned researcher at OpenAI who is a co-author of TensorFlow and Transformer Architecture as well as core contributor of Open AI’s GPT-4 and ChatGPT, explored the evolution and future of deep learning technologies and their future.
He emphasized that more data and compute lead to better results but highlighted the impending data scarcity. Łukasz discussed how in the future, training with fewer, high-quality retrieved data points will be the key to enhancing LLM performance. He also explained the importance of powerful retrieval mechanisms, integrating personal and organizational knowledge graphs, and efficient context provisioning for effective Reinforcement Learning with Human Feedback. Additionally, Łukasz mentioned a missed observation on parsing from his seminal paper "Attention is All You Need," and shared his vision for future Large Language Models (LLMs).
3. How Retrievers and LLMs Help Each Other and Achieving Infinite LLM Context Windows
Jan Chorowski, CTO of Pathway and a prominent figure in AI and NLP, extended the discussion by focusing on the essential role of context and retrieval in AI systems.
Building on Łukasz Kaiser's insights, he highlighted the "yin and yang” relationship between Large Language Models (LLMs) and retrieval systems. Effective LLM performance and reinforcement learning require robust retrieval mechanisms, and efficient retrieval relies on the processing power of LLMs. Jan shared an [example of Adaptive Retrieval Augmented Generation (RAG)](https://pathway.com/developers/templates/rag/adaptive-rag)
where they achieved great accuracy at a quarter of the cost by leveraging LLM preprocessing. He emphasized the need for tighter integration to achieve infinite LLM Context Windows and cost-effective AI solutions, inviting the audience to explore these concepts further with resources and examples at [Pathway's developer site](https://pathway.com/developers/user-guide/introduction/welcome)
.
Watch the recording:
* Talk 1: Deep Learning Past and Future: What Comes After GPT? by Lukasz Kaiser (“Attention is All you Need” co-author, Senior Researcher at OpenAI)
* Talk 2: Taming Unstructured Data: Which Indexing Strategy Wins? by Jan Chorowski (CTO, [Pathway](https://pathway.com/)
)
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Hugging Face\
\
news · bdh · developerSep 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
* [in French\
\
\
\
\
\
Le Point\
\
newsJun 22, 2023\
\
Pathway CEO featured in the ranking of the next generation of geniuses by the French national weekly Le Point](https://pathway.com/news/le-point)
* [\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[News\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
[News\
\
How Businesses Can Create Data Frameworks for Real-world AI](https://pathway.com/news/cdo-magazine)
---
# NATO & Pathway success story
Success stories: NATO and Pathway
=================================
NATO is using Pathway to build their AI tech stack, enabling **a new generation of use cases**.

Enables use cases that were not possible before
< 1 secData latency
Results
Challenge
Combining military data sources and open-source information such as civil traffic, social media alerts, and media in real-time for the planning and execution of military operations is complex.
Issue
24\# of Nations involved
250\# of people involved
10+Live data sources
Solution
Pathway developed the cornerstone for further development of AI-supported solutions to NATO.
Customer feedback
Robust and innovative data processing technology such as delivered by Pathway, unlocks new capabilities for critical use cases at scale.
Major General Gerry Ewart-Brookes, Deputy Chief of Staff Plans, NATO
**Pathway's Pathway Live Data Framework**
* Provides real-time analytics to strategic decision-makers, thanks to contextualized ML models
* Connected to ever-changing military and open source data
* Meets strict security requirements and deployment constraints
Product
[Read the Press Release](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
[Success Stories\
\
Banking and Financial services](https://pathway.com/success-stories/bank)
[Success Stories\
\
Postal Services: La Poste](https://pathway.com/success-stories/la-poste)
---
# Why continual learning and memory matters more than data in the next generation of AI | Pathway
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.expresscomputer.in/guest-blogs/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai/135038/](https://www.expresscomputer.in/guest-blogs/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai/135038/)
in a moment.
* * *

Express Computer
[](https://pathway.com/news/expresscomputer.in)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
ET Edge Insights\
\
news · bdhMar 12, 2026\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
* [\
\
\
\
Analytics India Magazine\
\
bdhApr 23, 2026\
\
Why the Future of AI Will Go Beyond Transformers](https://pathway.com/news/why-the-future-of-ai-will-go-beyond-transformers)
* [\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
[News\
\
What the Transformer vs. Post-Transformer debate revealed about AI's next architecture](https://pathway.com/news/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture)
[News\
\
Why the Future of AI Will Go Beyond Transformers](https://pathway.com/news/why-the-future-of-ai-will-go-beyond-transformers)
---
# Transdev & Pathway success story
Success stories: Transdev and Pathway
=====================================
Transdev improves public mobility with **real-time AI**

Flagging operational anomalies live
+6% pointETA accuracy
Results
Challenge
Operational inefficiencies and degraded customer experience due to inaccurate processing of real-time data
Issue
Thousandsof unusable data points
erroneous information communicated to users
Solution
The Pathway Live Data Framework geospatial pipeline to deliver insights and support decision-making based on always up-to-date knowledge
Customer feedback
Pathway offers an AI framework that reduces complexity, cost and time-to-market while guaranteeing reliable outputs. Operating efficiently in the mobility sector demands a clear view of data relevant in the moment, which is challenging to harness. Our partnership with Pathway means our decisions can be based on live, real-time data.
Julien Réau - Innovation Director
**Pathway's Pathway Live Data Framework**
* Enabled intelligent live operations graphs
* Easy Synchronization with real-time data sources
* Precise interpretation of available data
* Easy to put into production
Product
[Read the Press Release](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility)
**Transdev** provides multimodal, sustainable and inclusive transport solutions in 19 countries across Europe, North America, South America, Africa and Oceania. The company controls more than 150 transport business lines.

[Success Stories\
\
Postal Services: La Poste](https://pathway.com/success-stories/la-poste)
[Success Stories\
\
Formula 1 Team](https://pathway.com/success-stories/formula-1-team)
---
# Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™
Table of Contents
**Issy-les-Moulineaux (France), April 17, 2025** - [Pathway](https://pathway.com/)
, the data company that builds LiveAI™, and [Transdev](https://www.transdev.com/)
, a global daily mobility solutions provider, today announce a strategic partnership to transform public transport network operations by integrating innovative real-time AI frameworks at their heart.
With its operations and systems constantly generating more and more data, Transdev needed a solution capable of processing real-time information, combined with historical data, to address mobility challenges in various territories.
Pathway, which enables continuous learning via an efficient and scalable data engine to create LiveAI™ systems that think and learn in real time, allows Transdev to leverage AI systems powered by live data pipelines. This delivers insights and supports decision-making based on always up-to-date knowledge, which is crucial for the transportation sector. The Relevance of AI: Transforming Simple Geolocation Data into Reli
[The Relevance of AI: Transforming Simple Geolocation Data into Reliable Real-Time Passenger Information](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility#the-relevance-of-ai-transforming-simple-geolocation-data-into-reliable-real-time-passenger-information)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
For public transport applications, Pathway's LiveAI™ technology is specifically applied to geospatial and temporal data. For example, it enables live analytics of how vehicles are moving through a city in real time. Other data regarding the operation or functioning of vehicles can also be analyzed through AI.
The benefits of applying LiveAI™ to transport operations include:
* Increased operational efficiency: More accurate and reliable predictions of arrival times, enhanced dynamic management of planned and unplanned diversions and disruptions, and new high-performance tools for operators.
* Improved customer experience: Providing reliable, real-time passenger information, both in normal and disrupted situations to optimize user experience. The automated management of new arrival times when routes are diverted also reduces passenger waiting times and inconvenience.
> _Pathway shows that real-time data processing and AI integrate seamlessly into our chain of business tools. The solution complements our operating and passenger information systems, without adding complexity or implementation delays, while guaranteeing reliable results. Effectively ensuring daily mobility requires expert use of the real-time data we produce, transform, and deliver to both passengers and local authorities clients. Our partnership with Pathway strengthens our expertise in this area and enables significant gains for the benefit of service quality._
> _The experimentation on the DK’BUS network, which serves the Urban Community of Dunkirk, has shown significant gains in terms of information quality. The accuracy and reliability of the information delivered has improved, enabling the disappearance of theoretical arrival times, better prediction of waiting time estimations and efficient dynamic management of unscheduled deviations. We look forward to deploying and offering this quality of information to our passengers daily. The DK’Bus team, led by General Manager Nicolas Gaillard, already has great ideas to introduce it to our travelers! Pathway is undeniably the high-performance solution for monitoring and visualizing our activity to become even more reactive and continuously improve the data we produce._
> _Transportation is a dynamic industry, and an understanding of the real-time situation is critical for navigating mobility challenges. Applying AI and the most modern data processing to these challenges makes a very tangible difference to communities. We are proud to provide AI that reduces wait times and unpredictability, in turn attracting more people to public transport and boosting quality of life for residents of cities around the world._
Pathway's technology is proven with over 46,000 installations and users and is supported through the ZEBOX ecosystem that gathers companies like CMA CGM, Transdev or VINCI. Pathway now also delivers for major clients such as NATO and La Poste. The company recently raised $10 million in seed funding and has a growing community of developers based in over 100 countries.
[About Transdev](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility#about-transdev)
-------------------------------------------------------------------------------------------------------------
Operator and leading independent private mobility group, Transdev empowers freedom to move every day thanks to safe, reliable and innovative solutions that serve the common good. Present in 19 countries, Transdev transports an average of 12.8 million passengers daily, operating all transportation modes and resolutely committed to the ecological transition. The Group employs more than 105,000 women and men serving its passengers, consolidating its position as the world leader in public transportation. Transdev advises and supports local authorities and companies in a long-term partnership. Transdev is jointly owned by Caisse des Dépôts (66%) and the Rethmann Group (34%). In 2024, Transdev reported sales of €10.05 billion. For more information: [www.transdev.com](http://www.transdev.com/)
[About Pathway](https://pathway.com/news/transdev-pathway-live-ai-public-transport-mobility#about-pathway)
-----------------------------------------------------------------------------------------------------------
At Pathway, we believe that memory and the ability to learn on the fly is the single biggest limitation facing current transformer-based AI models. Pathway is a post-transformer neo-lab that has solved that problem. We are delivering a faster path to AGI through true continuous learning and long horizon reasoning. To learn more about BDH, visit [pathway.com](https://pathway.com/)
.
Pathway is led by co-founder & CEO Zuzanna Stamirowska, a complexity scientist who created a team consisting of AI pioneers, including CTO Jan Chorowski who was the first person to apply Attention to speech and worked with Nobel laureate Geoff Hinton at Google Brain, as well as CSO Adrian Kosowski, a leading computer scientist and quantum physicist who obtained his PhD at the age of 20.
* * *

Pathway Team
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
transdev\
\
news · case-studyApr 23, 2025\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-and-pathway-partner)
* [\
\
\
\
Maddyness\
\
newsDec 20, 2024\
\
Pathway featured in Maddyness 2025 Insights and Predictions](https://pathway.com/news/pathway-featured-maddyness-insights-and-predictions)
* [\
\
\
\
Pathway Team\
\
news · case-studyNov 13, 2024\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
[News\
\
Transdev and Pathway partner to improve mobility and public transport performance through LiveAI™](https://pathway.com/news/transdev-and-pathway-partner)
[News\
\
Victor Szczerba assumes CCO role at Pathway post funding](https://pathway.com/news/victor-szczerba-assumes-cco-role-at-pathway-post-funding)
---
# Run a template | Pathway
Run a a Pathway Live Data Framework Template
============================================
The Pathway Live Data Framework Templates provide ready-to-use setups for creating real-time, AI-driven applications built on the Pathway Live Data Framework. With YAML-configured templates, it's easy to customize or create your own processing pipelines for use cases like RAG and ETL.
This quick start guide will help you set up and run a Pathway Live Data Framework Template. Whether you're developing an ETL pipeline, a document indexing solution, a knowledge mining system, or a query-response interface, this guide will get you started quickly.
[Prerequisites](https://pathway.com/developers/templates/run-a-template#prerequisites)
---------------------------------------------------------------------------------------
To get started, you'll need:
* Git to clone the repository and manage updates.
* LLM API Key (e.g., OpenAI or Hugging Face) for embedding and querying models, if needed.
**Running Options**
1. Docker (recommended) will install all dependencies automatically.
2. Python 3.8+ with [the Pathway Live Data Framework](https://pathway.com/developers/user-guide/introduction/installation)
if you prefer a local setup.
**Note**: if you are using RAG pipelines locally, you will need to install Pathway Live Data Framework LLM xpack with:
`pip install pathway[all]`
**Optional**: Install Streamlit for UI and pip for dependency management (if not using Docker).
[Clone the Repository](https://pathway.com/developers/templates/run-a-template#clone-the-repository)
-----------------------------------------------------------------------------------------------------
First, you need to download the repository.
For ETL templates, clone Pathway repository:
`git clone https://github.com/pathwaycom/pathway.git`
For RAG templates, you need to clone the dedicated repository:
`git clone https://github.com/pathwaycom/llm-app.git`
[Selecting Your Template](https://pathway.com/developers/templates/run-a-template#selecting-your-template)
-----------------------------------------------------------------------------------------------------------
These templates provide several ready-to-go setups for common use cases. Whether you need a real-time ETL, document indexing, or context-based Q&A, you'll find templates for each.
[See the templates.](https://pathway.com/developers/templates#llm)
Then you need to go the repository of the chosen template, let's take the `question_answering_rag` as an example.
`cd llm-app/templates/question_answering_rag`
[Configuring Pathway Live Data Framework Templates](https://pathway.com/developers/templates/run-a-template#configuring-pathway-live-data-framework-templates)
---------------------------------------------------------------------------------------------------------------------------------------------------------------
Most of the templates can be configured using a YAML file. You can learn how to configure them by reading the [dedicated tutorial](https://pathway.com/developers/templates/configure-yaml)
.
For non-YAML templates, the detailed configuration and usage steps can be found in the the README and articles included with each template.
[Run a Template](https://pathway.com/developers/templates/run-a-template#run-a-template)
-----------------------------------------------------------------------------------------
You can run Pathway Live Data Framework Templates either locally or using Docker.
### [Self-hosting](https://pathway.com/developers/templates/run-a-template#self-hosting)
The exact information about how to run a given template is given in the dedicated article or GitHub repository. In general, the templates can be run in two different ways:
* Manually: by running the main Python file (usually called `main.py`). You'll need to install the dependencies manually.
* With Docker: by using `docker compose up` if a `docker-compose.yml` file is provided. The setup is automated, handling all required dependencies.
### [On the Cloud](https://pathway.com/developers/templates/run-a-template#on-the-cloud)
Local and Docker deployment may be not enough. Most cloud platforms offer robust support for Docker containers and/or Python deployment, allowing you to deploy your project on these cloud environments without encountering compatibility issues.
You can learn more about how to deploy a Pathway Template in the cloud [here](https://pathway.com/developers/templates/deploy/cloud-deployment)
.
### [Pathway Live Data Framework Enterprise](https://pathway.com/developers/templates/run-a-template#pathway-live-data-framework-enterprise)
If you want to scale your application, you may be interested in Pathway Live Data Framework Enterprise.
You can learn more about Pathway Live Data Framework Enterprise [here](https://pathway.com/pricing)
.
[Developers\
\
Pathway Live Data Framework Templates](https://pathway.com/developers/templates)
[Templates\
\
Customizing a RAG Template with YAML](https://pathway.com/developers/templates/configure-yaml)
---
# How to Use Your Own Components in YAML Configuration | Pathway
Customizing Pathway Live Data Framework Templates with Your Own Components
==========================================================================
When using YAML to configure the Pathway Live Data Framework Templates, you can use your own components with the [mapping tags](https://pathway.com/developers/templates/configure-yaml#mapping-tags)
- either to implement the components not available in the `pathway` library or to add additional processing steps. This article will go through details on importing custom components. This guide, however, does not cover basic syntax of the Pathway YAML configuration files - for that read the [YAML syntax guide](https://pathway.com/developers/templates/configure-yaml)
.
[How are components imported?](https://pathway.com/developers/templates/custom-components#how-are-components-imported)
-----------------------------------------------------------------------------------------------------------------------
To refer to any component after `!`, you need to provide the full module name, e.g. `pw.xpacks.llm.llms.OpenAIChat`. If no module is provided, only the name of the object, it is assumed to be from the builtins. For example you can use `!str` to convert some object to string.
`one_as_string: !str object: 1`
This means that any object you may want to use must be imported with the name of the module - this may be just the name of the Python file it is defined in. For example, if you want to use function `foo` that is in file `utils.py` in the same directory as `app.py` and `app.yaml` - the file tree looks as follows:
`. ├── app.py ├── app.yaml └── utils.py`
you would refer to it as `!utils.foo`.
Let's look at a couple of examples on how to utilize that in your pipelines.
[Altering metadata](https://pathway.com/developers/templates/custom-components#altering-metadata)
--------------------------------------------------------------------------------------------------
Say you want to add some metadata that are not created by the input connector. For example, your use case is about running RAG on data about funds, and each file in the dataset has name in the format `{ISIN number}_{Fund Name}_{Currency}.pdf`. While the filenames are part of the metadata, you may wish to take advantage of the specific format and include ISIN and Currency in the metadata to make the filtering easier - which cannot be done automatically by the connector.
First write a function that will add those fields to the metadata in `utils.py`.
utils.py
`import pathway as pw @pw.udf def add_isin_and_currency(metadata: pw.Json) -> dict: metadata_dict = metadata.as_dict() path = metadata_dict["path"] filename = path.split('/')[-1] isin = filename.split('_')[0] currency = filename.split('_')[-1][:-4] metadata_dict["isin"] = isin metadata_dict["currency"] = currency return metadata_dict def augment_metadata(sources: list[pw.Table]) -> list[pw.Table]: return [t.with_columns(_metadata=add_isin_and_currency(pw.this._metadata)) for t in sources]`
Then, in the `app.yaml` from [question\_answering\_rag](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
apply this function on `$sources` to obtain the changed tables, which are then given to the `$document_store`.
app.yaml
`$sources: # File System connector, reading data locally. - !pw.io.fs.read path: data format: binary with_metadata: true $sources_with_metadata: !utils.augment_metadata sources: $sources $document_store: !pw.xpacks.llm.document_store.DocumentStore docs: $sources_with_metadata parser: $parser splitter: $splitter retriever_factory: $retriever_factory`
[Parser for JSONs](https://pathway.com/developers/templates/custom-components#parser-for-jsons)
------------------------------------------------------------------------------------------------
For another example, consider needing a specific parser that is not a part of the LLM xpack. Consider streams coming from Kafka and each message is a dict with a key `"content"` having a text to be indexed. Then you can replace a parser in the `DocumentStore` with a version that extracts this string from each dict.
json\_parser.py
`import pathway as pw import json class JsonParser(pw.UDF): def __wrapped__(self, message: str) -> list[tuple[str, dict]]: message_dict = json.loads(message) return [(message_dict["content"], {})]`
app.yaml
`$sources: - !pw.io.kafka.read # Kafka configuration, check https://pathway.com/developers/api-docs/pathway-io/kafka for needed arguments format: plaintext $parser: !json_parser.JsonParser {} $document_store: !pw.xpacks.llm.document_store.DocumentStore docs: $sources parser: $parser splitter: $splitter retriever_factory: $retriever_factory`
[Importing objects from external libraries](https://pathway.com/developers/templates/custom-components#importing-objects-from-external-libraries)
--------------------------------------------------------------------------------------------------------------------------------------------------
You can of course use also objects from the external libraries. If you do so, remember to use full name of the library rather than commonly use abbreciation, e.g. use `pandas` module rather than `pd`\- the only abbreviation recognized by our YAML parser is that of `pathway` as `pw`. When you use components from the external libraries, you do not need to import them anywhere, `pw.load_yaml`, used to parse YAML configuration files, takes care of that.
app.yaml
`$dataframe: !pandas.DataFrame "data": ["foo", "bar", baz"] $sources: - !pw.debug.table_from_pandas df: $dataframe`
[Templates\
\
Customizing a RAG Template with YAML](https://pathway.com/developers/templates/configure-yaml)
[Templates\
\
Licensing Guide](https://pathway.com/developers/templates/licensing-guide)
---
# Licensing Guide | Pathway
Pathway Live Data Framework Licensing Guide
===========================================
The Pathway Live Data Framework offers a flexible licensing model designed to accommodate both community users and enterprise deployments. This guide explains the different licensing options, usage limitations, and key considerations for developers.
[Pathway Live Data Framework Community License (Free Version)](https://pathway.com/developers/templates/licensing-guide#pathway-live-data-framework-community-license-free-version)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework Community is distributed under the [**Pathway Live Data Framework Business Source License (BSL)**](https://pathway.com/license#pathway-business-source-license-bsl)
, which automatically converts to the open-source **Apache 2.0 license** after 4 years.
### [What's Included in Pathway Live Data Framework Community?](https://pathway.com/developers/templates/licensing-guide#whats-included-in-pathway-live-data-framework-community)
* **Most transformations and features** available in Pathway.
* **Most connectors** for integrating data.
* **Usage**: Permitted for most commercial applications.
* **Resource Limits:**
* **8 GB RAM** per node
* **4 CPU cores** per node
* **Deployment:** Self-hosted only (no managed cloud services provided by Pathway).
* **Exclusions:** Cannot be used by cloud providers reselling "Stream Data Processing Services," as detailed in the license terms.
The Pathway Live Data Framework Community is free to use in production environments, as long as it adheres to these constraints.
[Pathway Live Data Framework Scale License (Advanced Features & Higher Limits)](https://pathway.com/developers/templates/licensing-guide#pathway-live-data-framework-scale-license-advanced-features-higher-limits)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
The Pathway Live Data Framework Scale is intended for demanding users who need extra features and higher resource limits beyond what Pathway Live Data Framework Community offers.
You can get a Pathway Live Data Framework Scale license [here](https://pathway.com/framework/get-license)
.
### [What's Included in Pathway Live Data Framework Scale?](https://pathway.com/developers/templates/licensing-guide#whats-included-in-pathway-live-data-framework-scale)
* **Enterprise connectors**, including:
* [SharePoint](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read)
* [Delta Lake](https://pathway.com/developers/api-docs/pathway-io/deltalake)
* [Iceberg](https://pathway.com/developers/api-docs/pathway-io/iceberg)
* **Advanced features**, such as:
* [Full persistence](https://pathway.com/developers/user-guide/deployment/persistence)
* [Monitoring](https://pathway.com/developers/user-guide/deployment/live-data-framework-monitoring)
* [`SlideParser`](https://pathway.com/developers/api-docs/pathway-xpacks-llm/parsers#pathway.xpacks.llm.parsers.SlideParser)
.
* **Higher Resource Limits:**
* **16 GB RAM** per node
* **4 CPU cores** per node
* **License Activation:**
* Requires setting a license key using [`pathway.set_license_key()`](https://pathway.com/get-license#how-to-use-the-license-key)
.
* License keys are available in different tiers, which may be **free or paid**, depending on resource needs.
### [**Additional Terms for Pathway Live Data Framework Scale Users**](https://pathway.com/developers/templates/licensing-guide#additional-terms-for-pathway-live-data-framework-scale-users)
* By using a Pathway Live Data Framework Scale license key, you agree that **anonymized product usage data** is sent to Pathway via an OpenTelemetry collector.
* This data helps improve Pathway and enhance support services.
* All collected data is governed by [**Pathway's Privacy Policy**](https://pathway.com/privacy_gdpr_di)
, which users can review to understand data handling practices.
[Multi-Node Deployments & Licensing Considerations](https://pathway.com/developers/templates/licensing-guide#multi-node-deployments-licensing-considerations)
--------------------------------------------------------------------------------------------------------------------------------------------------------------
### [Are the Resource Limits Per Node?](https://pathway.com/developers/templates/licensing-guide#are-the-resource-limits-per-node)
Yes, all memory and CPU limitations apply **per node**.
### [Can I Buy Multiple Scale Licenses for Multiple Nodes?](https://pathway.com/developers/templates/licensing-guide#can-i-buy-multiple-scale-licenses-for-multiple-nodes)
Yes, you can:
* Mix & match **free (small) and paid (larger) Scale nodes** to fit your needs.
* Purchase multiple licenses for multiple nodes.
* **Enterprise Licenses** are available to cover all nodes and pipelines under one agreement.
* **Automation Restriction:**
* Non-enterprise users **cannot automate the launching of new instances**.
* Scaling up/down must require **manual intervention** by a team member.
[Looking for more?](https://pathway.com/developers/templates/licensing-guide#looking-for-more)
-----------------------------------------------------------------------------------------------
If you want more, don't hesitate to contact us for an Enterprise License.
[Templates\
\
How to Use Your Own Components in YAML Configuration](https://pathway.com/developers/templates/custom-components)
[Yaml Snippets\
\
Data Sources Examples](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples)
---
# Solutions | Pathway
Solutions
Empower your Business with Powerful AI Solutions for RAG, ETL and Real-Time Data processing
===========================================================================================
Discover how to quickly put in production AI applications which offer high accuracy and low latency at scale, using the most up-to-date knowledge available in your data sources.
[RAG and LLM Pipelines](https://pathway.com/framework/solutions#by-topic)
[\
\
Document Answering\
\
High-accuracy Document Answering](https://pathway.com/framework/solutions/document-answering)
[\
\
RAG Slides Search\
\
Accurate Slides Search - Boost productivity with accurate slide search on Sharepoint or Google Drive\
\
Accurate Slides Search - Boost productivity with accurate slide search on Sharepoint or Google Drive](https://pathway.com/framework/solutions/slides-ai-search)
[ETL Pipelines](https://pathway.com/framework/solutions#industries-and-use-cases)
[\
\
AI-enabled vehicles & eSports\
\
Implementation of a core real-time processing analytics engine to enable a platform approach\
\
Implementation of a core real-time processing analytics engine to enable a platform approach](https://pathway.com/framework/solutions/ai-enabled-vehicles-n-esports)
[\
\
Logistics\
\
Postal Services, 3PL, Container Shipping - Enabling real-time intelligence in Logistics\
\
Postal Services, 3PL, Container Shipping - Enabling real-time intelligence in Logistics](https://pathway.com/framework/solutions/logistics)
Trusted by
----------
[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


---
# pathway.persistence package
pathway.persistence package
===========================
[class **Backend**(engine\_data\_storage, fs\_path=None)](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend)
---------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L13-L112)
The settings of a backend, which is used to persist the computation state.
### [classmethod **azure**(root\_path, account, password, container)](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend.azure)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L70-L96)
Configure the Azure Blob Storage backend.
* **Parameters**
* **root\_path** (`str`) – path to the root in the Azure Blob Storage container, which will be used to store persisted data;
* **account** (`str`) – account name for Azure Blob Storage;
* **password** (`str`) – password for the specified account;
* **container** (`str`) – container name to store the data in.
* **Returns**
Class instance denoting the Azure Blob Storage backend with root directory as `root_path` and connection settings given by the extra parameters.
### [classmethod **filesystem**(path)](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend.filesystem)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L26-L45)
Configure the filesystem backend.
* **Parameters**
**path** (`str` | `PathLike`\[`str`\]) – the path to the root directory in the file system, which will be used to store the persisted data.
* **Returns**
Class instance denoting the filesystem storage backend with root directory at `path`.
### [classmethod **s3**(root\_path, bucket\_settings)](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend.s3)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L47-L68)
Configure the S3 backend.
* **Parameters**
* **root\_path** (`str`) – path to the root in the S3 storage, which will be used to store persisted data;
* **bucket\_settings** ([`AwsS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.AwsS3Settings)
) – the settings for S3 bucket connection in the same format as they are used by S3 connectors.
* **Returns**
Class instance denoting the S3 storage backend with root directory as `root_path` and connection settings given by `bucket_settings`.
[class **Config**(backend, \*, snapshot\_interval\_ms=0, snapshot\_access=, persistence\_mode=, continue\_after\_replay=True, worker\_scaling\_enabled=False, workload\_tracking\_window\_ms=120000)](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Config)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L115-L223)
Configure the data persistence. An instance of this class should be passed as a parameter to pw.run in case persistence is enabled.
* **Parameters**
* **backend** ([`Backend`](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend)
) – persistence backend configuration.
* **snapshot\_interval\_ms** (`int`) – the desired duration between snapshot updates in milliseconds.
* **persistence\_mode** ([`PersistenceMode`](https://pathway.com/developers/api-docs/pathway#pathway.PersistenceMode)
) – Can be set to one of the following values. `pw.PersistenceMode.PERSISTING`: the default value and means that all data will be persisted. When this parameter is specified, or when it is omitted, and the configuration is passed to `pw.run`, no additional actions are required to persist the state of your program. Alternatively, you can use `pw.PersistenceMode.UDF_CACHING` meaning that only user-defined function (UDF) calls will be cached. The cache stores the mapping from function input parameters to their results, so if a function is called again with the same inputs, the cached result is returned. `pw.PersistenceMode.OPERATOR_PERSISTING`: the most efficient persistence mechanism, performing persistence only over the state of internal operators, neither preserving the input nor performing any recomputation on it.
* **worker\_scaling\_enabled** (`bool`) – Enables dynamic scaling of worker processes. When enabled, the program may increase or decrease the number of workers and restart itself with the new configuration if the pipeline remains overloaded or underloaded for a sustained period of time. Note that dynamic scaling requires the program to be started using `pathway spawn`.
* **workload\_tracking\_window\_ms** (`int`) – Specifies the time window (in milliseconds) used to evaluate pipeline load when worker scaling is enabled. The load condition (overload or underload) must persist throughout this entire window before a scaling decision is made.
### [classmethod **simple\_config**(backend, snapshot\_interval\_ms=0, snapshot\_access=api.SnapshotAccess.FULL, persistence\_mode=api.PersistenceMode.PERSISTING, continue\_after\_replay=True)](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Config.simple_config)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L156-L205)
Construct config from a single instance of the `Backend` class, using this backend to persist metadata and snapshot.
Note that this method is deprecated and is left for the backward compatibility purposes only. Please use the pw.persistence.Config constructor instead.
* **Parameters**
* **backend** ([`Backend`](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend)
) – storage backend settings;
* **snapshot\_interval\_ms** (`int`) – the desired freshness of the persisted snapshot in milliseconds. The greater the value is, the more the amount of time that the snapshot may fall behind, and the less computational resources are required.
* **persistence\_mode** ([`PersistenceMode`](https://pathway.com/developers/api-docs/pathway#pathway.PersistenceMode)
) – Can be set to one of the following values. `pw.PersistenceMode.PERSISTING`: the default value and means that all data will be persisted. When this parameter is specified, or when it is omitted, and the configuration is passed to `pw.run`, no additional actions are required to persist the state of your program. Alternatively, you can use `pw.PersistenceMode.UDF_CACHING` meaning that only user-defined function (UDF) calls will be cached. The cache stores the mapping from function input parameters to their results, so if a function is called again with the same inputs, the cached result is returned.
* **Returns**
Persistence config.
---
# AI Paper Reviewer | LiveAI™ for Conference Classification | Pathway
Table of Contents
[1\. Why Another AI Paper Reviewer?](https://pathway.com/framework/blog/ai-paper-reviewer#_1-why-another-ai-paper-reviewer)
----------------------------------------------------------------------------------------------------------------------------
Because the stakes—and the gaps—are bigger than ever.
> “Scientists get naturally anxious when submitting a research paper. We know that peer review is coming.”
> — [PeerRecognized](https://peerrecognized.com/)
Most “AI helpers” still act like static proofreading bots.
* A GPT plug-in on [ResearchGate](https://www.researchgate.net/post/Review_My_Paper-An_AI_tool)
offers generic feedback across “various parameters.”
* Marketplaces such as [YesChat](https://www.yeschat.ai/gpts-ZxWzhxhY-Paper-Reviewer)
promise _“Expert AI-Powered Academic Paper Reviews.”_
* Even full-fledged platforms like [Paper Digest](https://www.paperdigest.org/)
warn that hallucinations remain a critical risk and stress the need for citation-grounded outputs—because “for research, every word counts.”
Yet none of these tools confront the two questions that _make or break_ a submission:
1. Is my work publishable right now?
2. Which conference will actually accept it?
* * *
### [Enter the **LiveAI™ Paper Reviewer**](https://pathway.com/framework/blog/ai-paper-reviewer#enter-the-liveai-paper-reviewer)
Built on a dual-LLM **Tree-of-Thought Actor–Contrastive-Critic (TACC)** engine and a hybrid Retrieval-Augmented Generation (RAG) layer, this system goes far beyond copy-editing:
* Binary publishability prediction with up to 92% real-world accuracy.
* Ensemble-reasoned conference classification (SCHOLAR → SCRIBE) that resolves overlap, class imbalance, and keyword bias across venues like **CVPR, EMNLP, KDD, NeurIPS, and TMLR**.
Because the entire pipeline runs in streaming mode, every new paragraph, revision, or freshly uploaded pre-print is re-indexed on the fly—turning conventional peer-review anxiety into **live, data-backed confidence**.
### [User Walkthrough: LiveAI™ for Conference Classification and Paper Publishability Prediction](https://pathway.com/framework/blog/ai-paper-reviewer#user-walkthrough-liveai-for-conference-classification-and-paper-publishability-prediction)
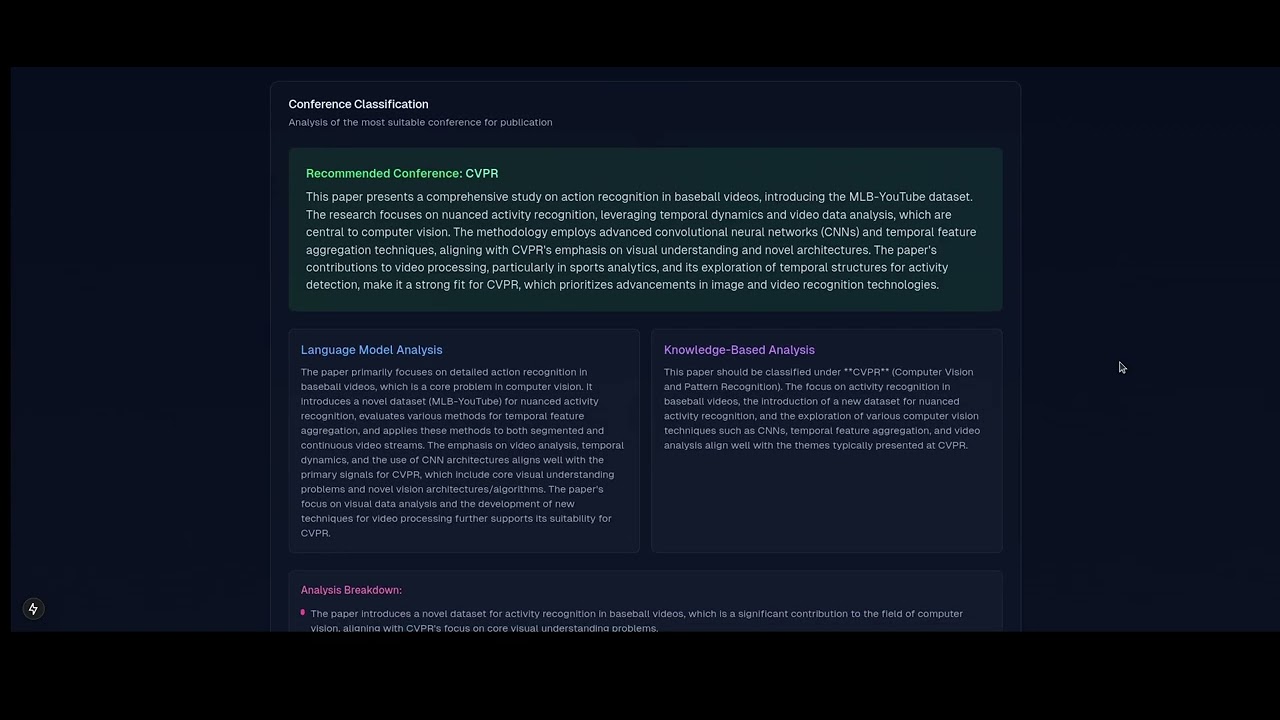
### [Code Repository - Complete Setup & Usage Guide](https://pathway.com/framework/blog/ai-paper-reviewer#code-repository-complete-setup-usage-guide)
[\
\
LiveAI™ for Conference ClassificationGitHub](https://github.com/Cath3dr4l/kdsh)
[2\. Building the AI Paper Reviewer: The Architecture of TACC](https://pathway.com/framework/blog/ai-paper-reviewer#_2-building-the-ai-paper-reviewer-the-architecture-of-tacc)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [2.1. Motivation: Moving Beyond the Black Box to a Transparent AI Reviewer](https://pathway.com/framework/blog/ai-paper-reviewer#_21-motivation-moving-beyond-the-black-box-to-a-transparent-ai-reviewer)
Our first objective was to determine a paper's publishability. While a basic LLM prompt can achieve reasonable accuracy, it functions as an opaque "black box," providing an answer without a verifiable line of reasoning. For a task that demands trust and justification, this is a non-starter. Our core motivation was to construct a "glass box" , a system whose decision-making process is transparent, auditable, and structurally sound.
### [2.2. Our Design Journey: From Simple Embeddings to Agentic Reasoning](https://pathway.com/framework/blog/ai-paper-reviewer#_22-our-design-journey-from-simple-embeddings-to-agentic-reasoning)
Our final architecture was the culmination of a deliberate, four-stage evolution:
* **Stage 1: BERT-Based Clustering (73.3% Accuracy)**: A foundational but naive start.
* **Stage 2: Basic LLM Classification (78% Accuracy)**: A leap in knowledge, but a step back in transparency.
* **Stage 3: Simple Actor-Critic (83% Accuracy)**: Our first foray into meta-cognition, proving that a system's ability to evaluate its own reasoning was the path forward.
* **Stage 4: The TACC Architecture**: The synthesis of our learnings into a sophisticated, transparent reasoning engine.
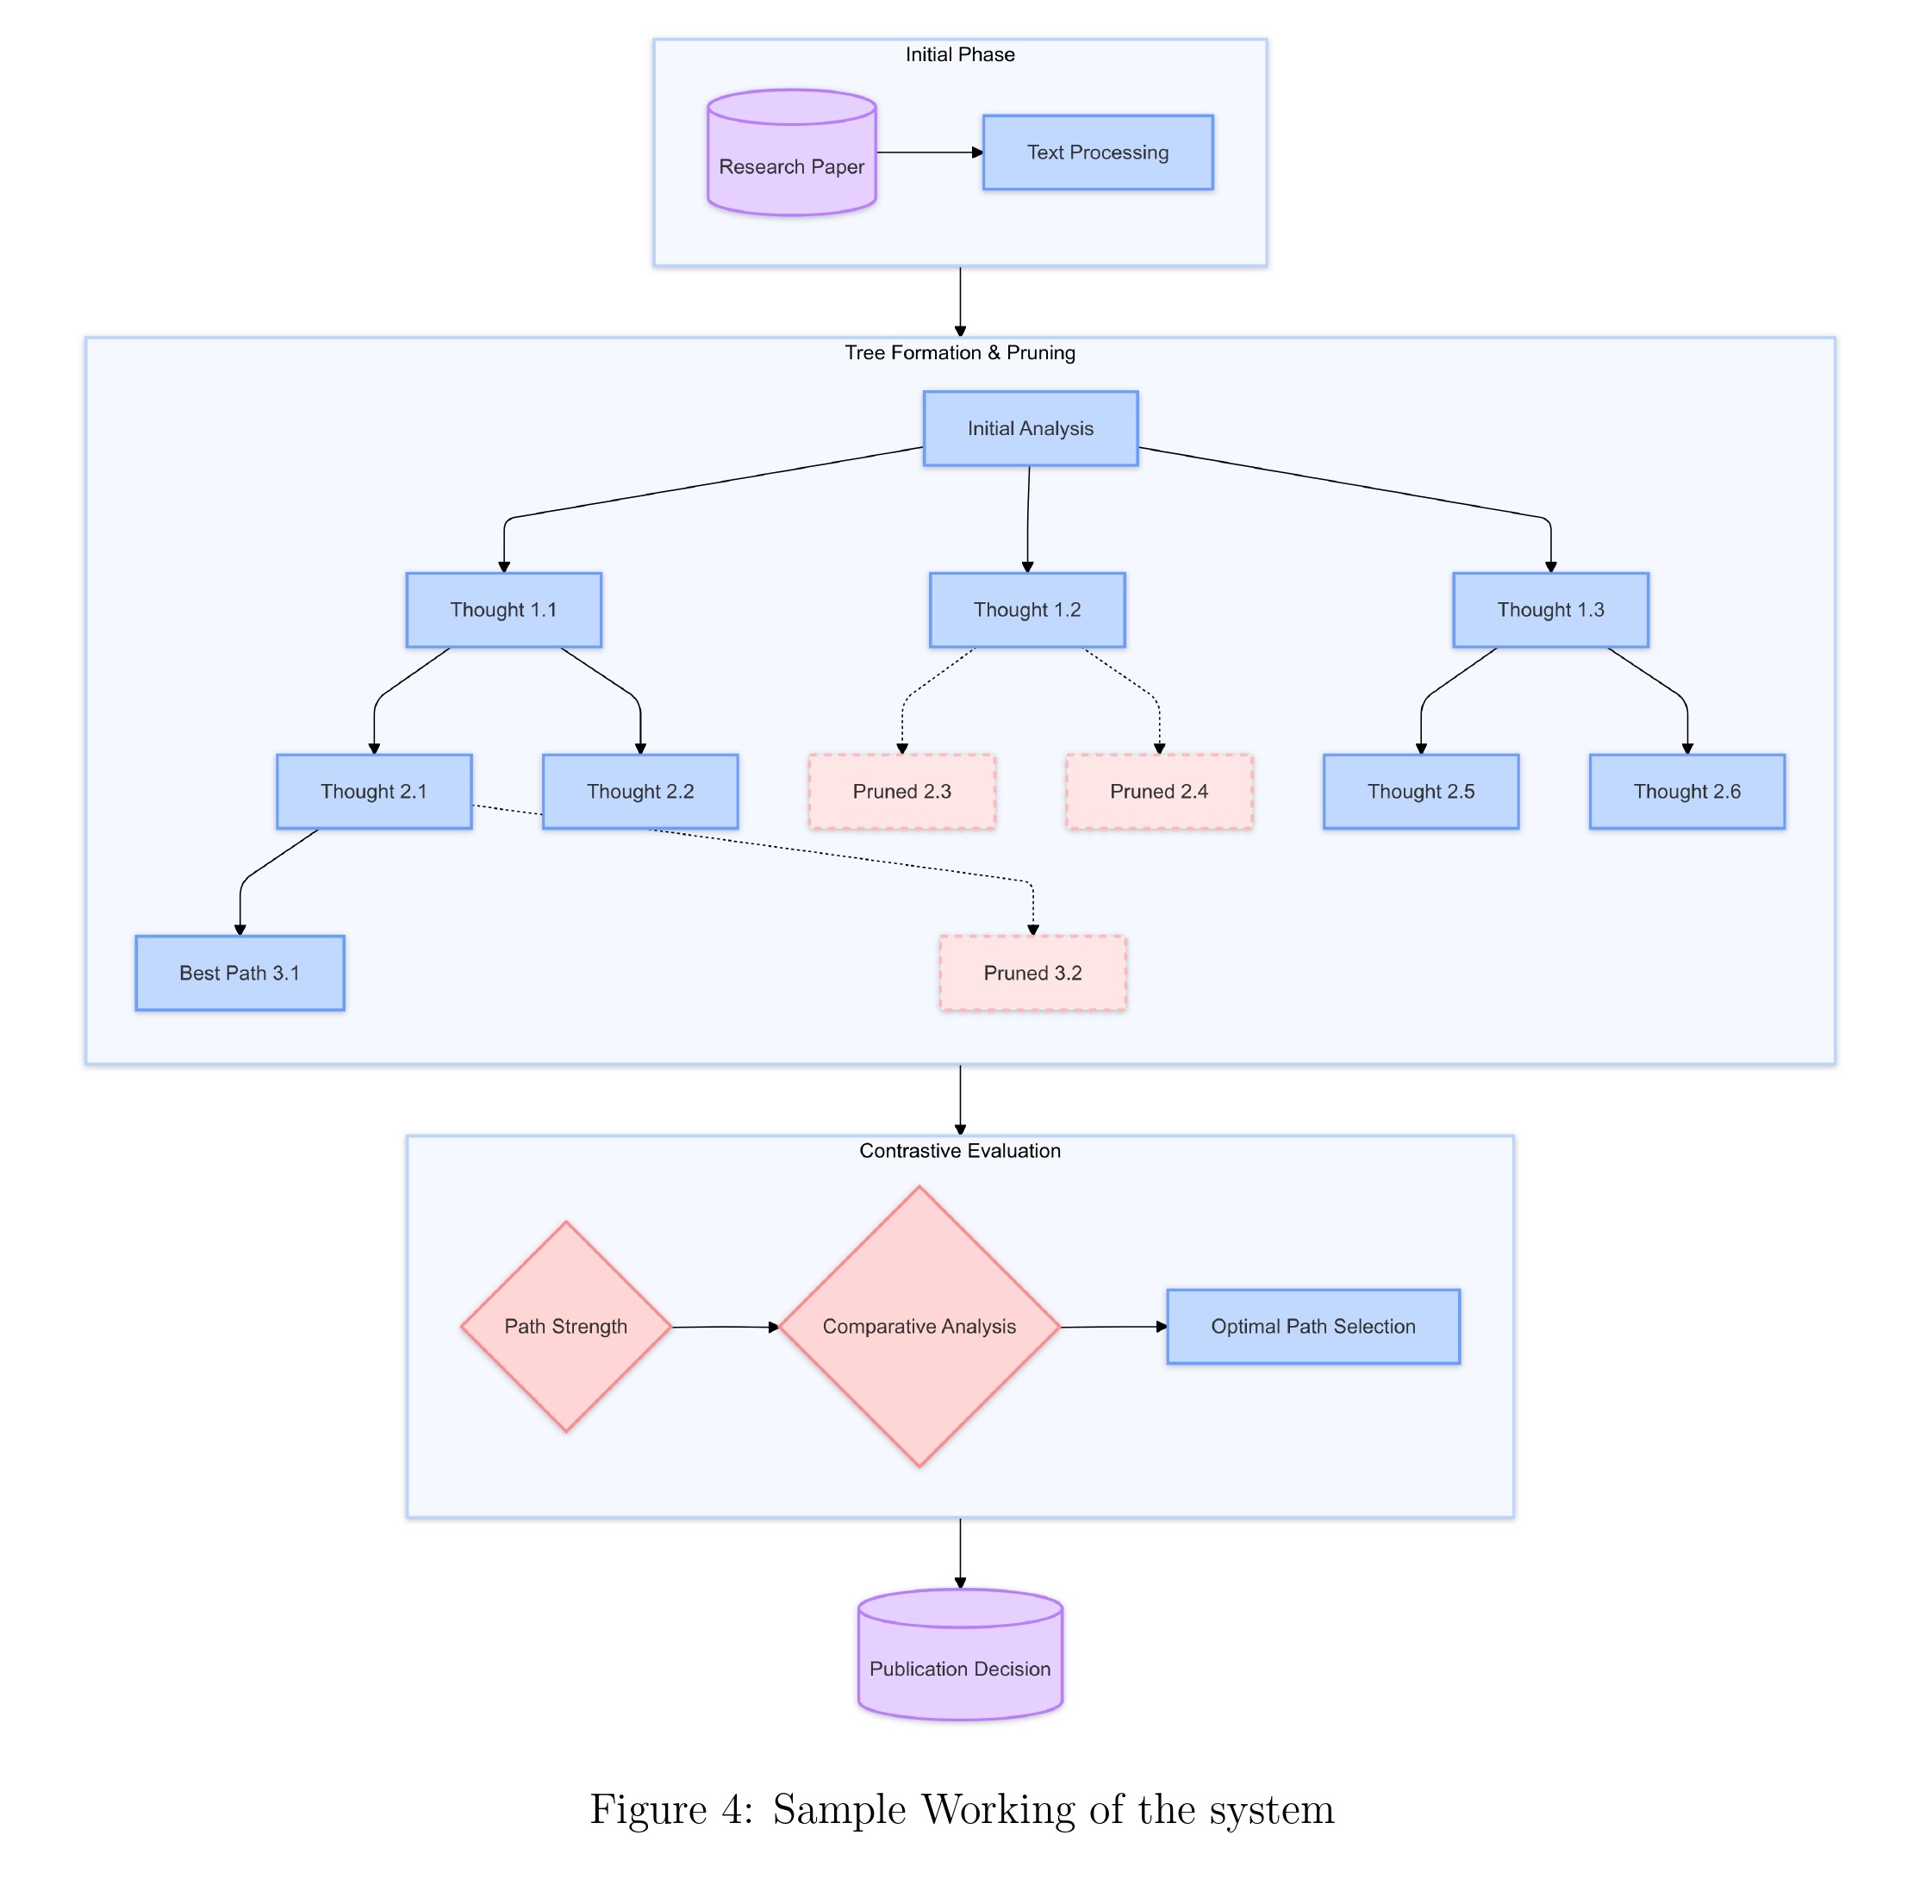
### [2.3. TACC: An Architectural Deep Dive into our AI Paper Reviewer](https://pathway.com/framework/blog/ai-paper-reviewer#_23-tacc-an-architectural-deep-dive-into-our-ai-paper-reviewer)
**TACC** (**T**oT **A**ctor–Contrastive-CoT **C**ritic) is a dual-LLM system engineered for hierarchical, multi-step reasoning. It integrates several advanced AI paradigms to create an evaluation engine that is both accurate and interpretable.
#### [2.3.1. Core Framework: Why Tree of Thoughts (ToT) for AI Review?](https://pathway.com/framework/blog/ai-paper-reviewer#_231-core-framework-why-tree-of-thoughts-tot-for-ai-review)
At the heart of TACC lies the **Tree of Thoughts** framework. Unlike a linear Chain of Thought (CoT), which pursues a single, sequential line of reasoning, ToT empowers the system to explore multiple analytical branches in parallel. This is a fundamental architectural choice. When a human expert reviews a paper, they don't just read it from start to finish; they concurrently evaluate its novelty, check its methodology for flaws, assess the clarity of its language, and question the validity of its conclusions. ToT mimics this divergent thinking process, allowing our AI to build a comprehensive and multi-faceted understanding of the paper's quality. This entire workflow is programmatically managed in agent/services/tree\_of\_thoughts.py.
#### [2.3.2. The Decisive Component: Intelligent Pruning with Contrastive CoT](https://pathway.com/framework/blog/ai-paper-reviewer#_232-the-decisive-component-intelligent-pruning-with-contrastive-cot)
This is TACC's most significant innovation. A standard evaluation loop would have the Critic assess each of the Actor's thoughts in isolation ("Is this thought valid?"). We implemented a more sophisticated **Contrastive Chain-of-Thought**. In this paradigm, the Critic is prompted to take a set of parallel thoughts and explicitly compare them against each other. It must generate a structured rationale answering questions like: "Which of these three analytical paths is most critical to the paper's publishability? Which argument is best supported by textual evidence? Which path is a red herring?" This comparative analysis allows the system to intelligently prune weaker or less relevant branches, ensuring that computational resources are focused on the most promising lines of inquiry.
#### [2.3.3. Engineering TACC, an Efficient AI Reviewer: Asynchronicity and Optimization](https://pathway.com/framework/blog/ai-paper-reviewer#_233-engineering-tacc-an-efficient-ai-reviewer-asynchronicity-and-optimization)
Building a ToT system that performs well requires careful engineering.
* **The Dual-LLM Dynamic**: We made a strategic decision to use two different models. The **Actor**, responsible for generating a wide "fan-out" of thoughts, was gpt-4o-mini. Its speed and cost-effectiveness were ideal for generating breadth. The **Critic**, which required nuanced understanding for its contrastive analysis, was the more powerful gpt-4o. This created a highly effective and economically viable division of labor.
* **Asynchronous Execution**: The entire system, implemented in agent/services/paper\_evaluator.py, is built on Python's asyncio. The Actor's thought generation and the Critic's evaluation are executed as parallel, asynchronous tasks. This means that while the Critic is evaluating the thoughts at Depth N, the Actor can already begin generating new branches for Depth N+1 from the previously validated nodes. This concurrent processing was crucial for achieving high performance.
* **Strategic Pruning**: Through empirical testing, we found our "sweet spot" for performance and cost. At each depth of the tree (up to a maximum of 3), the Critic was configured to prune the weakest one-third of the thought branches. The remaining validated nodes would then serve as the foundation for the next level of thought generation, each producing three new branches. This 3x3 expansion-pruning cycle kept the search space manageable while allowing for deep exploration.
This robust architecture resulted in **100% accuracy on the reference sample papers and an exceptional 92% overall accuracy** on the combined, human-labeled dataset.
[3\. Mastering Conference Classification: The SCRIBE Multi-Agent Ensemble](https://pathway.com/framework/blog/ai-paper-reviewer#_3-mastering-conference-classification-the-scribe-multi-agent-ensemble)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [3.1. How the Pathway Live Data Framework helped as a LiveAI™ layer:](https://pathway.com/framework/blog/ai-paper-reviewer#_31-how-the-pathway-live-data-framework-helped-as-a-liveai-layer)
* Our conference classification agent couldn’t rely on a static, pre-trained model. It needed to be grounded in a live, evolving dataset of academic papers. The Pathway Live Data Framework provided the critical infrastructure for this "LiveAI™ Layer."
* We chose the Pathway Live Data Framework for its performance and simplicity. Its core engine is written in Rust, ensuring the low-latency data processing required for a responsive RAG pipeline. This speed was essential for minimizing the time-to-first-token in our LLM agent.
* The framework’s unified architecture handles both batch and streaming data with the same code. This simplified our development, allowing us to use a single logic for both the initial bulk indexing and for processing new papers as they arrived.
* The framework’s Google Drive Connector gave us a seamless, real-time data pipeline. It automatically detected and streamed new reference papers from our source folder, keeping our knowledge base current without manual intervention.
* For retrieval, we used the framework’s DocumentStore configured for hybrid search. This combined fast keyword matching (BM25) with conceptual semantic search (USearchKNN), a crucial capability for navigating the precise and nuanced language of academic research.
In short, the Pathway Live Data Framework provided the high-performance data backbone, allowing us to focus our efforts on the agent’s reasoning logic rather than on complex data engineering.
### [3.2. The Challenge: Tackling Nuance and Data Imbalance in Conference Classification](https://pathway.com/framework/blog/ai-paper-reviewer#_32-the-challenge-tackling-nuance-and-data-imbalance-in-conference-classification)
Task 2 presented a more subtle challenge. Conferences have thematic overlaps (e.g., NLP papers in EMNLP and NeurIPS) and severe data imbalances (thousands of papers at NeurIPS vs. hundreds at TMLR). A simple classifier would be hopelessly biased. Our motivation was to design a system that could navigate this nuance through a multi-perspective, ensemble-based architecture.
### [3.3. SCRIBE (Semantic Conference Recommendation with Intelligent Balanced Evaluation)](https://pathway.com/framework/blog/ai-paper-reviewer#_33-scribe-semantic-conference-recommendation-with-intelligent-balanced-evaluation)
**SCRIBE** (**S**emantic **C**onference **R**ecommendation with **I**ntelligent **B**alanced **E**valuation) is our solution a multi-agent ensemble where three specialized AI agents independently analyze a paper and "vote" on the best conference. A final controller then weighs these recommendations to make an informed decision.

### [3.4. The SCRIBE Expert Committee: A Three-Pronged Approach to Classification](https://pathway.com/framework/blog/ai-paper-reviewer#_34-the-scribe-expert-committee-a-three-pronged-approach-to-classification)
#### [3.4.1. Agent 1: The 'Cookbook' LLM for Foundational Knowledge](https://pathway.com/framework/blog/ai-paper-reviewer#_341-agent-1-the-cookbook-llm-for-foundational-knowledge)
This agent's expertise comes from a meticulously curated knowledge base we called the "Cookbook." This was not a simple prompt; it was a comprehensive, structured document built through a semi-automated pipeline. We used advanced web-scraping agents and LLM-powered summarization (akin to Gemini's DeepResearch) to synthesize information from hundreds of sources, official conference websites, calls for papers, and topical analyses from academic blogs. The resulting "cookbook" provided the LLM agent (agent/services/llm\_based\_classifier.py) with a deep, nuanced understanding of each conference's unique academic identity, including its core topics, methodological preferences, and evolving trends.

#### [3.4.2. Agent 2: Real-Time Pathway Live Data Framework RAG Agent for Data-Grounded Conference Classification](https://pathway.com/framework/blog/ai-paper-reviewer#_342-agent-2-real-time-pathway-live-data-framework-rag-agent-for-data-grounded-conference-classification)
This agent provided a data-driven perspective grounded in historical precedent, and it was our direct implementation of the hackathon's core requirement.

* **Real-Time Data Ingestion**: Using the framework’s Google Drive Connector (indexer/services/drive\_connector.py), we created a live data pipeline that streamed reference papers directly from the source.
* **Advanced Hybrid Retrieval**: We indexed this content using **the framework’s DocumentStore**, which we configured in indexer/services/document\_store.py for hybrid retrieval. This is a crucial technical choice. It combines **BM25** for fast, keyword-based lexical search with **USearchKNN** for dense, semantic search. This dual-pronged approach, powered by Pathway's efficient indexing, allowed our RAG agent (agent/services/rag\_based\_classifier.py) to retrieve highly relevant examples from past conference papers, providing a robust foundation for its recommendations.
#### [3.4.3. Agent 3: The SCHOLAR Agent for Global-Scale Analysis](https://pathway.com/framework/blog/ai-paper-reviewer#_343-agent-3-the-scholar-agent-for-global-scale-analysis)
This agent(agent/services/similarity\_based\_classifier.py) was designed to overcome the limitations of our local dataset and tap into the vast corpus of global academic research.
* **Hierarchical Query Generation**: It begins with an LLM that generates 5-7 diverse search queries. This is run in parallel five times, and a "consolidator" agent synthesizes the ~30 initial queries into 10-20 unique, non-redundant queries, optimizing the search space.
* **Large-Scale Search & Re-ranking**: These queries are dispatched to the Semantic Scholar API, searching over 190 million papers. The top 1,000 results are then re-ranked using lightweight machine learning models (like learning-to-rank algorithms) that consider metadata features and fuzzy text matching to promote the most relevant results.
* **Final RAG Similarity**: The top 100 papers from this re-ranked list then undergo a final, precise similarity comparison between their abstracts and a summary of the input paper.
* **Logarithmic Scoring for Imbalance**: To solve the critical data imbalance problem, we devised a logarithmic scoring function: Final Score = Average Similarity \* log(Number of Papers). The logarithm dampens the effect of raw paper counts, preventing a conference like NeurIPS from winning simply because it has more papers. This focuses the decision on the quality of the match, not the size of the conference. We also explored a more advanced version where an LLM would perform a final qualitative re-ranking of the top-scoring papers, though for the hackathon, the direct metric was used for efficiency.
### [3.5. The Ensemble Controller: From Voting to Agentic Adjudication](https://pathway.com/framework/blog/ai-paper-reviewer#_35-the-ensemble-controller-from-voting-to-agentic-adjudication)
Currently, the FinalClassifier (agent/services/final\_classifier.py) analyzes the outputs and rationales from the three agents to make a reasoned final decision. A key future improvement would be to replace this with a dedicated "**Judge Agent**." This agent could use an Actor-Critic framework itself to moderate a simulated debate, forcing the three agents to justify their choices and leading to an even more robust and transparent final recommendation.

[4\. Engineering for Performance and the Future of AI Paper Review](https://pathway.com/framework/blog/ai-paper-reviewer#_4-engineering-for-performance-and-the-future-of-ai-paper-review)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [4.1. Optimizing for Speed: Inference Acceleration with LPUs and Speculative Decoding](https://pathway.com/framework/blog/ai-paper-reviewer#_41-optimizing-for-speed-inference-acceleration-with-lpus-and-speculative-decoding)
We leveraged [Groq's LPU™ Inference Engine](https://console.groq.com/home)
for its exceptional speed on sequential language tasks. We further amplified this with [speculative decoding](https://groq.com/groq-first-generation-14nm-chip-just-got-a-6x-speed-boost-introducing-llama-3-1-70b-speculative-decoding-on-groqcloud/)
, where a smaller "draft" model generates token sequences that are then validated in a single pass by the larger model, dramatically increasing throughput.
### [4.2. The Path Forward: Next-Generation Models and Automated System Tuning](https://pathway.com/framework/blog/ai-paper-reviewer#_42-the-path-forward-next-generation-models-and-automated-system-tuning)
The field is advancing rapidly.
* **Next-Generation Models**: Our architecture is model-agnostic. Integrating newer, more powerful reasoning models (like gemini-2.5-pro, o3, o4-mini-high, and claude 4 sonnet) is a direct path to higher performance.
* **Hyperscale Inference**: Emerging hardware like [Cerebras's Wafer-Scale Engines](https://cloud.cerebras.ai/platform/)
, which can hold entire LLMs on a single chip, could enable near-instantaneous analysis of entire research libraries.
* **Automated System Tuning**: A truly advanced implementation would involve a meta-learning layer. A reinforcement learning agent could learn to dynamically tune the system's parameters like the pruning threshold in TACC or the voting weights in SCRIBE based on feedback, creating a self-improving system that gets more accurate over time.
[5\. Conclusion](https://pathway.com/framework/blog/ai-paper-reviewer#_5-conclusion)
-------------------------------------------------------------------------------------
Our journey was a deep dive into the practical engineering of complex AI systems. We demonstrated that the true power of modern LLMs is unlocked when they are augmented with structured reasoning frameworks like Tree of Thoughts and grounded in real-world data via technologies like the real-time RAG using the Pathway Live Data Framework pipeline. TACC and SCRIBE represent a philosophical shift from AI as a passive tool to AI as an active analytical partner.
Take a look at the original report
[\
\
ARC2.pdfGoogle Drive](https://drive.google.com/file/d/1RgvO5TzbvvSahGFKQPu8nVA5Mr__oLeQ/view?usp=sharing)
If you are interested in diving deeper into the topic, here are some good references to get started with Pathway:
* [Pathway Live Data Framework Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
* [Pathway Live Data Framework's Ready-to-run App Templates](https://pathway.com/developers/templates)
* [End-to-end Real-time RAG app with Pathway Live Data Framework Live Data Framework](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
* [Discord Community](https://discord.gg/pathway)
[Authors](https://pathway.com/framework/blog/ai-paper-reviewer#authors)
------------------------------------------------------------------------
* [Divyansh Sharma](https://www.linkedin.com/in/divyanshsharma-/)
* [Tasmay Pankaj Tibrewal](https://www.linkedin.com/in/tasmay-tibrewal/)
* [Tanush Agarwal](https://www.linkedin.com/in/shashwat-singh-ranka-7a168a259/)
* [Shashwat Singh Ranka](https://www.linkedin.com/in/shashwat-singh-ranka-7a168a259/)
* * *
Pathway Live Data Framework Community
Multiple authors
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Sajjad Nakhwa\
\
communityFeb 11, 2025\
\
How Text Embeddings help suggest similar words](https://pathway.com/framework/blog/how-text-embeddings-help-suggest-similar-words)
* [\
\
\
\
Pathway Team\
\
researchNov 30, 2025\
\
Benchmarks: Fundamental Unlocks for AI](https://pathway.com/#benchmarks)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsSep 24, 2023\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
[Blog\
\
LiveAI™ for SEC Filings Analysis](https://pathway.com/framework/blog/ai-for-sec-filings)
[Blog\
\
LiveAI™ Tools for Equity Research & Compliance Management](https://pathway.com/framework/blog/ai-tools-for-equity-analysis)
---
# Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason
Building LiveAI™ systems
========================
Underpinned by the fastest data processing engine on the market, Pathway Live Data Framework offering includes infrastructure components that fuel LiveAI™ systems from dynamic sources of structured and unstructured data, enabling decision-making based on always up-to-date knowledge
Pathway Live Data Framework
[Pathway Live Data Framework](https://pathway.com/)
is a Python ETL framework for stream processing, real-time analytics, LLM pipelines, and RAG.
Key Benefits:
-------------
* Easy Integration: Easy-to-use Python API, allowing you to seamlessly integrate your favorite Python ML libraries
* Flexible Deployment: Use it in both development and production environments
* Real-time Processing: Handle both batch and streaming data efficiently. The same code can be used for local development, CI/CD tests, running batch jobs, handling stream replays, and processing data streams
* High Performance: Powered by a scalable Rust engine for optimized performance, enabling multithreading, multiprocessing, and distributed computations
* Simplified Deployment: Deploy easily with Docker and Kubernetes
How it works
------------
Streamlined Cloud-Native Development Built in Rust with ❤ for Python developers, The Pathway Live Data Framework streamlines the entire ML/AI project lifecycle from prototype to production. It supports local, notebook, and scaled container deployments.
Fast, and Always In-Sync. [Connect](https://pathway.com/developers/user-guide/connect/live-data-framework-connectors)
live data sources like SharePoint, Google Drive, S3 and Delta Tables, cloud folders, Kafka, databases, and 300+ APIs such as Salesforce and Hubspot. The Pathway Live Data Framework's high-speed Rust engine delivers real-time updates, and is scalable to hundreds of CPU cores, with cost-efficient incremental computing, persistence, and caching.
A single robust container. You own it. Deploy each of your Pathway Live Data Framework applications from a git folder using Docker or Kubernetes, on-premises or in any cloud. Simplify your setup by avoiding multiple databases and compute engines linked by clunky APIs. Gain full control of the pathway that your data follows. It is made available for download as a Python-native package from [GitHub](https://github.com/pathwaycom)
Chef's Choice, or à la carte? Have it your own way. Choose from ready-to-use [app templates](https://pathway.com/developers/templates)
suitable for various industries and data types. Customize them using functions from the Pathway Live Data Framework, connectors, and integrations. Safely interact with LLMs and external asynchronous APIs.
They Trust us
-------------
[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


Use cases
---------
Pathway Live Data Framework offers flexible plans to suit collections of any size. [Learn more](https://pathway.com/pricing?tab=live-data-framework)
.
Backed by Enterprise Security & Authentication
*  Host on your cloud or on-premise
*  Secure by Design
*  Granular Access Management
* Compliance-Ready
Spin up your live pipelines in minutes. [Try it out](https://pathway.com/developers/user-guide/introduction/welcome)
Pathway Live Data Framework's Application templates allow you to quickly put in production [AI applications](https://pathway.com/developers/templates)
which offer high-accuracy RAG at scale using the most up-to-date knowledge available in your data sources.
Pathway Live Data Framework [connects](https://pathway.com/developers/user-guide/connect/live-data-framework-connectors)
to your data sources (file systems, databases, APIs) in real-time, ensuring your AI pipelines always work with the latest information.
Key Benefits:
-------------
* Seamless Data Integration: Connect to a variety of data sources from Enterprise file systems, Kafka, real-time data APIs, to Sharepoint, S3, PostgreSQL, Google Drive, etc.
* Real-Time Indexing: Keep your data up-to-date for accurate and relevant results. All new data additions, deletions, updates are automatically taken into account.
* Advanced Search Capabilities: Built-in data indexing enabling vector search, hybrid search, and full-text search - all done in-memory, with cache.
* No Infrastructure Hassle: Deploy easily with no additional infrastructure setup.
How it works
------------

They Trust us
-------------
[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


[](https://pathway.com/success-stories/db-schenker "Read about db-schenker")
[](https://pathway.com/framework/blog/intel-summit "Read about intel")
[](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024 "Read about nato")
[](https://pathway.com/success-stories/formula-1-team "Read about F1")
[](https://pathway.com/success-stories/la-poste "Read about la-poste")
[](https://pathway.com/success-stories/transdev "Read about transdev")
[](https://pathway.com/success-stories/cma-cgm "Read about cma-cgm")


Use cases
---------
Pricing
-------
Pathway Live Data Framework AI pipelines offer flexible plans to suit collections of any size. [Learn more](https://pathway.com/pricing)
.
Fully customizable in Python
Deploys with Kubernetes
Runs on cloud, runs in a data center, runs in a Faraday cage
Backed by Enterprise Security & Authentication
*  Host on your cloud or on-premise
*  Secure by Design
*  Granular Access Management
* Compliance-Ready
Spin up your all-inclusive RAG pipelines in minutes.One containerized service, no infrastructure dependencies. [Try it out](https://pathway.com/developers/templates/run-a-template)
* High accuracy knowledge retrieval
* Live synchronization with data sources
* Unstructured document support (PDF, DOC,...)
* Fast built-in vector indexing up to millions of documents\*
---
# pw.debug | Pathway
pw.debug
========
Methods and classes for debugging Pathway Live Data Framework computation.
Typical use:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' pet Dog Cat ''') t2 = t1.select(animal=t1.pet, desc="fluffy") pw.debug.compute_and_print(t2, include_id=False)`
Code Results
[**compute\_and\_print**(\*tables, include\_id=True, short\_pointers=True, n\_rows=None, \*\*kwargs)](https://pathway.com/developers/api-docs/debug#pathway.debug.compute_and_print)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L220-L245)
A function running the computations and printing the table.
* **Parameters**
* **tables** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – tables to be computed and printed
* **include\_id** – whether to show ids of rows
* **short\_pointers** – whether to shorten printed ids
* **n\_rows** (`int` | `None`) – number of rows to print, if None whole table will be printed
[**compute\_and\_print\_update\_stream**(\*tables, include\_id=True, short\_pointers=True, n\_rows=None, \*\*kwargs)](https://pathway.com/developers/api-docs/debug#pathway.debug.compute_and_print_update_stream)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L248-L273)
A function running the computations and printing the update stream of the table.
* **Parameters**
* **tables** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – tables for which the update stream is to be computed and printed
* **include\_id** – whether to show ids of rows
* **short\_pointers** – whether to shorten printed ids
* **n\_rows** (`int` | `None`) – number of rows to print, if None whole update stream will be printed
[**table\_from\_markdown**(table\_def, id\_from=None, unsafe\_trusted\_ids=False, schema=None, \*, split\_on\_whitespace=True, )](https://pathway.com/developers/api-docs/debug#pathway.debug.table_from_markdown)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L446-L472)
A function for creating a table from its definition in markdown. If it contains a special column `__time__`, rows will be split into batches with timestamps from the column. A special column `__diff__` can be used to set an event type - with `1` treated as inserting the row and `-1` as removing it.
By default, it splits on whitespaces. To get a table containing strings with whitespaces, use with `split_on_whitespace = False`.
[**table\_from\_pandas**(df, id\_from=None, unsafe\_trusted\_ids=False, schema=None, )](https://pathway.com/developers/api-docs/debug#pathway.debug.table_from_pandas)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L356-L419)
A function for creating a table from a pandas DataFrame. If it contains a special column `__time__`, rows will be split into batches with timestamps from the column. A special column `__diff__` can be used to set an event type - with `1` treated as inserting the row and `-1` as removing it.
[**table\_from\_parquet**(path, id\_from=None, unsafe\_trusted\_ids=False, )](https://pathway.com/developers/api-docs/debug#pathway.debug.table_from_parquet)
--------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L475-L489)
Reads a Parquet file into a pandas DataFrame and then converts that into a Pathway Live Data Framework table.
[**table\_from\_rows**(schema, rows, unsafe\_trusted\_ids=False, is\_stream=False)](https://pathway.com/developers/api-docs/debug#pathway.debug.table_from_rows)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L325-L353)
A function for creating a table from a list of tuples. Each tuple should describe one row of the input data (or stream), matching provided schema.
If `is_stream` is set to `True`, each tuple representing a row should contain two additional columns, the first indicating the time of arrival of particular row and the second indicating whether the row should be inserted (1) or deleted (-1).
[**table\_to\_dicts**(table, \*\*kwargs)](https://pathway.com/developers/api-docs/debug#pathway.debug.table_to_dicts)
----------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L60-L89)
Runs the computations needed to get the contents of the Pathway Live Data Framework Table and converts it to a dictionary representation, where each column is mapped to its respective values.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The Pathway Live Data Framework Table to be converted.
* **\*\*kwargs** – Additional keyword arguments to customize the behavior of the function.
* terminate\_on\_error (bool): If True, the function will terminate execution upon encountering an error during the squashing of updates. Defaults to True.
* **Returns**
_tuple_ – A tuple containing two elements: 1) list of keys (pointers) that represent the rows in the table, and 2) a dictionary where each key is a column name, and the value is another dictionary mapping row keys (pointers) to their respective values in that column.
[**table\_to\_parquet**(table, filename)](https://pathway.com/developers/api-docs/debug#pathway.debug.table_to_parquet)
------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/debug/__init__.py#L492-L500)
Converts a Pathway Live Data Framework Table into a pandas DataFrame and then writes it to Parquet
[API Docs\
\
pw.Table](https://pathway.com/developers/api-docs/pathway-table)
[API Docs\
\
pw.demo](https://pathway.com/developers/api-docs/pathway-demo)
---
# Adaptive Agents for Real-Time RAG: Domain-Specific AI for Legal, Finance & Healthcare | Pathway
Table of Contents
[Unleashing Intelligent RAG: How Adaptive Agents and Reflection Elevate Information Retrieval](https://pathway.com/framework/blog/adaptive-agents-rag#unleashing-intelligent-rag-how-adaptive-agents-and-reflection-elevate-information-retrieval)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Retrieval-Augmented Generation (RAG) has revolutionized how Large Language Models (LLMs) access and utilize external knowledge. By fetching relevant information before generating a response, RAG makes LLMs more factual and up-to-date. But what happens when the information sources are constantly changing, or the queries become complex, requiring nuanced understanding and reasoning? Standard RAG systems often hit a wall, struggling with adaptability and static workflows.
Enter **Real-time Agentic RAG**, a sophisticated evolution of the RAG concept. Utilizing the **Pathway Live Data Framework**, we've developed a system that doesn't just retrieve information – it dynamically deploys specialized AI "agents" to tackle queries with unprecedented adaptability and accuracy. This isn't just RAG; it's RAG with a thinking, collaborating team behind it.
Let's dive into how this innovative approach works, the unique challenges it addresses, and why it represents a significant step forward for intelligent information systems.
### [A Quick 3-Minute Summary– Adaptive Agents for Real-Time RAG System:](https://pathway.com/framework/blog/adaptive-agents-rag#a-quick-3-minute-summary-adaptive-agents-for-real-time-rag-system)
### [Code Repository – Complete Setup & Usage Guide](https://pathway.com/framework/blog/adaptive-agents-rag#code-repository-complete-setup-usage-guide)
[\
\
pack0shades/DynamicAgenticRAGGitHub](https://github.com/pack0shades/DynamicAgenticRAG/tree/stagging)
[The Limits of Traditional RAG](https://pathway.com/framework/blog/adaptive-agents-rag#the-limits-of-traditional-rag)
----------------------------------------------------------------------------------------------------------------------
Traditional RAG pipelines, while powerful, often operate with a fixed structure: retrieve -> augment -> generate. This works well for static datasets but faces hurdles when dealing with:
1. **Real-time Data**: Real-world knowledge isn't static. Financial markets shift, legal precedents evolve, medical records update. Static RAG struggles to keep pace.
2. **Complex Queries**: Questions requiring information synthesis from multiple document sections or specific, nuanced analysis can overwhelm simple retrieval mechanisms.
3. **Contextual Nuance**: Understanding how a piece of information fits within the larger document context is crucial for relevance, something basic chunking can miss.
4. **Efficiency and Accuracy**: Retrieving too much irrelevant information increases processing load (token usage) and the risk of the LLM generating inaccurate or "hallucinated" responses based on noisy context.
These limitations highlight the need for a more flexible, intelligent, and context-aware RAG system.
[Real-time Adaptive Agentic RAG: A Smarter Approach](https://pathway.com/framework/blog/adaptive-agents-rag#real-time-adaptive-agentic-rag-a-smarter-approach)
---------------------------------------------------------------------------------------------------------------------------------------------------------------
Our solution reimagines the RAG process by introducing AI agents – specialized entities designed to perform specific tasks within the pipeline. Think of it like assembling a bespoke team of experts for every query. The core innovation lies in its _adaptive_ nature.
### [Adaptive Agent Formation: Tailored Expertise on Demand](https://pathway.com/framework/blog/adaptive-agents-rag#adaptive-agent-formation-tailored-expertise-on-demand)
Instead of relying on a fixed set of tools, this system uses the CrewAI framework to _generate agents at runtime_, specifically tailored to the content of the document being queried.
* **How it works**: When a document (e.g., a complex contract, a patient's medical history, a financial report) is processed, the system analyzes its structure and content to create agents specializing in different sections or aspects (e.g., a 'Liability Clause Agent' for a contract, a 'Diagnosis History Agent' for medical records).
* **Why it matters**: This ensures that the agents handling a query possess the most relevant "expertise" for that specific document and potential questions related to it. This dramatically improves adaptability across diverse domains like **Healthcare**, **Legal**, and **Finance**, where document structures and information types vary significantly. It ensures the system is always aligned with the latest data sources

[Key Innovations Driving Performance](https://pathway.com/framework/blog/adaptive-agents-rag#key-innovations-driving-performance)
----------------------------------------------------------------------------------------------------------------------------------
Beyond dynamic agents, we integrated several cutting-edge techniques, many extending the capabilities of the **Pathway Live Data Framework**:
### [Advanced Contextual Retrieval and Re-ranking](https://pathway.com/framework/blog/adaptive-agents-rag#advanced-contextual-retrieval-and-re-ranking)
Getting the _right_ information to the agents is paramount. The system employs a sophisticated multi-stage retrieval process:
1. **Contextual Chunking**: Documents are split into chunks, but crucially, each chunk is stored alongside its surrounding context (using a custom Pathway splitter). This helps the system understand the relevance of information more deeply.
2. **Hybrid Search**: It combines **dense embeddings** (capturing semantic meaning, via the Pathway Live Data Framework) with **sparse embeddings** (capturing keyword relevance, using a custom Splade encoder integrated into the framework). This hybrid approach provides a more nuanced understanding of relevance than either method alone.
3. **Rank Fusion**: Results from dense and sparse searches are combined using a rank fusion formula to produce an initial ranked list of chunks.
4. **Re-ranking**: A transformer-based model then re-evaluates and re-ranks these initial chunks, pushing the most contextually relevant ones to the top and penalizing noise. This ensures high-quality information feeds the generation process.

### [The Reflection Loop: AI Critiquing AI](https://pathway.com/framework/blog/adaptive-agents-rag#the-reflection-loop-ai-critiquing-ai)
Inspired by the concept of Self-RAG, this system incorporates a **Critique Agent**.
* **The Process**: After the selected agents generate their initial responses based on the retrieved context and the query, the Critique Agent evaluates these responses. It checks for accuracy, relevance, consistency with the source material, and overall coherence.
* **Iterative Refinement**: The critique agent provides constructive feedback to the other agents. This process repeats for a set number (N) of iterations (defaulting to 2 in our tests). Each loop allows the agents to refine their outputs, leading to progressively better, more accurate, and contextually grounded final answers. This is a powerful mechanism for reducing hallucinations and improving quality.

### [Intelligent Routing](https://pathway.com/framework/blog/adaptive-agents-rag#intelligent-routing)
With potentially many adaptive agents created, how does the system know which ones to engage for a specific query? A dedicated **Router Agent** steps in. It analyzes the user's query and selects the subset of dynamically generated agents most relevant to answering it. This optimizes resource usage (fewer agents activated) and ensures the response generation process is focused and efficient.
### [Enhancing the Pathway Live Data Framework](https://pathway.com/framework/blog/adaptive-agents-rag#enhancing-the-pathway-live-data-framework)
**We** didn't just use the Pathway Live Data Framework; we extended it. **We** integrated a **Sparse Embedder** (Splade), developed a **Contextual Retrieval Splitter**, and added functionality to store **Document Summaries** within the framework's vector store, potentially aiding in agent creation or providing high-level context.
### [Collaborative Agents with CrewAI](https://pathway.com/framework/blog/adaptive-agents-rag#collaborative-agents-with-crewai)
The selected agents, along with a **Meta Agent** (responsible for synthesizing the final answer) and the **Critique Agent**, form a "Crew" using the **CrewAI** framework. This framework facilitates communication and task delegation between agents. They share a common knowledge base (refined query + retrieved context) and can leverage each other's outputs, enabling collaborative problem-solving for complex queries.
[Putting It All Together: System Architecture](https://pathway.com/framework/blog/adaptive-agents-rag#putting-it-all-together-system-architecture)
---------------------------------------------------------------------------------------------------------------------------------------------------
Visualizing the flow helps understand how these components interact (referencing Figure 4):
1. **Ingestion**: A document (e.g., from Google Drive via the UI) is parsed and processed.
2. **Embedding & Agent Creation**: Contextual chunks are created and embedded (dense & sparse) using the enhanced Pathway pipeline. Simultaneously, adaptive agents tailored to the document are generated via CrewAI.
3. **Query Processing**: A user query arrives, undergoes guardrail checks and refinement.
4. **Retrieval & Routing**: The refined query retrieves the most relevant contextual chunks (using hybrid search, rank fusion, re-ranking). The Router Agent selects the most relevant adaptive agents.
5. **Agent Crew Execution**: The selected agents, Meta Agent, and Critique Agent form a Crew. They access the knowledge base (query + context) and begin processing.
6. **Reflection**: The Critique Agent reviews agent outputs, providing feedback for N iterative refinement cycles.
7. **Synthesis**: The Meta Agent synthesizes the refined responses into a final answer.
8. **Validation** & Delivery: The final response passes through output guardrails before being delivered to the user.

[Does It Work? Evaluation Insights](https://pathway.com/framework/blog/adaptive-agents-rag#does-it-work-evaluation-insights)
-----------------------------------------------------------------------------------------------------------------------------
**We** tested this system, primarily using the CUAD dataset (legal/financial contracts), evaluating different configurations. We measured:
* **Semantic Similarity**: How closely the generated answer matches the ground truth (using RAGAS).
* **Answer Relevancy**: How well the answer addresses the prompt, avoiding redundancy (using RAGAS).
* **Time of Inference**: How long it takes to get an answer.
* **Judge LLM**: Using another LLM to provide an independent quality score.
**Key Findings**:
* **Reflection Works**: Increasing reflection iterations (from n=0 to n=2) consistently improved both Semantic Similarity and Answer Relevancy, demonstrating the effectiveness of the critique loop.
* **Contextual Retrieval & Re-ranking Boost Quality**: Pipelines using these techniques generally outperformed those without, showing their value in providing better context.
* **Trade-offs**: There's a clear trade-off between performance and speed. More reflection iterations significantly increase inference time. The best configuration achieved ~90% Semantic Similarity and ~95% Answer Relevancy but took around 45 seconds.
These results validate the core concepts, showing measurable improvements in response quality at the cost of increased computation.
[Tackling the Hurdles: Challenges and Solutions](https://pathway.com/framework/blog/adaptive-agents-rag#tackling-the-hurdles-challenges-and-solutions)
-------------------------------------------------------------------------------------------------------------------------------------------------------
Developing such a sophisticated system isn't without challenges:
* **Reliability & Safety**: Ensuring accurate, non-toxic outputs. Addressed by input/output **Guardrails** and the **Critique Agent's** refinement.
* **Hallucinations (Multi-Agent Cascading)**: One agent's error could mislead others. The **Reflection Loop** is key to catching and correcting these before they propagate.
* **Complexity & Efficiency**: Managing multiple agents and complex retrieval adds overhead. **Adaptive Agent Formation** and **Routing** help by activating only necessary agents. **Contextual Retrieval** optimizes the information quality/quantity trade-off.
* **Evaluation**: Lack of standard metrics for agentic RAG. Addressed by using a combination of metrics like **Semantic Similarity**, **Answer Relevancy**, and a **Judge LLM**.
### [When Things Go Wrong: Robust Error Handling](https://pathway.com/framework/blog/adaptive-agents-rag#when-things-go-wrong-robust-error-handling)
What if the system can't find a good answer, or the user isn't satisfied? **We** implemented a fallback mechanism. If the pipeline encounters an error or the user flags the response, it can trigger a **web search** using APIs like **JinaAI** (with Exa AI as a backup), providing an alternative route to information.

[Interacting with the System: The User Interface](https://pathway.com/framework/blog/adaptive-agents-rag#interacting-with-the-system-the-user-interface)
---------------------------------------------------------------------------------------------------------------------------------------------------------
Accessibility is key. **We** built a **Gradio-based** UI allowing users to:
* Input a Google Drive folder URL and credentials.
* Submit queries.
* See the "thinking process" of the agents streamed in real-time.
* Access the web search fallback.
This interface, styled with a nod to the Pathway Live Data Framework, makes the complex backend processes accessible and transparent.

[Building Trust: Responsible AI Practices](https://pathway.com/framework/blog/adaptive-agents-rag#building-trust-responsible-ai-practices)
-------------------------------------------------------------------------------------------------------------------------------------------
**We** emphasize responsible AI throughout the pipeline:
* **Query Intake Validation**: Guardrails check incoming queries for safety and appropriateness.
* **Response Safeguarding**: Guardrails validate the final output for contextual accuracy, ethical alignment, and relevance, filtering out toxic or misleading content.
* **Agent Oversight**: The Meta-Agent synthesizes information, and the Critique Agent acts as a guardrail through iterative review, enhancing reliability.
[Lessons Learned and the Road Ahead](https://pathway.com/framework/blog/adaptive-agents-rag#lessons-learned-and-the-road-ahead)
--------------------------------------------------------------------------------------------------------------------------------
Building this system offered valuable insights:
* **Iterative Refinement is Powerful**: Loops within agent interactions (like the reflection cycle) significantly improve outcome quality by allowing for debate, correction, and deeper task exploration.
* **Adaptability is Key**: Adaptive agent formation proved crucial for handling diverse data and use cases effectively.
The future could involve further optimizing agent communication, exploring more sophisticated memory mechanisms for agents, reducing latency, and expanding the range of supported data sources and use cases.
[Conclusion: The Dawn of Smarter RAG](https://pathway.com/framework/blog/adaptive-agents-rag#conclusion-the-dawn-of-smarter-rag)
---------------------------------------------------------------------------------------------------------------------------------
Our **Real-time Agentic RAG** approach with the Pathway Live Data Framework marks a significant advancement beyond traditional RAG. By incorporating **adaptive agent formation**, **advanced contextual retrieval**, and a **powerful reflection mechanism**, we've created a system that is more adaptable, accurate, and robust, particularly when dealing with complex queries and evolving information landscapes.
While challenges like computational cost remain, this approach demonstrates the immense potential of agentic AI to create truly intelligent information retrieval systems. It paves the way for applications that can understand context, reason dynamically, and deliver trustworthy insights from complex data – moving us closer to AI that doesn't just retrieve, but truly understands.
* * *
[Frequently Asked Questions (FAQ)](https://pathway.com/framework/blog/adaptive-agents-rag#frequently-asked-questions-faq)
--------------------------------------------------------------------------------------------------------------------------
Q1: What is the main difference between this and standard RAG?
A1: The key differences are adaptive agent generation (agents tailored to the document at runtime), the use of a critique agent for iterative reflection/improvement, and advanced contextual retrieval with hybrid search and re-ranking. Standard RAG is typically more static.
Q2: What is Pathway and CrewAI's role?
A2: The Pathway Live Data Framework is used as the underlying data processing framework, handling tasks like chunking, embedding (both dense and custom sparse), and vector storage. CrewAI is used to orchestrate the AI agents, enabling their creation, task assignment, and communication within the "crew."
Q3: How does the "Reflection" part work?
A3: A dedicated "Critique Agent" examines the responses generated by other agents based on the query and retrieved context. It provides feedback, and the agents revise their responses. This loop repeats a few times to improve accuracy and relevance.
Q4: Is this system much slower than normal RAG?
A4: Yes, the added complexity, especially the reflection loops, increases the time it takes to get an answer (inference time), as shown in the evaluations. There's a trade-off between response quality and speed.
Q5: Can this handle any type of document?
A5: The adaptive agent formation makes it highly adaptable to any domain. The paper mentions successful application to legal and financial documents (CUAD dataset) and potential for healthcare records. Its suitability would depend on the ability to parse the document and generate meaningful specialized agents.
* * *
If you are interested in diving deeper into the topic, here are some good references to get started with Pathway:
* [Pathway Live Data Framework Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
* [Pathway Live Data Framework App Templates](https://pathway.com/developers/templates)
* [Discord Community of Pathway](https://discord.gg/pathway)
* [Power and Deploy RAG Agent Tools with Pathway](https://pathway.com/blog/deploy-rag-agent-tools-with-pathway)
* [End-to-end Real-time RAG app with Pathway Live Data Framework Live Data Framework](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
For more information for our concepts and frameworks which we have used, these are a good place to start with:
* [CrewAI Quickstart](https://docs.crewai.com/introduction)
* [RAGAS Evaluation Metrics](https://docs.ragas.io/en/latest/concepts/metrics/)
* [Jina AI Reader API](https://jina.ai/reader/)
* [Exa AI Web Search API](https://exa.ai/)
* [Self-RAG concept (arXiv Paper)](https://arxiv.org/abs/2310.11511)
[Authors](https://pathway.com/framework/blog/adaptive-agents-rag#authors)
--------------------------------------------------------------------------
* [Sukriti Goyal](https://www.linkedin.com/in/sukriti-goyal-1697a71a5/)
* [Shikar Dave](https://www.linkedin.com/in/shikhar-dave-400810258/)
* [Jyotin Goel](https://www.linkedin.com/in/jyotin-goel-16924b263/)
* [Akshat Jain](https://www.linkedin.com/in/akshat-jain-2bba94280/)
* [Pragay Kumar](https://www.linkedin.com/in/pragay-kumar-56b97116b/)
* [Laksh Mendpara](https://www.linkedin.com/in/laksh-mendpara/)
* [Nisarg Upadhyay](https://www.linkedin.com/in/nisarg-upadhyay-156643287/)
* [Sirin Changulani](https://www.linkedin.com/in/sirin-changulani-7b69a927b/)
* * *

Pathway Live Data Framework Community
Multiple authors
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Sajjad Nakhwa\
\
communityFeb 11, 2025\
\
How Text Embeddings help suggest similar words](https://pathway.com/framework/blog/how-text-embeddings-help-suggest-similar-words)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsSep 24, 2023\
\
Building Data Frameworks for Real-time AI Applications](https://pathway.com/news/european-financial-review)
* [\
\
\
\
Pathway Team\
\
researchNov 30, 2025\
\
Benchmarks: Fundamental Unlocks for AI](https://pathway.com/#benchmarks)
[Blog\
\
Gartner® recognizes Pathway as an Emerging Visionary in GenAI Engineering](https://pathway.com/framework/blog/gartner-gen-ai-engineering)
[Blog\
\
How AI Agents in Finance Are Transforming Financial Due Diligence: FA3STER](https://pathway.com/framework/blog/ai-agents-finance-due-diligence)
---
# pw.demo | Pathway
pw.demo
=======
Pathway Live Data Framework demo module
This module allows you to create custom data streams from scratch or by utilizing a CSV file. This feature empowers you to effectively test and debug your Pathway Live Data Framework implementation using realtime data.
Typical use:
`class InputSchema(pw.Schema): name: str age: int pw.demo.replay_csv("./input_stream.csv", schema=InputSchema)`
Code Results
[**generate\_custom\_stream**(value\_generators, \*, schema, nb\_rows=None, autocommit\_duration\_ms=1000, input\_rate=1.0, name=None)](https://pathway.com/developers/api-docs/pathway-demo#pathway.demo.generate_custom_stream)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/demo/__init__.py#L29-L115)
Generates a data stream.
The generator creates a table and periodically streams rows. If a `nb_rows` value is provided, there are `nb_rows` row generated in total, else the generator streams indefinitely. The rows are generated iteratively and have an associated index x, starting from 0. The values of each column are generated by their associated function in `value_generators`.
* **Parameters**
* **value\_generators** (`dict`\[`str`, `Any`\]) – Dictionary mapping column names to functions that generate values for each column.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **nb\_rows** (`int` | `None`) – The number of rows to generate. Defaults to None. If set to None, the generator generates streams indefinitely.
* **types** – Dictionary containing the mapping between the columns and the data types (`pw.Type`) of the values of those columns. This parameter is optional, and if not provided the default type is `pw.Type.ANY`.
* **autocommit\_duration\_ms** (`int`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **input\_rate** (`float`) – The rate at which rows are generated per second. Defaults to 1.0.
* **Returns**
_Table_ – The generated table.
Example:
`value_functions = { 'number': lambda x: x + 1, 'name': lambda x: f'Person {x}', 'age': lambda x: 20 + x, } class InputSchema(pw.Schema): number: int name: str age: int pw.demo.generate_custom_stream(value_functions, schema=InputSchema, nb_rows=10)`
Code Results
In the above example, a data stream is generated with 10 rows, where each row has columns ‘number’, ‘name’, and ‘age’. The ‘number’ column contains values incremented by 1 from 1 to 10, the ‘name’ column contains ‘Person’ followed by the respective row index, and the ‘age’ column contains values starting from 20 incremented by the row index.
[**noisy\_linear\_stream**(nb\_rows=10, input\_rate=1.0)](https://pathway.com/developers/api-docs/pathway-demo#pathway.demo.noisy_linear_stream)
-------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/demo/__init__.py#L118-L162)
Generates an artificial data stream for the linear regression tutorial.
* **Parameters**
* **nb\_rows** (`int, optional`) – The number of rows to generate in the data stream. Defaults to 10.
* **input\_rate** (`float, optional`) – The rate at which rows are generated per second. Defaults to 1.0.
* **Returns**
_pw.Table_ – A table containing the generated data stream.
Example:
`table = pw.demo.noisy_linear_stream(nb_rows=100, input_rate=2.0)`
In the above example, an artificial data stream is generated with 100 rows. Each row has two columns, ‘x’ and ‘y’. The ‘x’ values range from 0 to 99, and the ‘y’ values are equal to ‘x’ plus some random noise.
[**range\_stream**(nb\_rows=30, offset=0, input\_rate=1.0, autocommit\_duration\_ms=1000)](https://pathway.com/developers/api-docs/pathway-demo#pathway.demo.range_stream)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/demo/__init__.py#L165-L209)
Generates a simple artificial data stream, used to compute the sum in our examples.
* **Parameters**
* **nb\_rows** (`int, optional`) – The number of rows to generate in the data stream. Defaults to 30.
* **offset** (`int, optional`) – The offset value added to the generated ‘value’ column. Defaults to 0.
* **input\_rate** (`float, optional`) – The rate at which rows are generated per second. Defaults to 1.0.
* **autocommit\_duration\_ms** (`int`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **Returns**
_pw.Table_ – a table containing the generated data stream.
Example:
`table = pw.demo.range_stream(nb_rows=50, offset=10, input_rate=2.5)`
In the above example, an artificial data stream is generated with a single column ‘value’ and 50 rows. The ‘value’ column contains values ranging from ‘offset’ (10 in this case) to ‘nb\_rows’ + ‘offset’ (60).
[**replay\_csv**(path, \*, schema, input\_rate=1.0)](https://pathway.com/developers/api-docs/pathway-demo#pathway.demo.replay_csv)
-----------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/demo/__init__.py#L212-L254)
Replay a static CSV files as a data stream.
* **Parameters**
* **path** (`str` | `PathLike`) – Path to the file to stream.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **autocommit\_duration\_ms** – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **input\_rate** (`float, optional`) – The rate at which rows are read per second. Defaults to 1.0.
* **Returns**
_Table_ – The table read.
Note: the CSV files should follow a standard CSV settings. The separator is ‘,’, the quotechar is ‘”’, and there is no escape.
[**replay\_csv\_with\_time**(path, \*, schema, time\_column, unit='s', autocommit\_ms=100, speedup=1)](https://pathway.com/developers/api-docs/pathway-demo#pathway.demo.replay_csv_with_time)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/demo/__init__.py#L257-L337)
Replay a static CSV files as a data stream while respecting the time between updated based on a timestamp columns. The timestamps in the file should be ordered positive integers.
* **Parameters**
* **path** (`str`) – Path to the file to stream.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **time\_column** (`str`) – Column containing the timestamps.
* **unit** (`str`) – Unit of the timestamps. Only ‘s’, ‘ms’, ‘us’, and ‘ns’ are supported. Defaults to ‘s’.
* **autocommit\_duration\_ms** – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **speedup** (`float`) – Produce stream speedup times faster than it would result from the time column.
* **Returns**
_Table_ – The table read.
Note: the CSV files should follow a standard CSV settings. The separator is ‘,’, the quotechar is ‘”’, and there is no escape.
[API Docs\
\
pw.debug](https://pathway.com/developers/api-docs/debug)
[API Docs\
\
pw.indexing](https://pathway.com/developers/api-docs/indexing)
---
# Pathway joins Agoranov, French Science and Tech incubator - in Paris, France
Table of Contents
Pathway joins Agoranov
======================
We are extremely happy to join [Agoranov](https://www.agoranov.com/)
- the French Science and Tech incubator.
We are looking forward to start working alongside talented entrepreneurs in science and technology.
Successful startups that went through Agoranov include the 5 French unicorns [Alan](https://alan.com/)
, [Dataiku](https://www.dataiku.com/)
, [Criteo](https://www.criteo.com/)
, [Doctolib](https://www.doctolib.fr/)
, or [Shift Technology](https://www.shift-technology.com/)
.
Feel free to stop by our Parisian [office](https://www.google.com/maps/place/Pathway+(pathway.com)/@48.8461594,2.3258312,17z/data=!3m1!4b1!4m5!3m4!1s0x47e671a847e17629:0xba3fda61ef6a248a!8m2!3d48.8461559!4d2.3280252)
(96bis Boulevard Raspail, 75006 Paris) to chat about developer tools, AI, Machine Learning, Real Time analytics, entrepreneurship, and beyond!
* * *
* * *

Zuzanna Stamirowska
CEO
[](https://www.linkedin.com/in/stamirowska/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Saksham Goel\
\
blog · tutorial · engineeringFeb 5, 2025\
\
Real-Time AI Pipeline with DeepSeek, Ollama and Pathway](https://pathway.com/framework/blog/deepseek-ollama)
* [\
\
\
\
Saksham Goel\
\
blog · engineeringJan 16, 2025\
\
Power and Deploy RAG Agent Tools with Pathway](https://pathway.com/framework/blog/deploy-rag-agent-tools-with-pathway)
* [\
\
\
\
Zuzanna Stamirowska\
\
blog · open betaDec 5, 2022\
\
Pathway Live Data Framework is now in Open Beta](https://pathway.com/framework/blog/pathway-open-beta-announced)
[Blog\
\
Pathway is a Gartner Representative Vendor](https://pathway.com/framework/blog/gartner)
[Blog\
\
Pathway has been selected by Hello Tomorrow as a Deep Tech Pioneer](https://pathway.com/framework/blog/hellotomorrow)
---
# Customizing a RAG Template with YAML | Pathway
Customizing Pathway Live Data Framework RAG Templates with YAML configuration files
===================================================================================
Pathway offers a number of ready-to-use and easy to deploy [RAG Templates](https://pathway.com/developers/templates#llm)
built on the Pathway Live Data Framework. To fit them to your needs without the need to alter Python code, you can configure them with YAML configuration files. Pathway uses a custom YAML parser to make configuring templates easier, and this guide explores capabilities of the YAML parser.
This article focus on the syntax of the YAML configuration files. You can find examples on configuration YAML files in the dedicated articles:
* [Data Sources](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples)
* [RAG Configuration](https://pathway.com/developers/templates/yaml-snippets/rag-configuration-examples)
[Mapping tags](https://pathway.com/developers/templates/configure-yaml#mapping-tags)
-------------------------------------------------------------------------------------
YAML format allows for assigning tags to key-value mappings, by prepending a chosen string with `!`. In Pathway configuration files, these tags are used to reference Python objects. If you provide a mapping, these objects will be called with arguments taken from the mapping. For example, this can be used to define a source Table using an input connector:
`source: !pw.io.fs.read path: data format: binary with_metadata: true`
Since classes are also callables, this syntax can also be used to initialize objects.
`llm: !pw.xpacks.llm.llms.OpenAIChat model: "gpt-3.5-turbo" retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy max_retries: 6 cache_strategy: !pw.udfs.DefaultCache {} temperature: 0.05 capacity: 8`
If a callable doesn't take any arguments, but you want it to be called when the YAML is read, you need to pass an empty mapping. In the example below an instance of `pw.udfs.DefaultCache` is assigned to `cache_strategy`, obtained by calling `pw.udfs.DefaultCache` without any arguments.
`cache_strategy: !pw.udfs.DefaultCache {}`
On the other hand, if no mapping is provided, the object is used as is. In LLM templates, this is used to set value of an argument that is an enum, e.g. `BruteForceKnnFactory` requires `metric` argument to be given a value from `pw.indexing.BruteForceKnnMetricKind` enum:
`retriever_factory: !pw.indexing.BruteForceKnnFactory reserved_space: 1000 embedder: $embedder metric: !pw.indexing.BruteForceKnnMetricKind.COS dimensions: 1536`
While these examples refer to components from the `pathway` package, you can use it for importing any object - in particular you can use your own functions and classes.
### [Defining the Data Sources and Schemas](https://pathway.com/developers/templates/configure-yaml#defining-the-data-sources-and-schemas)
Tags are used to define the data sources and the schema. You can learn more on how to do it in the YAML file in the [dedicated article](https://pathway.com/developers/templates/yaml-snippets/data-sources-examples)
.
[Variables](https://pathway.com/developers/templates/configure-yaml#variables)
-------------------------------------------------------------------------------
Identifiers starting with `$` are given a new meaning - these denote variables to be used later in the configuration file.
`$retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy max_retries: 6 llm: !pw.xpacks.llm.llms.OpenAIChat model: "gpt-3.5-turbo" retry_strategy: $retry_strategy cache_strategy: !pw.udfs.DefaultCache {} temperature: 0.05 capacity: 8 embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder model: "text-embedding-ada-002" retry_strategy: $retry_strategy cache_strategy: !pw.udfs.DefaultCache {}`
### [Environment Variables](https://pathway.com/developers/templates/configure-yaml#environment-variables)
You can also use `$` to refer to environment variables. For that purpose, you need to use identifiers that consist only of upper case letters and `_`. Also, if a variable is defined in the YAML file and present in the environment variables, the definition from the YAML file takes precedence. As an example, you can set the `port` in the [question\_answering\_rag pipeline](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
to be taken from the `$PATHWAY_PORT` environment variable.
`port: $PATHWAY_PORT`
Then, before running the pipeline set the `$PATHWAY_PORT` environment variable and it will be used by the app.
If the values of the environment variables are a valid integer, float or boolean (according to the YAML syntax), they will be parsed. Otherwise the value of the environment value is returned as a string.
[Example: Question-Answering RAG](https://pathway.com/developers/templates/configure-yaml#example-question-answering-rag)
--------------------------------------------------------------------------------------------------------------------------
To see YAMLs in practice let's look at the [Question-Answering RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
. Note, that it differs from [adaptive RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/adaptive_rag)
, [multimodal RAG](https://github.com/pathwaycom/llm-app/tree/main/multimodal_rag)
and [private RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/private_rag)
by the YAML configuration file - their Python code is the same.
Here is the content of `app.yaml` from question\_answering\_rag:
``$sources: - !pw.io.fs.read path: data format: binary with_metadata: true # - !pw.xpacks.connectors.sharepoint.read # url: $SHAREPOINT_URL # tenant: $SHAREPOINT_TENANT # client_id: $SHAREPOINT_CLIENT_ID # cert_path: sharepointcert.pem # thumbprint: $SHAREPOINT_THUMBPRINT # root_path: $SHAREPOINT_ROOT # with_metadata: true # refresh_interval: 30 # - !pw.io.gdrive.read # object_id: $DRIVE_ID # service_user_credentials_file: gdrive_indexer.json # name_pattern: # - "*.pdf" # - "*.pptx" # object_size_limit: null # with_metadata: true # refresh_interval: 30 $llm: !pw.xpacks.llm.llms.OpenAIChat model: "gpt-3.5-turbo" retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy max_retries: 6 cache_strategy: !pw.udfs.DiskCache temperature: 0.05 capacity: 8 $embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder model: "text-embedding-ada-002" cache_strategy: !pw.udfs.DiskCache $splitter: !pw.xpacks.llm.splitters.TokenCountSplitter max_tokens: 400 $parser: !pw.xpacks.llm.parsers.UnstructuredParser $retriever_factory: !pw.stdlib.indexing.BruteForceKnnFactory reserved_space: 1000 embedder: $embedder metric: !pw.stdlib.indexing.BruteForceKnnMetricKind.COS dimensions: 1536 $document_store: !pw.xpacks.llm.document_store.DocumentStore docs: $sources parser: $parser splitter: $splitter retriever_factory: $retriever_factory question_answerer: !pw.xpacks.llm.question_answering.BaseRAGQuestionAnswerer llm: $llm indexer: $document_store # Change host and port by uncommenting these lines # host: "0.0.0.0" # port: 8000 # Cache configuration # with_cache: true # If `terminate_on_error` is true then the program will terminate whenever any error is encountered. # Defaults to false, uncomment the following line if you want to set it to true # terminate_on_error: true``
This demo needs the `question_answerer` to be defined in the configuration file, and allows to override values of `host`, `port`, `with_cache` and `terminate_on_error`. The first thing you can try to do, is to add another input connector, e.g. that connects to files from Google Drive. The stub is already present in the file, so just uncomment it and fill `object_id` and `service_user_credentials_file`.
`$sources: - !pw.io.fs.read path: data format: binary with_metadata: true - !pw.io.gdrive.read object_id: FILL_YOUR_DRIVE_ID service_user_credentials_file: FILL_PATH_TO_CREDENTIALS_FILE name_pattern: - "*.pdf" - "*.pptx" object_size_limit: null with_metadata: true refresh_interval: 30 $llm: !pw.xpacks.llm.llms.OpenAIChat model: "gpt-3.5-turbo" retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy max_retries: 6 cache_strategy: !pw.udfs.DiskCache temperature: 0.05 capacity: 8 $embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder model: "text-embedding-ada-002" cache_strategy: !pw.udfs.DiskCache $splitter: !pw.xpacks.llm.splitters.TokenCountSplitter max_tokens: 400 $parser: !pw.xpacks.llm.parsers.UnstructuredParser $retriever_factory: !pw.stdlib.indexing.BruteForceKnnFactory reserved_space: 1000 embedder: $embedder metric: !pw.stdlib.indexing.BruteForceKnnMetricKind.COS dimensions: 1536 $document_store: !pw.xpacks.llm.document_store.DocumentStore docs: $sources parser: $parser splitter: $splitter retriever_factory: $retriever_factory question_answerer: !pw.xpacks.llm.question_answering.BaseRAGQuestionAnswerer llm: $llm indexer: $document_store`
If you want to change the provider of LLM models, you can change values of `llm` and `embedder`. By changing `llm` to be `LiteLLMChat`, that uses local `api_base`, and `embedder` to be `SentenceTransformerEmbedder` you obtain a local RAG that does not call external services (this pipeline is now very similar to [private RAG](https://github.com/pathwaycom/llm-app/tree/main/templates/private_rag)
from the llm-app).
`$sources: - !pw.io.fs.read path: data format: binary with_metadata: true $llm_model: "ollama/mistral" $llm: !pw.xpacks.llm.llms.LiteLLMChat model: $llm_model retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy max_retries: 6 cache_strategy: !pw.udfs.DiskCache temperature: 0 top_p: 1 format: "json" # only available in Ollama local deploy, not usable in Mistral API api_base: "http://localhost:11434" $embedding_model: "avsolatorio/GIST-small-Embedding-v0" $embedder: !pw.xpacks.llm.embedders.SentenceTransformerEmbedder model: $embedding_model call_kwargs: show_progress_bar: False $splitter: !pw.xpacks.llm.splitters.TokenCountSplitter max_tokens: 400 $parser: !pw.xpacks.llm.parsers.UnstructuredParser $retriever_factory: !pw.stdlib.indexing.BruteForceKnnFactory reserved_space: 1000 embedder: $embedder metric: !pw.engine.BruteForceKnnMetricKind.COS dimensions: 1536 $document_store: !pw.xpacks.llm.document_store.DocumentStore docs: $sources parser: $parser splitter: $splitter retriever_factory: $retriever_factory question_answerer: !pw.xpacks.llm.question_answering.BaseRAGQuestionAnswerer llm: $llm indexer: $document_store`
Alternatively, you may wish to improve indexing capabilities by using the [HybridIndex](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.HybridIndex)
. In this example you'll use Hybrid Index that combines vector based index - `BruteForceKNN` - and index based on text search - [`TantivyBM25`](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.TantivyBM25)
.
`$sources: - !pw.io.fs.read path: data format: binary with_metadata: true $llm: !pw.xpacks.llm.llms.OpenAIChat model: "gpt-3.5-turbo" retry_strategy: !pw.udfs.ExponentialBackoffRetryStrategy max_retries: 6 cache_strategy: !pw.udfs.DiskCache temperature: 0.05 capacity: 8 $embedder: !pw.xpacks.llm.embedders.OpenAIEmbedder model: "text-embedding-ada-002" cache_strategy: !pw.udfs.DiskCache $splitter: !pw.xpacks.llm.splitters.TokenCountSplitter max_tokens: 400 $parser: !pw.xpacks.llm.parsers.UnstructuredParser $knn_index: !pw.stdlib.indexing.BruteForceKnnFactory reserved_space: 1000 embedder: $embedder metric: !pw.engine.BruteForceKnnMetricKind.COS dimensions: 1536 $bm25_index: !pw.stdlib.indexing.TantivyBM25Factory $hybrid_index_factory: !pw.stdlib.indexing.HybridIndexFactory retriever_factories: - $knn_index - $bm25_index $document_store: !pw.xpacks.llm.document_store.DocumentStore docs: $sources parser: $parser splitter: $splitter retriever_factory: $hybrid_index_factory question_answerer: !pw.xpacks.llm.question_answering.BaseRAGQuestionAnswerer llm: $llm indexer: $document_store`
These are just a few examples, but you can use any components from [LLM xpack](https://pathway.com/developers/api-docs/pathway-xpacks-llm)
to have a pipeline that fully meets your need!
[Templates\
\
Run a template](https://pathway.com/developers/templates/run-a-template)
[Templates\
\
How to Use Your Own Components in YAML Configuration](https://pathway.com/developers/templates/custom-components)
---
# pw.xpacks.connectors | Pathway
pw.xpacks.connectors
====================
This page provides the documentation of connectors in the Live Data Framework that are available as an xpack. **This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
[**read**(url, \*, tenant, client\_id, cert\_path, thumbprint, root\_path, mode='streaming', format='binary', recursive=True, object\_size\_limit=None, with\_metadata=False, refresh\_interval=30, max\_failed\_attempts\_in\_row=8, max\_backlog\_size=None)](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint#pathway.xpacks.connectors.sharepoint.read)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/xpacks/connectors/sharepoint/__init__.py#L307-L450)
Reads a table from a directory or a file in Microsoft SharePoint site. Requires a valid Pathway Live Data Framework Scale license key.
It will return a table with single column `data` containing each file in a binary format.
Note that if you only need to monitor changes in the given directory, you can use the `"only_metadata"` format, in which case the table will contain only the `_metadata` column, and no time or traffic will be spent on downloading the files’ contents.
* **Parameters**
* **url** (`str`) – URL of the SharePoint site including the path to the site. For example: `https://company.sharepoint.com/sites/MySite`;
* **tenant** (`str`) – ID of SharePoint tenant. It is normally a GUID;
* **client\_id** (`str`) – ClientID of the SharePoint application that has the required grants and will be used to access the data;
* **cert\_path** (`str`) – Path to the certificate, normally .pem-file, added to the applicationspecified above and used to authenticate;
* **thumbprint** (`str`) – Thumbprint for the specified certificate;
* **root\_path** (`str`) – The path for a directory or a file within the SharePoint space to beread;
* **mode** (`str`) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"`, it will check for updates, deletions and new files every `refresh_interval` seconds. `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`;
* **format** (`Literal`\[`'binary'`, `'only_metadata'`\]) – The format of the resulting table. Can be either `"binary"`, which corresponds to a table with a `data` column containing each file’s contents, or `"only_metadata"`, which corresponds to a table that has only the `_metadata` column with the objects’ metadata, without downloading the objects themselves;
* **recursive** (`bool`) – If set to `True`, the connector will scan the nested directories. Otherwise it will only process files that are placed in the specified directory;
* **object\_size\_limit** (`int` | `None`) – Maximum size (in bytes) of a file that will be processed by this connector or `None` if no filtering by size should be made;
* **with\_metadata** (`bool`) – when set to `True`, the connector will add an additional column named `_metadata` to the table. This column will contain file metadata, such as: `path`, `modified_at`, `created_at`. The creation and modification times will be given as UNIX timestamps;
* **refresh\_interval** (`int` | `float` | `timedelta`) – Time between scans, given as a number of seconds or a `datetime.timedelta` / `pw.Duration`. Applicable if mode is set to `"streaming"`.
* **max\_failed\_attempts\_in\_row** (`int` | `None`) – The maximum number of consecutive read errors beforethe connector terminates with an error. If set to `None`, the connector tries to readdata indefinitely, regardless of possible errors in the provided credentials.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
The table read.
Example:
Let’s consider that there is a dataset stored in SharePoint site Datasets. Below we give an example for reading this dataset in the streaming mode. Please note that you canuse this example for the reference of how the parameters should look:
`t = pw.xpacks.connectors.sharepoint.read( url="https://company.sharepoint.com/sites/Datasets", tenant="c2efaf1f-8add-4334-b1ca-32776acb61ea", client_id="f521a53a-0b36-4f47-8ef7-60dc07587eb2", cert_path="certificate.pem", thumbprint="33C1B9D17115E848B1E956E54EECAF6E77AB1B35", root_path="Shared Documents/Data", )`
In the example above we also consider that this dataset is located by the path `Shared Documents/Data`. This code will also recursively scan the subdirectories of thegiven directory.
We can change it a little. Let’s suppose that we need to take the dataset from the directory `Datasets/Animals/2023` and not take the nested subdirectories into consideration. That leads us to the following snippet:
`t = pw.xpacks.connectors.sharepoint.read( url="https://company.sharepoint.com/sites/Datasets", tenant="c2efaf1f-8add-4334-b1ca-32776acb61ea", client_id="f521a53a-0b36-4f47-8ef7-60dc07587eb2", cert_path="certificate.pem", thumbprint="33C1B9D17115E848B1E956E54EECAF6E77AB1B35", root_path="Datasets/Animals/2023", recursive=False, )`
SharePoint sites are often used with the subsites. The Pathway Live Data Framework supports the data reads from the subsites as well. To read the data from the subsite, you need to specify its’ URL in the `url` parameter. For example, if you read the dataset from `vendor` subspace, you can configure the connector this way:
`t = pw.xpacks.connectors.sharepoint.read( url="https://company.sharepoint.com/sites/Datasets/vendor", tenant="c2efaf1f-8add-4334-b1ca-32776acb61ea", client_id="f521a53a-0b36-4f47-8ef7-60dc07587eb2", cert_path="certificate.pem", thumbprint="33C1B9D17115E848B1E956E54EECAF6E77AB1B35", root_path="Datasets/Animals/2023", recursive=False, )`
[API Docs\
\
pw.udfs](https://pathway.com/developers/api-docs/udfs)
[API Docs\
\
pw.xpacks.llm](https://pathway.com/developers/api-docs/pathway-xpacks-llm)
---
# Financial Report Analysis with LiveAI™ | Pathway
Table of Contents
[Introduction](https://pathway.com/framework/blog/ai-financial-report-analysis#introduction)
---------------------------------------------------------------------------------------------
Most finance work starts with a pile of documents: annual reports, quarterly results, investor decks, filings. They’re long, they change often, and the facts you need are scattered across pages and versions. The result? Hours spent scrolling, searching, and cross-checking numbers just to answer a simple question like _“How did margins change compared to last quarter?”_
This blog introduces a different way forward: Financial report analysis with LiveAI™. Instead of digging through static PDFs, you ask plain-English questions and get clear answers, always grounded in the latest version of your reports.
Financial teams drown in PDFs: annual reports, investor presentations, SEC/SEBI filings, broker notes; each packed with metrics that move decisions. This post shows how to do financial report analysis with LiveAI™, so you can turn those documents into reliable, queryable insights in minutes not days.
**Why LiveAI™ matters:** traditional RAG pipelines go stale the moment your corpus changes. The Pathway Live Data Framework treats static and streaming data the same way: once your documents are preprocessed and indexed, it auto-detects updates in your document directory and refreshes the store, keeping every answer grounded in the latest facts. In other words, your RAG stays live by design: no manual re-indexing, no nightly jobs, no lag.
Under the hood, we pair this real-time substrate with an agentic workflow designed for finance. A **decider** routes simple vs. complex asks; **query augmentation** expands finance shorthand (EPS, EBITDA, ROI, CAGR) to boost recall; **multi-agent retrieval** pulls from internal knowledge, the web, and downloaded finance PDFs; a **consolidation step** resolves conflicts across sources; and **guardrails** (PII/profanity checks) keep outputs safe and compliant. The result is a pipeline built to handle noisy PDFs and contradictory narratives without melting down.
### [Why you should care:](https://pathway.com/framework/blog/ai-financial-report-analysis#why-you-should-care)
* **Speed:** jump from 200-page PDFs to answers (revenue, margins, guidance shifts) in a single query.
* **Accuracy:** conflict-aware consolidation reduces hallucinations and reconciles PRs vs. filings vs. transcripts.
* **Coverage:** works across annual reports, quarterly results, regulatory filings, and investor decks.
* **Compliance:** guardrails help you avoid leaking sensitive identifiers while staying audit-friendly.
### [What you’ll learn in this post](https://pathway.com/framework/blog/ai-financial-report-analysis#what-youll-learn-in-this-post)
* How LiveAI™ keeps your RAG real-time without extra ETL.
* A finance-tuned, multi-agent architecture that understands jargon and multi-hop questions.
* A PDF-first ingestion pattern for balance sheets, income statements, cash-flows, and risk sections.
* Practical prompts, schemas, and deployment tips you can reuse for your own AI financial repo
Read on to see how to plug this into your workflow and ship insights your stakeholders can trust.
[Financial Report Analysis with LiveAI™: A Multi-Agent Workflow with Response Resolution](https://pathway.com/framework/blog/ai-financial-report-analysis#financial-report-analysis-with-liveai-a-multi-agent-workflow-with-response-resolution)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [Overview](https://pathway.com/framework/blog/ai-financial-report-analysis#overview)
The solution integrates advanced techniques to build a robust Retrieval-Augmented Generation (RAG) system:
* **Decider agent**: A decider classifies queries as either simple or complex. Simple queries, which rely on general knowledge or straightforward logic, are answered directly using the agent's internal knowledge, while complex queries requiring tools, data processing, or sub-questions are forwarded for further processing (see Figure 1).
* **Query Augmentation**: Detects jargon using a dynamic repository and enriches queries via a Large Language Model(LLM) to enhance retrieval accuracy.
* **Pathway Integration**: Utilizes Pathway APIs with Google Drive for scalable storage and automated indexing, supporting diverse data formats (e.g., PDFs, JSON).
* **Multi-Agent Retrieval**: Implements tools for direct answers, internal knowledge retrieval, web search, and domain-specific retrieval (e.g., financial data in PDFs).
* **Conflict Resolution**: Addresses conflicting information through iterative knowledge consolidation, conflict flagging, and generating reliable answers. Guardrails ensure ethical and secure outputs.
* **User Interface**: Combines Flask and React for a responsive and low-latency interface. This system ensures accurate, scalable, and context-aware retrieval and response generation.
### [System Demonstration: AI Financial Report Analysis](https://pathway.com/framework/blog/ai-financial-report-analysis#system-demonstration-ai-financial-report-analysis)
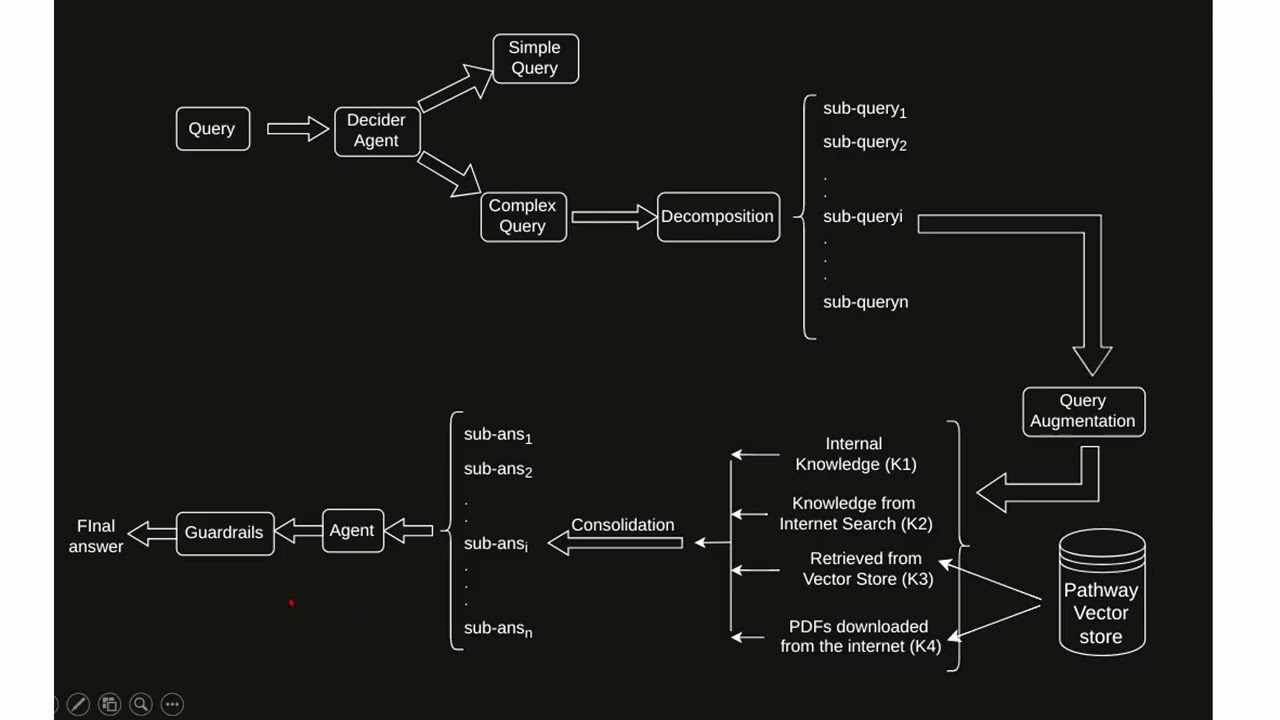
### [Code Repository - Complete Setup & Usage Guide](https://pathway.com/framework/blog/ai-financial-report-analysis#code-repository-complete-setup-usage-guide)
[\
\
AI Financial Report AnalysisGitHub](https://github.com/Kesav73/AI-Financial-Report-Analysis.git)
### [Query Decomposition and Augmentation](https://pathway.com/framework/blog/ai-financial-report-analysis#query-decomposition-and-augmentation)
As new information is continually generated, user queries may include terms that carry different meanings depending on the context. Specifically, queries containing jargon accompanied by some context can be reinterpreted to provide more precise or alternative meanings using an LLM.
To address this use case, we focus on identifying jargon within the user's query. This is achieved using a semi-dynamic predefined store that serves as a repository for querying and managing jargon. New jargon encountered can be added to this store, ensuring its adaptability over time.
Once jargon is identified, the entire query is passed to the LLM, which generates an augmented version enriched with additional contextual information. This process ensures that the retriever aligns more closely with the user's intent, enhancing the relevance and accuracy of the retrieved information.
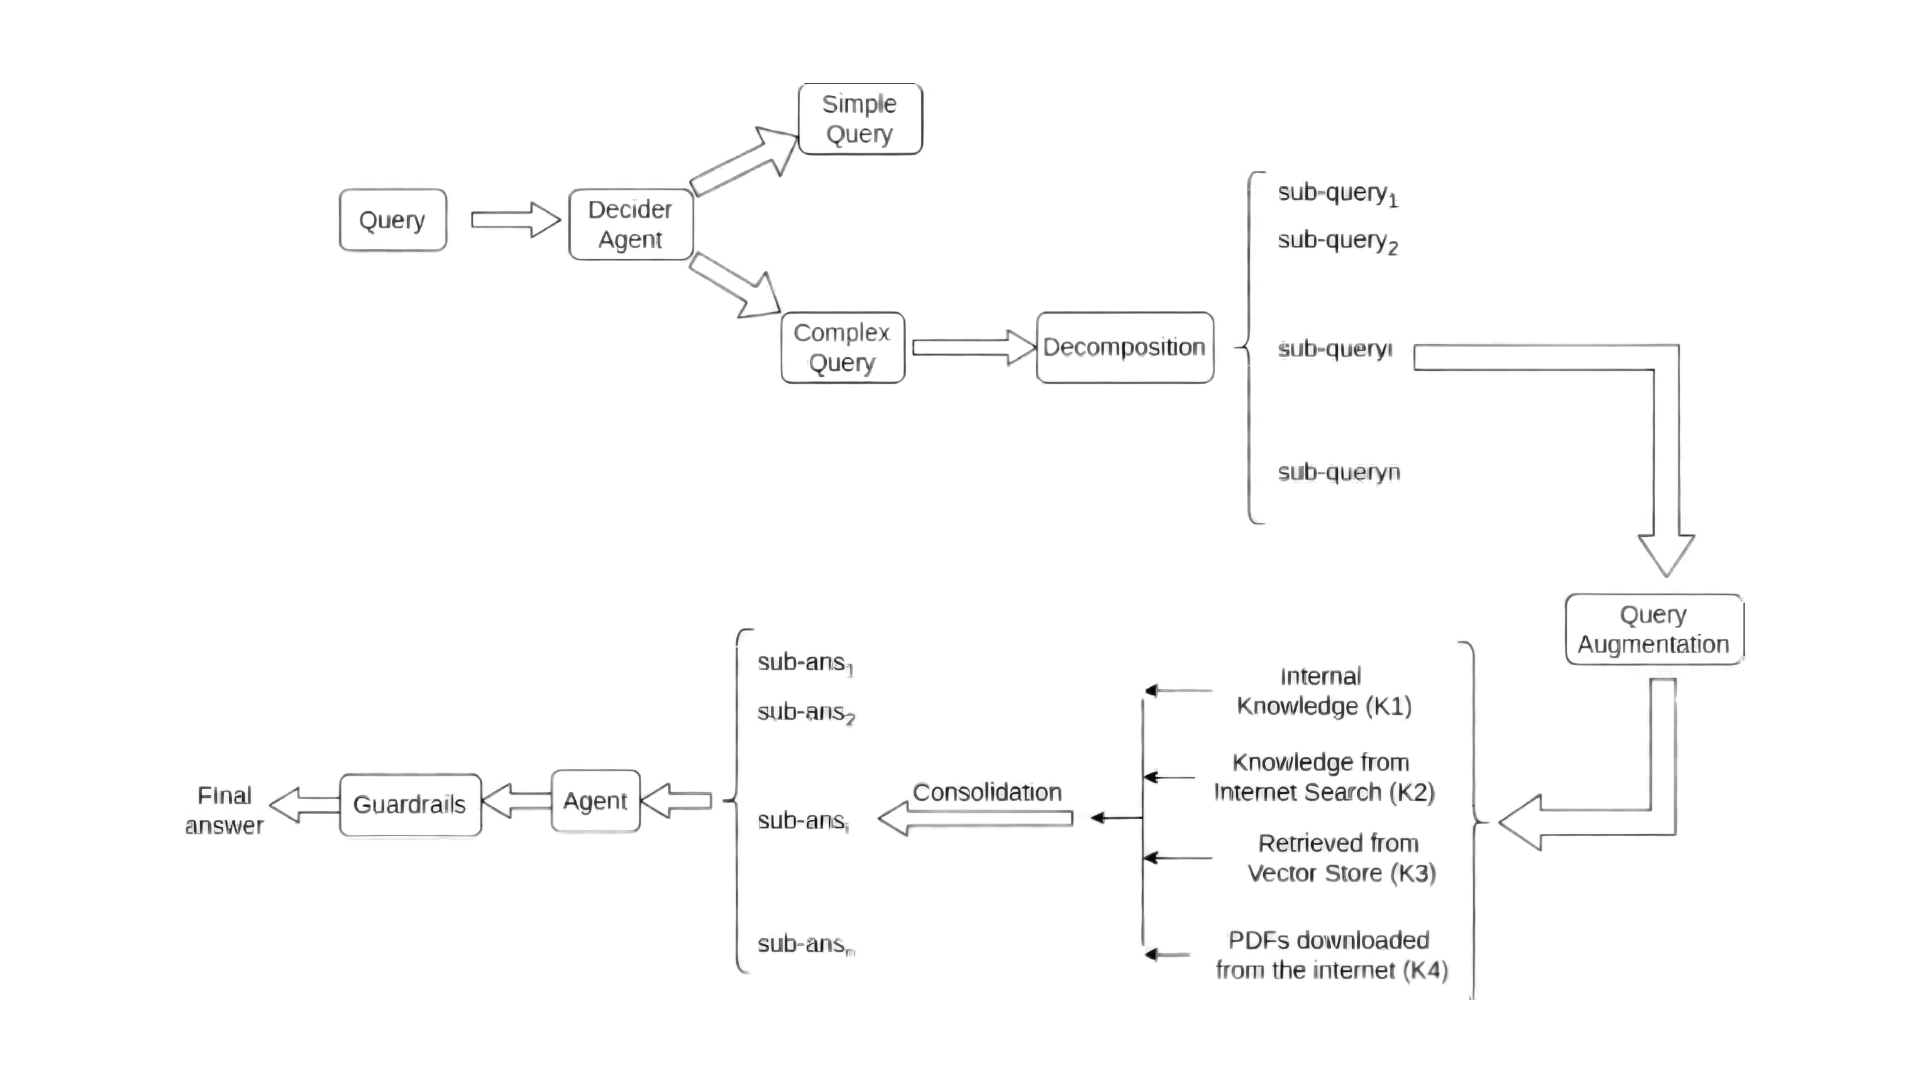
### [Integration with Pathway](https://pathway.com/framework/blog/ai-financial-report-analysis#integration-with-pathway)
The integration of Pathway offers a flexible and versatile approach, leveraging its diverse range of APIs. For data storage, we chose Google Drive, primarily due to its adaptability and compatibility with our design requirements. This choice also aligns with our scalable approach, enabling seamless support for various data formats, such as PDF, JSON, and SQL, with minimal effort.
Moreover, the framework's existing vector store architecture facilitates efficient data management. Its reactivity allows for easy and rapid additions, deletions, and updates, all of which are automatically incorporated into the system. Additionally, the framework's automated indexing capabilities further enhance the efficiency of our workflow, ensuring smooth and reliable data retrieval.
### [Multi-Agent Retrieval for Financial Report Analysis](https://pathway.com/framework/blog/ai-financial-report-analysis#multi-agent-retrieval-for-financial-report-analysis)
Initially, we adopted a divide-and-regain strategy for our approach. However, we discovered that this method resulted in incomplete integration of conflicting knowledge. To address this limitation, we explored an alternative approach, as outlined below.
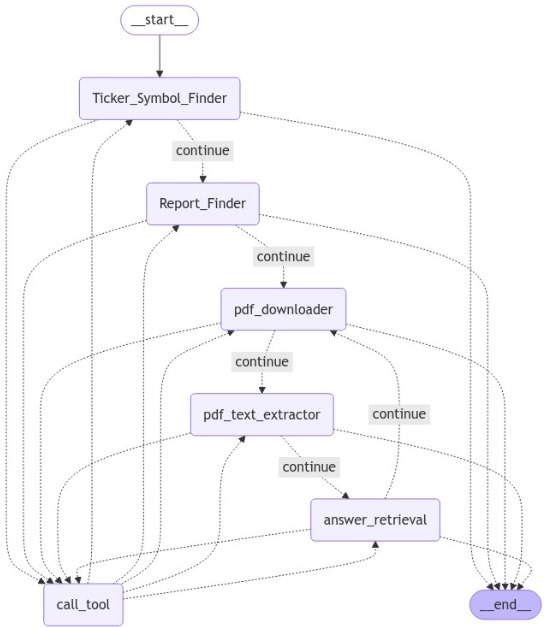
* **Internal Knowledge agent**: This works when the LLM possesses the information in its internal knowledge to answer the query which has been asked.
* **Retrieval Agent**: We have set up the "retrieve\_documents" tool to search for relevant documents from the internal knowledge base.
* **Web Search Agent**: Here, we used the "tavily\_tool" to perform a web search which effectively finds critical and relevant information related to our context, if real time financial information like stock prices etc. is required then "google\_search\_tool" shall also be used.
* **Downloaded Documents agent**: This implementation introduces a novel approach focused on extracting domain-specific knowledge, specifically targeting the finance sector. It enables the retrieval and processing of PDF documents, as financial information from major companies is often stored in this format. Future scalability plans include integrating a web-list, allowing the system to expand and gather domain-specific knowledge from a variety of fields beyond finance depending upon the use case.
* **Consolidation agent**: The Consolidation Agent collects information retrieved by the above agents, it then processes this data using an iterative consolidation tool to reconcile discrepancies and ensure consistency. The final output consists of the most reliable and coherent information, providing a comprehensive and accurate response.
### [Resolving Conflicting Responses](https://pathway.com/framework/blog/ai-financial-report-analysis#resolving-conflicting-responses)
Once we get data from retrieval, we proceed to resolving issues arising from unreliable external sources through the integration of internal and external information through a series of steps.
1. **Adaptive Internal Knowledge Generation**: The LLM generates passages based on its internal knowledge relevant to the given query, this acts as a data source going forward.
2. **Iterative Source-Aware Knowledge Consolidation**: Next, we consolidate and refine the knowledge pool by selectively iterating through the generated and retrieved passages obtained from various sources.
3. **Identifying Conflicts**: Passages which present conflicting information are separated and flagged as conflicting. This allows the model to evaluate the reliability of each conflicting source, preventing the combination of contradictory data. We have also found the answers with a confidence which can be even converted to a score later on in future work.
4. **Answer Finalization**: Finally, we generate the final, reliable answer from the consolidated knowledge pool. This is done through the consideration of multiple perspectives to provide a well-rounded response.
5. **Guardrails**: It has been noticed that sometimes the answer provided could contain information which is private/controversial. To prevent the generation of answers like this, we have implemented rail checks which ensured that such information is not included in the final response.
### [Integration with User Interface](https://pathway.com/framework/blog/ai-financial-report-analysis#integration-with-user-interface)
For the development of our solution, we integrated Flask with React, ensuring a seamless and efficient design. Special attention was given to minimizing latency to provide a smooth user experience. The resulting user interface features a dynamic and intuitive design, making it easy to navigate and interact with our solution.
[Novelty and Specific Use-Cases](https://pathway.com/framework/blog/ai-financial-report-analysis#novelty-and-specific-use-cases)
---------------------------------------------------------------------------------------------------------------------------------
### [Use Cases](https://pathway.com/framework/blog/ai-financial-report-analysis#use-cases)
Our solution is specifically designed for the finance domain, addressing limitations in current solutions that typically rely on scraping raw text from web pages. These existing methods often miss out on structured and essential data found in documents like PDFs. Our approach leverages a multi-agent system that not only searches for and downloads PDF documents, such as financial report press releases, but also extracts meaningful insights from them, like tables, graphs, and key financial metrics.
For example, while many financial websites may display earnings reports or balance sheets in a web page's text, the most accurate and comprehensive information often resides in downloadable PDF documents. Our system efficiently retrieves these documents, extracts critical data such as revenue, profits, and year-over-year growth rates, and processes them to provide a more structured and insightful analysis. By focusing on these high-value sources, we ensure that the information we deliver is both up-to-date and relevant, providing a more accurate picture of a company's financial health.
### [Jargon Expansion in Question Augmentation](https://pathway.com/framework/blog/ai-financial-report-analysis#jargon-expansion-in-question-augmentation)
Our approach introduces jargon expansion as a key enhancement to the Agentic RAG framework, ensuring that domain-specific abbreviations and technical terms are fully understood by the retrieval system. This improves the accuracy and relevance of retrieved information, especially in domains with complex jargon. Our method stands out by automatically expanding jargon within financial queries, enabling the system to better interpret terms like EPS (Earnings Per Share) or P/E ratio (Price-to-Earnings Ratio). This ensures precise document retrieval and improves query understanding without requiring manual intervention.
### [Use Cases in Finance](https://pathway.com/framework/blog/ai-financial-report-analysis#use-cases-in-finance)
**Stock Market Analysis**: Financial queries that contain shorthand terms like EPS or P/E ratio are expanded to their full forms, ensuring accurate retrieval of relevant stock market data. Example: "What's the impact of EPS on stock performance?" becomes "What's the impact of Earnings Per Share (EPS) on stock performance?"
**Investment Strategy**: Terms like ROI (Return on Investment) or CAGR (Compound Annual Growth Rate) are expanded to help retrieve more specific and relevant investment insights. Example: "What's the effect of ROI on business growth?" becomes "What's the effect of Return on Investment (ROI) on business growth?"
**Financial Reports**: Queries involving financial statements or metrics are enhanced by expanding abbreviations like EBITDA (Earnings Before Interest, Taxes, Depreciation, and Amortization), ensuring proper understanding in reports. Example: "How does EBITDA affect company valuation?" becomes "How does Earnings Before Interest, Taxes, Depreciation, and Amortization (EBITDA) affect company valuation?"
**Advantage**
* This approach allows for easy domain-specific tuning without retraining models. By expanding jargon, we can fine-tune the system for the finance domain, ensuring efficient and precise query handling for financial analysis, investment strategies, and reporting.
### [Question decomposition](https://pathway.com/framework/blog/ai-financial-report-analysis#question-decomposition)
In finance, users often ask questions that require insights from multiple angles. Query decomposition breaks down these complex questions into manageable sub-queries, enabling the system to retrieve and combine information from various sources for a more comprehensive answer.
**Example of Query Decomposition**
> Original Query: "Who is the CEO of the company that made the biggest loss in Q3 2024?" This query requires two distinct pieces of information: The company that made the biggest loss. The CEO of that company.
To break it down:
> Sub-query 1: "Which company made the biggest loss in Q3 2024?"
> Sub-query 2: "Who is the CEO of Company Name?"
By splitting the query, the system can pull the relevant details from separate documents---one about Q3 2024 financial results and another listing company executives---and then combine them to generate the final answer.
Process in Action:
> Sub-query 1 Retrieval: Search for data on financial losses in Q3 2024 and find that Company XYZ reported the biggest loss.
> Sub-query 2 Retrieval: Search for information on Company XYZ and find that the CEO is Jane Doe.
Final Answer: "The CEO of the company that made the biggest loss in Q3 2024, Company XYZ, is Jane Doe."
### [Financial Data from PDFs: A Novel Approach to Domain-Specific Retrieval](https://pathway.com/framework/blog/ai-financial-report-analysis#financial-data-from-pdfs-a-novel-approach-to-domain-specific-retrieval)
A standout feature of our multi-agent retrieval system is its ability to extract and process financial data from PDFs. In industries like finance, crucial information is often stored in PDF format, especially when companies release detailed financial reports, earnings statements, regulatory filings, and annual reports. Traditional information retrieval systems might struggle to access and interpret this rich, domain-specific content. Our solution addresses this challenge by integrating a dedicated PDF extraction tool tailored specifically for financial data. This tool not only locates and retrieves PDF documents containing valuable financial knowledge but also processes them effectively to extract key insights such as:
* **Balance Sheets**: Extracting financial data related to assets, liabilities, and equity to understand a company's financial health.
* **Income Statements**: Identifying revenue, expenses, and profit margins to assess operational performance.
* **Cash Flow Statements**: Capturing cash inflows and outflows, which is crucial for understanding liquidity and financial stability.
* **Investment Insights**: Parsing through investment-related documents, including corporate announcements and projections, that influence market behavior.
he financial PDF extraction tool operates seamlessly alongside other retrieval agents, ensuring that when users ask finance-related questions, the system can efficiently retrieve and process the most relevant, up-to-date financial information directly from these sources. For example, if a user asks, "What were the revenue trends of XYZ Corp in the Q4 report for 2024?", the system would locate the latest PDF document containing XYZ Corp's financial report, extract the revenue data from the income statement, and present the insights directly in response.
### [Filtering Out Relevant Information](https://pathway.com/framework/blog/ai-financial-report-analysis#filtering-out-relevant-information)
A key challenge in Retrieval-Augmented Generation (RAG) systems is ensuring the reliability and relevance of the information pulled from both internal and external sources. To address this, our approach integrates a series of systematic steps designed to enhance the performance of RAG while filtering out unreliable or conflicting data. This novel methodology ensures that the generated responses are both accurate and comprehensive.
Our information filtering process includes the following steps:
* **Adaptive Internal Knowledge Generation**: Initially, the LLM generates relevant passages from its internal knowledge base. These passages are generated based on the specific context of the query, ensuring that the information provided aligns with the user's needs and the domain of the query.
* **Iterative Source-Aware Knowledge Consolidation**: Once the internal knowledge is generated, the system consolidates and refines the knowledge pool by iterating through both generated and retrieved passages. This step ensures that the most relevant and high-quality information is retained while less relevant data is filtered out.
* **Identifying Conflicts**: In the case where different passages provide conflicting information (such as contradictory facts or varying perspectives), these conflicting passages are flagged and separated. This step is crucial in preventing the combination of contradictory data in the final answer. The system evaluates the reliability of each conflicting source, ensuring that only the most trustworthy and consistent information contributes to the final response.
* **Answer Finalization**: Finally, the system generates the most reliable answer by drawing from the consolidated knowledge pool. The final response is shaped by considering multiple perspectives and integrating the best sources of information, ensuring that the result is both balanced and well-rounded.
**Advantages**
This filtering process significantly improves the quality and accuracy of the generated answers. By systematically filtering and consolidating information from various sources, we ensure that the final response reflects the most reliable and relevant data. Moreover, by flagging conflicting information and evaluating its reliability, our system reduces the risk of propagating errors and inconsistencies, which is especially important in domains like finance, where accurate, dependable information is paramount. Through this innovative filtering mechanism, we not only enhance the performance of RAG but also ensure that the responses are trustworthy, relevant, and comprehensive, providing users with a robust tool for answering complex queries.
| Dataset | Norm Rouge-1 | | Norm Rouge-2 | | Embed Rouge-1 | | Embed Rouge-2 | |
| --- | --- | --- | --- | --- | --- | --- | --- | --- |
| Vanilla | R2R | Vanilla | R2R | Vanilla | R2R | Vanilla | R2R |
| --- | --- | --- | --- | --- | --- | --- | --- | --- |
| FinanceBench | 0.0769 | 0.1334 | 0.0231 | 0.0426 | 0.0908 | 0.1663 | 0.0458 | 0.0899 |
_Table 1: Rouge_
| Dataset | Meteor | |
| --- | --- | --- |
| Vanilla | R2R |
| --- | --- | --- |
| FinanceBench | 0.1069 | 0.1548 |
_Table 2: Meteor Scores_
### [Guardrails](https://pathway.com/framework/blog/ai-financial-report-analysis#guardrails)
To ensure user safety and maintain ethical standards, we have implemented robust guardrails within the multi-agent RAG system. These guardrails are designed to identify and redact sensitive information such as credit card numbers, Aadhaar numbers, PAN, CVV, GSTIN, and IFSC codes using a combination of Presidio Analyzer and Presidio Anonymizer libraries. Additionally, we utilize Better Profanity to detect and censor offensive language, replacing inappropriate content with redaction markers. Custom rules tailored for India-specific identifiers enhance the system's ability to manage local regulatory requirements. By integrating these components, the system ensures that all outputs are sanitized, free from harmful or private information, and safe for user consumption. This critical feature reinforces the reliability and trustworthiness of the RAG system across diverse use cases.
[Evaluation of the Approach for Financial Report Analysis](https://pathway.com/framework/blog/ai-financial-report-analysis#evaluation-of-the-approach-for-financial-report-analysis)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
The evaluation of our Retrieval-Augmented Generation (RAG) system focuses on assessing the effectiveness of the retrieval component, which plays a crucial role in selecting and ranking relevant documents or data. To gauge how well the retrieval phase operates, we measure its performance using several standard metrics, which allow us to monitor the precision and overall quality of our pipeline. In particular, we use metrics such as ROUGE scores and METEOR, calculated for different values of k, to provide insights into the effectiveness of our retrieval mechanism.
**ROUGE Score**
ROUGE (Recall-Oriented Understudy for Gisting Evaluation) is a widely-used metric for evaluating automatic summarization and machine translation systems. It combines precision, recall, and F1-score by considering k-grams (subsequences of k words). For this evaluation, we have chosen ROUGE-1 and ROUGE-2 with values of k set to 1 and 2, respectively. The choice of these values comes from the observation that larger values of k often result in difficulty finding exact matching n-grams in scenarios where the answer can be augmented by the language model (LLM). Thus, using k = 1 and k = 2 allows for a reasonable balance between capturing meaningful content while acknowledging the challenges posed by larger k-grams.
**METEOR Score**
METEOR (Metric for Evaluation of Translation with Explicit ORdering) is another automatic evaluation metric, originally developed for machine translation. It evaluates translation quality by comparing unigrams between machine-produced and human-produced reference translations. Unigrams are matched based on their surface forms, stemmed forms, and meanings. METEOR then calculates a score by combining unigram precision, unigram recall, and a measure of fragmentation that captures how well-ordered the matched words are relative to the reference. This ordering is particularly valuable in evaluating sentence accuracy and fluency.
**Datasets**
Given that our solution is primarily focused on financial tasks, we selected datasets that are relevant to the domain of finance while also choosing general datasets to maintain comparability with other solutions. The datasets used for this evaluation are HOTPOTQA, TriviaQA, and FinanceBench (a dataset specifically focused on financial terms). These datasets allow us to assess the system's performance in both general knowledge and domain-specific contexts. For the evaluation, we present results from our RAG implementation on the FinanceBench dataset, compared to the baseline Vanilla RAG.
**Evaluation Results**
The evaluation metrics used include both the ROUGE and METEOR scores, as shown in the Tables 1 and 2. Our results indicate a significant improvement in performance with our approach compared to Vanilla RAG.
* ROUGE-1: **73.4%** improvement.
* ROUGE-2: **84.7%** improvement.
* Embed ROUGE-1: **83.0%** improvement.
* Embed ROUGE-2: **96.4%** improvement.
* METEOR: **44.8%** improvement.
[Conclusion](https://pathway.com/framework/blog/ai-financial-report-analysis#conclusion)
-----------------------------------------------------------------------------------------
This solution built using the Pathway Live Data Framework addresses significant limitations in traditional RAG systems by introducing a multi-agent design capable of resolving conflicting responses and refining query decomposition. Its integration with Pathway and the ability to handle diverse data formats ensure scalability and adaptability. Focused on the finance domain, it demonstrates practical utility through its capacity to retrieve and analyze structured data, such as financial PDFs, with precision. The approach’s novelty lies in its modular design, conflict resolution mechanisms, and ability to expand into other domains. Future scalability through unified embeddings and Swanson linking shows promise for broader applications, making this solution a notable advancement in intelligent query handling and domain-specific retrieval systems.
If you are interested in diving deeper into the topic, here are some good references to get started with Pathway:
* [Pathway Live Data Framework Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
* [Pathway Live Data Framework's Ready-to-run App Templates](https://pathway.com/developers/templates)
* [End-to-end Real-time RAG app with Pathway Live Data Framework Live Data Framework](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
* [Discord Community](https://discord.gg/pathway)
[References](https://pathway.com/framework/blog/ai-financial-report-analysis#references)
-----------------------------------------------------------------------------------------
[Authors](https://pathway.com/framework/blog/ai-financial-report-analysis#authors)
-----------------------------------------------------------------------------------
* [Kesav Patneedi](https://www.linkedin.com/in/kesav-patneedi-b804932a9)
* [Rohan Kumar Mishra](https://www.linkedin.com/in/rohan-kumar-mishra-996b911bb)
* [Nishant Verma](https://www.linkedin.com/in/me-nishant-verma)
* [Bhavik Shangari](https://www.linkedin.com/in/bhavik-shangari-416b0324a)
* [Vedansh Sharma](https://www.linkedin.com/in/vedansh-sharma-202809218)
* [Uday Bhardwaj](https://www.linkedin.com/in/uday-bhardwaj-054013265)
* [Ojus Goel](https://www.linkedin.com/in/ojusgoel)
* [Avinash Patel](https://www.linkedin.com/in/avinash-patel-633195283)
* * *

Pathway Live Data Framework Community
Multiple authors
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Sajjad Nakhwa\
\
communityFeb 11, 2025\
\
How Text Embeddings help suggest similar words](https://pathway.com/framework/blog/how-text-embeddings-help-suggest-similar-words)
* [\
\
\
\
Pathway Team\
\
showcase · llmAug 6, 2024\
\
Multimodal RAG with Gemini](https://pathway.com/framework/blog/gemini-rag)
* [\
\
\
\
Saksham Goel\
\
showcase · llm · case-study · engineeringJul 15, 2024\
\
Real-time Enterprise RAG with SharePoint](https://pathway.com/framework/blog/enterprise_rag_sharepoint)
[Blog\
\
How AI Agents in Finance Are Transforming Financial Due Diligence: FA3STER](https://pathway.com/framework/blog/ai-agents-finance-due-diligence)
[Blog\
\
LiveAI™ for SEC Filings Analysis](https://pathway.com/framework/blog/ai-for-sec-filings)
---
# How AI Agents in Finance Are Transforming Financial Due Diligence: FA3STER | Pathway
Table of Contents
[Introduction](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#introduction)
------------------------------------------------------------------------------------------------
Financial due diligence represents a highly resource-intensive, time-consuming and painstakingly manual process, often extending over several weeks or months. This complexity arises from the need for exhaustive, detailed analysis and reasoning across financial datasets, which often require frequent updates.
In our ambitious approach , we're harnessing **the Pathway Live Data Framework's dynamic capabilities** to develop a cutting-edge Agentic RAG (Retrieval-Augmented Generation) system. Our goal? To create a solution that autonomously retrieves, analyzes, and synthesizes information from diverse documents—solving real-world challenges efficiently.
Our solution, designed around the core objectives outlined earlier, directly addresses the key pain points of financial due diligence (FDD). It is tailored to serve all of the stakeholders of FDD, from investors to analysts and lawyers, by automating document analysis, accurately responding to queries, and dynamically adapting to changing document datasets. Additionally, it generates summarized, concise FDD reports and quick-look dashboards for targeted firms, offering a strong starting point in the due diligence process. It can also be used independently to perform Q&A on financial documents.
### [A Quick 3-Minute Overview of FA3STER – an Autonomous, Multi-Agent Real-Time RAG System](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#a-quick-3-minute-overview-of-fa3ster-an-autonomous-multi-agent-real-time-rag-system)

[Why does it stand out ?](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#why-does-it-stand-out)
--------------------------------------------------------------------------------------------------------------------
While there are generic RAG-based systems available for Q&A on documents, these have moderate accuracy and often suffer from high scope for error. Given the high stakes involved in FDD, these systems cannot be relied upon
* **Real-World Application**: Our solution is not just an abstract RAG implementation—it is purpose-built to handle the complexities of financial due diligence (FDD).
* **Versatile Functionality**: Beyond streamlining the FDD process, our solution can also act as an agentic RAG-based chatbot for financial documents, capable of answering complex queries related to financial documents.
* **Innovative Architecture**: Our approach is not just about using RAG but refining it. This is validated by both theoretical intuitions and empirical results.
* **Unmatched Offering**: The competitive landscape lacks a dedicated solution that combines all such aspects that parallel the comprehensive and innovative capabilities we deliver for our specific use case of enhancing the FDD process.
[Solution Overview](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#solution-overview)
----------------------------------------------------------------------------------------------------------
**F**inancial **A**gentic **A**utonomous and **A**ccurate **S**ystem **T**hrough **E**volving (Dynamic) **R**etrieval Augmented Generation, or FA3STERFA^3STERFA3STER is designed to address the challenges of FDD. At the heart of FA3STER lies a sophisticated four-component architecture:
### [1\. Intelligent Retrieval with Context-Aware Chunking](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_1-intelligent-retrieval-with-context-aware-chunking)
FA3STER enhances document parsing through an **Agentic Chunker**, ensuring contextually relevant information retrieval. Powered by the Pathway Live Data Framework’s real-time streaming and dynamic indexing, this phase improves accuracy while keeping data fresh.
### [2\. Autonomous Post-Retrieval Processing](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_2-autonomous-post-retrieval-processing)
Our system goes beyond simple data retrieval by integrating **specialized agents** for finance, document grading, SQL querying, and data visualization. These agents intelligently analyze, cross-validate, and optimize workflows—minimizing errors and ensuring reliable insights.
### [3\. The Vertical Autonomous Layer (The Game-Changer)](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_3-the-vertical-autonomous-layer-the-game-changer)
Rather than just stacking more tools, FA3STER introduces a self-improving network of interlinked agents that:
* Collaborate, cross-check findings, and exchange knowledge
* Iterate through multiple rounds to refine financial insights
* Generate concise, actionable FDD reports and real-time dashboards
### [4\. Transparent and Interactive UI](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_4-transparent-and-interactive-ui)
Users get a real-time agent workflow visualization, allowing complete transparency into how FA3STER processes financial documents. The interactive UI makes complex operations accessible, ensuring seamless user experience.
[System Architecture](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#system-architecture)
--------------------------------------------------------------------------------------------------------------
Our multi-agent RAG system ensures precision, seamless integration, and robust performance in financial analysis. It leverages the Pathway Live Data Framework’s Dynamic Indexing Pipeline, integrating Vector Store and Google Drive Connector for real-time data updates.
Key components include:
* **Agentic Chunker (GPT-4o-mini)** – Enhances document fragments for context-aware retrieval.
* **Unstructured’s Parser & OpenAI’s text-embedding-3-small** – Processes unstructured data and enables hybrid indexing with semantic search and metadata filtering.
* **Cohere’s Re-ranker** – Optimizes complex query decomposition and ranking.
* **LangGraph & SELF-RAG Architecture** – Drives post-retrieval decision-making with specialized financial agents.
* **Tavily Search & Reasoning Agents** – Enrich data with external sources and generate insightful visualizations.
### [Code Repository – Complete Setup & Usage Guide](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#code-repository-complete-setup-usage-guide)
[\
\
lalit-03/fa3ster-iitp-interiit-techGitHub](https://github.com/lalit-03/fa3ster-iitp-interiit-tech)
[Pre-Retrieval and Retrieval](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#pre-retrieval-and-retrieval)
------------------------------------------------------------------------------------------------------------------------------

1. **The Pathway Live Data Framework’s Real-Time Streaming**
The Pathway Live Data Framework’s Google Drive connector dynamically streamlines data ingestion into the RAG system, supporting both real-time updates and one-time imports.
2. **Pre-Retrieval Workflow and Data Processing**
Since the documents are mainly in pdf format, we need to have them converted to embeddings before using them for retrieval. For that we have to parse the document, chunk and embed it and finally store it in the vector store.
* **Unstructured’s Parser**: Unstructured.io's parsing tools excel at extracting structured data from various financial document formats, including tables, lists, and key-value pairs.
* **Agentic Chunker (GPT-4o-mini)**
* Goes beyond standard segmentation by enriching document chunks with contextual metadata.
* Enhances retrieval accuracy by incorporating semantic relationships across different document sections.
* Addresses limitations of traditional retrieval methods by improving nuanced understanding and relevance ranking.
* **OpenAI’s text-embedding-3-small**: OpenAI's text-embedding-3-small model generates vector representations of text, capturing semantic meaning.
* **The framework’s Vector Store**
* Optimized for storing and retrieving embeddings, enabling efficient similarity search.
* Supports dynamic updates, ensuring the database remains up to date as new financial data is ingested.
* Implements Hybrid Indexing, combining:
* Semantic relevance (vector embeddings).
* Metadata-based filtering (e.g., company name, stock ticker, document date).
* Provides scalability for large financial datasets.
3. **Query Decomposer**: Breaks down complex financial queries into smaller subqueries, allowing retrieval of relevant documents from multiple perspectives.
4. **Cohere Re-ranker**: Assigns a relevance score to each document by understanding the query's intent, ensuring that the most relevant knowledge base entries are prioritized in responses.
[Post-Retrieval](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#post-retrieval)
----------------------------------------------------------------------------------------------------

FA3STER’s post-retrieval phase transforms raw data into highly relevant financial insights using an Agentic-RAG framework powered by LangGraph. This hybrid system integrates specialized agents, ensuring accuracy, efficiency, and adaptability in financial due diligence.
[1\. Intelligent Document Retrieval](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_1-intelligent-document-retrieval)
-------------------------------------------------------------------------------------------------------------------------------------------
The process begins by retrieving the most contextually relevant financial documents from the Pathway Live Data Framework Vector Store. FA3STER enhances transparency by preserving metadata, ensuring users can track the source and reliability of retrieved data.
[2\. Smart Document Grading & Routing](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_2-smart-document-grading-routing)
---------------------------------------------------------------------------------------------------------------------------------------------
Retrieved documents undergo automated evaluation based on:
* **Relevance & Quality** – Ensuring only high-value data is processed.
* **Content-Type Detection** – Routing subqueries based on document type:
* Transform Query Agent – Refines unclear queries for better results.
* SQL Agent – Extracts structured financial data from databases.
* Finance Agent – Analyzes market trends, stock performance, and key financial metrics.
* Generate Node – If documents fully answer the query, they proceed to final output generation.
[3\. Real-Time Web Search for External Insights](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_3-real-time-web-search-for-external-insights)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------
When internal data is insufficient, FA3STER utilizes Tavily Search to fetch real-time financial insights from external sources. If results lack precision, the Finance Agent cross-verifies retrieved data and refines the response.
[4\. Financial Data Interpretation & Visualization](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_4-financial-data-interpretation-visualization)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------
* **Reasoning Agent** – Converts financial data into statistical graphs and trend visualizations, making insights actionable and easier to interpret.
[5\. Fact-Checked Response Generation](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_5-fact-checked-response-generation)
-----------------------------------------------------------------------------------------------------------------------------------------------
* **Fact Verification Agent** – Ensures coherence and eliminates inconsistencies before final output.
* **Aggregator Agent** – Merges multiple subquery responses into a single, well-structured report.
[Vertical Autonomous Layer:](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#vertical-autonomous-layer)
---------------------------------------------------------------------------------------------------------------------------

[Revolutionizing Due Diligence with Vertical Scaling](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#revolutionizing-due-diligence-with-vertical-scaling)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Instead of expanding FA3STER horizontally, we introduced a Vertical Autonomous Layer—a self-optimizing intelligence layer that enhances speed, accuracy, and efficiency in financial due diligence. This layer generates a concise FDD report in 10–12 minutes, offering stakeholders a quick yet highly detailed financial assessment. With a processing cost of only ₹15–₹20 ($0.20–$0.25) per report, FA3STER ensures affordable and scalable automation.
[Key Components of the Autonomous Layer](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#key-components-of-the-autonomous-layer)
----------------------------------------------------------------------------------------------------------------------------------------------------
* **Key Metrics Agent** – Analyzes revenue, profit margins, and growth rates to assess financial health.
* **Business Agent** – Evaluates market conditions, competitive positioning, and risk factors.
* **Executive Agent** – Assesses governance, compliance, and long-term strategic alignment.
[How FA3STER’s Autonomous Layer Works](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#how-fa3sters-autonomous-layer-works)
-----------------------------------------------------------------------------------------------------------------------------------------------
FA3STER’s agents operate in two iterative modes:
1. **Q&A Mode** – Agents generate domain-specific financial queries, retrieving insights using the RAG system.
2. **Discussion Mode** – Agents collaborate, refine findings, and generate new investigative questions to enhance financial accuracy.
The cycle repeats until the majority of agents agree on the accuracy and completeness of the analysis. The final Quick Overview Panel displays summarized insights, making it easy for stakeholders to interact with key financial data instantly.
[Results and Metrics](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#results-and-metrics)
--------------------------------------------------------------------------------------------------------------
For evaluation, we use 2 datasets:
* [FinQABench](https://huggingface.co/datasets/lighthouzai/finqabench)
:
* Based on Apple’s 2022 10K SEC filing, containing 100 test cases with financial queries and expected responses.
* Used to assess accuracy, hallucination prevention, and response quality in financial AI systems.
We compared the performance of the following workflows on this dataset:
* Naive RAG without Agentic Contextual Chunking
* Naive RAG with Agentic Contextual Chunking
| Workflow | Context Precision | Context Recall | Response Relevancy | Faithfulness | Factual Correctness |
| --- | --- | --- | --- | --- | --- |
| Naive RAG with Agentic Chunking | 0.904 | 0.849 | 0.928 | 0.901 | 0.518 |
| Naive RAG without Agentic Chunking | 0.801 | 0.782 | 0.883 | 0.828 | 0.449 |
It is clear from the results that the performance is enhanced by Agentic Chunking.
* [SEC 10-Q dataset](https://github.com/docugami/KG-RAG-datasets/tree/main/sec-10-q)
:
* Includes four AAPL 10-Q filings and 39 complex financial queries requiring multi-step reasoning.
* Designed to stress-test retrieval-augmented generation (RAG) models for multi-document financial analysis.
Here, we compared the following workflows:
* OpenParser with Self-RAG [\[3\]](https://arxiv.org/abs/2310.11511)
* OpenParser with Naive-RAG
* Our Post-Retrieval Agentic Workflow with Contextual Chunking
* Unstructured Parser with Naive-RAG
* Unstructured Parser with Self-RAG
It can be observed that Our Post-Retrieval Agentic Workflow with Contextual Chunking outperforms other methods by a significant margin. This shows the efficiency and enhanced performance of our Post-Retrieval Agentic Workflow on datasets which require reasoning over multiple documents in order to answer queries. In particular, improved Factual Correctness and Faithfulness are much needed in Financial Due Diligence, as it indicates that hallucination is minimized and information is preserved.
The following metrics from **RAGAS** [\[2\]](https://arxiv.org/abs/2309.15217)
were used for evaluation:
1. **[Context Precision](https://docs.ragas.io/en/stable/concepts/metrics/available_metrics/context_precision/)
**: Measures how many retrieved chunks are relevant to the query. Higher is better.
2. **[Context Recall](https://docs.ragas.io/en/stable/concepts/metrics/available_metrics/context_recall/)
**: Assesses the proportion of relevant documents successfully retrieved
3. **[Response Relevancy](https://docs.ragas.io/en/stable/concepts/metrics/available_metrics/answer_relevance/)
**: Evaluates how well the generated answer matches the query intent.
4. **[Faithfulness](https://docs.ragas.io/en/stable/concepts/metrics/available_metrics/faithfulness/)
**: Ensures responses remain factually consistent with retrieved data.
5. **[Factual Correctness](https://docs.ragas.io/en/stable/concepts/metrics/available_metrics/factual_correctness/)
**: Compares answers to ground truth financial data for accuracy.
| Workflow | Context Precision | Context Recall | Response Relevancy | Faithfulness | Factual Correctness |
| --- | --- | --- | --- | --- | --- |
| OpenParser with Self-RAG | 0.524 | 0.272 | 0.364 | 0.659 | 0.280 |
| OpenParser with Naive-RAG | 0.521 | 0.253 | 0.374 | 0.623 | 0.273 |
| Unstructured Parser with Self-RAG | 0.499 | 0.259 | 0.269 | 0.596 | 0.269 |
| Unstructured Parser with Naive-RAG | 0.524 | 0.313 | 0.319 | 0.503 | 0.276 |
| Our Workflow | 0.690 | 0.396 | 0.701 | 0.788 | 0.384 |
[Resilience to Error Handling:](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#resilience-to-error-handling)
---------------------------------------------------------------------------------------------------------------------------------
Our Financial Agentic RAG system incorporates robust error management, ensuring uninterrupted functionality. This enhances resilience by enabling quick recovery from failures, rapid error identification, and timely debugging and resolution.
**Tool-Specific Fallbacks**: Key tools have designated backups, such as web search stepping in for API failures or alternative tools in the Finance Agent. For example: When the relevant data is not retrieved from the primary data source, Finance Agent falls back to tools like Tavily and if that too fails, it falls back to open source web searches like duck duck go, further fallback details have been mentioned in the appendix.
**Error Handling**: Nested try and except blocks to manage failures effectively. Fallback Mechanisms, extensive logging is implemented to ensure traceability. When a fallback is triggered, the callback function raises a warning to facilitate tracking and debugging.
**Avoiding Exponential Back-Off**: Excluded exponential back-off to maintain query speed, as most tool failures were observed to be binary.
[Seamless User Experience with Dual-Mode Interface](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#seamless-user-experience-with-dual-mode-interface)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------
FA3STER provides an intuitive, transparent, and data-driven interface designed for financial professionals, analysts, and investors. Users can switch between two core modes for flexibility and depth in financial analysis.
### [1\. Chat Mode: Interactive Financial Query Resolution](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_1-chat-mode-interactive-financial-query-resolution)
* Users can ask real-time financial questions, and FA3STER generates accurate, data-backed responses.
* Built on the Pathway Live Data Framework’s infrastructure, the system provides a clear, step-by-step breakdown of how each response is generated by live streaming the agentic flow.
* Offers full transparency, allowing users to track how financial insights are derived.
### [2\. Report Generation Mode: Automated Due Diligence Reports](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#_2-report-generation-mode-automated-due-diligence-reports)
* Users enter a company’s name, and FA3STER’s Agentic RAG framework autonomously retrieves and processes financial data.
* Generates concise yet detailed FDD reports, summarizing key financial insights such as:
* Revenue shares
* Global market penetration
* Key financial performance indicators
* The Next.js-powered UI & websockets ensures real-time visibility into agent activity.
* The final report is saved locally, while an interactive dashboard visualizes insights for strategic decision-making.

[Responsible AI: Security, Compliance & Transparency](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#responsible-ai-security-compliance-transparency)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------
Our AI architecture incorporates robust guardrails to ensure secure, ethical, and compliant interactions. These safeguards block irrelevant queries, including defamation, privacy violations, hate speech, and intellectual property concerns, upholding privacy and ethical standards.
**Llamaguard’s Safety guardrail** [\[4\]](https://arxiv.org/abs/2312.06674)
:
* Powered by Llama-3.1 8B, Llamaguard classifies queries as safe or unsafe.
* Detects 14 predefined risk categories (e.g., privacy violations, hate speech, defamation).
* Ensures secure and compliance-driven user interactions.
**PII Guardrail** [\[5\]](https://www.guardrailsai.com/docs/examples/check_for_pii)
:
* Initially explored Guardrail.ai with Presidio Analyzer & Anonymizer for PII detection.
* Found the approach unnecessary and resource-intensive, leading to its removal for workflow optimization.
**Transparency through Socket Communication**:
* FA3STER’s backend and frontend are connected via socket communication to track query execution in real time.
* Every query’s processing path is logged and visually represented, giving users a clear, step-by-step breakdown of data flow.
* Enhances trust, explainability, and system reliability.
[Conclusion: Transforming Financial Due Diligence with FA3STER](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#conclusion-transforming-financial-due-diligence-with-fa3ster)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
FA3STER redefines financial due diligence by combining the Pathway Live Data Framework’s dynamic capabilities with an agentic RAG architecture. Through intelligent document retrieval, contextual chunking, and autonomous multi-agent processing, it delivers highly accurate, efficient, and scalable financial insights.
Rigorous testing confirms FA3STER’s superior performance over traditional RAG systems, minimizing errors while enhancing speed, transparency, and reliability. By leveraging the Pathway Live Data Framework’s real-time streaming and indexing capabilities, FA3STER ensures seamless financial analysis, adapting to evolving datasets with unparalleled precision.
As AI-driven financial intelligence continues to evolve, FA3STER stands at the forefront—setting new standards for automation, accuracy, and decision-making in the financial sector.
If you are interested in diving deeper into the topic, here are some good references to get started with Pathway:
* [Pathway Live Data Framework Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
* [Pathway Live Data Framework App Templates](https://pathway.com/developers/templates)
* [Discord Community of Pathway](https://discord.gg/pathway)
* [Power and Deploy RAG Agent Tools with Pathway](https://pathway.com/blog/deploy-rag-agent-tools-with-pathway)
* [End-to-end Real-time RAG app with Pathway Live Data Framework Live Data Framework](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
[Authors:](https://pathway.com/framework/blog/ai-agents-finance-due-diligence#authors)
---------------------------------------------------------------------------------------
* [Rishikant Chigrupaatii](https://www.linkedin.com/in/rishikant-chigrupaatii-693230240)
* [Anurag Deo](https://www.linkedin.com/in/anurag-deo-8b30b422b)
* [Lalit Chandra Routhu](https://www.linkedin.com/in/lalit-chandra-routhu-3901aa225)
* [Vinayak Goyal](https://www.linkedin.com/in/vinayak-goyal-b769b5251)
* [Krishna Rathore](https://www.linkedin.com/in/kr005)
* [Bibhuti Jha](https://www.linkedin.com/in/bibhuti-jha-045195253)
* [Pratik Amrit](https://www.linkedin.com/in/pratik-amrit-2322a6287)
* [Satyam Sahoo](https://www.linkedin.com/in/satyam-sahoo-7b9786248)
* * *

Pathway Live Data Framework Community
Multiple authors
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Sajjad Nakhwa\
\
communityFeb 11, 2025\
\
How Text Embeddings help suggest similar words](https://pathway.com/framework/blog/how-text-embeddings-help-suggest-similar-words)
* [\
\
\
\
Zuzanna Stamirowska\
\
newsFeb 9, 2024\
\
How Businesses Can Create Data Frameworks for Real-world AI](https://pathway.com/news/cdo-magazine)
* [\
\
\
\
Financial Times\
\
newsAug 17, 2023\
\
Pathway quoted in the FT: The skeptical case on generative AI](https://pathway.com/news/financial-times-skeptical-case)
[Blog\
\
Adaptive Agents for Real-Time RAG: Domain-Specific AI for Legal, Finance & Healthcare](https://pathway.com/framework/blog/adaptive-agents-rag)
[Blog\
\
Financial Report Analysis with LiveAI™](https://pathway.com/framework/blog/ai-financial-report-analysis)
---
# LiveAI™ for SEC Filings Analysis | Pathway
Table of Contents
[Introduction](https://pathway.com/framework/blog/ai-for-sec-filings#introduction)
-----------------------------------------------------------------------------------
When finance professionals spend hours digging through dense SEC filings, it’s clear we need better tools, enter AI for SEC filings.
> _The average annual report filed with the SEC (Form 10-K) exceeds 150 pages and contains thousands of data points, making manual analysis both time-consuming and error-prone._
Our team tackled this challenge head-on by developing a sophisticated LiveAI™ for SEC Filings system powered by multi-agent RAG (Retrieval-Augmented Generation)—transforming how financial documents are analyzed and understood in real time.
The result? A system that achieved 56% accuracy on FinanceBench, one of the most challenging evaluation datasets for financial document analysis significantly outperforming the baseline 19% accuracy reported for GPT-4 Turbo.
[The Challenge: Why Traditional RAG Fails on SEC Filings](https://pathway.com/framework/blog/ai-for-sec-filings#the-challenge-why-traditional-rag-fails-on-sec-filings)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------
SEC filings present unique challenges that break traditional RAG systems. Each page contains dense, tabular data that appears nearly identical to embedding models, causing similarity search to fail catastrophically. Even exact matching algorithms like [BM25](https://en.wikipedia.org/wiki/Okapi_BM25)
struggle when dealing with multiple companies' filings in a single index.
Consider this scenario: a finance professional needs to compare revenue growth across three different companies from their 10-K filings. Traditional systems would either:
* Return irrelevant chunks due to poor similarity matching
* Miss critical data buried in complex tables
* Fail to perform the mathematical calculations needed for comparison
Our multi-agent approach solves these fundamental limitations through intelligent architecture design and data enrichment strategies.
### [Enter the Multi-Agent Financial Document Analyzer](https://pathway.com/framework/blog/ai-for-sec-filings#enter-the-multi-agent-financial-document-analyzer)
Built on a sophisticated **Supervisor-Agent architecture** with dynamic RAG enhancement and mathematical computation capabilities, this system transforms traditional document analysis:
* **56% accuracy on FinanceBench ([Arxiv Paper](https://arxiv.org/abs/2311.11944)
)** - dramatically outperforming GPT-4 Turbo's 19% baseline
* **Intelligent data enrichment** that solves the similarity search problem plaguing dense financial tables
* **Expert reasoning simulation** with specialized financial personas (Risk Management, Market Sentiment, Fundamental Analysis)
* **Mathematical computation agent** ensuring calculation accuracy that LLMs typically fail at
* **Built on the Pathway Live Data Framework’s LiveAI™ infrastructure** - every new SEC filing is processed and indexed in real-time, turning traditional research bottlenecks into instantly accessible insights.
### [System Demonstration: LiveAI™ for SEC Filings Analysis](https://pathway.com/framework/blog/ai-for-sec-filings#system-demonstration-liveai-for-sec-filings-analysis)
**Video Walkthrough - Complete System in Action**
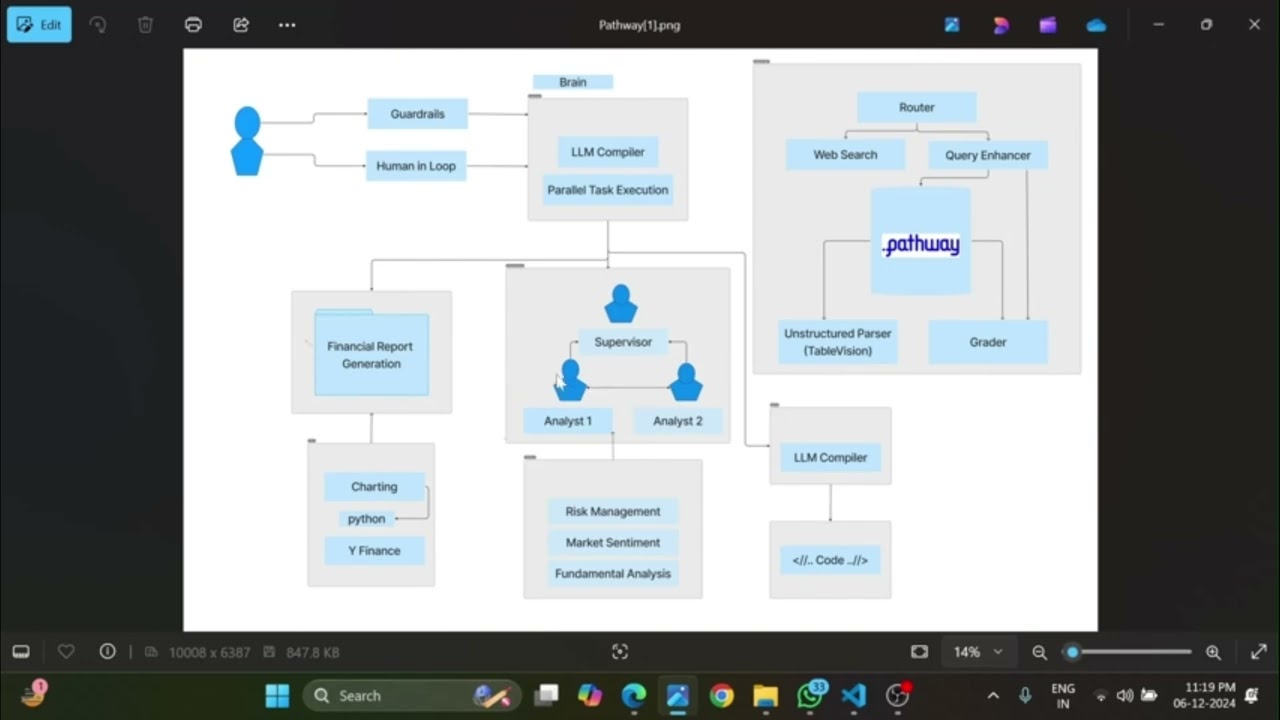
**Code Repository - Complete Setup & Usage Guide**
[\
\
Multi-Agent RAG System for Financial DocumentsGitHub](https://github.com/alankritkadian/pathway_rag)
[Architecture Deep Dive: Supervisor With Agents as Tools](https://pathway.com/framework/blog/ai-for-sec-filings#architecture-deep-dive-supervisor-with-agents-as-tools)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [Why We Chose This Architecture](https://pathway.com/framework/blog/ai-for-sec-filings#why-we-chose-this-architecture)
After evaluating multiple multi-agent architectures including fully connected networks, hierarchical systems, and custom topologies, we selected the "Supervisor with Agents as Tools" approach with an even more modified version inspired by the [LLM Compiler paper](https://arxiv.org/abs/2312.04511)
.
This architecture provides three critical advantages:
* **Context Separation**: Each agent maintains its own context, preventing the supervisor from getting overwhelmed by individual task details while focusing on the bigger picture.
* **Parallel Execution**: The supervisor can call multiple agent tools simultaneously, dramatically reducing processing time for complex queries.
* **Token Efficiency**: This approach requires fewer total tokens compared to other multi-agent architectures, making it more cost-effective at scale.
### [The LLM Compiler Enhancement](https://pathway.com/framework/blog/ai-for-sec-filings#the-llm-compiler-enhancement)
Our implementation incorporates the LLM Compiler's innovation of concurrent function calling using a directed acyclic graph. This creates execution plans with built-in routing logic, allowing for truly intelligent task orchestration.
[Dynamic RAG Pipeline: Solving Key Challenges in AI for SEC Filings](https://pathway.com/framework/blog/ai-for-sec-filings#dynamic-rag-pipeline-solving-key-challenges-in-ai-for-sec-filings)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
### [The Data Enrichment Strategy](https://pathway.com/framework/blog/ai-for-sec-filings#the-data-enrichment-strategy)
Raw SEC filing chunks are information-dense but retrieval-unfriendly. Our solution enriches each chunk with three key components:
1. **Contextual Descriptions**: LLM-generated summaries that include context from surrounding chunks
2. **Markdown Formatting**: Enhanced readability for both humans and AI systems
3. **Search Query Generation**: Relevant queries derived from table content to improve discoverability
4. **MetaData Inclusion**: Included metadata such as document type, year, company name etc for metadata filtering.
This was possible using the support of [unstructured parser](https://pathway.com/developers/api-docs/pathway-xpacks-llm/parsers#pathway.xpacks.llm.parsers.UnstructuredParser)
supported by the framework’s retrievers.
Here's what this enrichment process achieves:

**Before Enrichment**: A raw table with quarterly revenue figures **After Enrichment**: The same table plus a natural language description explaining revenue trends, formatted in readable markdown, with associated search terms like "quarterly revenue growth Q3 2023"
### [Advanced Retrieval Capabilities](https://pathway.com/framework/blog/ai-for-sec-filings#advanced-retrieval-capabilities)

Our RAG agent incorporates several sophisticated features:
* **Multi-query Decomposition**: Breaking complex questions into retrievable sub-queries
* **Web Search Integration**: Accessing real-time market data when needed
* **Grading and Reranking**: Quality assessment of retrieved content
* **Retry Logic**: Intelligent decision-making on when to retry retrieval
The agent makes autonomous decisions about data quality and retrieval success, ensuring the supervisor receives only relevant, high-quality information.
### [The Pathway Live Data Framework: The Infrastructure Foundation](https://pathway.com/framework/blog/ai-for-sec-filings#the-pathway-live-data-framework-the-infrastructure-foundation)
Our dynamic RAG pipeline's success relied heavily on the Pathway Live Data Framework serving as the LiveAI™ layer that handled enterprise-scale data integration and retrieval optimization.
**Seamless Data Integration**: [The framework's Google Drive connector](https://pathway.com/developers/user-guide/connect/connectors/gdrive-connector)
eliminated traditional data pipeline complexity, automatically ingesting new SEC filings and regulatory documents without manual intervention. This plug-and-play integration allowed us to focus on multi-agent orchestration rather than data management.
**Hybrid Retrieval Enhancement**: Beyond our data enrichment strategy, we leveraged the framework's built-in hybrid search combining vector similarity with BM25 keyword matching. This proved crucial for financial documents filled with domain-specific jargon, stock tickers, and regulatory codes that embedding models often under-emphasize. We configured BM25 with a 0.6 weight alongside semantic search, ensuring exact financial terms weren't lost while maintaining contextual relevance.
**Advanced Metadata Filtering**: The framework's out-of-the-box metadata filtering capabilities allowed our agents to narrow search scope rapidly:
* Company-specific queries by ticker symbol
* Time-based filtering for specific quarters or fiscal years
* Document type restrictions (10-K vs. 8-K reports)
* Regulatory section targeting for specific disclosures
These filters operate at the vector store level, dramatically reducing search space before similarity calculations and improving both response time and result relevance.
**Performance at Scale**: The optimized Rust backend ensured consistently low latency even when multiple agents queried simultaneously, supporting our concurrent execution architecture while maintaining the token efficiency that made our supervisor-agent approach cost-effective.

[Specialized Agent Tools: Beyond Simple Retrieval](https://pathway.com/framework/blog/ai-for-sec-filings#specialized-agent-tools-beyond-simple-retrieval)
----------------------------------------------------------------------------------------------------------------------------------------------------------
### [The Mathematical Computation Agent](https://pathway.com/framework/blog/ai-for-sec-filings#the-mathematical-computation-agent)
Financial analysis requires precise calculations that LLMs often get wrong. Our mathematical agent uses code interpreter capabilities to:
* Determine whether calculations should be performed in LLM memory or through code execution
* Handle large-scale data processing with accuracy
* Provide step-by-step calculation breakdowns for transparency
This agent bridges the gap between data retrieval and actionable financial insights.

### [The Expert Reasoning Group: Domain-Adaptive Professional Simulation](https://pathway.com/framework/blog/ai-for-sec-filings#the-expert-reasoning-group-domain-adaptive-professional-simulation)
One of our most innovative and transferable tools simulates conversations between domain experts with different specializations. For financial analysis, this includes:
* **Risk Management Analysts**: Assess potential downsides and regulatory concerns
* **Market Sentiment Experts**: Evaluate investor perception and market positioning
* **Fundamental Analysts**: Deep-dive into company fundamentals and valuation metrics
These personas engage in structured dialogues using retrieved data, mimicking how real professional teams collaborate on complex decisions. This approach leverages the same reasoning principles that make modern LLMs more effective generating extensive intermediate reasoning before reaching conclusions.
**The beauty of this system lies in its adaptability**. The expert personas are easily configurable, making the entire framework transferable to virtually any professional domain requiring complex document analysis and multi-perspective reasoning.

### [Rapid Report Generation](https://pathway.com/framework/blog/ai-for-sec-filings#rapid-report-generation)
For time-pressed professionals, our system includes a report generation tool that creates concise, two-page company summaries. These reports distill key financial metrics, recent performance, and risk factors into actionable insights.
### [Complete System Architecture](https://pathway.com/framework/blog/ai-for-sec-filings#complete-system-architecture)
Now that we've covered each component, the diagram above shows how all pieces work together from initial document ingestion through the enriched RAG pipeline, mathematical processing, expert reasoning simulation, and final report generation.

[Performance Results: FinanceBench Evaluation](https://pathway.com/framework/blog/ai-for-sec-filings#performance-results-financebench-evaluation)
--------------------------------------------------------------------------------------------------------------------------------------------------
We tested our system against [FinanceBench](https://financebench.github.io/)
, one of the most challenging benchmarks for financial document analysis:
* **Baseline (Simple RAG)**: 24% accuracy
* **With Data Enrichment**: 36% accuracy
* **Complete Multi-Agent Pipeline**: 42% accuracy
* **Human-in-the-Loop Integration**: 56% accuracy
The human-in-the-loop component allows for clarification requests, significantly boosting accuracy for ambiguous queries while maintaining system autonomy for straightforward tasks.

[Implementation Insights and Lessons Learned](https://pathway.com/framework/blog/ai-for-sec-filings#implementation-insights-and-lessons-learned)
-------------------------------------------------------------------------------------------------------------------------------------------------
### [Data Processing at Scale](https://pathway.com/framework/blog/ai-for-sec-filings#data-processing-at-scale)
We leveraged the Pathway Live Data Framework's Google Drive connector for seamless data ingestion, allowing real-time processing of large volumes of unstructured financial documents. The plug-and-play nature of this integration eliminated traditional data pipeline complexity.
### [Guardrails and Safety](https://pathway.com/framework/blog/ai-for-sec-filings#guardrails-and-safety)
Input validation includes:
* Content sanitization
* Personally Identifiable Information (PII) detection
* Jailbreak attempt prevention through vector matching
Since SEC filings are public documents, we focused guardrails on user inputs rather than retrieved content.
### [Performance Optimization](https://pathway.com/framework/blog/ai-for-sec-filings#performance-optimization)
Key optimizations that improved system performance:
1. **Chunk Size Tuning**: Optimizing for both context preservation and retrieval accuracy
2. **Embedding Model Selection**: Testing multiple models for financial document understanding
3. **Concurrent Processing**: Maximizing parallel execution opportunities
4. **Cache Strategy**: Implementing intelligent caching for frequently accessed data
[Beyond Finance: Universal Applicability of Multi-Agent RAG](https://pathway.com/framework/blog/ai-for-sec-filings#beyond-finance-universal-applicability-of-multi-agent-rag)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
While this system was purpose-built as an AI for SEC filings analysis system, the architecture's components are inherently domain-agnostic. The power of our multi-agent approach lies in its modularity; each component can be adapted to different professional fields without fundamental architectural changes.
### [Core Components That Transfer Across Domains](https://pathway.com/framework/blog/ai-for-sec-filings#core-components-that-transfer-across-domains)
**Dynamic RAG Pipeline**: The data enrichment strategy works for any document type with dense, structured information. Legal contracts, medical research papers, engineering specifications all benefit from contextual descriptions and improved retrievability.
**Mathematical Computation Agent**: Any field requiring precise calculations can leverage this component. Engineering calculations, statistical analysis in research, or financial modeling in accounting all utilize the same code interpreter capabilities.
**Expert Reasoning Simulation**: Perhaps the most adaptable component, the multi-persona reasoning system can be reconfigured for any professional domain by simply changing the expert roles and their specialized knowledge areas.
### [Case Study: Adapting for Legal Document Analysis](https://pathway.com/framework/blog/ai-for-sec-filings#case-study-adapting-for-legal-document-analysis)
Consider how easily our financial system transforms for legal applications:
**Original Financial Personas:**
* Risk Management Analyst
* Market Sentiment Expert
* Fundamental Analyst
**Legal Domain Adaptation:**
* **Constitutional Law Expert**: Analyzes constitutional implications and precedent alignment
* **Contract Specialist**: Focuses on clause interpretation, liability assessment, and enforceability
* **Litigation Strategist**: Evaluates case strength, procedural considerations, and potential outcomes
The system would analyze legal documents (contracts, case law, regulatory filings) using the same retrieval and enrichment strategies, but with legal-specific reasoning patterns. For example, when analyzing a complex merger agreement, the three legal personas might debate:
* **Constitutional Expert**: "The interstate commerce implications here require careful consideration of federal vs. state jurisdiction..."
* **Contract Specialist**: "The indemnification clauses in Section 8.3 create asymmetric risk exposure that favors the acquirer..."
* **Litigation Strategist**: "If this deal faces regulatory challenge, the antitrust arguments in the Hart-Scott-Rodino filing suggest a 60% probability of approval..."
### [Other Domain Applications](https://pathway.com/framework/blog/ai-for-sec-filings#other-domain-applications)
**Healthcare/Medical Research:**
* Clinical Research Specialist
* Regulatory Affairs Expert
* Patient Safety Analyst
**Engineering/Technical Documentation:**
* Systems Architecture Expert
* Safety Compliance Engineer
* Performance Optimization Specialist
**Academic Research:**
* Methodology Expert
* Statistical Analysis Specialist
* Peer Review Evaluator
The mathematical agent adapts to domain-specific calculations (statistical analysis for research, safety factor calculations for engineering), while the RAG pipeline handles field-specific document structures and terminology.
* **Due Diligence**: Rapidly analyzing multiple companies' financial health for investment decisions
* **Regulatory Compliance**: Tracking changes in financial reporting requirements across filings
* **Competitive Analysis**: Comparing key metrics and strategies across industry competitors
* **Risk Assessment**: Identifying potential red flags in financial statements and disclosures
[Technical Architecture Considerations](https://pathway.com/framework/blog/ai-for-sec-filings#technical-architecture-considerations)
-------------------------------------------------------------------------------------------------------------------------------------
### [Scalability Design](https://pathway.com/framework/blog/ai-for-sec-filings#scalability-design)
The system scales horizontally through:
* Independent agent processing
* Distributed vector storage
* Load-balanced API endpoints
* Asynchronous task processing
### [Integration Capabilities](https://pathway.com/framework/blog/ai-for-sec-filings#integration-capabilities)
Built with enterprise integration in mind:
* RESTful API interfaces
* Webhook support for real-time updates
* SSO authentication compatibility
* Audit logging and compliance tracking
[Future Enhancements and Roadmap](https://pathway.com/framework/blog/ai-for-sec-filings#future-enhancements-and-roadmap)
-------------------------------------------------------------------------------------------------------------------------
Current development focuses on:
1. **Multi-Modal Analysis**: Incorporating chart and graph analysis from financial documents
2. **Temporal Reasoning**: Better understanding of time-series financial data
3. **Regulatory Updates**: Automatic adaptation to changing financial reporting standards
4. **Industry Specialization**: Custom models for specific financial sectors
[Getting Started With Multi-Agent RAG Systems](https://pathway.com/framework/blog/ai-for-sec-filings#getting-started-with-multi-agent-rag-systems)
---------------------------------------------------------------------------------------------------------------------------------------------------
If you're considering building similar systems for any professional domain, here are key takeaways:
* **Start Simple**: Begin with a basic supervisor-agent architecture before adding complexity
* **Focus on Data Quality**: Invest heavily in data enrichment and preprocessing this principle applies whether you're working with financial statements or legal contracts
* **Domain Expertise Configuration**: Identify the key professional perspectives in your field and configure expert personas accordingly
* **Measure Everything**: Establish clear metrics and evaluation datasets early, tailored to your specific domain requirements
* **Plan for Scale**: Design with horizontal scaling and distributed processing in mind
* **User Experience Matters**: Balance automation with human oversight capabilities
* **Cross-Domain Thinking**: Consider how components might be reused or adapted for related professional fields
[Conclusion: Advancing AI for SEC Filings](https://pathway.com/framework/blog/ai-for-sec-filings#conclusion-advancing-ai-for-sec-filings)
------------------------------------------------------------------------------------------------------------------------------------------
Our multi-agent AI for SEC filings system demonstrates that complex document analysis can be significantly improved through thoughtful architecture design and specialized agent capabilities not just for finance, but across any professional domain requiring deep document understanding and expert reasoning.
By achieving 56% accuracy on challenging financial benchmarks, we've proven that AI can genuinely augment professional capabilities rather than simply replacing manual processes. The system's modular design means these benefits can extend to legal professionals analyzing contracts, medical researchers reviewing literature, or engineers evaluating technical specifications.
The combination of intelligent retrieval, domain-specific computation, and expert reasoning simulation creates a powerful template for professional document analysis tools. As organizations across industries grapple with information overload, this multi-agent approach offers a scalable solution that adapts to sector-specific needs while maintaining high performance standards.
If you are interested in diving deeper into the topic, here are some good references to get started with Pathway:
* [Pathway Live Data Framework Developer Documentation](https://pathway.com/developers/user-guide/introduction/welcome)
* [Pathway Live Data Framework's Ready-to-run App Templates](https://pathway.com/developers/templates)
* [End-to-end Real-time RAG app with Pathway Live Data Framework Live Data Framework](https://github.com/pathwaycom/llm-app/tree/main/templates/question_answering_rag)
* [Discord Community](https://discord.gg/pathway)
* * *
[Frequently Asked Questions](https://pathway.com/framework/blog/ai-for-sec-filings#frequently-asked-questions)
---------------------------------------------------------------------------------------------------------------
What makes this AI for SEC filings solution different from others?
Our multi-agent system solves core issues like table parsing, financial reasoning, and cross-document comparison.
How easily can this system be adapted to other professional domains?
Very easily. The core components are domain-agnostic; only the expert personas and domain-specific terminology need adjustment. We estimate 2-3 weeks for full adaptation to a new field like legal or medical document analysis.
What types of documents work best with this architecture?
Any structured, information-dense documents benefit most financial filings, legal contracts, technical specifications, research papers, or regulatory documents.
How does this compare to existing financial AI tools?
Our multi-agent approach specifically addresses the limitations of single-model systems when dealing with complex, multi-step financial analysis requiring both retrieval and computation.
What types of financial documents can the system analyze?
Currently optimized for SEC filings (10-K, 10-Q, 8-K), with plans to expand to earnings reports, analyst notes, and regulatory submissions.
How accurate is the mathematical computation component?
The code interpreter approach achieves near-perfect accuracy for computational tasks, unlike LLM-only calculations which can introduce errors.
Can the system handle real-time market data?
Yes, through web search integration, though the primary focus remains on structured document analysis rather than live market feeds.
What's required for implementation in an enterprise environment?
Standard enterprise requirements: API access, secure data handling, user authentication, and integration with existing workflow tools.
[Authors](https://pathway.com/framework/blog/ai-for-sec-filings#authors)
-------------------------------------------------------------------------
* [Yugam Bhatt](https://www.linkedin.com/in/yugam-bhatt-062591257)
* [Alankrit Kadian](https://www.linkedin.com/in/alankrit-kadian-a848a623a)
* [Devanshu Dhawan](https://www.linkedin.com/in/devanshu-dhawan-914a64236)
* [Anushtha Prakash](https://www.linkedin.com/in/anushtha-prakash-4a4848226)
* [Harsh Rai](https://www.linkedin.com/in/harsh-rai-8a2446288)
* [Vrushank Ahire](https://www.linkedin.com/in/vrushank-ahire)
* [Akash Jangid](https://www.linkedin.com/in/akash-jangid-617134279)
* [Sumit Bahl](https://www.linkedin.com/in/sumitbahl)
* * *

Pathway Live Data Framework Community
Multiple authors
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
Sajjad Nakhwa\
\
communityFeb 11, 2025\
\
How Text Embeddings help suggest similar words](https://pathway.com/framework/blog/how-text-embeddings-help-suggest-similar-words)
* [in French\
\
\
\
\
\
Paris-Saclay\
\
newsMay 15, 2023\
\
Interview for Paris-Saclay](https://pathway.com/news/paris-saclay)
* [\
\
\
\
Pathway Team\
\
researchNov 30, 2025\
\
Benchmarks: Fundamental Unlocks for AI](https://pathway.com/#benchmarks)
[Blog\
\
Financial Report Analysis with LiveAI™](https://pathway.com/framework/blog/ai-financial-report-analysis)
[Blog\
\
AI Paper Reviewer | LiveAI™ for Conference Classification](https://pathway.com/framework/blog/ai-paper-reviewer)
---
# Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason
2023
Jun
Oct
Nov
2024
Jan
Mar
Apr
May
Jul
Sep
Oct
Nov
Dec
2025
Feb
Mar
Apr
Oct
Dec
2026
Jan
Feb
Mar
Apr
May
Sep
Oct
Upcoming events
---------------
23/06/2023
Save to calendar

Jun232023
[FCRC 2023\
=========](https://pathway.com/events/fcrc-2023)
Federated Computing Research Conference
Friday, June 23 about 3 years ago
Orlando World Marriott, Orlando, Florida[8701 World Center Dr, Orlando, FL 32821, United States](https://www.google.com/maps/search/8701%20World%20Center%20Dr%2C%20Orlando%2C%20FL%2032821%2C%20United%20States)
[Read More](https://pathway.com/events/fcrc-2023)
05/10/2023
Save to calendar

Oct052023
[Sifted Summit\
=============](https://pathway.com/events/sifted-summit-2023)
The Best event of Big Data and Artificial Intelligence in France
Thursday, October 5 almost 3 years ago
Magazine London[11 Ordnance Cres London SE10 0JH](https://www.google.com/maps/search/11%20Ordnance%20Cres%20London%20SE10%200JH)
[Read More](https://pathway.com/events/sifted-summit-2023)
29/10/2023
Save to calendar

Oct292023
[ML in PL\
========](https://pathway.com/events/ml-in-pl-2023)
7th edition of an annual conference focused on the best of Machine Learning both in academia and in business.
Sunday, October 29 over 2 years ago
Koszykowa 75, 00-662 Warsaw[Faculty of mathematics and information science, Warsaw University of Technology, Koszykowa 75, 00-662 Warszawa](https://www.google.com/maps/search/Faculty%20of%20mathematics%20and%20information%20science%2C%20Warsaw%20University%20of%20Technology%2C%20Koszykowa%2075%2C%2000-662%20Warszawa)
[Read More](https://pathway.com/events/ml-in-pl-2023)
02/11/2023
Save to calendar

Nov022023
[Fireside Chat with Jan Chorowski\
================================](https://pathway.com/events/jan-fireside-chat)
Exploring the Frontiers of Large Language Models
Thursday, November 2 over 2 years ago
Online
[Read More](https://pathway.com/events/jan-fireside-chat)
29/11/2023
Save to calendar

Nov292023
[Ask Me Anything with Pathway CEO Zuzanna Stamirowska at Women’s forum Global Meeting\
====================================================================================](https://pathway.com/events/womens-forum-global-meeting)
International network for transforming the power of women's voices and perspectives into forward-thinking economic and policy initiatives for societal change
Wednesday, November 29 over 2 years ago
Palais Brongniart, France[16 Pl. de la Bourse, 75002 Paris](https://www.google.com/maps/search/16%20Pl.%20de%20la%20Bourse%2C%2075002%20Paris)
[Read More](https://pathway.com/events/womens-forum-global-meeting)
31/01/2024
Save to calendar

Jan312024
[\[In French\] Client Testimonial: La Poste at Modern Data Stack\
===============================================================](https://pathway.com/events/modern-data-stack)
DATANOSCO Conference, explore the future of the Modern Data Stack in the context of simplification, performance, and governance
Wednesday, January 31 over 2 years ago
Criteo Offices in paris, 32 rue Blanche – 75009 Paris[32 rue Blanche, 75009 Paris](https://www.google.com/maps/search/32%20rue%20Blanche%2C%2075009%20Paris)
[Read More](https://pathway.com/events/modern-data-stack)
02/03/2024
Save to calendar

Mar022024
[GPT with Realtime Data | National Science Day Keynote at IIT Kharagpur\
======================================================================](https://pathway.com/events/rag-intro-iitkgp-24)
Join us on March 2nd, 2024, for a keynote session by Mudit Srivastava at IIT Kharagpur. Explore the expansive world of LLMs like ChatGPT and their applications with real-time data
Saturday, March 2 over 2 years ago
IIT Kharagpur and Online[IIT Kharagpur, India, and Online](https://www.google.com/maps/search/IIT%20Kharagpur%2C%20India%2C%20and%20Online)
[Read More](https://pathway.com/events/rag-intro-iitkgp-24)
30/03/2024
Save to calendar

Mar302024
[Building LLMs and Realtime Apps Workshop at Tryst IIT Delhi\
===========================================================](https://pathway.com/events/realtime-and-llm-iitd24)
Join Pathway and DevClub IIT Delhi for an exclusive session with Prof Abhilash Jindal and Mudit Srivastava. Explore Large Language Models and Streaming insights
Saturday, March 30 over 2 years ago
IIT Delhi[IIT Delhi, India and Online](https://www.google.com/maps/search/IIT%20Delhi%2C%20India%20and%20Online)
[Read More](https://pathway.com/events/realtime-and-llm-iitd24)
11/04/2024
Save to calendar

Apr112024
[Make your LLM app sane again: Forgetting incorrect data in real time\
====================================================================](https://pathway.com/events/conf42-llm-sane-again-2024)
How to create an LLM-powered chatbot in Python from scratch with an up-to-date RAG mechanism. The chatbot will answer questions about your documents, updating its knowledge in real-time alongside the changes in the documentation, enabling the chatbot to filter out fake news.
Thursday, April 11 over 2 years ago
Online
[Read More](https://pathway.com/events/conf42-llm-sane-again-2024)
15/04/2024
Save to calendar

Apr152024
[Vision Transformers (ViTs) Masterclass at IIT Guwahati\
======================================================](https://pathway.com/events/vits-microsoft-24)
Join Pathway's 'Building Realtime LLM Apps' bootcamp for a live session on recent advances in computer vision with Dr. Vijay Srinivas Agneeswaran from Microsoft
Monday, April 15 over 2 years ago
Online
[Read More](https://pathway.com/events/vits-microsoft-24)
30/04/2024
Save to calendar

Apr302024
[LLMs + Smarter Search: The Future of RAG \[Register on Luma\]\
=============================================================](https://pathway.com/events/llms-smarter-search-the-future-of-rag)
This talk explores flexible retrieval approaches that let you optimize for accuracy, cost, and latency based on your specific use case.
Tuesday, April 30 about 2 years ago
MindsDB SF AI Collective[3154 17th St, San Francisco, CA 94110, United States](https://www.google.com/maps/search/3154%2017th%20St%2C%20San%20Francisco%2C%20CA%2094110%2C%20United%20States)
[Read More](https://pathway.com/events/llms-smarter-search-the-future-of-rag)
01/05/2024
Save to calendar

May012024
[Night of LLMs at UC Davis\
=========================](https://pathway.com/events/llms-uc-davis-24)
Join Pathway and GDSC UC Davis for an exclusive session with CTO Jan Chorowski. Explore Large Language Models and Data Streaming insights
Wednesday, May 1 about 2 years ago
Davis, California[UC Davis, California and Online](https://www.google.com/maps/search/UC%20Davis%2C%20California%20and%20Online)
[Read More](https://pathway.com/events/llms-uc-davis-24)
24/05/2024
Save to calendar

May242024
[Stream Data Processing: Today’s Landscape and Horizons\
======================================================](https://pathway.com/events/stream-data-processing-ama-iitb24)
Join Pathway, NPCI, Web & Coding Club, and IIT Bombay on May 24, 2024, for an exclusive AMA-style discussion with industry leaders. Explore Stream Data Processing insights
Friday, May 24 about 2 years ago
Online
[Read More](https://pathway.com/events/stream-data-processing-ama-iitb24)
22/07/2024
Save to calendar

Jul222024
[ICML 2024\
=========](https://pathway.com/events/icml-2024)
Monday - Saturday, July 22 - 27 about 2 years ago
Messe Wien Exhibition Congress Center[Messepl. 1, 1020 Wien, Austria](https://www.google.com/maps/search/Messepl.%201%2C%201020%20Wien%2C%20Austria)
[Read More](https://pathway.com/events/icml-2024)
17/09/2024
Save to calendar

Sep172024
[Intel AI Summit Paris\
=====================](https://pathway.com/events/intel-ai-summit-paris-2024)
Series of events to educate and inform developers and technology decision makers on how Intel’s software and hardware portfolios can help power your AI solutions and accelerate your AI journey at scale.
Tuesday, September 17 (17:00 BST) almost 2 years ago
Paris Trocadéro Business Center[Paris Trocadéro Business Center, 112 Avenue Kléber, 75116, Paris, France](https://www.google.com/maps/search/Paris%20Trocad%C3%A9ro%20Business%20Center%2C%20112%20Avenue%20Kl%C3%A9ber%2C%2075116%2C%20Paris%2C%20France)
[Read More](https://pathway.com/events/intel-ai-summit-paris-2024)
20/09/2024
Save to calendar

Sep202024
[Pathway StreamInk 2024, India\
=============================](https://pathway.com/events/pathway-blogathon)
Showcase skills and connect with the Data/AI community
Friday, September 20 almost 2 years ago
SteamInk[Online](https://www.google.com/maps/search/Online)
[Read More](https://pathway.com/events/pathway-blogathon)
22/09/2024
Save to calendar

Sep222024
[3-Hour Code Along RAG Workshop with GTech Mulearn\
=================================================](https://pathway.com/events/llm-crash-course-mulearn-24)
Join MuLearn and Pathway on September 22nd, 2024, for a 3-hour online code-along workshop with Saksham Goel. Build your first RAG application synced with dynamic data sources like Google Drive
Sunday, September 22 almost 2 years ago
Online
[Read More](https://pathway.com/events/llm-crash-course-mulearn-24)
20/10/2024
Save to calendar

Oct202024
[UC Davis Gen AI Founders Mix 2024\
=================================](https://pathway.com/events/gen-ai-uc-davis)
Sunday, October 20 almost 2 years ago
University of California, Davis[1 Shields Ave, Davis, CA 95616, United States](https://www.google.com/maps/search/1%20Shields%20Ave%2C%20Davis%2C%20CA%2095616%2C%20United%20States)
[Read More](https://pathway.com/events/gen-ai-uc-davis)
22/10/2024
Save to calendar

Oct222024
[RAG Bootcamp with Official Inter IIT, India\
===========================================](https://pathway.com/events/rag-bootcamp-official-inter-iit-24)
Join Pathway's free RAG Bootcamp with Official Inter IIT on October 22, 2024. Master Generative AI, LLMs, and real-time data processing
Tuesday, October 22 almost 2 years ago
Online
[Read More](https://pathway.com/events/rag-bootcamp-official-inter-iit-24)
23/10/2024
Save to calendar

Oct232024
[NVIDIA AI Summit 2024\
=====================](https://pathway.com/events/nvidia-ai-summit-2024)
Wednesday - Friday, October 23 - 25 almost 2 years ago
Mumbai, India[](https://www.google.com/maps/search/)
[Read More](https://pathway.com/events/nvidia-ai-summit-2024)
30/10/2024
Save to calendar

Oct302024
[SF AI Cocktail\
==============](https://pathway.com/events/sf-meet-up-2024)
Enjoy delicious Italian bites and drinks while networking with Pathway's friends and family. All founders, Zuzanna, Jan, Adrian and Claire will be excited to see you in person!
Wednesday, October 30 over 1 year ago
Piccino Coffee Bar[845 22nd St, San Francisco, CA 94107, United States](https://www.google.com/maps/search/845%2022nd%20St%2C%20San%20Francisco%2C%20CA%2094107%2C%20United%20States)
[Read More](https://pathway.com/events/sf-meet-up-2024)
06/11/2024
Save to calendar

Nov062024
[Realtime RAG with Pathway Live Data Framework at ADSC\
=====================================================](https://pathway.com/events/realtime-rag-adsc-aachen-24)
Join Pathway and ADSC RWTH Aachen on November 6, 2024, for a masterclass with Mudit Srivastava and Julian Wiking. Explore Realtime RAG and LLM applications
Wednesday, November 6 over 1 year ago
Aachen, Germany[Aachen, Germany and Online](https://www.google.com/maps/search/Aachen%2C%20Germany%20and%20Online)
[Read More](https://pathway.com/events/realtime-rag-adsc-aachen-24)
07/11/2024
Save to calendar

Nov072024
[ML in PL Conference 2024\
========================](https://pathway.com/events/ml-in-pl-2024)
Thursday - Sunday, November 7 - 10 over 1 year ago
Copernicus Science Center, Warsaw[Wybrzeże Kościuszkowskie 20, 00-390 Warsaw](https://www.google.com/maps/search/Wybrze%C5%BCe%20Ko%C5%9Bciuszkowskie%2020%2C%2000-390%20Warsaw)
[Read More](https://pathway.com/events/ml-in-pl-2024)
19/11/2024
Save to calendar

Nov192024
[Bengaluru Tech Summit 2024\
==========================](https://pathway.com/events/bengaluru-tech-summit-2024)
Tuesday, November 19 over 1 year ago
Bangalore, India[Bangalore Palace, Bengaluru, India](https://www.google.com/maps/search/Bangalore%20Palace%2C%20Bengaluru%2C%20India)
[Read More](https://pathway.com/events/bengaluru-tech-summit-2024)
20/11/2024
Save to calendar

Nov202024
[Davis Gen AI Founders Mixer with Pathway\
========================================](https://pathway.com/events/davis-gen-ai-founders-mixer-24)
Join Pathway and GDSC UC Davis for an exclusive session with Victor Szczerba. Explore insights on launching and leading in the GenAI space
Wednesday, November 20 over 1 year ago
Walker 1310, UC Davis[Walker 1310, UC Davis, California and Online](https://www.google.com/maps/search/Walker%201310%2C%20UC%20Davis%2C%20California%20and%20Online)
[Read More](https://pathway.com/events/davis-gen-ai-founders-mixer-24)
23/11/2024
Save to calendar

Nov232024
[ICPC x Pathway Regional Contest Collaboration\
=============================================](https://pathway.com/events/icpc-pathway-regional-contest-collaboration)
Join Pathway and ICPC India for an exciting series of regional contests aimed at fostering programming excellence and promoting advancements in AI and ML.
Saturday - Wednesday, November 23 - December 4 over 1 year ago
Kanpur, Amrita, and Chennai[Kanpur, Amrita, and Chennai, India (on-site)](https://www.google.com/maps/search/Kanpur%2C%20Amrita%2C%20and%20Chennai%2C%20India%20(on-site))
[Read More](https://pathway.com/events/icpc-pathway-regional-contest-collaboration)
18/12/2024
Save to calendar

Dec182024
[ICPC India x Pathway: AMA with Programming Champions\
====================================================](https://pathway.com/events/icpc-india-ama-24)
Join Pathway and ICPC India for an exclusive AMA with top competitive programming medalists on 18th December 2024. Gain insights to advance your coding career
Wednesday, December 18 over 1 year ago
Online
[Read More](https://pathway.com/events/icpc-india-ama-24)
26/02/2025
Save to calendar

Feb262025
[Intel AI DevSummit\
==================](https://pathway.com/events/intel-ai-summit-2025)
The AI DevSummit is focused on technical talks and workshops that highlight the capabilities of Intel hardware and AI software to inspire the community to create AI powered software, fine tuning models, and educating the audience of the latest AI capabilities.
Wednesday, February 26 (14:10 GMT-6) over 1 year ago
[Online](https://www.google.com/maps/search/Online)
[Read More](https://pathway.com/events/intel-ai-summit-2025)
17/03/2025
Save to calendar

Mar172025
[NVIDIA GTC 2025\
===============](https://pathway.com/events/2025-nvidia-gtc)
NVIDIA GTC is coming back to San Jose on March 17–21, 2025. Join us and thousands of developers, innovators, and business leaders to experience how AI and accelerated computing are helping humanity solve our most complex challenges!
Monday - Friday, March 17 - 21 (13:10 GMT-5) over 1 year ago
150 W San Carlos St + Online[150 W San Carlos St, San Jose, CA 95113, USA](https://www.google.com/maps/search/150%20W%20San%20Carlos%20St%2C%20San%20Jose%2C%20CA%2095113%2C%20USA)
[Read More](https://pathway.com/events/2025-nvidia-gtc)
22/03/2025
Save to calendar

Mar222025
[Tinkerer's Lab IIT Hyderabad Gen AI Hackathon by Pathway\
========================================================](https://pathway.com/events/iit-hyderabad-tinkerers-lab)
The Tinkerer's Lab IIT Hyderabad Gen AI Hackathon, powered by Pathway Live Data Framework, is your chance to showcase your skills, innovate with live data, and win big!
Saturday, March 22 over 1 year ago
IIT Hyderabad, Hyderabad, Telangana[IITH Road, Near NH-65, Sangareddy, Kandi, Telangana 502285, India](https://www.google.com/maps/search/IITH%20Road%2C%20Near%20NH-65%2C%20Sangareddy%2C%20Kandi%2C%20Telangana%20502285%2C%20India)
[Read More](https://pathway.com/events/iit-hyderabad-tinkerers-lab)
25/03/2025
Save to calendar

Mar252025
[Generative AI Hackathon\
=======================](https://pathway.com/events/anhad-iit-jammu-2025)
Join us at Anhad 2025, the flagship hackathon at IIT Jammu, for a thrilling Generative AI Hackathon powered by Pathway Live Data Framework.
Tuesday - Sunday, March 25 - April 6 over 1 year ago
Online + IIT Jammu[NH-44 , PO Nagrota, Jagti, Jammu and Kashmir 181221](https://www.google.com/maps/search/NH-44%20%2C%20PO%20Nagrota%2C%20Jagti%2C%20Jammu%20and%20Kashmir%20181221)
[Read More](https://pathway.com/events/anhad-iit-jammu-2025)
09/04/2025
Save to calendar

Apr092025
[AWS Summit Paris 2025\
=====================](https://pathway.com/events/2025-04-09-aws-summit-paris)
We'll be exhibiting at the Startup Loft during AWS Summit Paris! Visit us on April 9th to learn more about Pathway. April 9th
Wednesday, April 9 over 1 year ago
2 Pl de la Pte Maillot[2 Pl de la Pte Maillot, 75017 Paris, France](https://www.google.com/maps/search/2%20Pl%20de%20la%20Pte%20Maillot%2C%2075017%20Paris%2C%20France)
[Read More](https://pathway.com/events/2025-04-09-aws-summit-paris)
09/04/2025
Save to calendar

Apr092025
[Google Cloud Next 2025\
======================](https://pathway.com/events/google-cloud-next-2025)
We’ll be at Google Cloud Next 2025! Join us on April 9-11, 2025 at the Mandalay Bay Convention Center in Las Vegas to learn more about Pathway.
Wednesday - Friday, April 9 - 11 (GMT-7) over 1 year ago
Mandalay Bay Convention Center[Mandalay Bay Convention Center, Las Vegas](https://www.google.com/maps/search/Mandalay%20Bay%20Convention%20Center%2C%20Las%20Vegas)
[Read More](https://pathway.com/events/google-cloud-next-2025)
28/10/2025
Save to calendar

Oct282025
[ODSC AI West 2025\
=================](https://pathway.com/events/odsc-ai-west-2025)
We'll be at ODSC AI West 2025 in Burlingame, California. Visit us on October 28–30, 2025 to learn more about Pathway.
Tuesday - Thursday, October 28 - 30 (GMT-7) 9 months ago
Burlingame[Burlingame, California](https://www.google.com/maps/search/Burlingame%2C%20California)
[Read More](https://pathway.com/events/odsc-ai-west-2025)
01/12/2025
Save to calendar

Dec012025
[AWS re:Invent 2025\
==================](https://pathway.com/events/aws-reinvent-2025)
We’ll be at AWS re:Invent 2025 in Las Vegas, where Pathway will present a talk by Jan Chorowski (CTO) and Victor Szczerba (CCO). Visit us on December 1–5, 2025 to learn more about Pathway, and attend the talk
Monday - Friday, December 1 - 5 (GMT-8) 8 months ago
Las Vegas
[Read More](https://pathway.com/events/aws-reinvent-2025)
11/12/2025
Save to calendar

Dec112025
[Inter IIT Tech Meet 14.0\
========================](https://pathway.com/events/inter-iit-tech-meet-14-2025)
Pathway took part in Inter IIT Tech Meet 14.0, a Pan-IIT annual event where teams solve real-world technical problem statements.
Thursday - Sunday, December 11 - 14 (GMT+5:30) 8 months ago
IIT Patna
[Read More](https://pathway.com/events/inter-iit-tech-meet-14-2025)
05/01/2026
Save to calendar

Jan05
[Synaptix Frontier AI Hack 2026\
==============================](https://pathway.com/events/synaptix-frontier-ai-hack-2026)
Pathway powered a frontier AI hack at IIT Madras through Shaastra, giving participants the chance to build, compete for a ₹50,000 prize pool, and showcase their work to Pathway engineering leaders.
Monday, January 5 (GMT+5:30) 7 months ago
IIT Madras
[Read More](https://pathway.com/events/synaptix-frontier-ai-hack-2026)
16/01/2026
Save to calendar

Jan16
[Kharagpur Data Science Hackathon 2026\
=====================================](https://pathway.com/events/kharagpur-data-science-hackathon-2026)
Pathway participated in the 6th edition of the Kharagpur Data Science Hackathon, organized by the Kharagpur Data Analytics Group.
Friday, January 16 (GMT+5:30) 6 months ago
IIT Kharagpur[IIT Kharagpur, with an online round followed by an offline finale](https://www.google.com/maps/search/IIT%20Kharagpur%2C%20with%20an%20online%20round%20followed%20by%20an%20offline%20finale)
[Read More](https://pathway.com/events/kharagpur-data-science-hackathon-2026)
21/01/2026
Save to calendar

Jan21
[Venture Scientist Demo Day\
==========================](https://pathway.com/events/venture-scientist-demo-day-2026)
We'll be joining Venture Scientist Demo Day on January 21, 2026 at Mila in Quebec, where Pathway CEO and Co-Founder Zuzanna Stamirowska will take part in a featured fireside chat.
Wednesday, January 21 (GMT-5) 6 months ago
Montreal[Montreal, Canada](https://www.google.com/maps/search/Montreal%2C%20Canada)
[Read More](https://pathway.com/events/venture-scientist-demo-day-2026)
06/02/2026
Save to calendar

Feb06
[The Post-Transformer Era: AI's Next Frontier\
============================================](https://pathway.com/events/nyu-post-transformer-2026)
Organized by NYU Tandon and Pathway, in partnership with select IIT Technical Councils.
Friday, February 6 (17:00 CET) 6 months ago
Online
[Read More](https://pathway.com/events/nyu-post-transformer-2026)
16/03/2026
Save to calendar

Mar16
[NVIDIA GTC 2026\
===============](https://pathway.com/events/nvidia-gtc-2026)
We'll be at NVIDIA GTC 2026 in San Jose on March 16–19, 2026. Visit us to learn more about Pathway.
Monday - Thursday, March 16 - 19 (GMT-7) 4 months ago
San Jose, CA
[Read More](https://pathway.com/events/nvidia-gtc-2026)
01/04/2026
Save to calendar

Apr01
[AWS Summit Paris 2026\
=====================](https://pathway.com/events/aws-summit-paris-2026)
We'll be at AWS Summit Paris on April 1, 2026 in Paris. If you'd like to connect and learn more about Pathway while we're on-site, reach out to schedule time with our team.
Wednesday, April 1 (CEST) 4 months ago
Paris[Paris, France](https://www.google.com/maps/search/Paris%2C%20France)
[Read More](https://pathway.com/events/aws-summit-paris-2026)
04/04/2026
Save to calendar

Apr04
[US AI Olympiad: From Transformers to Linear Attention Variants\
==============================================================](https://pathway.com/events/us-ai-olympiad-mit-2026)
Join us on April 4, 2026 at MIT in Cambridge for a technical talk by Junlin Jiang during the second round of the US AI Olympiad, exploring memory, scale, and emerging approaches beyond standard Transformer architectures.
Saturday, April 4 (GMT-4) 4 months ago
MIT, Cambridge[Massachusetts Institute of Technology, Cambridge](https://www.google.com/maps/search/Massachusetts%20Institute%20of%20Technology%2C%20Cambridge)
[Read More](https://pathway.com/events/us-ai-olympiad-mit-2026)
10/04/2026
Save to calendar

Apr10
[BDH: The Missing Link between the Transformer and Models of the Brain\
=====================================================================](https://pathway.com/events/bdh-missing-link-transformer-montreal-2026)
Join us on April 10, 2026 in Montreal, Canada for a talk by Jan Chorowski, CTO and Co-Founder of Pathway, on BDH: The Missing Link between the Transformer and Models of the Brain.
Friday, April 10 (GMT-4) 4 months ago
Montreal[Montreal, Canada](https://www.google.com/maps/search/Montreal%2C%20Canada)
[Read More](https://pathway.com/events/bdh-missing-link-transformer-montreal-2026)
14/04/2026
Save to calendar

Apr14
[Inside a Neolab: BDH and the Future of AI beyond the Transformer\
================================================================](https://pathway.com/events/acm-neolab-pathway-2026)
Stanford ACM is offering a rare chance to hear directly from the neo-lab building what comes next.
Tuesday, April 14 (08:00 GMT-7) 3 months ago
Stanford ACM[](https://www.google.com/maps/search/undefined)
[Read More](https://pathway.com/events/acm-neolab-pathway-2026)
17/04/2026
Save to calendar

Apr17
[BDH: The Missing Link Between the Transformer and Models of the Brain\
=====================================================================](https://pathway.com/events/bdh-missing-link-transformer-toronto-2026)
Join us on Friday, April 17, 2026 in Toronto, for a workshop with Jan Chorowski, CTO and Co-Founder of Pathway, who will present 'BDH: The Missing Link between the Transformer and Models of the Brain'
Friday, April 17 (GMT-4) 3 months ago
Toronto[U of T: Schwartz Reisman Innovation Campus, Toronto](https://www.google.com/maps/search/U%20of%20T%3A%20Schwartz%20Reisman%20Innovation%20Campus%2C%20Toronto)
[Read More](https://pathway.com/events/bdh-missing-link-transformer-toronto-2026)
22/04/2026
Save to calendar

Apr22
[Google Cloud Next 2026\
======================](https://pathway.com/events/google-cloud-next-2026)
We’ll be at Google Cloud Next 2026! Join us on April 22–24, 2026 at the Mandalay Bay Convention Center in Las Vegas to learn more about Pathway.
Wednesday - Friday, April 22 - 24 (GMT-7) 3 months ago
Mandalay Bay Convention Center[Mandalay Bay Convention Center, Las Vegas](https://www.google.com/maps/search/Mandalay%20Bay%20Convention%20Center%2C%20Las%20Vegas)
[Read More](https://pathway.com/events/google-cloud-next-2026)
05/05/2026
Save to calendar

May05
[Transformers vs. Post-Transformers: The Deciding Round, with Lukasz Kaiser\
==========================================================================](https://pathway.com/events/post-transformer-sf-2026)
On May 5, we’re turning the future of AI into a fast-paced evening of punchy rounds, playful rebuttals, crowd-fueled energy, and a clapometer that decides who takes the title.
Tuesday, May 5 (08:00 GMT-7) 3 months ago
San Francisco[San Francisco, California](https://www.google.com/maps/search/San%20Francisco%2C%20California)
[Read More](https://pathway.com/events/post-transformer-sf-2026)
30/09/2026
Save to calendar

Sep30
[Sifted Summit 2026\
==================](https://pathway.com/events/sifted-summit-2026)
Zuzanna Stamirowska, co-founder and CEO of Pathway, will be speaking at Sifted Summit 2026 in London on September 30 – October 1, 2026.
Wednesday - Thursday, September 30 - October 1 (BST) in 2 months
London[Shoreditch, London](https://www.google.com/maps/search/Shoreditch%2C%20London)
[Read More](https://pathway.com/events/sifted-summit-2026)
14/10/2026
Save to calendar

Oct14
[TechCrunch Disrupt 2026\
=======================](https://pathway.com/events/techcrunch-disrupt-2026)
Zuzanna Stamirowska, co-founder and CEO of Pathway, has been announced as a speaker on the Builders Stage at TechCrunch Disrupt 2026 in San Francisco on October 14, 2026.
Wednesday, October 14 (GMT-7) in 3 months
San Francisco[Moscone Center, San Francisco, California](https://www.google.com/maps/search/Moscone%20Center%2C%20San%20Francisco%2C%20California)
[Read More](https://pathway.com/events/techcrunch-disrupt-2026)
---
# Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So
Table of Contents
Taking you to an external site
==============================
You will be taken to [https://www.forbes.com/sites/victordey/2025/10/08/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so/](https://www.forbes.com/sites/victordey/2025/10/08/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so/)
in a moment.
* * *
Forbes
[](https://www.forbes.com/)
Power your RAG and ETL pipelines with Live Data
[Get started for free](https://pathway.com/developers/user-guide/introduction/installation)

Related Articles
* [\
\
\
\
AWS Events\
\
news · bdh · videoDec 4, 2025\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
* [in Spanish\
\
\
\
\
\
Forbes Argentina\
\
news · bdhSep 9, 2025\
\
Can an artificial intelligence learn like a human brain does? A startup believes it has achieved this](https://pathway.com/news/inteligencia-artificial-aprender-cerebro-humano)
* [in German\
\
\
\
\
\
Notebook Check\
\
news · bdhOct 21, 2025\
\
AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency](https://pathway.com/news/ai-should-think-like-the-human-brain-dragon-hatchling-bdh-copies-neurons-for-unlimited-context-and-higher-efficiency)
[News\
\
Benchmarks: Fundamental Unlocks for AI](https://pathway.com/news/benchmarks)
[News\
\
Embracing Modern Live Data Pipelines is Key to Scaling Enterprise AI](https://pathway.com/news/embracing-modern-live-data-pipelines-is-key-to-scaling-enterprise-ai)
---
# pw.xpacks.llm | Pathway
pw.xpacks.llm
=============
The Live Data Framework LLM xpack provides tools for working with large language models. This page provides their API documentation. See [user guide](https://pathway.com/developers/user-guide/llm-xpack/overview)
for an overview of the LLM xpack.
[API Docs\
\
pw.xpacks.connectors](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint)
[Pathway Xpacks LLM\
\
pw.xpacks.llm.llms](https://pathway.com/developers/api-docs/pathway-xpacks-llm/llms)
---
# pw.sql | Pathway
Using SQL with Pathway Live Data Framework
==========================================
Perform SQL commands using Pathway Live Data Framework's `pw.sql` function.
* * *
Pathway Live Data Framework provides a very simple way to use SQL commands directly in your Pathway Live Data Framework application: the use of `pw.sql`. Pathway Live Data Framework is significantly different from a usual SQL database, and not all SQL operations are available in Pathway Live Data Framework. In the following, we present the SQL operations which are compatible with Pathway Live Data Framework and how to use `pw.sql`.
**This article is a summary of dos and don'ts on how to use Pathway Live Data Framework to execute SQL queries, this is not an introduction to SQL.**
[Usage](https://pathway.com/developers/api-docs/sql-api#usage)
---------------------------------------------------------------
You can very easily execute a SQL command by doing the following:
`pw.sql(query, tab=t)`
This will execute the SQL command `query` where the Pathway Live Data Framework table `t` (Python local variable) can be referred to as `tab` (SQL table name) inside `query`. More generally, you can pass an arbitrary number of tables associations `name, table` using `**kwargs`: `pw.sql(query, tab1=t1, tab2=t2,.., tabn=tn)`.
[Example](https://pathway.com/developers/api-docs/sql-api#example)
-------------------------------------------------------------------
`import pathway as pw t = pw.debug.table_from_markdown( """ | a | b 1 | 1 | 2 2 | 4 | 3 3 | 4 | 7 """ ) ret = pw.sql("SELECT * FROM tab WHERE a2", tab=t) pw.debug.compute_and_print(result_where)`
`| a | b ^Z3QWT29... | 4 | 3 ^3CZ78B4... | 4 | 7`
### [Boolean and Arithmetic Expressions](https://pathway.com/developers/api-docs/sql-api#boolean-and-arithmetic-expressions)
With the `SELECT ...` and `WHERE ...` clauses, you can use the following operators:
* boolean operators: `AND`, `OR`, `NOT`
* arithmetic operators: `+`, `-`, `*`, `/`, `DIV`, `MOD`, `==`, `!=`, `<`, `>`, `<=`, `>=`, `<>`
* NULL
`result_bool = pw.sql("SELECT a,b FROM tab WHERE b-a>0 AND a>3", tab=t) pw.debug.compute_and_print(result_bool)`
`| a | b ^3CZ78B4... | 4 | 7`
Both `!=` and `<>` can be used to check non-equality.
`result_neq = pw.sql("SELECT a,b FROM tab WHERE a != 4 OR b <> 3", tab=t) pw.debug.compute_and_print(result_neq)`
`| a | b ^YYY4HAB... | 1 | 2 ^3CZ78B4... | 4 | 7`
`NULL` can be used to filter out rows with missing values:
`t_null = pw.debug.table_from_markdown( """ | a | b 1 | 1 | 2 2 | 4 | 3 | 4 | 7 """ ) result_null = pw.sql("SELECT a, b FROM tab WHERE b IS NOT NULL ", tab=t_null) pw.debug.compute_and_print(result_null)`
`| a | b ^YYY4HAB... | 1 | 2 ^3CZ78B4... | 4 | 7`
You can use single row result subqueries in the `WHERE` clause to filter a table based on the subquery results:
`t_subqueries = pw.debug.table_from_markdown( """ | employee | salary 1 | 1 | 10 2 | 2 | 11 3 | 3 | 12 """ ) result_subqueries = pw.sql( "SELECT employee, salary FROM t WHERE salary >= (SELECT AVG(salary) FROM t)", t=t_subqueries, ) pw.debug.compute_and_print(result_subqueries)`
`| employee | salary ^Z3QWT29... | 2 | 11 ^3CZ78B4... | 3 | 12`
⚠️ For now, only single row result subqueries are supported. Correlated subqueries and the associated operations `ANY`, `NONE`, and `EVERY` (or its alias `ALL`) are currently not supported.
### [`GROUP BY`](https://pathway.com/developers/api-docs/sql-api#group-by)
You can use `GROUP BY` to group rows with the same value for a given column, and to use an aggregate function over the grouped rows.
`result_groupby = pw.sql("SELECT a, SUM(b) FROM tab GROUP BY a", tab=t) pw.debug.compute_and_print(result_groupby)`
`| a | _col_1 ^YYY4HAB... | 1 | 2 ^3HN31E1... | 4 | 10`
⚠️ `GROUP BY` and `JOIN` should not be used together in a single `SELECT`.
#### [Aggregation functions](https://pathway.com/developers/api-docs/sql-api#aggregation-functions)
With `GROUP BY`, you can use the following aggregation functions:
* `AVG`
* `COUNT`
* `MAX`
* `MIN`
* `SUM`
⚠️ Pathway Live Data Framework reducers (`pw.count`, `pw.sum`, etc.) aggregate over `None` values, while traditional SQL aggregate functions skip `NULL` values: be careful to remove all the undefined values before using an aggregate function.
### [`HAVING`](https://pathway.com/developers/api-docs/sql-api#having)
`result_having = pw.sql("SELECT a, SUM(b) FROM tab GROUP BY a HAVING SUM(b)>5", tab=t) pw.debug.compute_and_print(result_having)`
`| a | _col_1 ^3HN31E1... | 4 | 10`
### [`AS` (alias)](https://pathway.com/developers/api-docs/sql-api#as-alias)
Pathway Live Data Framework supports both notations: `old_name as new_name` and `old_name new_name`.
`result_alias = pw.sql("SELECT b, a AS c FROM tab", tab=t) pw.debug.compute_and_print(result_alias)`
`| b | c ^YYY4HAB... | 2 | 1 ^Z3QWT29... | 3 | 4 ^3CZ78B4... | 7 | 4`
`result_alias = pw.sql("SELECT b, a c FROM tab", tab=t) pw.debug.compute_and_print(result_alias)`
`| b | c ^YYY4HAB... | 2 | 1 ^Z3QWT29... | 3 | 4 ^3CZ78B4... | 7 | 4`
### [`UNION`](https://pathway.com/developers/api-docs/sql-api#union)
Pathway Live Data Framework provides the standard `UNION` SQL operator. Note that `UNION` requires matching column names.
`t_union = pw.debug.table_from_markdown( """ | a | b 4 | 9 | 3 5 | 2 | 7 """ ) result_union = pw.sql("SELECT * FROM tab UNION SELECT * FROM tab2", tab=t, tab2=t_union) pw.debug.compute_and_print(result_union)`
`| a | b ^KYCVNKF... | 1 | 2 ^856GZ16... | 2 | 7 ^H3J0A0V... | 4 | 3 ^GX1QVN0... | 4 | 7 ^7HC68KR... | 9 | 3`
### [`INTERSECT`](https://pathway.com/developers/api-docs/sql-api#intersect)
Pathway Live Data Framework provides the standard `INTERSECT` SQL operator. Note that `INTERSECT` requires matching column names.
`t_inter = pw.debug.table_from_markdown( """ | a | b 4 | 9 | 3 5 | 2 | 7 6 | 1 | 2 """ ) result_inter = pw.sql( "SELECT * FROM tab INTERSECT SELECT * FROM tab2", tab=t, tab2=t_inter ) pw.debug.compute_and_print(result_inter)`
`| a | b ^KYCVNKF... | 1 | 2`
⚠️ `INTERSECT` does not support `INTERSECT ALL` (coming soon).
### [`JOIN`](https://pathway.com/developers/api-docs/sql-api#join)
Pathway Live Data Framework provides different join operations: `INNER JOIN`, `LEFT JOIN` (or `LEFT OUTER JOIN`), `RIGHT JOIN` (or `RIGHT OUTER JOIN`), `SELF JOIN`, and `CROSS JOIN`.
`t_join = pw.debug.table_from_markdown( """ | b | c 4 | 4 | 9 5 | 3 | 4 6 | 7 | 5 """ ) result_join = pw.sql( "SELECT * FROM left_table INNER JOIN right_table ON left_table.b==right_table.b", left_table=t, right_table=t_join, ) pw.debug.compute_and_print(result_join)`
`| a | b | c ^3CZBR2S... | 4 | 3 | 4 ^6A0R4A9... | 4 | 7 | 5`
⚠️ `GROUP BY` and `JOIN` should not be used together in a single `SELECT`.
⚠️ `NATURAL JOIN` and `FULL JOIN` are not supported (coming soon).
### [`WITH`](https://pathway.com/developers/api-docs/sql-api#with)
In addition to being placed inside a `WHERE` clause, subqueries can also be performed using the `WITH` keyword:
`result_with = pw.sql( "WITH group_table (a, sumB) AS (SELECT a, SUM(b) FROM tab GROUP BY a) SELECT sumB FROM group_table", tab=t, ) pw.debug.compute_and_print(result_with)`
`| sumB ^YYY4HAB... | 2 ^3HN31E1... | 10`
[Differences from the SQL standard](https://pathway.com/developers/api-docs/sql-api#differences-from-the-sql-standard)
-----------------------------------------------------------------------------------------------------------------------
First of all, not all SQL queries can be executed in Pathway Live Data Framework. This stems mainly from the fact that the Pathway Live Data Framework is built to process streaming and dynamic data efficiently.
### [No ordering](https://pathway.com/developers/api-docs/sql-api#no-ordering)
In Pathway Live Data Framework, indexes are separately generated and maintained by the engine, which does not guarantee any row order: SQL operations like `LIMIT`, `ORDER BY` or `SELECT TOP` don't always make sense in this context. In the future, we will support an `ORDER BY ... LIMIT ...` keyword combination, which is typically meaningful in Pathway Live Data Framework. The column `id` is reserved and should not be used as a column name, this column is not captured by `*` expressions.
Furthermore, there is no order on the columns and the column order used in a `SELECT` query need not be preserved.
### [Immutability](https://pathway.com/developers/api-docs/sql-api#immutability)
Pathway Live Data Framework tables are immutable: operations such as `INSERT INTO` are not supported.
### [Limits](https://pathway.com/developers/api-docs/sql-api#limits)
Correlated subqueries are currently not supported and keywords such as `LIKE`, `ANY`, `ALL`, or `EXISTS` are not supported. `COALESCE` and`IFNULL` are not supported but should be soon. We strongly suggest not to use anonymous columns: they might work but we cannot guarantee their behavior.
[Conclusion](https://pathway.com/developers/api-docs/sql-api#conclusion)
-------------------------------------------------------------------------
Pathway Live Data Framework provides a powerful API to ease the transition of SQL data transformations and pipelines into Pathway Live Data Framework. However, Pathway Live Data Framework and SQL serve different purposes. To benefit from all the possibilities Pathway Live Data Framework has to offer we strongly encourage you to use the Python syntax directly, as much as you can. Most of the time, this syntax is at least as easy to follow as SQL - see for example our [join](https://pathway.com/developers/user-guide/data-transformation/join-manual)
and [groupby](https://pathway.com/developers/user-guide/data-transformation/groupby-reduce-manual)
manuals.
[API Docs\
\
pw.reducers](https://pathway.com/developers/api-docs/reducers)
[API Docs\
\
pw.temporal](https://pathway.com/developers/api-docs/temporal)
---
# pw.indexing | Pathway
pw.indexing
===========
[class **BruteForceKnn**(data\_column, metadata\_column, \*, dimensions, reserved\_space, auxiliary\_space=131072, metric, embedder=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnn)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L169-L258)
Interface for a brute force implementation of a nearest neighbors index.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **auxiliary\_space** (`int`) – auxiliary space (in the number of entries), the maximum number of distances that are stored in memory, while evaluating queries, in case `auxiliary_space` is set to a value smaller than the current number of entries in the index, it is still proportional to the size of the index (the value given in this parameter is ignored)
* **metric** ([`BruteForceKnnMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
) – metric kind that is used to determine distance
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L206-L215)
Currently, brute force knn index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L217-L258)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **BruteForceKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, auxiliary\_space=131072, metric=)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnnFactory)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L485-L528)
Factory for creating BruteForceKnn indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries. This is only needed if the embedder is not provided.
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **auxiliary\_space** (`int`) – auxiliary space (in the number of entries), the maximum number of distances that are stored in memory, while evaluating queries, in case `auxiliary_space` is set to a value smaller than the current number of entries in the index, it is still proportional to the size of the index (the value given in this parameter is ignored)
* **metric** ([`BruteForceKnnMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
) – metric kind that is used to determine distance. Defaults to cosine similarity.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **BruteForceKnnMetricKind**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
--------------------------------------------------------------------------------------------------------------------------------------
Used for choosing the metric used in the BruteForceKnn index.
### [**L2SQ**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind.L2SQ)
Squared Euclidean distance.
### [**COS**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind.COS)
Cosine distance.
[class **DataIndex**(data\_table, inner\_index)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.DataIndex)
-------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L277-L473)
A class that given an implementation of an index provides methods that augment the search results with supplementary data.
* **Parameters**
* **data\_table** (`pw.Table`) – table containing supplementary data, using match-by-id ( ID from data\_table and ID from the response of `inner_index`)
* **inner\_index** ([`InnerIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)
) – a data structure that accepts data from some `data_column` and for each query answers with a list of IDs, one ID per matched row from `data_column`. The IDs are taken from the table that contains the `data_column` column
### [**query**(query\_column, \*, number\_of\_matches=3, collapse\_rows=True, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.DataIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L349-L410)
This method takes the query from `query_column`, optionally applies `self.embedder` on it and passes it to inner index to obtain matching entries stored in the `InnerIndex` (being a match depends on the implementation and the internal state of the `InnerIndex`).
For each query and for each column in `self.data_table` it computes a tuple of values that are in the rows that have IDs indicated by the response of the `InnerIndex`. It returns a [`JoinResult`](https://pathway.com/developers/api-docs/pathway#pathway.JoinResult)
of a left join between query table (a table that holds `query_column`) and the mentioned table of tuples (exactly one row per query, with values not present if set of matching IDs is empty).
Optionally, the method can skip the tupling step, and return a `JoinResult` of a left join between query table, and `self.data_table`, using the result of `InnerIndex` to indicate when the IDs match (exactly one row per match plus one row per query with no matches).
The answers to the old queries are updated when the state of the index changes. To work properly, the `inner_index` has to be an instance of `InnerIndex` supporting `query`.
* **Parameters**
* **query\_column** (`pw.ColumnReference`) – A column containing the queries, needs to be in the format compatible with `self.inner_index` (or `self.embedder`).
* **number\_of\_matches** (`pw.ColumnExpression | int`) – The maximum number of matches returned for each query.
* **collapse\_rows** (`bool`) – Indicates the format of the output. If set to `True`, the resulting table has exactly one row for each query, each column of the right side of the resulting `JoinResult` contains a tuple consisting of values from matched rows of corresponding column in `self.data_table`. If set to `False`, the result is a left join between the table holding the `query_column` and `self.data_index`, using the results from `self.inner_index` to indicate the matches between the IDs.
* **metadata\_filter** (`pw.ColumnExpression [str | None] | pw.ColumnExpression [str] | None`) – Optional, contains a boolean JMESPath query that is used to filter the potential answers inside `self.inner_index` - matching entries are included only when the filter function specified in metadata\_filter\` returns `True`, when run against data in `inner_index.metadata_column`, in a potentially matched row. Passing `None` as value in the column defined in the parameter `metadata_filter` indicates that all possible matches corresponding to this query pass the filtering step.
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, collapse\_rows=True, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.DataIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L412-L473)
This method takes the query from `query_column`, optionally applies self.embedder on it and passes it to inner index to obtain matching entries stored in the `InnerIndex` (being a match depends on the implementation and the internal state of the `InnerIndex`).
For each query and for each column in `self.data_table` it computes a tuple of values that are in the rows that have IDs indicated by the response of the `InnerIndex`. It returns a [`JoinResult`](https://pathway.com/developers/api-docs/pathway#pathway.JoinResult)
of a left join between query table (a table that holds `query_column`) and the mentioned table of tuples (exactly one row per query, with values not present if set of matching IDs is empty).
Optionally, the method can skip the tupling step, and return a `JoinResult` of a left join between query table, and self.data\_table, using the result of `InnerIndex` to indicate when the IDs match (exactly one row per match plus one row per query with no matches).
The index answers according to the current state of the data structure and does not revisit old answers. To work properly, the `inner_index` has to be an instance of `InnerIndex` supporting `query` (all predefined indices support it, this is an information for third party extensions).
* **Parameters**
* **query\_column** (`pw.ColumnReference`) – A column containing the queries, needs to be in the format compatible with `self.inner_index` (or `self.embedder`).
* **number\_of\_matches** (`pw.ColumnExpression | int`) – The maximum number of matches returned for each query.
* **collapse\_rows** (`bool`) – Indicates the format of the output. If set to `True`, the resulting table has exactly one row for each query, each column of the right side of the resulting `JoinResult` contains a tuple consisting of values from matched rows of corresponding column in self.data\_table. If set to `False`, the result is a left join between the table holding the `query_column` and `self.data_index`, using the results from `self.inner_index` to indicate the matches between the IDs.
* **metadata\_filter** (`pw.ColumnExpression [str | None] | pw.ColumnExpression [str] | None`) – Optional, contains a boolean JMESPath query that is used to filter the potential answers inside `self.inner_index` - matching entries are included only when the filter function specified in metadata\_filter\` returns `True`, when run against data in `inner_index.metadata_column`, in a potentially matched row. Passing `None` as value in the column defined in the parameter `metadata_filter` indicates that all possible matches corresponding to this query pass the filtering step.
[class **DefaultKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, auxiliary\_space=131072, metric=)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.DefaultKnnFactory)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L573-L586)
Default factory for creating Knn index - uses the BruteForceKnn index.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **HybridIndex**(retrievers, k=60)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.HybridIndex)
--------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L14-L158)
Hybrid Index that composes any number of other indices and combines them using the Reciprocal Rank Fusion (RRF). It queries each index, and each retrieved row `d` is assigned score `1/(k+rank(d))`, which is then summed over all indices. `HybridIndex` returns best rows from indexed data according to this score.
* **Parameters**
* **retrievers** (`list`\[[`InnerIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)\
\]) – list of indices to be used to compose the hybrid index.
* **k** (`float`) – constant used for calculating ranking score.
### [**query**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.HybridIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L124-L140)
An abstract method. Any implementation of `query` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
Whenever the index changes (via new entries in self.data\_column), it should adjust all old answers to the queries (which is a default behavior of pathway code, as long as it does not use operators telling that it is not the case).
The resulting table with results needs contain a column `_pw_index_reply` (name defined in `_INDEX_REPLY`), in which the resulting tuples are stored.
### [**query\_as\_of\_now**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.HybridIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L142-L158)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **HybridIndexFactory**(retriever\_factories, k=60)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.HybridIndexFactory)
--------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L161-L188)
Factory for creating hybrid indices.
* **Parameters**
* **retriever\_factories** (`list`\[`InnerIndexFactory`\]) – list of factories of indices that will be used in the hybrid index
* **k** (`float`) – constant used for calculating ranking score.
[class **LshKnn**(data\_column, metadata\_column, \*, dimensions, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean', embedder=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.LshKnn)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L261-L403)
Interface for Pathway Live Data Framework’s implementation of KNN via LSH.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of metadata as dictionary, in JSON format.
* **dimensions** (`int`) – number of dimensions in the data
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.LshKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L319-L378)
* **Parameters**
* **query\_column** (`pw.ColumnExpression`) – column containing data that is used to query the index;
* **number\_of\_matches** (`pw.ColumnExpression [int] | int`) – number of nearest neighbors in the index response; defaults to 3
* **metadata\_filter** (`pw.ColumnExpression [str] | None`) – optional, column expression evaluating to the text representation of a boolean JMESPath query. The index will consider only the entries with metadata that satisfies the condition in the filter.
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.LshKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L380-L403)
* **Parameters**
* **query\_column** (`pw.ColumnExpression`) – column containing data that is used to query the index;
* **number\_of\_matches** (`pw.ColumnExpression[int] | int`) – number of nearest neighbors in the index response; defaults to 3
* **metadata\_filter** (`pw.ColumnExpression [str] | None`) – optional, column expression evaluating to the text representation of a boolean JMESPath query. The index will consider only the entries with metadata that satisfies the condition in the filter.
[class **LshKnnFactory**(\*, dimensions=None, embedder=None, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean')](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.LshKnnFactory)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L531-L570)
Factory for creating LshKnn indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions in the data. This is only needed if the embedder is not provided.
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **TantivyBM25**(data\_column, metadata\_column, ram\_budget=52428800, in\_memory\_index=True)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.TantivyBM25)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L40-L105)
Interface for full text index based on [BM25](https://en.wikipedia.org/wiki/Okapi_BM25)
, provided via [tantivy](https://github.com/quickwit-oss/tantivy)
.
* **Parameters**
* **data\_column** (`pw.ColumnExpression[str]`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression[str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **ram\_budget** (`int`) – maximum capacity in bytes. When reached, the index moves a block of data to storage (hence, larger budget means faster index operations, but higher memory cost)
* **in\_memory\_index** (`bool`) – indicates, whether the whole index is stored in RAM; if set to false, the index is stored in some default Pathway Live Data Framework disk storage
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.TantivyBM25.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L60-L69)
Currently, tantivy bm25 index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.TantivyBM25.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L71-L105)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **TantivyBM25Factory**(ram\_budget=52428800, in\_memory\_index=True)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.TantivyBM25Factory)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L108-L135)
Factory for creating a TantivyBM25 index.
* **Parameters**
* **ram\_budget** (`int`) – maximum capacity in bytes. When reached, the index moves a block of data to storage (hence, larger budget means faster index operations, but higher memory cost)
* **in\_memory\_index** (`bool`) – indicates, whether the whole index is stored in RAM; if set to false, the index is stored in some default Pathway Live Data Framework disk storage
[class **USearchKnn**(data\_column, metadata\_column, \*, dimensions, reserved\_space, metric, connectivity=0, expansion\_add=0, expansion\_search=0, embedder=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchKnn)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L64-L166)
Interface for usearch nearest neighbors index, an implementation of k nearest neighbors based on HNSW algorithm [white paper](https://arxiv.org/abs/1603.09320)
.
To understand meaning of the explanation of some of the parameters, you might need some familiarity with either [HNSW algorithm](https://arxiv.org/abs/1603.09320)
or its implementation provided by [USearch](https://github.com/unum-cloud/usearch)
.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **metric** ([`USearchMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
) – metric kind that is used to determine distance
* **connectivity** (`int`) – maximum number of edges for a node in the HNSW index, setting this value to 0 tells usearch to configure it on its own
* **expansion\_add** (`int`) – indicates amount of work spent while adding elements to the index (higher = more accurate placement, more work), setting this value to 0 tells usearch to configure it on its own
* **expansion\_search** (`int`) – indicates amount of work spent while searching for elements in the index (higher = more accurate results, more work), setting this value to 0 tells usearch to configure it on its own
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L112-L121)
Currently, usearch knn index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L123-L166)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **USearchMetricKind**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind)
--------------------------------------------------------------------------------------------------------------------------
Used for choosing the metric used in the USearchKnn index. As these correspond to values of MetricKind from the usearch crate, you can find more information about them in the [usearch documentation](https://docs.rs/usearch/latest/usearch/ffi/struct.MetricKind.html)
.
### [**IP**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.IP)
Inner Product distance.
### [**L2SQ**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.L2SQ)
Squared Euclidean distance.
### [**COS**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.COS)
Cosine distance.
### [**PEARSON**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.PEARSON)
Pearson distance.
### [**HAVERSINE**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.HAVERSINE)
Haversine distance.
### [**DIVERGENCE**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.DIVERGENCE)
Jensen Shannon Divergence distance.
### [**HAMMING**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.HAMMING)
Hamming distance.
### [**TANIMOTO**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.TANIMOTO)
Tanimoto distance.
### [**SORENSEN**](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.USearchMetricKind.SORENSEN)
Sorensen distance.
[class **UsearchKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, metric=, connectivity=0, expansion\_add=0, expansion\_search=0)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.UsearchKnnFactory)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L431-L482)
Factory for creating UsearchKNN indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries. This is only needed if the embedder is not provided.
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **metric** ([`USearchMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
) – metric kind that is used to determine distance. Defaults to cosine similarity.
* **connectivity** (`int`) – maximum number of edges for a node in the HNSW index, setting this value to 0 tells usearch to configure it on its own
* **expansion\_add** (`int`) – indicates amount of work spent while adding elements to the index (higher = more accurate placement, more work), setting this value to 0 tells usearch to configure it on its own
* **expansion\_search** (`int`) – indicates amount of work spent while searching for elements in the index (higher = more accurate results, more work), setting this value to 0 tells usearch to configure it on its own
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[**default\_brute\_force\_knn\_document\_index**(data\_column, data\_table, dimensions, \*, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.default_brute_force_knn_document_index)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L154-L196)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
. This method chooses some parameters of `BruteForceKnn` arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
to see the parameters that can be adjusted.
[**default\_full\_text\_document\_index**(data\_column, data\_table, \*, metadata\_column=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.default_full_text_document_index)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/full_text_document_index.py#L8-L26)
Returns an instance of DataIndex ([`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
), with inner index (data structure) of our choosing. This method chooses an arbitrary implementation of `InnerIndex` (that supports text queries), but it’s not necessarily the best choice of index and its parameters (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project etc.
[**default\_lsh\_knn\_document\_index**(data\_column, data\_table, \*, dimensions, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.default_lsh_knn_document_index)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L66-L105)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
. This method chooses some parameters of LshKnn arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
to see the parameters that can be adjusted.
[**default\_usearch\_knn\_document\_index**(data\_column, data\_table, dimensions, \*, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.default_usearch_knn_document_index)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L108-L151)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
. This method chooses some parameters of USearchKnn arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
to see the parameters that can be adjusted.
[**default\_vector\_document\_index**(data\_column, data\_table, \*, dimensions, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/indexing#pathway.stdlib.indexing.default_vector_document_index)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L34-L63)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) of our choosing. This method chooses an arbitrary implementation of `InnerIndex` (that supports queries on vectors), but it’s not necessarily the best choice of index and its parameters (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project etc.
[API Docs\
\
pw.demo](https://pathway.com/developers/api-docs/pathway-demo)
[API Docs\
\
pw.io](https://pathway.com/developers/api-docs/pathway-io)
---
# pw.persistence | Pathway
pw.persistence
==============
This page provides the documentation on the classes required to set up persistence. See [persistence articles](https://pathway.com/developers/user-guide/deployment/persistence)
for the introduction to the topic.
[Configuration classes](https://pathway.com/developers/api-docs/persistence-api#configuration-classes)
-------------------------------------------------------------------------------------------------------
[class **Backend**(engine\_data\_storage, fs\_path=None)](https://pathway.com/developers/api-docs/persistence-api#pathway.persistence.Backend)
-----------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L13-L112)
The settings of a backend, which is used to persist the computation state.
### [classmethod **azure**(root\_path, account, password, container)](https://pathway.com/developers/api-docs/persistence-api#pathway.persistence.Backend.azure)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L70-L96)
Configure the Azure Blob Storage backend.
* **Parameters**
* **root\_path** (`str`) – path to the root in the Azure Blob Storage container, which will be used to store persisted data;
* **account** (`str`) – account name for Azure Blob Storage;
* **password** (`str`) – password for the specified account;
* **container** (`str`) – container name to store the data in.
* **Returns**
Class instance denoting the Azure Blob Storage backend with root directory as `root_path` and connection settings given by the extra parameters.
### [classmethod **filesystem**(path)](https://pathway.com/developers/api-docs/persistence-api#pathway.persistence.Backend.filesystem)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L26-L45)
Configure the filesystem backend.
* **Parameters**
**path** (`str` | `PathLike`\[`str`\]) – the path to the root directory in the file system, which will be used to store the persisted data.
* **Returns**
Class instance denoting the filesystem storage backend with root directory at `path`.
### [classmethod **s3**(root\_path, bucket\_settings)](https://pathway.com/developers/api-docs/persistence-api#pathway.persistence.Backend.s3)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L47-L68)
Configure the S3 backend.
* **Parameters**
* **root\_path** (`str`) – path to the root in the S3 storage, which will be used to store persisted data;
* **bucket\_settings** ([`AwsS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.AwsS3Settings)
) – the settings for S3 bucket connection in the same format as they are used by S3 connectors.
* **Returns**
Class instance denoting the S3 storage backend with root directory as `root_path` and connection settings given by `bucket_settings`.
[class **Config**(backend, \*, snapshot\_interval\_ms=0, snapshot\_access=, persistence\_mode=, continue\_after\_replay=True, worker\_scaling\_enabled=False, workload\_tracking\_window\_ms=120000)](https://pathway.com/developers/api-docs/persistence-api#pathway.persistence.Config)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L115-L223)
Configure the data persistence. An instance of this class should be passed as a parameter to pw.run in case persistence is enabled.
* **Parameters**
* **backend** ([`Backend`](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend)
) – persistence backend configuration.
* **snapshot\_interval\_ms** (`int`) – the desired duration between snapshot updates in milliseconds.
* **persistence\_mode** ([`PersistenceMode`](https://pathway.com/developers/api-docs/pathway#pathway.PersistenceMode)
) – Can be set to one of the following values. `pw.PersistenceMode.PERSISTING`: the default value and means that all data will be persisted. When this parameter is specified, or when it is omitted, and the configuration is passed to `pw.run`, no additional actions are required to persist the state of your program. Alternatively, you can use `pw.PersistenceMode.UDF_CACHING` meaning that only user-defined function (UDF) calls will be cached. The cache stores the mapping from function input parameters to their results, so if a function is called again with the same inputs, the cached result is returned. `pw.PersistenceMode.OPERATOR_PERSISTING`: the most efficient persistence mechanism, performing persistence only over the state of internal operators, neither preserving the input nor performing any recomputation on it.
* **worker\_scaling\_enabled** (`bool`) – Enables dynamic scaling of worker processes. When enabled, the program may increase or decrease the number of workers and restart itself with the new configuration if the pipeline remains overloaded or underloaded for a sustained period of time. Note that dynamic scaling requires the program to be started using `pathway spawn`.
* **workload\_tracking\_window\_ms** (`int`) – Specifies the time window (in milliseconds) used to evaluate pipeline load when worker scaling is enabled. The load condition (overload or underload) must persist throughout this entire window before a scaling decision is made.
### [classmethod **simple\_config**(backend, snapshot\_interval\_ms=0, snapshot\_access=api.SnapshotAccess.FULL, persistence\_mode=api.PersistenceMode.PERSISTING, continue\_after\_replay=True)](https://pathway.com/developers/api-docs/persistence-api#pathway.persistence.Config.simple_config)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/persistence/__init__.py#L156-L205)
Construct config from a single instance of the `Backend` class, using this backend to persist metadata and snapshot.
Note that this method is deprecated and is left for the backward compatibility purposes only. Please use the pw.persistence.Config constructor instead.
* **Parameters**
* **backend** ([`Backend`](https://pathway.com/developers/api-docs/pathway-persistence#pathway.persistence.Backend)
) – storage backend settings;
* **snapshot\_interval\_ms** (`int`) – the desired freshness of the persisted snapshot in milliseconds. The greater the value is, the more the amount of time that the snapshot may fall behind, and the less computational resources are required.
* **persistence\_mode** ([`PersistenceMode`](https://pathway.com/developers/api-docs/pathway#pathway.PersistenceMode)
) – Can be set to one of the following values. `pw.PersistenceMode.PERSISTING`: the default value and means that all data will be persisted. When this parameter is specified, or when it is omitted, and the configuration is passed to `pw.run`, no additional actions are required to persist the state of your program. Alternatively, you can use `pw.PersistenceMode.UDF_CACHING` meaning that only user-defined function (UDF) calls will be cached. The cache stores the mapping from function input parameters to their results, so if a function is called again with the same inputs, the cached result is returned.
* **Returns**
Persistence config.
[API Docs\
\
pw.ml](https://pathway.com/developers/api-docs/ml)
[Developers\
\
Pathway Live Data Framework Templates](https://pathway.com/developers/templates)
---
# pw.reducers | Pathway
pw.reducers
===========
Reducers are used in reduce to compute the aggregated results obtained by a groupby.
Typical use:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') result = t.groupby(t.colA).reduce(sum=pw.reducers.sum(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**any**(arg)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.any)
--------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L551-L576)
Returns any of the aggregated values. Values are consistent across application to many columns.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' | colA | colB | colD 1 | valA | -1 | 4 2 | valA | 1 | 7 3 | valA | 2 | -3 4 | valB | 4 | 2 5 | valB | 5 | 6 6 | valB | 7 | 1 ''') result = t.groupby(t.colA).reduce( any_B=pw.reducers.any(t.colB), any_D=pw.reducers.any(t.colD), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**argmax**(arg, id=thisclass.this.id)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.argmax)
------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L463-L517)
Returns the index of the maximum aggregated value.
By default it returns the index. You can modify this behavior by setting the id argument to another column. Then a value from this column will be returned from a row where arg is a maximum.
Examples:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') pw.debug.compute_and_print(t)`
Code Results
`result = t.groupby(t.colA).reduce(argmax=pw.reducers.argmax(t.colB), max=pw.reducers.max(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
`table = pw.debug.table_from_markdown( ''' name | age Charlie | 18 Alice | 18 Bob | 18 David | 19 Erin | 19 Frank | 20 ''' ) res = table.reduce(max=pw.reducers.argmax(table.age, table.name)) pw.debug.compute_and_print(res, include_id=False)`
Code Results
[**argmin**(arg, id=thisclass.this.id)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.argmin)
------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L406-L460)
Returns the index of the minimum aggregated value.
By default it returns the index. You can modify this behavior by setting the id argument to another column. Then a value from this column will be returned from a row where arg is a minimum.
Examples:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') pw.debug.compute_and_print(t)`
Code Results
`result = t.groupby(t.colA).reduce(argmin=pw.reducers.argmin(t.colB), min=pw.reducers.min(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
`table = pw.debug.table_from_markdown( ''' name | age Charlie | 18 Alice | 18 Bob | 18 David | 19 Erin | 19 Frank | 20 ''' ) res = table.reduce(min=pw.reducers.argmin(table.age, table.name)) pw.debug.compute_and_print(res, include_id=False)`
Code Results
[**avg**(expression)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.avg)
---------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L675-L697)
Returns the average of the aggregated values.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') result = t.groupby(t.colA).reduce(avg=pw.reducers.avg(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**count**(\*args)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.count)
---------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L641-L672)
Returns the number of aggregated elements.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') result = t.groupby(t.colA).reduce(count=pw.reducers.count()) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**count\_distinct**(\*args)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.count_distinct)
----------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L808-L834)
Returns the number of distinct values.
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''' ) result = t.groupby(t.colA).reduce( group=pw.this.colA, count=pw.reducers.count_distinct(pw.this.colB) ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**count\_distinct\_approximate**(\*args, precision=12)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.count_distinct_approximate)
-------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L837-L883)
Returns the approximation of the number of distinct values.
The reducer uses [HyperLogLog](https://en.wikipedia.org/wiki/HyperLogLog)
to estimate the number of distinct values without the need to store the values. It can only be used on append-only Tables.
This reducer uses less memory than a regular count\_distinct reducer. Their computational needs are similar though. Currently, both reducers use the same way of persisting the state. A better way of persisting the state is planned for count\_distinct\_approximate reducer.
* **Parameters**
* **\*args** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – `ColumnExpression` (or many) for which the number of distinct values has to be computed.
* **precision** (`int`) – The number of hash bits used for the index part in the algorithm. The algorithm uses `2^precision` buckets. Higher precision results in higher memory usage. The precision has to be between 4 and 18.
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''' ) result = t.groupby(t.colA).reduce( group=pw.this.colA, count=pw.reducers.count_distinct_approximate(pw.this.colB) ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**earliest**(expression)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.earliest)
-------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L735-L766)
Returns the earliest of the aggregated values (the one with the lowest processing time).
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' a | b | __time__ 1 | 2 | 2 2 | 3 | 2 1 | 4 | 4 2 | 2 | 6 1 | 1 | 8 ''' ) res = t.groupby(pw.this.a).reduce( pw.this.a, earliest=pw.reducers.earliest(pw.this.b), ) pw.debug.compute_and_print_update_stream(res, include_id=False)`
Code Results
`pw.debug.compute_and_print(res, include_id=False)`
Code Results
[**latest**(expression)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.latest)
---------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L769-L805)
Returns the latest of the aggregated values (the one with the greatest processing time).
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' a | b | __time__ 1 | 2 | 2 2 | 3 | 2 1 | 4 | 4 2 | 2 | 6 1 | 1 | 8 ''' ) res = t.groupby(pw.this.a).reduce( pw.this.a, latest=pw.reducers.latest(pw.this.b), ) pw.debug.compute_and_print_update_stream(res, include_id=False)`
Code Results
`pw.debug.compute_and_print(res, include_id=False)`
Code Results
[**max**(arg)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.max)
--------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L325-L347)
Returns the maximum of the aggregated values.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') result = t.groupby(t.colA).reduce(max=pw.reducers.max(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**min**(arg)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.min)
--------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L300-L322)
Returns the minimum of the aggregated values.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') result = t.groupby(t.colA).reduce(min=pw.reducers.min(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**ndarray**(expression, \*, skip\_nones=False)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.ndarray)
----------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L700-L732)
Returns an array containing all the aggregated values. Order of values inside an array is consistent across application to many columns. If optional argument skip\_nones is set to True, any Nones in aggregated values are omitted from the result.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' | colA | colB | colD 1 | valA | -1 | 4 2 | valA | 1 | 7 3 | valA | 2 | -3 4 | valB | 4 | 5 | valB | 4 | 6 6 | valB | 7 | 1 ''') result = t.groupby(t.colA).reduce( array_B=pw.reducers.ndarray(t.colB), array_D=pw.reducers.ndarray(t.colD, skip_nones=True), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**sorted\_tuple**(arg, \*, skip\_nones=False)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.sorted_tuple)
--------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L579-L607)
Return a sorted tuple containing all the aggregated values. If optional argument skip\_nones is set to True, any Nones in aggregated values are omitted from the result.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' | colA | colB | colD 1 | valA | -1 | 4 2 | valA | 1 | 7 3 | valA | 2 | -3 4 | valB | 4 | 5 | valB | 4 | 6 6 | valB | 7 | 1 ''') result = t.groupby(t.colA).reduce( tuple_B=pw.reducers.sorted_tuple(t.colB), tuple_D=pw.reducers.sorted_tuple(t.colD, skip_nones=True), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**stateful\_many**(combine\_many)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.stateful_many)
---------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/custom_reducers.py#L36-L104)
Decorator used to create custom stateful reducers.
A function wrapped with it has to process the previous state and a list of updates at a specific time. It has to return a new state. The updates are grouped in batches (all updates in a batch have the same processing time, the function is called once per batch) and the batches enter the function in order of increasing processing time.
Example:
Create a table where `__time__` column simulates processing time assigned to entries when they enter pathway:
`import pathway as pw table = pw.debug.table_from_markdown( ''' a | b | __time__ 3 | 1 | 2 4 | 1 | 2 13 | 2 | 2 16 | 2 | 4 2 | 2 | 6 4 | 1 | 6 ''' )`
Now create a custom stateful reducer. It is going to compute a weird sum. It is a sum of even entries incremented by 1 and unchanged odd entries.
`@pw.reducers.stateful_many def weird_sum(state: int | None, rows: list[tuple[list[int], int]]) -> int: if state is None: state = 0 for row, cnt in rows: value = row[0] if value % 2 == 0: state += value + 1 else: state += value return state`
`state` is `None` when the function is called for the first time for a given group. To compute a weird sum, you should set it to 0 then.
`row` is a list of values passed to the reducer. When the reducer is called as `weird_sum(pw.this.a)`, the list has only one element, i.e. value from the column a. `cnt` tells whether the row is an insertion (`cnt == 1`) or deletion (`cnt == -1`). You can learn more [here](https://pathway.com/developers/user-guide/introduction/concepts#the-output-is-a-data-stream)
.
You can now use the reducer in `reduce` operator and compute the result:
`result = table.groupby(pw.this.b).reduce(pw.this.b, s=weird_sum(pw.this.a)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
`weird_sum` is called 2 times for group 1 (at processing times 2 and 6) and 3 times for group 2 (at processing times 2, 4, 6).
[**stateful\_single**(combine\_single)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.stateful_single)
---------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/custom_reducers.py#L111-L174)
Decorator used to create custom stateful reducers.
A function wrapped with it has to process the previous state and a single update. It has to return a new state. The function is called with entries in order of increasing processing time. If there are multiple entries with the same processing time, their order is unspecified.
The function can only be used on tables with insertions only (no updates or deletions). If you need to handle updates/deletions, see [stateful\_many](https://pathway.com/developers/api-docs/reducers#pathway.reducers.stateful_many)
.
Example:
Create a table where `__time__` column simulates processing time assigned to entries when they enter pathway:
`import pathway as pw table = pw.debug.table_from_markdown( ''' a | b | __time__ 3 | 1 | 2 4 | 1 | 2 13 | 2 | 2 16 | 2 | 4 2 | 2 | 6 4 | 1 | 6 ''' )`
Create a custom stateful reducer. It is going to compute a weird sum. It is a sum of even entries incremented by 1 and unchanged odd entries.
`@pw.reducers.stateful_single def weird_sum(state: int | None, value) -> int: if state is None: state = 0 if value % 2 == 0: state += value + 1 else: state += value return state`
`state` is `None` when the function is called for the first time for a given group. To compute a weird sum, you should set it to 0 then.
You can now use the reducer in `reduce` operator and compute the result:
`result = table.groupby(pw.this.b).reduce(pw.this.b, s=weird_sum(pw.this.a)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**sum**(arg, strict=False)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.sum)
----------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L350-L403)
Returns the sum of the aggregated values. Can handle int, float, and array values.
Please note that ints and int arrays use 64-bit representations and as a result can overflow if the sum is too large.
* **Parameters**
* **arg** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – `ColumnExpression` to be summed.
* **strict** (`bool`) – Applicable when `float` or array of type `float` is summed. When set to `False` (default) each batch updates the sum that is a single float. It is a memory efficient and fast approach but can lead to numerical instability, especially if the values are frequently updated/deleted. If set to `True`, the sum is calculated from scratch for each batch by summing all values in a given group (also from previous batches). As a result, it is slower. It requires storing all values within a group separately so it has higher memory requirements.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' colA | colB valA | -1 valA | 1 valA | 2 valB | 4 valB | 4 valB | 7 ''') result = t.groupby(t.colA).reduce(sum=pw.reducers.sum(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
`import pandas as pd np_table = pw.debug.table_from_pandas( pd.DataFrame( { "data": [ np.array([1, 2, 3]), np.array([4, 5, 6]), np.array([7, 8, 9]), ] } ) ) result = np_table.reduce(data_sum=pw.reducers.sum(np_table.data)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**tuple**(arg, \*, skip\_nones=False)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.tuple)
-----------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L610-L638)
Return a tuple containing all the aggregated values. Order of values inside a tuple is consistent across application to many columns. If optional argument skip\_nones is set to True, any Nones in aggregated values are omitted from the result.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' | colA | colB | colC | colD 1 | valA | -1 | 5 | 4 2 | valA | 1 | 5 | 7 3 | valA | 2 | 5 | -3 4 | valB | 4 | 10 | 2 5 | valB | 4 | 10 | 6 6 | valB | 7 | 10 | 1 ''') result = t.groupby(t.colA).reduce( tuple_B=pw.reducers.tuple(t.colB), tuple_C=pw.reducers.tuple(t.colC), tuple_D=pw.reducers.tuple(t.colD), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**udf\_reducer**(reducer\_cls)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.udf_reducer)
----------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/custom_reducers.py#L282-L428)
Decorator for defining stateful reducers. Requires custom accumulator as an argument. Custom accumulator should implement `from_row`, `update` and `compute_result`. Optionally `neutral` and `retract` can be provided for more efficient processing on streams with changing data.
`import pathway as pw class CustomAvgAccumulator(pw.BaseCustomAccumulator): def __init__(self, sum, cnt): self.sum = sum self.cnt = cnt @classmethod def from_row(self, row): [val] = row return CustomAvgAccumulator(val, 1) def update(self, other): self.sum += other.sum self.cnt += other.cnt def compute_result(self) -> float: return self.sum / self.cnt custom_avg = pw.reducers.udf_reducer(CustomAvgAccumulator) t1 = pw.debug.table_from_markdown(''' age | owner | pet | price 10 | Alice | dog | 100 9 | Bob | cat | 80 8 | Alice | cat | 90 7 | Bob | dog | 70 ''') t2 = t1.groupby(t1.owner).reduce(t1.owner, avg_price=custom_avg(t1.price)) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
[**unique**(arg)](https://pathway.com/developers/api-docs/reducers#pathway.reducers.unique)
--------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/reducers.py#L520-L548)
Returns aggregated value, if all values are identical. If values are not identical, exception is raised.
Example:
`import pathway as pw t = pw.debug.table_from_markdown(''' | colA | colB | colD 1 | valA | 1 | 3 2 | valA | 1 | 3 3 | valA | 1 | 3 4 | valB | 2 | 4 5 | valB | 2 | 5 6 | valB | 2 | 6 ''') result = t.groupby(t.colA).reduce(unique_B=pw.reducers.unique(t.colB)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
`result = t.groupby(t.colA).reduce(unique_D=pw.reducers.unique(t.colD)) try: pw.debug.compute_and_print(result, include_id=False) except Exception as e: print(type(e))`
Code Results
[API Docs\
\
Pathway Live Data Framework API](https://pathway.com/developers/api-docs/pathway)
[API Docs\
\
pw.sql](https://pathway.com/developers/api-docs/sql-api)
---
# pw.ml | Pathway
pw.ml
=====
> ⚠️ For a more complete suite of Machine Learning tools and capabilities, please explore our Enterprise version
[**knn\_lsh\_classifier\_train**(data, L, type='euclidean', \*\*kwargs)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.classifiers.knn_lsh_classifier_train)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/classifiers/_knn_lsh.py#L64-L97)
Build the LSH index over data. L the number of repetitions of the LSH scheme. Returns a LSH projector of type (queries: Table, k:Any) -> Table
[**knn\_lsh\_classify**(knn\_model, data\_labels, queries, k)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.classifiers.knn_lsh_classify)
----------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/classifiers/_knn_lsh.py#L318-L337)
Classify the queries. Use the knn\_model to extract the k closest datapoints. The queries are then labeled using a majority vote between the labels of the retrieved datapoints, using the labels provided in data\_labels.
[**knn\_lsh\_euclidean\_classifier\_train**(data, d, M, L, A)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.classifiers.knn_lsh_euclidean_classifier_train)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/classifiers/_knn_lsh.py#L305-L315)
Build the LSH index over data using the Euclidean distances. d is the dimension of the data, L the number of repetition of the LSH scheme, M and A are specific to LSH with Euclidean distance, M is the number of random projections done to create each bucket and A is the width of each bucket on each projection.
[**knn\_lsh\_generic\_classifier\_train**(data, lsh\_projection, distance\_function, L)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.classifiers.knn_lsh_generic_classifier_train)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/classifiers/_knn_lsh.py#L147-L302)
Build the LSH index over data using the a generic lsh\_projector and its associated distance. L the number of repetitions of the LSH scheme. Returns a LSH projector of type (queries: Table, k:Any) -> Table
[**knn\_lsh\_train**(data, L, type='euclidean', \*\*kwargs)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.classifiers.knn_lsh_train)
-----------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/classifiers/_knn_lsh.py#L64-L97)
Build the LSH index over data. L the number of repetitions of the LSH scheme. Returns a LSH projector of type (queries: Table, k:Any) -> Table
[class **KNNIndex**(data\_embedding, data, n\_dimensions, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean', metadata=None)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.index.KNNIndex)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/index.py#L9-L301)
An approximate K-Nearest Neighbors (KNN) index implementation using the Locality-Sensitive Hashing (LSH) algorithm within Pathway Live Data Framework. This index is designed to efficiently find the nearest neighbors of a given query embedding within a dataset. It is approximate in a sense that it might return less than k records per query or skip some closer points. If it returns not enough points too frequently, increase `bucket_length` accordingly. If it skips points too often, increase `n_or` or play with other parameters. Note that changing the parameters will influence the time and memory requirements.
* **Parameters**
* **data\_embedding** (`pw.ColumnExpression`) – The column expression representing embeddings in the data.
* **data** (`pw.Table`) – The table containing the data to be indexed.
* **n\_dimensions** (`int`) – number of dimensions in the data
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **metadata** (`pw.ColumnExpression`) – optional column expression representing dict of the metadata.
### [**get\_nearest\_items**(query\_embedding, k=3, collapse\_rows=True, with\_distances=False, metadata\_filter=None)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.index.KNNIndex.get_nearest_items)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/index.py#L54-L192)
This method queries the index with given queries and returns ‘k’ most relevant documents for each query in the stream. While using this method, documents associated with the queries will be updated if new more relevant documents appear. If you don’t want queries results to get updated in the future, take a look at get\_nearest\_items\_asof\_now.
* **Parameters**
* **query\_embedding** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – column of embedding vectors precomputed from the query.
* **k** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
| `int`) – The number of most relevant documents to return for each query. Can be constant for all queries or set per query. If you want to set `k` per query, pass a reference to the column. Defaults to 3.
* **collapse\_rows** (`bool`) – Determines the format of the output. If set to True, multiple rows corresponding to a single query will be collapsed into a single row, with each column containing a tuple of values from the original rows. If set to False, the output will retain the multi-row format for each query. Defaults to True.
* **with\_distances** (`bool`) – whether to output distances
* **metadata\_filter** (`pw.ColumnExpression`) – optional column expression containing evaluating to the text representing the metadata filtering query in the JMESPath format. The search will happen only for documents satisfying this filtering. Can be constant for all queries or set per query.
* **Returns**
pw.Table
* If `collapse_rows` is set to True: Returns a table where each row corresponds to a unique query.
Each column in the row contains a tuple (or list) of values, aggregating up to ‘k’ matches from the dataset. For example:
`| name | age ^YYY4HAB... | () | () ^X1MXHYY... | ('bluejay', 'cat', 'eagle') | (43, 42, 41)`
* If `collapse_rows` is set to False: Returns a table where each row represents a match from the dataset
for a given query. Multiple rows can correspond to the same query, up to ‘k’ matches. Example:
`name | age | embedding | query_id | | | ^YYY4HAB... bluejay | 43 | (4, 3, 2) | ^X1MXHYY... cat | 42 | (3, 3, 2) | ^X1MXHYY... eagle | 41 | (2, 3, 2) | ^X1MXHYY...`
Example:
`import pathway as pw from pathway.stdlib.ml.index import KNNIndex import pandas as pd class InputSchema(pw.Schema): document: str embeddings: list[float] metadata: dict documents = pw.debug.table_from_pandas( pd.DataFrame.from_records([ {"document": "document 1", "embeddings":[1,-1, 0], "metadata":{"foo": 1}}, {"document": "document 2", "embeddings":[1, 1, 0], "metadata":{"foo": 2}}, {"document": "document 3", "embeddings":[0, 0, 1], "metadata":{"foo": 3}}, ]), schema=InputSchema ) index = KNNIndex(documents.embeddings, documents, n_dimensions=3) queries = pw.debug.table_from_pandas( pd.DataFrame.from_records([ {"query": "What is doc 3 about?", "embeddings":[.1, .1, .1]}, {"query": "What is doc -5 about?", "embeddings":[-1, 10, -10]}, ]) ) relevant_docs = index.get_nearest_items(queries.embeddings, k=2).without(pw.this.metadata) pw.debug.compute_and_print(relevant_docs)`
Code Results
``index = KNNIndex(documents.embeddings, documents, n_dimensions=3, metadata=documents.metadata) relevant_docs_meta = index.get_nearest_items(queries.embeddings, k=2, metadata_filter="foo >= `3`") pw.debug.compute_and_print(relevant_docs_meta)``
Code Results
`data = pw.debug.table_from_markdown( ''' x | y | __time__ 2 | 3 | 2 0 | 0 | 2 2 | 2 | 6 -3 | 3 | 10 ''' ).select(coords=pw.make_tuple(pw.this.x, pw.this.y)) queries = pw.debug.table_from_markdown( ''' x | y | __time__ | __diff__ 1 | 1 | 4 | 1 -3 | 1 | 8 | 1 ''' ).select(coords=pw.make_tuple(pw.this.x, pw.this.y)) index = KNNIndex(data.coords, data, n_dimensions=2) answers = queries + index.get_nearest_items(queries.coords, k=2).select( nn=pw.this.coords ) pw.debug.compute_and_print_update_stream(answers, include_id=False)`
Code Results
### [**get\_nearest\_items\_asof\_now**(query\_embedding, k=3, collapse\_rows=True, with\_distances=False, metadata\_filter=None)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.index.KNNIndex.get_nearest_items_asof_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/index.py#L194-L258)
This method queries the index with given queries and returns ‘k’ most relevant documents for each query in the stream. The already answered queries are not updated in the future if new documents appear.
* **Parameters**
* **query\_embedding** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – column of embedding vectors precomputed from the query.
* **k** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
| `int`) – The number of most relevant documents to return for each query. Can be constant for all queries or set per query. If you want to set `k` per query, pass a reference to the column. Defaults to 3.
* **collapse\_rows** (`bool`) – Determines the format of the output. If set to True, multiple rows corresponding to a single query will be collapsed into a single row, with each column containing a tuple of values from the original rows. If set to False, the output will retain the multi-row format for each query. Defaults to True.
* **metadata\_filter** (`pw.ColumnExpression`) – optional column expression containing evaluating to the text representing the metadata filtering query in the JMESPath format. The search will happen only for documents satisfying this filtering. Can be constant for all queries or set per query.
Example:
`import pathway as pw from pathway.stdlib.ml.index import KNNIndex data = pw.debug.table_from_markdown( ''' x | y | __time__ 2 | 3 | 2 0 | 0 | 2 2 | 2 | 6 -3 | 3 | 10 ''' ).select(coords=pw.make_tuple(pw.this.x, pw.this.y)) queries = pw.debug.table_from_markdown( ''' x | y | __time__ | __diff__ 1 | 1 | 4 | 1 -3 | 1 | 8 | 1 ''' ).select(coords=pw.make_tuple(pw.this.x, pw.this.y)) index = KNNIndex(data.coords, data, n_dimensions=2) answers = queries + index.get_nearest_items_asof_now(queries.coords, k=2).select( nn=pw.this.coords ) pw.debug.compute_and_print_update_stream(answers, include_id=False)`
Code Results
[**create\_hmm\_reducer**(graph, beam\_size=None, num\_results\_kept=None)](https://pathway.com/developers/api-docs/ml#pathway.stdlib.ml.hmm.create_hmm_reducer)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ml/hmm.py#L15-L214)
Generates a reducer performing decoding of the Hidden Markov Model.
* **Parameters**
* **graph** (`DiGraph`) – directed graph representing the state transitions of the HMM.
* **beam\_size** (`int` | `None`) – limits the search. Defaults to None
* **num\_results\_kept** (`int` | `None`) – Maximum number of previous results returned. Defaults to None (keep all the results).
Example:
`import pathway as pw import networkx as nx from typing import Literal from functools import partial MANUL_STATES = Literal["HUNGRY", "FULL"] MANUL_OBSERVATIONS = Literal["GRUMPY", "HAPPY"] input_observations = pw.debug.table_from_markdown(''' observation | __time__ HAPPY | 1 HAPPY | 2 GRUMPY | 3 GRUMPY | 4 HAPPY | 5 GRUMPY | 6 ''') def get_manul_hmm() -> nx.DiGraph: g = nx.DiGraph() def _calc_emission_log_ppb( observation: MANUL_OBSERVATIONS, state: MANUL_STATES ) -> float: if state == "HUNGRY": if observation == "GRUMPY": return np.log(0.9) if observation == "HAPPY": return np.log(0.1) if state == "FULL": if observation == "GRUMPY": return np.log(0.7) if observation == "HAPPY": return np.log(0.3) g.add_node( "HUNGRY", calc_emission_log_ppb=partial(_calc_emission_log_ppb, state="HUNGRY") ) g.add_node( "FULL", calc_emission_log_ppb=partial(_calc_emission_log_ppb, state="FULL") ) g.add_edge("HUNGRY", "HUNGRY", log_transition_ppb=np.log(0.4)) g.add_edge("HUNGRY", "FULL", log_transition_ppb=np.log(0.6)) g.add_edge("FULL", "HUNGRY", log_transition_ppb=np.log(0.6)) g.add_edge("FULL", "FULL", log_transition_ppb=np.log(0.4)) g.graph["start_nodes"] = ["HUNGRY", "FULL"] return g hmm_reducer = pw.reducers.udf_reducer(pw.stdlib.ml.hmm.create_hmm_reducer(get_manul_hmm(), num_results_kept=3)) decoded = input_observations.reduce(decoded_state=hmm_reducer(pw.this.observation)) pw.debug.compute_and_print_update_stream(decoded, include_id=False)`
Code Results
[Pathway Io\
\
pw.io.weaviate](https://pathway.com/developers/api-docs/pathway-io/weaviate)
[API Docs\
\
pw.persistence](https://pathway.com/developers/api-docs/persistence-api)
---
# pw.udfs | Pathway
pw.udfs
=======
Methods and classes for controlling the behavior of UDFs (User-Defined Functions) in Pathway Live Data Framework.
Typical use:
`import pathway as pw import asyncio import time t = pw.debug.table_from_markdown( ''' a | b 1 | 2 3 | 4 5 | 6 ''' ) @pw.udf( executor=pw.udfs.async_executor( capacity=2, retry_strategy=pw.udfs.ExponentialBackoffRetryStrategy() ) ) async def long_running_async_function(a: int, b: int) -> int: await asyncio.sleep(0.1) return a * b result_1 = t.select(res=long_running_async_function(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result_1, include_id=False)`
Code Results
`@pw.udf(executor=pw.udfs.async_executor()) def long_running_function(a: int, b: int) -> int: time.sleep(0.1) return a * b result_2 = t.select(res=long_running_function(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result_2, include_id=False)`
Code Results
[class **AsyncRetryStrategy**](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.AsyncRetryStrategy)
--------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/retries.py#L42-L48)
Class representing strategy of delays or backoffs for the retries.
[class **CacheStrategy**](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.CacheStrategy)
----------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/caches.py#L23-L32)
Base class used to represent caching strategy.
[class **DefaultCache**(name=None, size\_limit=1073741824)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.DefaultCache)
-------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/caches.py#L108-L117)
The default caching strategy. Persistence layer will be used if enabled. Otherwise, cache will be disabled.
[class **DiskCache**(name=None, size\_limit=1073741824)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.DiskCache)
-------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/caches.py#L35-L105)
On disk cache.
[class **ExponentialBackoffRetryStrategy**(max\_retries=3, initial\_delay=1\_000, backoff\_factor=2, jitter\_ms=300)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.ExponentialBackoffRetryStrategy)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/retries.py#L58-L104)
Retry strategy with exponential backoff with jitter and maximum retries.
[class **FixedDelayRetryStrategy**(max\_retries=3, delay\_ms=1000)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.FixedDelayRetryStrategy)
--------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/retries.py#L107-L116)
Retry strategy with fixed delay and maximum retries.
[class **InMemoryCache**(max\_size=None)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.InMemoryCache)
--------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/caches.py#L120-L137)
In-memory LRU cache. It is not persisted between runs.
[class **NoRetryStrategy**](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.NoRetryStrategy)
--------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/retries.py#L51-L55)
[class **UDF**(\*, return\_type=..., deterministic=False, propagate\_none=False, executor=AutoExecutor(), cache\_strategy=None, max\_batch\_size=None)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.UDF)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/__init__.py#L68-L237)
Base class for Pathway Live Data Framework UDF (user-defined functions).
Please use the wrapper `udf` to create UDFs out of Python functions. Please subclass this class to define UDFs using Python classes. When subclassing this class, please implement the `__wrapped__` function.
Example:
`import pathway as pw table = pw.debug.table_from_markdown( ''' a | b 1 | 2 3 | 4 5 | 6 ''' ) class VerySophisticatedUDF(pw.UDF): exponent: float def __init__(self, exponent: float) -> None: super().__init__() self.exponent = exponent def __wrapped__(self, a: int, b: int) -> float: intermediate = (a * b) ** self.exponent return round(intermediate, 2) func = VerySophisticatedUDF(1.5) res = table.select(result=func(table.a, table.b)) pw.debug.compute_and_print(res, include_id=False)`
Code Results
[**async\_executor**(\*, capacity=None, timeout=None, retry\_strategy=None)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.async_executor)
--------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L152-L222)
Returns the asynchronous executor for Pathway Live Data Framework UDFs.
Can be applied to a regular or an asynchronous function. If applied to a regular function, it is executed in `asyncio` loop’s `run_in_executor`.
The asynchronous UDFs are asynchronous _within a single batch_ with batch defined as all entries with equal processing times assigned. The UDFs are started for all entries in the batch and the execution of further batches is blocked until all UDFs for a given batch have finished.
* **Parameters**
* **capacity** (`int` | `None`) – Maximum number of concurrent operations allowed. Defaults to None, indicating no specific limit.
* **timeout** (`float` | `None`) – Maximum time (in seconds) to wait for the function result. When both `timeout` and `retry_strategy` are used, timeout applies to a single retry. Defaults to None, indicating no time limit.
* **retry\_strategy** ([`AsyncRetryStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.AsyncRetryStrategy)
| `None`) – Strategy for handling retries in case of failures. Defaults to None, meaning no retries.
Example:
`import pathway as pw import asyncio import time t = pw.debug.table_from_markdown( ''' a | b 1 | 2 3 | 4 5 | 6 ''' ) @pw.udf( executor=pw.udfs.async_executor( capacity=2, retry_strategy=pw.udfs.ExponentialBackoffRetryStrategy() ) ) async def long_running_async_function(a: int, b: int) -> int: await asyncio.sleep(0.1) return a * b result_1 = t.select(res=long_running_async_function(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result_1, include_id=False)`
Code Results
`@pw.udf(executor=pw.udfs.async_executor()) def long_running_function(a: int, b: int) -> int: time.sleep(0.1) return a * b result_2 = t.select(res=long_running_function(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result_2, include_id=False)`
Code Results
[**async\_options**(capacity=None, timeout=None, retry\_strategy=None, cache\_strategy=None)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.async_options)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L387-L427)
Decorator applying async options to a provided function. Regular function will be wrapped to run in async executor.
* **Parameters**
* **capacity** (`int` | `None`) – Maximum number of concurrent operations. Defaults to None, indicating no specific limit.
* **timeout** (`float` | `None`) – Maximum time (in seconds) to wait for the function result. When both `timeout` and `retry_strategy` are used, timeout applies to a single retry. Defaults to None, indicating no time limit.
* **retry\_strategy** ([`AsyncRetryStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.AsyncRetryStrategy)
| `None`) – Strategy for handling retries in case of failures. Defaults to None, meaning no retries.
* **cache\_strategy** ([`CacheStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.CacheStrategy)
| `None`) – Defines the caching mechanism. If set to None and a persistency is enabled, operations will be cached using the persistence layer. Defaults to None.
* **Returns**
Coroutine
[**auto\_executor**()](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.auto_executor)
-------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L48-L91)
Returns the automatic executor of Pathway Live Data Framework UDF. It deduces whether the execution should be synchronous or asynchronous from the function signature. If the function is a coroutine, then the execution is asynchronous. Otherwise, it is synchronous.
Example:
`import pathway as pw import asyncio import time t = pw.debug.table_from_markdown( ''' a | b 1 | 2 3 | 4 5 | 6 ''' ) @pw.udf(executor=pw.udfs.auto_executor()) def mul(a: int, b: int) -> int: return a * b result_1 = t.select(res=mul(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result_1, include_id=False)`
Code Results
`@pw.udf(executor=pw.udfs.auto_executor()) async def long_running_async_function(a: int, b: int) -> int: await asyncio.sleep(0.1) return a * b result_2 = t.select(res=long_running_async_function(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result_2, include_id=False)`
Code Results
[**coerce\_async**(func)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.coerce_async)
---------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/utils.py#L17-L37)
Wraps a regular function to be executed in async executor. It acts as a noop if the provided function is already a coroutine.
[**fully\_async\_executor**(\*, capacity=None, timeout=None, retry\_strategy=None, autocommit\_duration\_ms=1500)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.fully_async_executor)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L237-L320)
Returns the fully asynchronous executor for Pathway Live Data Framework UDFs.
Can be applied to a regular or an asynchronous function. If applied to a regular function, it is executed in `asyncio` loop’s `run_in_executor`.
In contrast to regular asynchronous UDFs, these UDFs are fully asynchronous. It means that computations from the next batch can start even if the previous batch hasn’t finished yet. When a UDF is started, instead of a result, a special `Pending` value is emitted. When the function finishes, an update with the true return value is produced.
Using fully asynchronous UDFs allows processing time to advance even if the function doesn’t return. As a result downstream computations are not blocked.
The data type of column returned from the fully async UDF is `Future[return_type]` to allow for `Pending` values. Columns of this type can be propagated further, but can’t be used in most expressions (e.g. arithmetic operations). They can be passed to the next fully async UDF though. To strip the `Future` wrapper and wait for the result, you can use [`pathway.Table.await_futures()`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.await_futures)
method on [`pathway.Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
. In practice, it filters out the `Pending` values and produces a column with the data type as returned by the fully async UDF.
* **Parameters**
* **capacity** (`int` | `None`) – Maximum number of concurrent operations allowed. Defaults to None, indicating no specific limit.
* **timeout** (`float` | `None`) – Maximum time (in seconds) to wait for the function result. When both `timeout` and `retry_strategy` are used, timeout applies to a single retry. Defaults to None, indicating no time limit.
* **retry\_strategy** ([`AsyncRetryStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.AsyncRetryStrategy)
| `None`) – Strategy for handling retries in case of failures. Defaults to None, meaning no retries.
Example:
`import pathway as pw import asyncio t = pw.debug.table_from_markdown( ''' a | b | __time__ 1 | 2 | 2 3 | 4 | 4 5 | 6 | 4 ''' ) @pw.udf(executor=pw.udfs.fully_async_executor()) async def long_running_async_function(a: int, b: int) -> int: c = a * b await asyncio.sleep(0.1 * c) return c result = t.with_columns(res=long_running_async_function(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
`pw.debug.compute_and_print_update_stream(result, include_id=False)`
Code Results
[**sync\_executor**()](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.sync_executor)
-------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L104-L131)
Returns the synchronous executor for Pathway Live Data Framework UDFs.
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' a | b 1 | 2 3 | 4 5 | 6 ''' ) @pw.udf(executor=pw.udfs.sync_executor()) def mul(a: int, b: int) -> int: return a * b result = t.select(res=mul(pw.this.a, pw.this.b)) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**udf**(fun, /, \*, return\_type=Ellipsis, deterministic=False, propagate\_none=False, executor=AutoExecutor(), cache\_strategy=None, max\_batch\_size=None)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.udf)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/__init__.py#L324-L420)
Create a Python UDF (user-defined function) out of a callable.
Output column type deduced from type-annotations of a function. Can be applied to a regular or asynchronous function.
* **Parameters**
* **return\_type** (`Any`) – The return type of the function. Can be passed here or as a return type annotation. Defaults to `...`, meaning that the return type will be inferred from type annotation.
* **deterministic** (`bool`) – Whether the provided function is deterministic. In this context, it means that the function always returns the same value for the same arguments. If it is not deterministic, the Pathway Live Data Framework will memoize the results until the row deletion. If your function is deterministic, you’re **strongly encouraged** to set it to True as it will improve the performance. Defaults to False, meaning that the function is not deterministic and its results will be kept.
* **executor** (`Executor`) – Defines the executor of the UDF. It determines if the execution is synchronous or asynchronous. Defaults to AutoExecutor(), meaning that the execution strategy will be inferred from the function annotation. By default, if the function is a coroutine, then it is executed asynchronously. Otherwise it is executed synchronously.
* **cache\_strategy** ([`CacheStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.CacheStrategy)
| `None`) – Defines the caching mechanism. Defaults to None.
* **max\_batch\_size** (`int` | `None`) – If set, defines the maximal number of rows that can be passed to a UDF at once. Then each argument is a list of values and a UDF has to return a list with results with the same length as input lists. The result at position i has to be the result for input at position i.
Example:
`import pathway as pw import asyncio table = pw.debug.table_from_markdown( ''' age | owner | pet 10 | Alice | dog 9 | Bob | dog | Alice | cat 7 | Bob | dog ''' ) @pw.udf def concat(left: str, right: str) -> str: return left + "-" + right @pw.udf(propagate_none=True) def increment(age: int) -> int: assert age is not None return age + 1 res1 = table.select( owner_with_pet=concat(table.owner, table.pet), new_age=increment(table.age) ) pw.debug.compute_and_print(res1, include_id=False)`
Code Results
`@pw.udf async def sleeping_concat(left: str, right: str) -> str: await asyncio.sleep(0.1) return left + "-" + right res2 = table.select(col=sleeping_concat(table.owner, table.pet)) pw.debug.compute_and_print(res2, include_id=False)`
Code Results
[**with\_cache\_strategy**(func, cache\_strategy)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.with_cache_strategy)
-----------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/caches.py#L152-L168)
Returns a function with applied cache strategy.
* **Parameters**
**cache\_strategy** ([`CacheStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.CacheStrategy)
) – Defines the caching mechanism.
* **Returns**
Callable/Coroutine
[**with\_capacity**(func, capacity)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.with_capacity)
---------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L327-L350)
Limits the number of simultaneous calls of the specified function. Regular function will be wrapped to run in async executor.
* **Parameters**
**capacity** (`int`) – Maximum number of concurrent operations.
* **Returns**
Coroutine
[**with\_retry\_strategy**(func, retry\_strategy)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.with_retry_strategy)
-----------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/retries.py#L19-L39)
Returns an asynchronous function with applied retry strategy. Regular function will be wrapped to run in async executor.
* **Parameters**
**retry\_strategy** ([`AsyncRetryStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.AsyncRetryStrategy)
) – Defines how failures will be handled.
* **Returns**
Coroutine
[**with\_timeout**(func, timeout)](https://pathway.com/developers/api-docs/udfs/#pathway.udfs.with_timeout)
------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/udfs/executors.py#L353-L384)
Limits the time spent waiting on the result of the function. If the time limit is exceeded, the task is canceled and an Error is raised. Regular function will be wrapped to run in async executor.
* **Parameters**
**timeout** (`float`) – Maximum time (in seconds) to wait for the function result. Defaults to None, indicating no time limit.
* **Returns**
Coroutine
[API Docs\
\
pw.temporal](https://pathway.com/developers/api-docs/temporal)
[API Docs\
\
pw.xpacks.connectors](https://pathway.com/developers/api-docs/pathway-xpacks-sharepoint)
---
# Pathway Live Data Framework Templates
Pathway Live Data Framework Templates
=====================================
**Pathway Live Data Framework's Application templates allow you to quickly put into production AI and ETL applications which offer high-accuracy RAG at scale using the most up-to-date knowledge available in your data sources.**
The Pathway Live Data Framework Templates are ready-to-deploy ETL and RAG pipelines built on the Pathway Live Data Framework, offering scalable, real-time data processing and AI-driven search capabilities through YAML and Python templates. They are designed for easy deployment and customization by both developers and non-developers. Get started by picking a template or visiting the [Run a Template page](https://pathway.com/developers/templates/run-a-template)
.
**Pick one and run the app with your own data, in minutes.**
[RAG Templates](https://pathway.com/developers/templates#ai-pipelines)
[YAML\
\
\
\
Question-Answering RAG App\
\
Basic end-to-end RAG app. A question-answering pipeline that uses the GPT model of choice to provide answers to queries to your documents (PDF, DOCX,...) on a live connected data source (files, Google Drive, Sharepoint,...).\
\
Basic end-to-end RAG app. A question-answering pipeline that uses the GPT model of choice to provide answers to queries to your documents (PDF, DOCX,...) on a live connected data source (files, Google Drive, Sharepoint,...).\
\
Featured](https://pathway.com/developers/templates/rag/demo-question-answering)
[YAML\
\
\
\
Adaptive RAG App\
\
A RAG application using Adaptive RAG, a technique developed by Pathway to reduce token cost in RAG up to 4x while maintaining accuracy.\
\
A RAG application using Adaptive RAG, a technique developed by Pathway to reduce token cost in RAG up to 4x while maintaining accuracy.](https://pathway.com/developers/templates/rag/template-adaptive-rag)
[YAML\
\
\
\
Private RAG App with Mistral and Ollama\
\
A fully private (local) version of the Question-Answering RAG pipeline using Pathway, Mistral, and Ollama.\
\
A fully private (local) version of the Question-Answering RAG pipeline using Pathway, Mistral, and Ollama.](https://pathway.com/developers/templates/rag/template-private-rag)
[YAML\
\
\
\
Multimodal RAG pipeline with GPT4o\
\
Multimodal RAG using GPT-4o in the parsing stage to index PDFs and other documents from a connected data source files, Google Drive, Sharepoint,...). It is perfect for extracting information from unstructured financial documents in your folders (including charts and tables), updating results as documents change or new ones arrive.\
\
Multimodal RAG using GPT-4o in the parsing stage to index PDFs and other documents from a connected data source files, Google Drive, Sharepoint,...). It is perfect for extracting information from unstructured financial documents in your folders (including charts and tables), updating results as documents change or new ones arrive.\
\
Featured](https://pathway.com/developers/templates/rag/template-multimodal-rag)
[YAML\
\
\
\
Live Document Indexing (Vector Store / Retriever)\
\
A real-time document indexing pipeline for RAG that acts as a vector store service. It performs live indexing on your documents (PDF, DOCX,...) from a connected data source (files, Google Drive, Sharepoint,...). It can be used with any frontend, or integrated as a retriever backend for a Langchain or Llamaindex application.\
\
A real-time document indexing pipeline for RAG that acts as a vector store service. It performs live indexing on your documents (PDF, DOCX,...) from a connected data source (files, Google Drive, Sharepoint,...). It can be used with any frontend, or integrated as a retriever backend for a Langchain or Llamaindex application.](https://pathway.com/developers/templates/rag/template-demo-document-indexing)
[YAML\
\
\
\
Slides AI Search App\
\
An indexing pipeline for retrieving slides. It performs multi-modal of PowerPoint and PDF and maintains live index of your slides.\
\
An indexing pipeline for retrieving slides. It performs multi-modal of PowerPoint and PDF and maintains live index of your slides.](https://pathway.com/developers/templates/rag/template-slides-search)
[\
\
Pathway Live Data Framework + PostgreSQL + LLM: app for querying financial reports with live document structuring pipeline.\
\
A RAG example which connects to unstructured financial data sources (financial report PDFs), structures the data into SQL, and loads it into a PostgreSQL table. It also answers natural language user queries to these financial documents by translating them into SQL using an LLM and executing the query on the PostgreSQL table.\
\
A RAG example which connects to unstructured financial data sources (financial report PDFs), structures the data into SQL, and loads it into a PostgreSQL table. It also answers natural language user queries to these financial documents by translating them into SQL using an LLM and executing the query on the PostgreSQL table.](https://pathway.com/developers/templates/rag/unstructured-to-structured)
* * *
Filter App Templates
Docker
Notebook
Live Data Pipeline
Machine Learning
Time Series
[Live Data pipeline](https://pathway.com/developers/templates#data-pipeline)
[YAML\
\
\
\
EL Pipeline: Move your data around with Pathway\
\
Use Pathway Live Data Framework EL YAML Template for easy data movement\
\
Use Pathway Live Data Framework EL YAML Template for easy data movement\
\
Featured](https://pathway.com/developers/templates/etl/el-pipeline)
[\
\
Kafka ETL: Processing event streams in Python\
\
Learn how to build a Kafka ETL pipeline in Python with the Pathway Live Data Framework and process event streams in real-time.\
\
Learn how to build a Kafka ETL pipeline in Python with the Pathway Live Data Framework and process event streams in real-time.\
\
Featured](https://pathway.com/developers/templates/etl/kafka-etl)
[\
\
Jupyter / Colab: visualizing and transforming live data streams in Python notebooks with Pathway Live Data Framework\
\
Featured](https://pathway.com/developers/templates/etl/live_data_jupyter)
[\
\
Deploy to AWS Cloud\
\
How to deploy the Pathway Live Data Framework in the cloud with AWS Fargate\
\
How to deploy the Pathway Live Data Framework in the cloud with AWS Fargate](https://pathway.com/developers/templates/deploy/aws-fargate-deploy)
[\
\
Deploy to Azure\
\
How to deploy the Pathway Live Data Framework in the cloud within Azure ecosystem\
\
How to deploy the Pathway Live Data Framework in the cloud within Azure ecosystem](https://pathway.com/developers/templates/deploy/azure-aci-deploy)
[\
\
Computing the Option Greeks using Pathway Live Data Framework and Databento\
\
Computing the Option Greeks using the Pathway Live Data Framework and Databento, in the Black Model\
\
Computing the Option Greeks using the Pathway Live Data Framework and Databento, in the Black Model](https://pathway.com/developers/templates/etl/option-greeks)
[\
\
Automating reconciliation of messy financial transaction logs using the Pathway Live Data Framework real-time fuzzy join\
\
Article introducing Fuzzy Join.](https://pathway.com/developers/templates/etl/fuzzy_join_chapter1)
[\
\
Interaction with a Feedback Loop.\
\
Article introducing Fuzzy Join.](https://pathway.com/developers/templates/etl/fuzzy_join_chapter2)
[\
\
Smart real-time monitoring application with alert deduplication\
\
Event stream processing](https://pathway.com/developers/templates/etl/alerting-significant-changes)
[\
\
Streaming ETL pipelines in Python with Airbyte and Pathway\
\
How to use Pathway for Airbyte sources.](https://pathway.com/developers/templates/etl/etl-python-airbyte)
[\
\
Delta Lake ETL with Pathway Live Data Framework for Spark Analytics\
\
How to use the Pathway Live Data Framework to prepare unstructured data for Spark analytics\
\
How to use the Pathway Live Data Framework to prepare unstructured data for Spark analytics](https://pathway.com/developers/templates/etl/delta_lake_etl)
[\
\
Python Kafka Alternative: Achieve Sub-Second Latency with your S3 Storage without Kafka using Pathway\
\
If you're searching for Kafka alternatives, this article explains how to use Pathway and MinIO+Delta Tables for a simple real-time processing pipeline without using the Confluent stack.\
\
If you're searching for Kafka alternatives, this article explains how to use Pathway and MinIO+Delta Tables for a simple real-time processing pipeline without using the Confluent stack.](https://pathway.com/developers/templates/etl/kafka-alternative)
[\
\
Out-of-Order Event Streams: Calculating Time Deltas with grouping by topic\
\
Event stream processing](https://pathway.com/developers/templates/etl/event_stream_processing_time_between_occurrences)
[\
\
Uncovering hidden user relationships in crypto exchanges with Fuzzy Join on streaming data\
\
An example of a cryptocurrency exchange](https://pathway.com/developers/templates/etl/user_pairs_fuzzy_join)
[\
\
Linear regression on a Kafka stream](https://pathway.com/developers/templates/etl/linear_regression_with_kafka)
[\
\
Realtime Server Log Monitoring: nginx + Filebeat + Pathway\
\
Monitor your server logs in real time with the Pathway Live Data Framework\
\
Monitor your server logs in real time with the Pathway Live Data Framework](https://pathway.com/developers/templates/etl/realtime-log-monitoring)
[Machine Learning](https://pathway.com/developers/templates#machine-learning)
[\
\
Real-Time Anomaly Detection: identifying brute-force logins using Tumbling Windows\
\
Detecting suspicious login attempts](https://pathway.com/developers/templates/etl/suspicious_activity_tumbling_window)
[\
\
Real-Time Twitter Sentiment Analysis and Prediction App with Pathway Live Data Framework\
\
Pathway Twitter showcase](https://pathway.com/developers/templates/etl/twitter)
[\
\
Adaptive Classifiers: Evolving Predictions with Real-Time Data\
\
Pathway Live Data Framework Showcase: kNN+LSH classifier\
\
Pathway Live Data Framework Showcase: kNN+LSH classifier](https://pathway.com/developers/templates/etl/lsh_chapter1)
[\
\
Pathway Live Data Framework Logistics Application: Streamlined Insights for Real-Time Asset Management\
\
Pathway Live Data Framework Logistics Showcase](https://pathway.com/developers/templates/etl/logistics)
[\
\
Real-Time Shortest Paths on Dynamic Networks with Bellman-Ford in Pathway Live Data Framework\
\
Article explaining step-by-step how to implement the Bellman-Ford algorithm in the Pathway Live Data Framework.\
\
Article explaining step-by-step how to implement the Bellman-Ford algorithm in the Pathway Live Data Framework.](https://pathway.com/developers/templates/etl/bellman_ford)
[\
\
Real-Time PageRank on Dynamic Graphs with Pathway Live Data Framework\
\
Demonstration of a PageRank computation](https://pathway.com/developers/templates/etl/pagerank)
[time series](https://pathway.com/developers/templates#time-series)
[\
\
Signal Processing with Real-time Upsampling: combining multiple time series data streams.\
\
Tutorial on signal processing: how to do upsampling with Pathway Live Data Framework using windowby and intervals\_over\
\
Tutorial on signal processing: how to do upsampling with Pathway Live Data Framework using windowby and intervals\_over\
\
Featured](https://pathway.com/developers/templates/etl/upsampling)
[\
\
Gaussian Filtering in Real-time: Signal processing with out-of-order data streams\
\
Tutorial on signal processing: how to apply a Gaussian filter with Pathway Live Data Framework using windowby and intervals\_over\
\
Tutorial on signal processing: how to apply a Gaussian filter with Pathway Live Data Framework using windowby and intervals\_over](https://pathway.com/developers/templates/etl/gaussian_filtering_python)
[\
\
Sensor Fusion in real-time: combining time series data with Pathway Live Data Framework\
\
Learn how to combine between two time series with different timestamps in the Pathway Live Data Framework.\
\
Learn how to combine between two time series with different timestamps in the Pathway Live Data Framework.](https://pathway.com/developers/templates/etl/combining_time_series)
[API Docs\
\
pw.persistence](https://pathway.com/developers/api-docs/persistence-api)
[Templates\
\
Run a template](https://pathway.com/developers/templates/run-a-template)
---
# pathway.stdlib.indexing package
pathway.stdlib.indexing package
===============================
[class **BruteForceKnn**(data\_column, metadata\_column, \*, dimensions, reserved\_space, auxiliary\_space=131072, metric, embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L169-L258)
Interface for a brute force implementation of a nearest neighbors index.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **auxiliary\_space** (`int`) – auxiliary space (in the number of entries), the maximum number of distances that are stored in memory, while evaluating queries, in case `auxiliary_space` is set to a value smaller than the current number of entries in the index, it is still proportional to the size of the index (the value given in this parameter is ignored)
* **metric** ([`BruteForceKnnMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
) – metric kind that is used to determine distance
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L206-L215)
Currently, brute force knn index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L217-L258)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **BruteForceKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, auxiliary\_space=131072, metric=)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L485-L528)
Factory for creating BruteForceKnn indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries. This is only needed if the embedder is not provided.
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **auxiliary\_space** (`int`) – auxiliary space (in the number of entries), the maximum number of distances that are stored in memory, while evaluating queries, in case `auxiliary_space` is set to a value smaller than the current number of entries in the index, it is still proportional to the size of the index (the value given in this parameter is ignored)
* **metric** ([`BruteForceKnnMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
) – metric kind that is used to determine distance. Defaults to cosine similarity.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **BruteForceKnnMetricKind**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
-----------------------------------------------------------------------------------------------------------------------------------------------------
Used for choosing the metric used in the BruteForceKnn index.
### [**L2SQ**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind.L2SQ)
Squared Euclidean distance.
### [**COS**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind.COS)
Cosine distance.
[class **DataIndex**(data\_table, inner\_index)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
----------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L277-L473)
A class that given an implementation of an index provides methods that augment the search results with supplementary data.
* **Parameters**
* **data\_table** (`pw.Table`) – table containing supplementary data, using match-by-id ( ID from data\_table and ID from the response of `inner_index`)
* **inner\_index** ([`InnerIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)
) – a data structure that accepts data from some `data_column` and for each query answers with a list of IDs, one ID per matched row from `data_column`. The IDs are taken from the table that contains the `data_column` column
### [**query**(query\_column, \*, number\_of\_matches=3, collapse\_rows=True, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L349-L410)
This method takes the query from `query_column`, optionally applies `self.embedder` on it and passes it to inner index to obtain matching entries stored in the `InnerIndex` (being a match depends on the implementation and the internal state of the `InnerIndex`).
For each query and for each column in `self.data_table` it computes a tuple of values that are in the rows that have IDs indicated by the response of the `InnerIndex`. It returns a [`JoinResult`](https://pathway.com/developers/api-docs/pathway#pathway.JoinResult)
of a left join between query table (a table that holds `query_column`) and the mentioned table of tuples (exactly one row per query, with values not present if set of matching IDs is empty).
Optionally, the method can skip the tupling step, and return a `JoinResult` of a left join between query table, and `self.data_table`, using the result of `InnerIndex` to indicate when the IDs match (exactly one row per match plus one row per query with no matches).
The answers to the old queries are updated when the state of the index changes. To work properly, the `inner_index` has to be an instance of `InnerIndex` supporting `query`.
* **Parameters**
* **query\_column** (`pw.ColumnReference`) – A column containing the queries, needs to be in the format compatible with `self.inner_index` (or `self.embedder`).
* **number\_of\_matches** (`pw.ColumnExpression | int`) – The maximum number of matches returned for each query.
* **collapse\_rows** (`bool`) – Indicates the format of the output. If set to `True`, the resulting table has exactly one row for each query, each column of the right side of the resulting `JoinResult` contains a tuple consisting of values from matched rows of corresponding column in `self.data_table`. If set to `False`, the result is a left join between the table holding the `query_column` and `self.data_index`, using the results from `self.inner_index` to indicate the matches between the IDs.
* **metadata\_filter** (`pw.ColumnExpression [str | None] | pw.ColumnExpression [str] | None`) – Optional, contains a boolean JMESPath query that is used to filter the potential answers inside `self.inner_index` - matching entries are included only when the filter function specified in metadata\_filter\` returns `True`, when run against data in `inner_index.metadata_column`, in a potentially matched row. Passing `None` as value in the column defined in the parameter `metadata_filter` indicates that all possible matches corresponding to this query pass the filtering step.
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, collapse\_rows=True, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L412-L473)
This method takes the query from `query_column`, optionally applies self.embedder on it and passes it to inner index to obtain matching entries stored in the `InnerIndex` (being a match depends on the implementation and the internal state of the `InnerIndex`).
For each query and for each column in `self.data_table` it computes a tuple of values that are in the rows that have IDs indicated by the response of the `InnerIndex`. It returns a [`JoinResult`](https://pathway.com/developers/api-docs/pathway#pathway.JoinResult)
of a left join between query table (a table that holds `query_column`) and the mentioned table of tuples (exactly one row per query, with values not present if set of matching IDs is empty).
Optionally, the method can skip the tupling step, and return a `JoinResult` of a left join between query table, and self.data\_table, using the result of `InnerIndex` to indicate when the IDs match (exactly one row per match plus one row per query with no matches).
The index answers according to the current state of the data structure and does not revisit old answers. To work properly, the `inner_index` has to be an instance of `InnerIndex` supporting `query` (all predefined indices support it, this is an information for third party extensions).
* **Parameters**
* **query\_column** (`pw.ColumnReference`) – A column containing the queries, needs to be in the format compatible with `self.inner_index` (or `self.embedder`).
* **number\_of\_matches** (`pw.ColumnExpression | int`) – The maximum number of matches returned for each query.
* **collapse\_rows** (`bool`) – Indicates the format of the output. If set to `True`, the resulting table has exactly one row for each query, each column of the right side of the resulting `JoinResult` contains a tuple consisting of values from matched rows of corresponding column in self.data\_table. If set to `False`, the result is a left join between the table holding the `query_column` and `self.data_index`, using the results from `self.inner_index` to indicate the matches between the IDs.
* **metadata\_filter** (`pw.ColumnExpression [str | None] | pw.ColumnExpression [str] | None`) – Optional, contains a boolean JMESPath query that is used to filter the potential answers inside `self.inner_index` - matching entries are included only when the filter function specified in metadata\_filter\` returns `True`, when run against data in `inner_index.metadata_column`, in a potentially matched row. Passing `None` as value in the column defined in the parameter `metadata_filter` indicates that all possible matches corresponding to this query pass the filtering step.
[class **DefaultKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, auxiliary\_space=131072, metric=)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DefaultKnnFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L573-L586)
Default factory for creating Knn index - uses the BruteForceKnn index.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **HybridIndex**(retrievers, k=60)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.HybridIndex)
-----------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L14-L158)
Hybrid Index that composes any number of other indices and combines them using the Reciprocal Rank Fusion (RRF). It queries each index, and each retrieved row `d` is assigned score `1/(k+rank(d))`, which is then summed over all indices. `HybridIndex` returns best rows from indexed data according to this score.
* **Parameters**
* **retrievers** (`list`\[[`InnerIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)\
\]) – list of indices to be used to compose the hybrid index.
* **k** (`float`) – constant used for calculating ranking score.
### [**query**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.HybridIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L124-L140)
An abstract method. Any implementation of `query` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
Whenever the index changes (via new entries in self.data\_column), it should adjust all old answers to the queries (which is a default behavior of pathway code, as long as it does not use operators telling that it is not the case).
The resulting table with results needs contain a column `_pw_index_reply` (name defined in `_INDEX_REPLY`), in which the resulting tuples are stored.
### [**query\_as\_of\_now**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.HybridIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L142-L158)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **HybridIndexFactory**(retriever\_factories, k=60)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.HybridIndexFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L161-L188)
Factory for creating hybrid indices.
* **Parameters**
* **retriever\_factories** (`list`\[`InnerIndexFactory`\]) – list of factories of indices that will be used in the hybrid index
* **k** (`float`) – constant used for calculating ranking score.
[class **LshKnn**(data\_column, metadata\_column, \*, dimensions, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean', embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L261-L403)
Interface for Pathway Live Data Framework’s implementation of KNN via LSH.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of metadata as dictionary, in JSON format.
* **dimensions** (`int`) – number of dimensions in the data
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L319-L378)
* **Parameters**
* **query\_column** (`pw.ColumnExpression`) – column containing data that is used to query the index;
* **number\_of\_matches** (`pw.ColumnExpression [int] | int`) – number of nearest neighbors in the index response; defaults to 3
* **metadata\_filter** (`pw.ColumnExpression [str] | None`) – optional, column expression evaluating to the text representation of a boolean JMESPath query. The index will consider only the entries with metadata that satisfies the condition in the filter.
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L380-L403)
* **Parameters**
* **query\_column** (`pw.ColumnExpression`) – column containing data that is used to query the index;
* **number\_of\_matches** (`pw.ColumnExpression[int] | int`) – number of nearest neighbors in the index response; defaults to 3
* **metadata\_filter** (`pw.ColumnExpression [str] | None`) – optional, column expression evaluating to the text representation of a boolean JMESPath query. The index will consider only the entries with metadata that satisfies the condition in the filter.
[class **LshKnnFactory**(\*, dimensions=None, embedder=None, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean')](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnnFactory)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L531-L570)
Factory for creating LshKnn indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions in the data. This is only needed if the embedder is not provided.
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **TantivyBM25**(data\_column, metadata\_column, ram\_budget=52428800, in\_memory\_index=True)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.TantivyBM25)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L40-L105)
Interface for full text index based on [BM25](https://en.wikipedia.org/wiki/Okapi_BM25)
, provided via [tantivy](https://github.com/quickwit-oss/tantivy)
.
* **Parameters**
* **data\_column** (`pw.ColumnExpression[str]`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression[str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **ram\_budget** (`int`) – maximum capacity in bytes. When reached, the index moves a block of data to storage (hence, larger budget means faster index operations, but higher memory cost)
* **in\_memory\_index** (`bool`) – indicates, whether the whole index is stored in RAM; if set to false, the index is stored in some default Pathway Live Data Framework disk storage
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.TantivyBM25.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L60-L69)
Currently, tantivy bm25 index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.TantivyBM25.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L71-L105)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **TantivyBM25Factory**(ram\_budget=52428800, in\_memory\_index=True)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.TantivyBM25Factory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L108-L135)
Factory for creating a TantivyBM25 index.
* **Parameters**
* **ram\_budget** (`int`) – maximum capacity in bytes. When reached, the index moves a block of data to storage (hence, larger budget means faster index operations, but higher memory cost)
* **in\_memory\_index** (`bool`) – indicates, whether the whole index is stored in RAM; if set to false, the index is stored in some default Pathway Live Data Framework disk storage
[class **USearchKnn**(data\_column, metadata\_column, \*, dimensions, reserved\_space, metric, connectivity=0, expansion\_add=0, expansion\_search=0, embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L64-L166)
Interface for usearch nearest neighbors index, an implementation of k nearest neighbors based on HNSW algorithm [white paper](https://arxiv.org/abs/1603.09320)
.
To understand meaning of the explanation of some of the parameters, you might need some familiarity with either [HNSW algorithm](https://arxiv.org/abs/1603.09320)
or its implementation provided by [USearch](https://github.com/unum-cloud/usearch)
.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **metric** ([`USearchMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
) – metric kind that is used to determine distance
* **connectivity** (`int`) – maximum number of edges for a node in the HNSW index, setting this value to 0 tells usearch to configure it on its own
* **expansion\_add** (`int`) – indicates amount of work spent while adding elements to the index (higher = more accurate placement, more work), setting this value to 0 tells usearch to configure it on its own
* **expansion\_search** (`int`) – indicates amount of work spent while searching for elements in the index (higher = more accurate results, more work), setting this value to 0 tells usearch to configure it on its own
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L112-L121)
Currently, usearch knn index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L123-L166)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **USearchMetricKind**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
-----------------------------------------------------------------------------------------------------------------------------------------
Used for choosing the metric used in the USearchKnn index. As these correspond to values of MetricKind from the usearch crate, you can find more information about them in the [usearch documentation](https://docs.rs/usearch/latest/usearch/ffi/struct.MetricKind.html)
.
### [**IP**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.IP)
Inner Product distance.
### [**L2SQ**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.L2SQ)
Squared Euclidean distance.
### [**COS**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.COS)
Cosine distance.
### [**PEARSON**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.PEARSON)
Pearson distance.
### [**HAVERSINE**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.HAVERSINE)
Haversine distance.
### [**DIVERGENCE**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.DIVERGENCE)
Jensen Shannon Divergence distance.
### [**HAMMING**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.HAMMING)
Hamming distance.
### [**TANIMOTO**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.TANIMOTO)
Tanimoto distance.
### [**SORENSEN**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind.SORENSEN)
Sorensen distance.
[class **UsearchKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, metric=, connectivity=0, expansion\_add=0, expansion\_search=0)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.UsearchKnnFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L431-L482)
Factory for creating UsearchKNN indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries. This is only needed if the embedder is not provided.
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **metric** ([`USearchMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
) – metric kind that is used to determine distance. Defaults to cosine similarity.
* **connectivity** (`int`) – maximum number of edges for a node in the HNSW index, setting this value to 0 tells usearch to configure it on its own
* **expansion\_add** (`int`) – indicates amount of work spent while adding elements to the index (higher = more accurate placement, more work), setting this value to 0 tells usearch to configure it on its own
* **expansion\_search** (`int`) – indicates amount of work spent while searching for elements in the index (higher = more accurate results, more work), setting this value to 0 tells usearch to configure it on its own
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[**default\_brute\_force\_knn\_document\_index**(data\_column, data\_table, dimensions, \*, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.default_brute_force_knn_document_index)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L154-L196)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
. This method chooses some parameters of `BruteForceKnn` arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
to see the parameters that can be adjusted.
[**default\_full\_text\_document\_index**(data\_column, data\_table, \*, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.default_full_text_document_index)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/full_text_document_index.py#L8-L26)
Returns an instance of DataIndex ([`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
), with inner index (data structure) of our choosing. This method chooses an arbitrary implementation of `InnerIndex` (that supports text queries), but it’s not necessarily the best choice of index and its parameters (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project etc.
[**default\_lsh\_knn\_document\_index**(data\_column, data\_table, \*, dimensions, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.default_lsh_knn_document_index)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L66-L105)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
. This method chooses some parameters of LshKnn arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
to see the parameters that can be adjusted.
[**default\_usearch\_knn\_document\_index**(data\_column, data\_table, dimensions, \*, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.default_usearch_knn_document_index)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L108-L151)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
. This method chooses some parameters of USearchKnn arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
to see the parameters that can be adjusted.
[**default\_vector\_document\_index**(data\_column, data\_table, \*, dimensions, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.default_vector_document_index)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L34-L63)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) of our choosing. This method chooses an arbitrary implementation of `InnerIndex` (that supports queries on vectors), but it’s not necessarily the best choice of index and its parameters (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project etc.
[Submodules](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#submodules)
-----------------------------------------------------------------------------------------
[pathway.stdlib.indexing.bm25 module](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathwaystdlibindexingbm25-module)
----------------------------------------------------------------------------------------------------------------------------------------
[class **TantivyBM25**(data\_column, metadata\_column, ram\_budget=52428800, in\_memory\_index=True)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.bm25.TantivyBM25)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L40-L105)
Interface for full text index based on [BM25](https://en.wikipedia.org/wiki/Okapi_BM25)
, provided via [tantivy](https://github.com/quickwit-oss/tantivy)
.
* **Parameters**
* **data\_column** (`pw.ColumnExpression[str]`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression[str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **ram\_budget** (`int`) – maximum capacity in bytes. When reached, the index moves a block of data to storage (hence, larger budget means faster index operations, but higher memory cost)
* **in\_memory\_index** (`bool`) – indicates, whether the whole index is stored in RAM; if set to false, the index is stored in some default Pathway Live Data Framework disk storage
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.bm25.TantivyBM25.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L60-L69)
Currently, tantivy bm25 index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.bm25.TantivyBM25.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L71-L105)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **TantivyBM25Factory**(ram\_budget=52428800, in\_memory\_index=True)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.bm25.TantivyBM25Factory)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/bm25.py#L108-L135)
Factory for creating a TantivyBM25 index.
* **Parameters**
* **ram\_budget** (`int`) – maximum capacity in bytes. When reached, the index moves a block of data to storage (hence, larger budget means faster index operations, but higher memory cost)
* **in\_memory\_index** (`bool`) – indicates, whether the whole index is stored in RAM; if set to false, the index is stored in some default Pathway Live Data Framework disk storage
[pathway.stdlib.indexing.data\_index module](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathwaystdlibindexingdata_index-module)
-----------------------------------------------------------------------------------------------------------------------------------------------------
[class **DataIndex**(data\_table, inner\_index)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.DataIndex)
---------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L277-L473)
A class that given an implementation of an index provides methods that augment the search results with supplementary data.
* **Parameters**
* **data\_table** (`pw.Table`) – table containing supplementary data, using match-by-id ( ID from data\_table and ID from the response of `inner_index`)
* **inner\_index** ([`InnerIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)
) – a data structure that accepts data from some `data_column` and for each query answers with a list of IDs, one ID per matched row from `data_column`. The IDs are taken from the table that contains the `data_column` column
### [**query**(query\_column, \*, number\_of\_matches=3, collapse\_rows=True, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.DataIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L349-L410)
This method takes the query from `query_column`, optionally applies `self.embedder` on it and passes it to inner index to obtain matching entries stored in the `InnerIndex` (being a match depends on the implementation and the internal state of the `InnerIndex`).
For each query and for each column in `self.data_table` it computes a tuple of values that are in the rows that have IDs indicated by the response of the `InnerIndex`. It returns a [`JoinResult`](https://pathway.com/developers/api-docs/pathway#pathway.JoinResult)
of a left join between query table (a table that holds `query_column`) and the mentioned table of tuples (exactly one row per query, with values not present if set of matching IDs is empty).
Optionally, the method can skip the tupling step, and return a `JoinResult` of a left join between query table, and `self.data_table`, using the result of `InnerIndex` to indicate when the IDs match (exactly one row per match plus one row per query with no matches).
The answers to the old queries are updated when the state of the index changes. To work properly, the `inner_index` has to be an instance of `InnerIndex` supporting `query`.
* **Parameters**
* **query\_column** (`pw.ColumnReference`) – A column containing the queries, needs to be in the format compatible with `self.inner_index` (or `self.embedder`).
* **number\_of\_matches** (`pw.ColumnExpression | int`) – The maximum number of matches returned for each query.
* **collapse\_rows** (`bool`) – Indicates the format of the output. If set to `True`, the resulting table has exactly one row for each query, each column of the right side of the resulting `JoinResult` contains a tuple consisting of values from matched rows of corresponding column in `self.data_table`. If set to `False`, the result is a left join between the table holding the `query_column` and `self.data_index`, using the results from `self.inner_index` to indicate the matches between the IDs.
* **metadata\_filter** (`pw.ColumnExpression [str | None] | pw.ColumnExpression [str] | None`) – Optional, contains a boolean JMESPath query that is used to filter the potential answers inside `self.inner_index` - matching entries are included only when the filter function specified in metadata\_filter\` returns `True`, when run against data in `inner_index.metadata_column`, in a potentially matched row. Passing `None` as value in the column defined in the parameter `metadata_filter` indicates that all possible matches corresponding to this query pass the filtering step.
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, collapse\_rows=True, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.DataIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L412-L473)
This method takes the query from `query_column`, optionally applies self.embedder on it and passes it to inner index to obtain matching entries stored in the `InnerIndex` (being a match depends on the implementation and the internal state of the `InnerIndex`).
For each query and for each column in `self.data_table` it computes a tuple of values that are in the rows that have IDs indicated by the response of the `InnerIndex`. It returns a [`JoinResult`](https://pathway.com/developers/api-docs/pathway#pathway.JoinResult)
of a left join between query table (a table that holds `query_column`) and the mentioned table of tuples (exactly one row per query, with values not present if set of matching IDs is empty).
Optionally, the method can skip the tupling step, and return a `JoinResult` of a left join between query table, and self.data\_table, using the result of `InnerIndex` to indicate when the IDs match (exactly one row per match plus one row per query with no matches).
The index answers according to the current state of the data structure and does not revisit old answers. To work properly, the `inner_index` has to be an instance of `InnerIndex` supporting `query` (all predefined indices support it, this is an information for third party extensions).
* **Parameters**
* **query\_column** (`pw.ColumnReference`) – A column containing the queries, needs to be in the format compatible with `self.inner_index` (or `self.embedder`).
* **number\_of\_matches** (`pw.ColumnExpression | int`) – The maximum number of matches returned for each query.
* **collapse\_rows** (`bool`) – Indicates the format of the output. If set to `True`, the resulting table has exactly one row for each query, each column of the right side of the resulting `JoinResult` contains a tuple consisting of values from matched rows of corresponding column in self.data\_table. If set to `False`, the result is a left join between the table holding the `query_column` and `self.data_index`, using the results from `self.inner_index` to indicate the matches between the IDs.
* **metadata\_filter** (`pw.ColumnExpression [str | None] | pw.ColumnExpression [str] | None`) – Optional, contains a boolean JMESPath query that is used to filter the potential answers inside `self.inner_index` - matching entries are included only when the filter function specified in metadata\_filter\` returns `True`, when run against data in `inner_index.metadata_column`, in a potentially matched row. Passing `None` as value in the column defined in the parameter `metadata_filter` indicates that all possible matches corresponding to this query pass the filtering step.
[class **GeneralJoin**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.GeneralJoin)
------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L32-L43)
[class **IdScoreSchema**](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.IdScoreSchema)
--------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L24-L26)
[class **InnerIndex**(data\_column, metadata\_column)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L205-L274)
Abstract class representing a data structure that accepts data (in `self.data_column`) with optional metadata (in `self.metadata_column`), and answers queries with a set of ‘matching’ IDs from the data structure (optionally filtered with JMESPath query run against stored metadata). The IDs are taken from the table that contains the data\_column column. Which IDs are considered as matched is defined in particular implementations of subclasses of this class. Can be used as `index` argument of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, which is a wrapper that augments the matching IDs with some additional data.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
### [abstract **query**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L228-L251)
An abstract method. Any implementation of `query` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
Whenever the index changes (via new entries in self.data\_column), it should adjust all old answers to the queries (which is a default behavior of pathway code, as long as it does not use operators telling that it is not the case).
The resulting table with results needs contain a column `_pw_index_reply` (name defined in `_INDEX_REPLY`), in which the resulting tuples are stored.
### [abstract **query\_as\_of\_now**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/data_index.py#L253-L274)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[**default\_full\_text\_document\_index**(data\_column, data\_table, \*, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.full_text_document_index.default_full_text_document_index)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/full_text_document_index.py#L8-L26)
Returns an instance of DataIndex ([`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
), with inner index (data structure) of our choosing. This method chooses an arbitrary implementation of `InnerIndex` (that supports text queries), but it’s not necessarily the best choice of index and its parameters (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project etc.
[pathway.stdlib.indexing.hybrid\_index module](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathwaystdlibindexinghybrid_index-module)
---------------------------------------------------------------------------------------------------------------------------------------------------------
[class **HybridIndex**(retrievers, k=60)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.hybrid_index.HybridIndex)
------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L14-L158)
Hybrid Index that composes any number of other indices and combines them using the Reciprocal Rank Fusion (RRF). It queries each index, and each retrieved row `d` is assigned score `1/(k+rank(d))`, which is then summed over all indices. `HybridIndex` returns best rows from indexed data according to this score.
* **Parameters**
* **retrievers** (`list`\[[`InnerIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.data_index.InnerIndex)\
\]) – list of indices to be used to compose the hybrid index.
* **k** (`float`) – constant used for calculating ranking score.
### [**query**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.hybrid_index.HybridIndex.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L124-L140)
An abstract method. Any implementation of `query` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
Whenever the index changes (via new entries in self.data\_column), it should adjust all old answers to the queries (which is a default behavior of pathway code, as long as it does not use operators telling that it is not the case).
The resulting table with results needs contain a column `_pw_index_reply` (name defined in `_INDEX_REPLY`), in which the resulting tuples are stored.
### [**query\_as\_of\_now**(query\_column, \*, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.hybrid_index.HybridIndex.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L142-L158)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **HybridIndexFactory**(retriever\_factories, k=60)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.hybrid_index.HybridIndexFactory)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/hybrid_index.py#L161-L188)
Factory for creating hybrid indices.
* **Parameters**
* **retriever\_factories** (`list`\[`InnerIndexFactory`\]) – list of factories of indices that will be used in the hybrid index
* **k** (`float`) – constant used for calculating ranking score.
[class **BruteForceKnn**(data\_column, metadata\_column, \*, dimensions, reserved\_space, auxiliary\_space=131072, metric, embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.BruteForceKnn)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L169-L258)
Interface for a brute force implementation of a nearest neighbors index.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **auxiliary\_space** (`int`) – auxiliary space (in the number of entries), the maximum number of distances that are stored in memory, while evaluating queries, in case `auxiliary_space` is set to a value smaller than the current number of entries in the index, it is still proportional to the size of the index (the value given in this parameter is ignored)
* **metric** ([`BruteForceKnnMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
) – metric kind that is used to determine distance
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.BruteForceKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L206-L215)
Currently, brute force knn index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.BruteForceKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L217-L258)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **BruteForceKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, auxiliary\_space=131072, metric=)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.BruteForceKnnFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L485-L528)
Factory for creating BruteForceKnn indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries. This is only needed if the embedder is not provided.
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **auxiliary\_space** (`int`) – auxiliary space (in the number of entries), the maximum number of distances that are stored in memory, while evaluating queries, in case `auxiliary_space` is set to a value smaller than the current number of entries in the index, it is still proportional to the size of the index (the value given in this parameter is ignored)
* **metric** ([`BruteForceKnnMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnnMetricKind)
) – metric kind that is used to determine distance. Defaults to cosine similarity.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **DefaultKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, auxiliary\_space=131072, metric=)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.DefaultKnnFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L573-L586)
Default factory for creating Knn index - uses the BruteForceKnn index.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **KnnIndexFactory**(\*, dimensions=None, embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.KnnIndexFactory)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L406-L428)
[class **LshKnn**(data\_column, metadata\_column, \*, dimensions, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean', embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.LshKnn)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L261-L403)
Interface for Pathway Live Data Framework’s implementation of KNN via LSH.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of metadata as dictionary, in JSON format.
* **dimensions** (`int`) – number of dimensions in the data
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.LshKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L319-L378)
* **Parameters**
* **query\_column** (`pw.ColumnExpression`) – column containing data that is used to query the index;
* **number\_of\_matches** (`pw.ColumnExpression [int] | int`) – number of nearest neighbors in the index response; defaults to 3
* **metadata\_filter** (`pw.ColumnExpression [str] | None`) – optional, column expression evaluating to the text representation of a boolean JMESPath query. The index will consider only the entries with metadata that satisfies the condition in the filter.
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.LshKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L380-L403)
* **Parameters**
* **query\_column** (`pw.ColumnExpression`) – column containing data that is used to query the index;
* **number\_of\_matches** (`pw.ColumnExpression[int] | int`) – number of nearest neighbors in the index response; defaults to 3
* **metadata\_filter** (`pw.ColumnExpression [str] | None`) – optional, column expression evaluating to the text representation of a boolean JMESPath query. The index will consider only the entries with metadata that satisfies the condition in the filter.
[class **LshKnnFactory**(\*, dimensions=None, embedder=None, n\_or=20, n\_and=10, bucket\_length=10.0, distance\_type='euclidean')](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.LshKnnFactory)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L531-L570)
Factory for creating LshKnn indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions in the data. This is only needed if the embedder is not provided.
* **n\_or** (`int`) – number of ORs
* **n\_and** (`int`) – number of ANDs
* **bucket\_length** (`float`) – bucket length (after projecting on a line)
* **distance\_type** (`str`) – “euclidean” and “cosine” metrics are supported.
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[class **USearchKnn**(data\_column, metadata\_column, \*, dimensions, reserved\_space, metric, connectivity=0, expansion\_add=0, expansion\_search=0, embedder=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.USearchKnn)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L64-L166)
Interface for usearch nearest neighbors index, an implementation of k nearest neighbors based on HNSW algorithm [white paper](https://arxiv.org/abs/1603.09320)
.
To understand meaning of the explanation of some of the parameters, you might need some familiarity with either [HNSW algorithm](https://arxiv.org/abs/1603.09320)
or its implementation provided by [USearch](https://github.com/unum-cloud/usearch)
.
* **Parameters**
* **data\_column** (`pw.ColumnExpression`) – the column expression representing the data.
* **metadata\_column** (`pw.ColumnExpression [str] | None`) – optional column expression, string representation of some auxiliary data, in JSON format.
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **metric** ([`USearchMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
) – metric kind that is used to determine distance
* **connectivity** (`int`) – maximum number of edges for a node in the HNSW index, setting this value to 0 tells usearch to configure it on its own
* **expansion\_add** (`int`) – indicates amount of work spent while adding elements to the index (higher = more accurate placement, more work), setting this value to 0 tells usearch to configure it on its own
* **expansion\_search** (`int`) – indicates amount of work spent while searching for elements in the index (higher = more accurate results, more work), setting this value to 0 tells usearch to configure it on its own
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
### [**query**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.USearchKnn.query)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L112-L121)
Currently, usearch knn index is supported only in the as-of-now variant
### [**query\_as\_of\_now**(query\_column, number\_of\_matches=3, metadata\_filter=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.USearchKnn.query_as_of_now)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L123-L166)
An abstract method. Any implementation of `query_as_of_now` in a subclass for each entry in `query_column` is supposed to return a tuple containing pairs, each pair consisting of the matched ID and the score indicating quality of the match (all that taking into account `number_of_matches` and `metadata_filter` parameters).
The implementation of the index should not update the answers to the old queries, when its internal state is modified.
The resulting table with results needs contain a column `_pw_index_reply` (name defined in pathway.stdlib.indexing.colnames.\_INDEX\_REPLY), in which the resulting tuples are stored.
[class **UsearchKnnFactory**(\*, dimensions=None, embedder=None, reserved\_space=400, metric=, connectivity=0, expansion\_add=0, expansion\_search=0)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.nearest_neighbors.UsearchKnnFactory)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/nearest_neighbors.py#L431-L482)
Factory for creating UsearchKNN indices.
* **Parameters**
* **dimensions** (`int`) – number of dimensions of vectors that are used by the index and queries. This is only needed if the embedder is not provided.
* **reserved\_space** (`int`) – initial capacity (in the number of entries) of the index
* **metric** ([`USearchMetricKind`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchMetricKind)
) – metric kind that is used to determine distance. Defaults to cosine similarity.
* **connectivity** (`int`) – maximum number of edges for a node in the HNSW index, setting this value to 0 tells usearch to configure it on its own
* **expansion\_add** (`int`) – indicates amount of work spent while adding elements to the index (higher = more accurate placement, more work), setting this value to 0 tells usearch to configure it on its own
* **expansion\_search** (`int`) – indicates amount of work spent while searching for elements in the index (higher = more accurate results, more work), setting this value to 0 tells usearch to configure it on its own
* **embedder** ([`UDF`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.UDF)
| `None`) – [`UDF`](https://pathway.com/developers/api-docs/pathway#pathway.UDF)
used for calculating embeddings of string. It is needed, if index is used for indexing texts.
[pathway.stdlib.indexing.typecheck\_utils module](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathwaystdlibindexingtypecheck_utils-module)
---------------------------------------------------------------------------------------------------------------------------------------------------------------
[pathway.stdlib.indexing.vector\_document\_index module](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathwaystdlibindexingvector_document_index-module)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[**default\_brute\_force\_knn\_document\_index**(data\_column, data\_table, dimensions, \*, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.vector_document_index.default_brute_force_knn_document_index)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L154-L196)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
. This method chooses some parameters of `BruteForceKnn` arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`BruteForceKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.BruteForceKnn)
to see the parameters that can be adjusted.
[**default\_lsh\_knn\_document\_index**(data\_column, data\_table, \*, dimensions, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.vector_document_index.default_lsh_knn_document_index)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L66-L105)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
. This method chooses some parameters of LshKnn arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`LshKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.LshKnn)
to see the parameters that can be adjusted.
[**default\_usearch\_knn\_document\_index**(data\_column, data\_table, dimensions, \*, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.vector_document_index.default_usearch_knn_document_index)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L108-L151)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) that is an instance of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
. This method chooses some parameters of USearchKnn arbitrarily, but it’s not necessarily a choice that works well in any scenario (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project, etc.
Remark: the arbitrarily chosen configuration of the index may change (whenever tests suggest some better default values). To have fixed configuration, you can use [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
with a parameterized instance of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
. Look up [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
constructor to see how to make data index parameterized by custom data structure, and the constructor of [`USearchKnn`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.USearchKnn)
to see the parameters that can be adjusted.
[**default\_vector\_document\_index**(data\_column, data\_table, \*, dimensions, embedder=None, metadata\_column=None)](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.vector_document_index.default_vector_document_index)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/indexing/vector_document_index.py#L34-L63)
Returns an instance of [`DataIndex`](https://pathway.com/developers/api-docs/pathway-stdlib-indexing#pathway.stdlib.indexing.DataIndex)
, with inner index (data structure) of our choosing. This method chooses an arbitrary implementation of `InnerIndex` (that supports queries on vectors), but it’s not necessarily the best choice of index and its parameters (each usecase may need slightly different configuration). As such, it is meant to be used for development, demonstrations, starting point of larger project etc.
---
# Pathway - Building AI architectures and models that autonomously and continually learn, evolve, and reason
News
====
[\
\
\
\
Wall Street Journal\
\
news · bdhDec 1, 2025\
\
Pathway Looks Toward the Post-Transformer Era](https://pathway.com/news/an-ai-startup-looks-toward-the-post-transformer-era)
[\
\
\
\
Forbes\
\
news · bdhOct 8, 2025\
\
Can AI Learn And Evolve Like A Brain? Pathway’s Bold Research Thinks So](https://pathway.com/news/can-ai-learn-and-evolve-like-a-brain-pathways-bold-research-thinks-so)
[\
\
\
\
techradar\
\
news · bdhMay 26, 2026\
\
What Sudoku reveals about the limits of LLMs](https://pathway.com/news/what-sudoku-reveals-about-the-limits-of-llms)
[\
\
\
\
The Neuron\
\
podcast · video · bdh · researchMay 19, 2026\
\
What the Transformer vs. Post-Transformer debate revealed about AI's next architecture](https://pathway.com/news/what-the-transformer-vs-post-transformer-debate-revealed-about-ais-next-architecture)
[\
\
\
\
Express Computer\
\
bdhMay 14, 2026\
\
Why continual learning and memory matters more than data in the next generation of AI](https://pathway.com/news/why-continual-learning-and-memory-matters-more-than-data-in-the-next-generation-of-ai)
[\
\
\
\
AWS Startups\
\
news · bdhMay 3, 2026\
\
Pathway's BDH: a new post-transformer approach to enterprise AI, on AWS](https://pathway.com/news/pathways-bdh-a-new-post-transformer-approach-to-enterprise-ai-on-aws)
[\
\
\
\
Analytics India Magazine\
\
bdhApr 23, 2026\
\
Why the Future of AI Will Go Beyond Transformers](https://pathway.com/news/why-the-future-of-ai-will-go-beyond-transformers)
[\
\
\
\
Pathway Team\
\
bdh · researchMar 17, 2026\
\
Pathway’s BDH solves Sudoku Extreme with 97.4% accuracy, while leading LLMs are close to 0](https://pathway.com/research/beyond-transformers-sudoku-bench)
[\
\
\
\
ET Edge Insights\
\
news · bdhMar 12, 2026\
\
Why today’s AI struggles with the real world, and what comes next](https://pathway.com/news/why-todays-ai-struggles-with-the-real-world-and-what-comes-next)
[\
\
\
\
Eye on AI\
\
news · bdhMar 11, 2026\
\
Inside Pathway's Post-Transformer Architecture Designed for Memory and On-the-Fly Learning](https://pathway.com/news/inside-pathways-post-transformer-architecture-designed-for-memory-and-on-the-fly-learning)
[\
\
\
\
MILA Tea Talk\
\
podcast · video · bdh · researchMar 10, 2026\
\
BDH: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/mila-bdh)
[\
\
\
\
Pathway Team\
\
podcast · video · bdh · researchFeb 6, 2026\
\
The Post-Transformer Era: AI's Next Frontier | NYU x Pathway](https://pathway.com/news/the-post-transformer-era-ais-next-frontier-nyu-x-pathway)
[\
\
\
\
Pathway Team\
\
newsletterJan 15, 2026\
\
WSJ: Pathway marks the beginning of the post-transformer era](https://pathway.com/news/newsletter-2026-01-15)
[\
\
\
\
The Neuron\
\
news · podcast · bdhJan 6, 2026\
\
This AI Grows a Brain During Training (Pathway's AI w/ Zuzanna Stamirowska)](https://pathway.com/news/this-ai-grows-a-brain-during-training)
[\
\
\
\
Turing Post\
\
news · bdhDec 29, 2025\
\
That Hint Where AI Is Heading](https://pathway.com/news/that-hint-where-ai-is-heading)
[\
\
\
\
Hugging Face\
\
news · bdh · researchDec 28, 2025\
\
BDH is the second most popular AI paper of 2025](https://pathway.com/news/second-most-popular-ai-paper-of-the-year-in-2025)
[\
\
\
\
Wall Street Journal\
\
newsDec 26, 2025\
\
Tech That Will Change Your Life in 2026](https://pathway.com/news/tech-predictions-2026)
[\
\
\
\
Inc.\
\
news · bdhDec 21, 2025\
\
How 'Neolabs' Are Betting Against the OpenAI Model and What It Means for Founders](https://pathway.com/news/how-neolabs-are-betting-against-the-openai-model-and-what-it-means-for-founders)
[\
\
\
\
AWS Events\
\
news · bdh · videoDec 4, 2025\
\
AWS re:Invent 2025 -The new AI architecture that adapts and thinks just like humans](https://pathway.com/news/aws-reinvent-2025-the-new-ai-architecture-that-adapts-and-thinks-just-like-humans)
[\
\
\
\
businesswire\
\
news · bdhDec 1, 2025\
\
Pathway to Deliver New Class of Adaptive and Continuously Learning AI Systems with AWS and NVIDIA Technologies](https://pathway.com/news/pathway-to-deliver-new-class-of-adaptive-and-continuously-learning-ai-systems-with-aws-and-nvidia-technologies)
[\
\
\
\
Pathway Team\
\
researchNov 30, 2025\
\
Benchmarks: Fundamental Unlocks for AI](https://pathway.com/#benchmarks)
[\
\
\
\
Arxiv.org\
\
bdh · researchNov 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/arxiv-bdh)
[\
\
\
\
Live Science\
\
news · bdhNov 13, 2025\
\
New 'Dragon Hatchling' AI architecture modeled after the human brain could be a key step toward AGI, researchers claim](https://pathway.com/news/new-dragon-hatchling-ai-architecture-modeled-after-the-human-brain-could-be-a-key-step-toward-agi-researchers-claim)
[in German\
\
\
\
\
\
Notebook Check\
\
news · bdhOct 21, 2025\
\
AI should think like the human brain: Dragon Hatchling (BDH) copies neurons for unlimited context and higher efficiency](https://pathway.com/news/ai-should-think-like-the-human-brain-dragon-hatchling-bdh-copies-neurons-for-unlimited-context-and-higher-efficiency)
[\
\
\
\
Pathway Team\
\
newsletterOct 15, 2025\
\
The next Transformer moment for AI - read in Forbes](https://pathway.com/news/newsletter-2025-10-15)
[\
\
\
\
sifted.eu\
\
newsOct 10, 2025\
\
100 Women in Tech](https://pathway.com/news/100-women-in-tech-2025)
[\
\
\
\
SuperDataScience\
\
news · podcast · bdh · researchOct 7, 2025\
\
Dragon Hatchling: The Missing Link Between Transformers and the Brain, with Adrian Kosowski (SDS 929)](https://pathway.com/news/sds-929-dragon-hatchling-the-missing-link-between-transformers-and-the-brain-with-adrian-kosowski)
[\
\
\
\
This Is The World\
\
news · podcast · bdhOct 4, 2025\
\
Revealing the First Biological AI: A Step Closer to Singularity](https://pathway.com/news/revealing-the-first-biological-ai-a-step-closer-to-singularity-copy)
[\
\
\
\
Intelligent CIO\
\
news · bdhOct 3, 2025\
\
Pathway launches new post-transformer architecture paving the way for autonomous AI](https://pathway.com/news/pathway-launches-new-post-transformer-architecture-paving-the-way-for-autonomous-ai)
[\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Pathway Launches a New “Post-Transformer” Architecture That Paves the Way for Autonomous AI](https://pathway.com/news/pathway-launches-a-new-post-transformer-architecture-that-paves-the-way-for-autonomous-ai)
[in Japanese\
\
\
\
\
\
Radical Data Science\
\
news · bdhOct 1, 2025\
\
Brain-inspired AI model 'BDH' may surpass the limits of Transformers](https://pathway.com/news/pathway-bdh-brain-inspired-ai-architecture)
[\
\
\
\
Semafor\
\
news · bdhOct 1, 2025\
\
New AI research claims to be getting closer to modeling human brain](https://pathway.com/news/new-ai-research-claims-to-be-getting-closer-to-modeling-human-brain)
[\
\
\
\
Hugging Face\
\
news · bdh · developerSep 30, 2025\
\
The Dragon Hatchling: The Missing Link between the Transformer and Models of the Brain](https://pathway.com/news/the-dragon-hatchling-the-missing-link-between-the-transformer-and-models-of-the-brain)
[\
\
\
\
Unite AI\
\
newsSep 26, 2025\
\
Zuzanna Stamirowska, Co-Founder and CEO of Pathway – Interview Series](https://pathway.com/news/zuzanna-stamirowska-co-founder-and-ceo-of-pathway-interview-series)
[\
\
\
\
Fast Company\
\
newsSep 26, 2025\
\
OpenAI claims AI is making coding jobs better, not worse. Is it true?](https://pathway.com/news/open-ai-coding-jobs-silicon-valley-google)
[in Spanish\
\
\
\
\
\
Forbes Argentina\
\
news · bdhSep 9, 2025\
\
Can an artificial intelligence learn like a human brain does? A startup believes it has achieved this](https://pathway.com/news/inteligencia-artificial-aprender-cerebro-humano)
[\
\
\
\
Quantum Zeitgeist\
\
news · bdhAug 3, 2025\
\
Palo Alto AI Firm Pathway Unveils Post-Transformer Architecture for Autonomous AI](https://pathway.com/news/palo-alto-ai-firm-pathway-unveils-post-transformer-architecture-for-autonomous-ai)
[in Polish\
\
\
\
\
\
Forbes\
\
newsMar 20, 2025\
\
Forbes Poland: CEO profile (in Polish)](https://pathway.com/news/forbes-poland-ceo-profile-in-polish)
[\
\
\
\
Pathway Team\
\
newsletterFeb 25, 2025\
\
Pathway to the Silicon Valley](https://pathway.com/news/newsletter-2025-02-25)
[\
\
\
\
Forbes\
\
newsFeb 13, 2025\
\
Forbes: Pathway Navigates Next Road For AI Foundational Models](https://pathway.com/news/pathway-mentioned-in-the-financial-times)
[\
\
\
\
Zuzanna Stamirowska\
\
newsDec 19, 2024\
\
Pathway CEO and co-founder predicts 2025 AI trends: Will your startup survive the shift?](https://pathway.com/news/pathway-ceo-predicts-2025-ai-trends)
[\
\
\
\
TechCrunch\
\
newsNov 29, 2024\
\
As Cohere and Writer mine the ‘LiveAI™’ arena, Pathway joins the pack with a $10M round](https://pathway.com/news/as-cohere-and-writer-mine-the-live-ai-arena-pathway-joins-the-pack-with-a-10m-round)
[\
\
\
\
Mudit Srivastava\
\
newsNov 14, 2024\
\
Gartner® recognizes Pathway as an Emerging Visionary in GenAI Engineering](https://pathway.com/framework/blog/gartner-gen-ai-engineering)
[\
\
\
\
Pathway Team\
\
news · case-studyNov 13, 2024\
\
Joint Support and Enabling Command collaborates with AI company Pathway to combine industry and military expertise](https://pathway.com/news/jsec-pathway-ai-collaboration-steadfast-foxtrot-2024)
[\
\
\
\
Pathway Team\
\
newsApr 30, 2024\
\
The Future of Large Language Models by Lukasz Kaiser and Jan Chorowski](https://pathway.com/news/pathway-meetup-2024)
* * *
Showing 45 of 45 results
---
# pw.io.null | Pathway
pw.io.null
==========
[**write**(table, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/null#pathway.io.null.write)
--------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/null/__init__.py#L14-L64)
Writes `table`’s stream of updates to the empty sink.
Inside this routine, the data is formatted into the empty object, and then doesn’t get written anywhere.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
One (of a very few) examples, where you can probably need this kind of functionality if the case when a Pathway Live Data Framework program is benchmarked and the IO part needs to be simplified as much as possible.
If the table is `table`, the null output can be configured in the following way:
`pw.io.null.write(table)`
[Pathway Io\
\
pw.io.nats](https://pathway.com/developers/api-docs/pathway-io/nats)
[Pathway Io\
\
pw.io.pinecone](https://pathway.com/developers/api-docs/pathway-io/pinecone)
---
# pw.io.slack | Pathway
pw.io.slack
===========
[**send\_alerts**(alerts, slack\_channel\_id, slack\_token)](https://pathway.com/developers/api-docs/pathway-io/slack#pathway.io.slack.send_alerts)
----------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/slack/__init__.py#L7-L45)
Sends content of a given column to the Slack channel. Each row in a column is a distinct message in the Slack channel.
* **Parameters**
* **alerts** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – ColumnReference with alerts to be sent.
* **slack\_channel\_id** (`str`) – id of the channel to which alerts are to be sent.
* **slack\_token** (`str`) – token used for authenticating to Slack API.
Example:
`import os import pathway as pw slack_channel_id = os.environ["SLACK_CHANNEL_ID"] slack_token = os.environ["SLACK_TOKEN"] t = pw.debug.table_from_markdown(''' alert This_is_Slack_alert ''') pw.io.slack.send_alerts(t.alert, slack_channel_id, slack_token)`
[Pathway Io\
\
pw.io.s3](https://pathway.com/developers/api-docs/pathway-io/s3)
[Pathway Io\
\
pw.io.sqlite](https://pathway.com/developers/api-docs/pathway-io/sqlite)
---
# pw.io.pubsub | Pathway
pw.io.pubsub
============
[**write**(table, publisher, project\_id, topic\_id, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/pubsub#pathway.io.pubsub.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/pubsub/__init__.py#L53-L142)
Publish the `table`’s stream of changes into the specified PubSub topic. Please note that `table` must consist of a single column of the binary type. In addition, the connector adds two attributes: `pathway_time` containing the logical time of the change and `pathway_diff` corresponding to the change type: either addition (`pathway_diff = 1`) or deletion (`pathway_diff = -1`).
* **Parameters**
* **table** – The table to publish.
* **publisher** (`PublisherClient`) – The configured `pubsub_v1.PublisherClient` object. You can refer to the Google Cloud [documentation](https://cloud.google.com/pubsub/docs/samples/pubsub-quickstart-publisher?hl=en)
for the example of a simple publisher configuration. You can also see the examples for [batching settings configuration](https://cloud.google.com/pubsub/docs/samples/pubsub-publisher-batch-settings?hl=en)
or [flow control configuration](https://cloud.google.com/pubsub/docs/samples/pubsub-publisher-flow-control?hl=en)
.
* **project\_id** (`str`) – The ID of the project where the changes are published.
* **topic\_id** (`str`) – The topic ID where the changes are published.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
Consider that you have a table `blobs`, consisting of a single column that has a binary type. You would like to publish changes that happen to this table into a topic called `blobs` in your Google Cloud pub/sub project.
For simplicity, let’s consider that the project ID is stored in the `project_id` variable. The `topic_id` variable then would denote the name of the target topic which is `blobs` in our case:
`project_id = "YOUR_PROJECT_ID" topic_id = "blobs"`
Now, you need to create the publisher object of `pubsub_v1.PublisherClient` type. If you have the [service account](https://cloud.google.com/iam/docs/service-account-overview)
credentials stored in a file `./credentials.json`, it can be done with the following code:
`from google.cloud import pubsub_v1 publisher = pubsub_v1.PublisherClient.from_service_account_file( "./credentials.json" )`
If you don’t have the topic created yet, you may want to create it first:
`topic_path = publisher.topic_path(project_id, topic_id) topic = publisher.create_topic(request={"name": topic_path})`
After that you can configure the table output with the following code:
`import pathway as pw pw.io.pubsub.write(table, publisher, project_id, topic_id)`
At last, don’t forget to add `pw.run()` to run your pipeline.
[Pathway Io\
\
pw.io.postgres](https://pathway.com/developers/api-docs/pathway-io/postgres)
[Pathway Io\
\
pw.io.pyfilesystem](https://pathway.com/developers/api-docs/pathway-io/pyfilesystem)
---
# pw.io.logstash | Pathway
pw.io.logstash
==============
[**write**(table, endpoint, n\_retries=0, retry\_policy=, connect\_timeout\_ms=None, request\_timeout\_ms=None, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/logstash#pathway.io.logstash.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/logstash/__init__.py#L15-L84)
Sends the stream of updates from the table to [HTTP input](https://www.elastic.co/guide/en/logstash/current/plugins-inputs-http.html)
of Logstash. The data is sent in the format of flat JSON objects, where two additional fields are included: `time`, which indicates the time of the Pathway minibatch, and `diff`, which can be either `1` (row addition) or `-1` (row deletion).
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – table to be tracked;
* **endpoint** (`str`) – Logstash endpoint, accepting entries;
* **n\_retries** (`int`) – number of retries in case of failure;
* **retry\_policy** ([`RetryPolicy`](https://pathway.com/developers/api-docs/pathway-io-http#pathway.io.http.RetryPolicy)
) – policy of delays or backoffs for the retries;
* **connect\_timeout\_ms** (`int` | `None`) – connection timeout, specified in milliseconds. In cas it’s None, no restrictions on connection duration will be applied;
* **request\_timeout\_ms** (`int` | `None`) – request timeout, specified in milliseconds. In case it’s None, no restrictions on request duration will be applied.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
Example:
Suppose that we need to send the stream of updates to locally installed Logstash. For example, you can use [docker-elk](https://github.com/deviantony/docker-elk)
repository in order to get the ELK stack up and running at your local machine in a few minutes.
If Logstash stack is installed, you need to configure the input pipeline. The simplest possible way to do this, is to add the following lines in the input plugins list:
`http { port => 8012 }`
The port is specified for the sake of example and can be changed. Further, we will use `8012` for clarity.
Now, with the pipeline configured, you can stream the changed into Logstash as simple as:
`pw.io.logstash.write(table, "http://localhost:8012")`
[Pathway Io\
\
pw.io.leann](https://pathway.com/developers/api-docs/pathway-io/leann)
[Pathway Io\
\
pw.io.milvus](https://pathway.com/developers/api-docs/pathway-io/milvus)
---
# pw.io | Pathway
pw.io
=====
In the Pathway Live Data Framework, accessing the data is done using connectors. This page provides their API documentation. See [connector articles](https://pathway.com/developers/user-guide/connect/pathway-connectors)
for an overview of their architecture.
[class **CsvParserSettings**(delimiter=',', quote='"', escape=None, enable\_double\_quote\_escapes=True, enable\_quoting=True, comment\_character=None)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/_utils.py#L197-L228)
Class representing settings for the CSV parser.
* **Parameters**
* **delimiter** – Field delimiter to use when parsing CSV.
* **quote** – Quote character to use when parsing CSV.
* **escape** – What character to use for escaping fields in CSV.
* **enable\_double\_quote\_escapes** – Enable escapes of double quotes.
* **enable\_quoting** – Enable quoting for the fields.
* **comment\_character** – If specified, the lines starting with the comment character will be treated as comments and therefore, will be ignored by parser
[class **OnChangeCallback**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.OnChangeCallback)
---------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table_subscription.py#L29-L60)
The callback to be called on every change in the table. It is required to be callable and to accept four parameters: the key, the row changed, the time of the change in milliseconds and the flag stating if the change was an addition of the row.
[class **OnChangeCallbackAsync**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.OnChangeCallbackAsync)
-------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table_subscription.py#L63-L94)
The async callback to be called on every change in the table. It is required to be callable and to accept four parameters: the key, the row changed, the time of the change in milliseconds and the flag stating if the change was an addition of the row.
[class **OnFinishCallback**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.OnFinishCallback)
---------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table_subscription.py#L15-L26)
The callback function to be called when the stream of changes ends. It will be called on each engine worker separately.
[class **SynchronizedColumn**(column, priority=0, idle\_duration=None)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.SynchronizedColumn)
----------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/_synchronization.py#L19-L56)
Defines synchronization settings for a column within a synchronization group.
The purpose of such groups is to ensure that, at any moment, the values read across the group of columns remain within a defined range relative to each other. The size of this range and the set of tracked columns are configured using the `register_input_synchronization_group` method.
There are two principal parameters for the tracking: the **priority** and the **idle duration**.
**Priority** determines the order in which sources can contribute values. A value from a source is only allowed if it does not exceed the maximum of values already read from all sources with higher priority. By default, priority is `0`. This means that if unchanged, all sources are considered equal, and the synchronization group ensures only that no source gets too far ahead of the others.
**Idle duration** specifies the time after which a source that remains idle (produces no new data) will be excluded from the group. While excluded, the source does not participate in priority checks and is not considered when verifying that values stay within the allowed range. If the source later produces new data, it is re-included in the synchronization group and resumes synchronization. This field is optional. If not specified, the source will remain in the group even while idle, and it may block values that try to advance too far compared to other sources.
* **Parameters**
* **column** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – Reference to the column that will participate in synchronization.
* **priority** (`int`) – The priority of this column when reading data. Defaults to `0`.
* **idle\_duration** (`int` | `float` | `timedelta` | `None`) – Optional duration after which an idle source is temporarily excluded from the group. Given as a number of seconds or a `datetime.timedelta` / `pw.Duration`.
[class **TLSSettings**(\*, mode='prefer', root\_cert\_path=None, client\_cert\_path=None, client\_key\_path=None, trust\_certificates=False)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.TLSSettings)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/_io_helpers.py#L18-L60)
Stores TLS connection settings for connectors that support encrypted communication (e.g. PostgreSQL, RabbitMQ).
* **Parameters**
* **mode** (`str`) – The SSL verification mode. Determines how strictly the server certificate is validated. Possible values: `"disable"`, `"allow"`, `"prefer"` (default), `"require"`, `"verify-ca"`, `"verify-full"`.
* **root\_cert\_path** (`str` | `None`) – Path to the root CA certificate file used to verify the server’s certificate.
* **client\_cert\_path** (`str` | `None`) – Path to the client certificate file for mutual TLS authentication.
* **client\_key\_path** (`str` | `None`) – Path to the client private key file for mutual TLS authentication.
* **trust\_certificates** (`bool`) – If True, trust server certificates without verification. Use only for development and testing.
[**register\_input\_synchronization\_group**(\*columns, max\_difference, name='default')](https://pathway.com/developers/api-docs/pathway-io#pathway.io.register_input_synchronization_group)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/_synchronization.py#L59-L308)
Creates a synchronization group for a specified set of columns. The set must consist of at least two columns, each belonging to a different table. These tables must be read using one of the input connectors (they have to be input tables). Transformed tables cannot be used.
The synchronization group ensures that the engine reads data into the specified tables in such a way that the difference between the maximum read values from each column does not exceed `max_difference`.
All columns must have the same data type to allow for proper comparison, and `max_difference` must be the result of subtracting values from two columns.
The logic of synchronization group is the following:
* If a data source lags behind, the engine will read more data from it to align its values with the others and will continue reading from the other sources only after the lagging one has caught up.
* If a data source is too fast compared to others, the engine will delay its reading until the slower sources (i.e., those with lower values in their specified columns) catch up.
Limitations:
* This mechanism currently works only in runs that use a single Pathway Live Data Framework process. The multi-processing support will be added soon.
* Currently, `int`, `DateTimeNaive`, `DateTimeUtc` and `Duration` field types are supported.
Please note that all columns within the synchronization group must have the same type.
* **Parameters**
* **columns** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| [`SynchronizedColumn`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.SynchronizedColumn)
) – A list of column references or `SynchronizedColumn` instances denoting the set of columns that will be monitored and synchronized. If using a `ColumnReference`, the source is added with a priority `0` and without idle duration. Each column must belong to a different table read from an input connector.
* **max\_difference** (`Union`\[`None`, `int`, `float`, `str`, `bytes`, `bool`, `Pointer`, `datetime`, `timedelta`, `ndarray`, [`Json`](https://pathway.com/developers/api-docs/pathway#pathway.Json)\
, `dict`\[`str`, `Any`\], `tuple`\[`Any`, `...`\], `Error`, `Pending`\]) – The maximum allowed difference between the highest values in the tracked columns at any given time. Must be derived from subtracting values of two columns specified before.
* **name** (`str`) – The name of the synchronization group, used for logging and debugging purposes.
* **Returns**
None
Example:
Suppose you have two data sources:
* `login_events`, a table read from the Kafka topic `"logins"`.
* `transactions`, a table read from the Kafka topic `"transactions"`.
Each table contains a `timestamp` field that represents the number of seconds since the UNIX Epoch. You want to ensure that these tables are read simultaneously, with no more than a 10-minute (600-second) difference between their maximum `timestamp` values.
First, you need define the table schema:
`import pathway as pw class InputSchema(pw.Schema): event_id: str unix_timestamp: int data: pw.Json # Other relevant fields can be added here`
Next, you read both tables from Kafka. Assuming the Kafka server runs on host `"kafka"` and port `8082`:
`login_events = pw.io.kafka.simple_read("kafka:8082", "logins", format="json", schema=InputSchema) transactions = pw.io.kafka.simple_read("kafka:8082", "transactions", format="json", schema=InputSchema)`
Finally, you can synchronize these two tables by creating a synchronization group:
`pw.io.register_input_synchronization_group( login_events.unix_timestamp, transactions.unix_timestamp, max_difference=600, )`
This ensures that both topics are read in such a way that the difference between the maximum `timestamp` values at any moment does not exceed 600 seconds (10 minutes). In other words, `login_events` and `transactions` will not get too far ahead of each other.
However, this may not be sufficient if you want to guarantee that, whenever a transaction at a given timestamp is being processed, you have already seen all login events up to that timestamp. To achieve this, you can use priorities.
By assigning a higher priority to `login_events` and a lower priority to `transactions`, you ensure that `login_events` always progresses ahead, so that all login events are read before transactions reach the corresponding timestamps while the general stream is still in sync and the login events are read only up to the globally-defined bound. The code snippet would look as follows:
`pw.io.register_input_synchronization_group( pw.io.SynchronizedColumn(login_events.unix_timestamp, priority=1), pw.io.SynchronizedColumn(transactions.unix_timestamp, priority=0), max_difference=600, )`
The code above solves the problem where a transaction could be read before its corresponding user login event appears. However, consider the opposite situation: a user logs in and then performs a transaction. In this case, transactions may be forced to wait until new login events arrive with timestamps equal to or greater than those of the transactions. Such waiting is unnecessary if you can guarantee that all login events up to this point have already been read, and there is nothing else to read.
To avoid this unnecessary delay, you can specify an `idle_duration` for the `login_events` source. This tells the synchronization group that if no new login events appear for a certain period (for example, 10 seconds), the source can be temporarily considered idle. Once it is marked as idle, transactions are allowed to continue even if no newer login events are available. When new login events arrive, the source automatically becomes active again and resumes synchronized reading.
The code snippet then looks as follows:
`import datetime pw.io.register_input_synchronization_group( pw.io.SynchronizedColumn( login_events.unix_timestamp, priority=1, idle_duration=datetime.timedelta(seconds=10), ), pw.io.SynchronizedColumn(transactions.unix_timestamp, priority=0), max_difference=600, )`
Note:
If all data sources exceed the allowed `max_difference` relative to each other, the synchronization group will wait until new data arrives from all sources. Once all sources have values within the acceptable range, reading can proceed. The sources can proceed quicker if the `idle_duration` is set in some: then the synchronization group will not have to wait for their next read values.
**Example scenario:** Consider a synchronization group with two data sources, both tracking a `timestamp` column, and `max_difference` set to 600 seconds (10 minutes).
* Initially, both sources send a record with timestamp `T`.
* Later, the first source sends a record with `T + 1h`. This record is not yet forwarded for processing because it exceeds `max_difference`.
* If the second source then sends a record with `T + 1h`, the system detects a 1-hour gap. Since both sources have moved beyond `T`, the synchronization group accepts `T + 1h` as the new baseline and continues processing from there.
* However, if the second source instead sends a record with `T + 5m`, this record is processed normally. The system will continue waiting for the first source to catch up before advancing further.
This behavior ensures that data gaps do not cause deadlocks but are properly detected and handled.
[**subscribe**(table, on\_change, on\_end=lambda : ..., on\_time\_end=lambda time: ..., \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io#pathway.io.subscribe)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/_subscribe.py#L17-L84)
Calls a callback function `on_change` on every change happening in table.
* **Parameters**
* **table** – the table to subscribe.
* **on\_change** ([`OnChangeCallback`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.OnChangeCallback)
| [`OnChangeCallbackAsync`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.OnChangeCallbackAsync)
) – the callback to be called on every change in the table. The function is required to accept four parameters: the key, the row changed, the time of the change in microseconds and the flag stating if the change had been an addition of the row. These parameters of the callback are expected to have names `key`, `row`, `time` and `is_addition` respectively.
* **on\_end** ([`OnFinishCallback`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.OnFinishCallback)
) – the callback to be called when the stream of changes ends.
* **on\_time\_end** (`OnTimeEndCallback`) – the callback function to be called on each closed time of computation.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically. Incompatible with async callbacks.
* **Returns**
None
Example:
`import pathway as pw table = pw.debug.table_from_markdown(''' | pet | owner | age | __time__ | __diff__ 1 | dog | Alice | 10 | 0 | 1 2 | cat | Alice | 8 | 2 | 1 3 | dog | Bob | 7 | 4 | 1 2 | cat | Alice | 8 | 6 | -1 ''') def on_change(key: pw.Pointer, row: dict, time: int, is_addition: bool): print(f"{row}, {time}, {is_addition}") def on_end(): print("End of stream.") pw.io.subscribe(table, on_change, on_end) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
Code Results
[API Docs\
\
pw.indexing](https://pathway.com/developers/api-docs/indexing)
[Pathway Io\
\
pw.io.airbyte](https://pathway.com/developers/api-docs/pathway-io/airbyte)
---
# pw.io.minio | Pathway
pw.io.minio
===========
[class **MinIOSettings**(endpoint, bucket\_name, access\_key, secret\_access\_key, \*, with\_path\_style=True, region=None)](https://pathway.com/developers/api-docs/pathway-io/minio#pathway.io.minio.MinIOSettings)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/minio/__init__.py#L15-L54)
Stores MinIO bucket connection settings.
* **Parameters**
* **endpoint** – Endpoint for the bucket.
* **bucket\_name** – Name of a bucket.
* **access\_key** – Access key for the bucket.
* **secret\_access\_key** – Secret access key for the bucket.
* **region** – Region of the bucket.
* **with\_path\_style** – Whether to use path-style addresses for bucket access. It defaults to True as this is the most widespread way to access MinIO, but can be overridden in case of a custom configuration.
[**read**(path, minio\_settings, format, \*, schema=None, mode='streaming', with\_metadata=False, csv\_settings=None, json\_field\_paths=None, path\_filter=None, downloader\_threads\_count=None, name=None, autocommit\_duration\_ms=1500, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/minio#pathway.io.minio.read)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/minio/__init__.py#L57-L188)
Reads a table from one or several objects from S3 bucket in MinIO.
In case the prefix is specified, and there are several objects lying under this prefix, their order is determined according to their modification times: the smaller the modification time is, the earlier the file will be passed to the engine.
Note that if you only need to monitor changes in the bucket, you can use the `"only_metadata"` format, in which case the table will contain only metadata, and no time or traffic will be spent on downloading the objects.
* **Parameters**
* **path** (`str`) – Path to an object or to a folder of objects in MinIO S3 bucket.
* **minio\_settings** ([`MinIOSettings`](https://pathway.com/developers/api-docs/pathway-io-minio#pathway.io.minio.MinIOSettings)
) – Connection parameters for the MinIO account and the bucket.
* **format** (`Literal`\[`'csv'`, `'json'`, `'plaintext'`, `'plaintext_by_object'`, `'binary'`, `'only_metadata'`\]) – Format of data to be read. Currently `csv`, `json`, `plaintext`, `plaintext_by_object`, `binary` and `only_metadata` formats are supported. The difference between `plaintext` and `plaintext_by_object` is how the input is tokenized: if the `plaintext` option is chosen, it’s split by the newlines. Otherwise, the files are split in full and one row will correspond to one file. In case the `binary` format is specified, the data is read as raw bytes without UTF-8 parsing. If the `only_metadata` format is chosen, the objects are not downloaded at all: the resulting table contains only the `_metadata` column, which is useful when you only need to track changes in the bucket without spending time and traffic on fetching the objects’ contents.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table. Not required for `plaintext_by_object` and `binary` formats: if they are chosen, the contents of the read objects are stored in the column `data`.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – If set to `streaming`, the engine waits for the new objects under the given path prefix. Set it to `static`, it only considers the available data and ingest all of it. Default value is `streaming`.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field that will contain an optional field `modified_at`. Additionally, the column will also have an optional field named `owner` containing an ID of the object owner. Finally, the column will also contain a field named `path` that will show the full path to the object within a bucket from where a row was filled.
* **csv\_settings** ([`CsvParserSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
| `None`) – Settings for the CSV parser. This parameter is used only in case the specified format is “csv”.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is “json”, this field allows to map field names into path in the read json object. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **path\_filter** (`str` | `None`) – A wildcard pattern used to match full object paths. Supports `*` (any number of any characters, including none) and `?` (any single character). If specified, only paths matching this pattern will be included. Applied as an additional filter after the initial `path` matching.
* **downloader\_threads\_count** (`int` | `None`) – The number of threads created to download the contents of the bucket under the given path. It defaults to the number of cores available on the machine. It is recommended to increase the number of threads if your bucket contains many small files.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Consider that there is a table, which is stored in CSV format in the min.io S3 bucket. Then, you can use this method in order to connect and acquire its contents.
It may look as follows:
`import os import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.minio.read( "animals/", minio_settings=pw.io.minio.MinIOSettings( bucket_name="datasets", endpoint="avv749.stackhero-network.com", access_key=os.environ["MINIO_S3_ACCESS_KEY"], secret_access_key=os.environ["MINIO_S3_SECRET_ACCESS_KEY"], ), format="csv", schema=InputSchema, )`
Please note that this connector is **interoperable** with the **AWS S3** connector, therefore all examples concerning different data formats in `pw.io.s3.read` also work with min.io input.
[Pathway Io\
\
pw.io.milvus](https://pathway.com/developers/api-docs/pathway-io/milvus)
[Pathway Io\
\
pw.io.mongodb](https://pathway.com/developers/api-docs/pathway-io/mongodb)
---
# pw.io.pyfilesystem | Pathway
pw.io.pyfilesystem
==================
[**read**(source, \*, path='', refresh\_interval=30, mode='streaming', format='binary', with\_metadata=False, name=None, max\_backlog\_size=None)](https://pathway.com/developers/api-docs/pathway-io/pyfilesystem#pathway.io.pyfilesystem.read)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/pyfilesystem/__init__.py#L157-L266)
Reads a table from PyFilesystem [https://docs.pyfilesystem.org/en/latest/introduction.html](https://docs.pyfilesystem.org/en/latest/introduction.html)
\_ source.
It returns a table with a single column `data` containing each file in a binary format. If the `with_metadata` option is specified, it also attaches a column `_metadata` containing the metadata of the objects read.
Note that if you only need to monitor changes in the given source, you can use the `"only_metadata"` format, in which case the table will contain only the `_metadata` column, and no time or resources will be spent on reading the files’ contents.
* **Parameters**
* **source** – PyFilesystem source.
* **path** (`str`) – Path inside the PyFilesystem source to process. All files within this path will be processed recursively. If unspecified, the root of the source is taken.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"`, it will check for updates, deletions, and new files every `refresh_interval` seconds. `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **format** (`Literal`\[`'binary'`, `'only_metadata'`\]) – the format of the resulting table. Can be either `"binary"`, which corresponds to a table with a `data` column containing each file’s contents, or `"only_metadata"`, which corresponds to a table that has only the `_metadata` column with the objects’ metadata, without reading the objects themselves.
* **refresh\_interval** (`int` | `float` | `timedelta`) – time between scans, given as a number of seconds or a `datetime.timedelta` / `pw.Duration`. Applicable if the mode is set to `"streaming"`.
* **with\_metadata** (`bool`) – when set to `True`, the connector will add column named `_metadata` to the table. This column will contain file metadata, such as: `path`, `name`, `owner`, `created_at`, `modified_at`, `accessed_at`, `size`.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
The table read.
Example:
Suppose that you want to read a file from a ZIP archive `projects.zip` with the usage of PyFilesystem. To do that, you first need to import the `fs` library or just the `open_fs` method and to create the data source. It can be done as follows:
`from fs import open_fs source = open_fs("zip://projects.zip")`
Then you can use the connector as follows:
`import pathway as pw table = pw.io.pyfilesystem.read(source)`
This command reads all files in the archive in full. If the data is not supposed to be changed, it makes sense to run this read in the static mode. It can be done by specifying the `mode` parameter:
`table = pw.io.pyfilesystem.read(source, mode="static")`
Please note that PyFilesystem offers a great variety of sources that can be read. You can refer to the “Index of Filesystems” [https://www.pyfilesystem.org/page/index-of-filesystems/](https://www.pyfilesystem.org/page/index-of-filesystems/)
\_ web page for the list and the respective documentation.
For instance, you can also read a dataset from the remote FTP source with this connector. It can be done with the usage of `FTP` file source with the code as follows:
`source = fs.open_fs('ftp://login:password@ftp.example.com/datasets') table = pw.io.pyfilesystem.read(source)`
[Pathway Io\
\
pw.io.pubsub](https://pathway.com/developers/api-docs/pathway-io/pubsub)
[Pathway Io\
\
pw.io.python](https://pathway.com/developers/api-docs/pathway-io/python)
---
# pw.io.plaintext | Pathway
pw.io.plaintext
===============
[**read**(path, \*, mode='streaming', object\_pattern='\*', with\_metadata=False, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/plaintext#pathway.io.plaintext.read)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/plaintext/__init__.py#L14-L91)
Reads a table from a text file or a directory of text files. The resulting table will consist of a single column `data`, and have the number of rows equal to the number of lines in the file. Each cell will contain a single line from the file.
In case the folder is specified, and there are several files placed in the folder, their order is determined according to their modification times: the smaller the modification time is, the earlier the file will be passed to the engine.
* **Parameters**
* **path** (`str` | `PathLike`) – Path to the file or to the folder with files or [glob](https://en.wikipedia.org/wiki/Glob_(programming))
pattern for the objects to be read. The connector will read the contents of all matching files as well as recursively read the contents of all matching folders.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"` the engine will wait for the updates in the specified directory. It will track file additions, deletions, and modifications and reflect these events in the state. For example, if a file was deleted, `"streaming"` mode will also remove rows obtained by reading this file from the table. On the other hand, the `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **object\_pattern** (`str`) – Unix shell style pattern for filtering only certain files in the directory. Ignored in case a path to a single file is specified. This value will be deprecated soon, please use glob pattern in `path` instead.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field that will contain two optional fields - `created_at` and `modified_at`. These fields will have integral UNIX timestamps for the creation and modification time respectively. Additionally, the column will also have an optional field named `owner` that will contain the name of the file owner (applicable only for Un). Finally, the column will also contain a field named `path` that will show the full path to the file from where a row was filled.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every `autocommit_duration_ms` milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
`import pathway as pw t = pw.io.plaintext.read("raw_dataset/lines.txt")`
[Pathway Io\
\
pw.io.pinecone](https://pathway.com/developers/api-docs/pathway-io/pinecone)
[Pathway Io\
\
pw.io.postgres](https://pathway.com/developers/api-docs/pathway-io/postgres)
---
# pw.io.gdrive | Pathway
pw.io.gdrive
============
[**read**(object\_id, \*, mode='streaming', format='binary', object\_size\_limit=None, refresh\_interval=30, service\_user\_credentials\_file, with\_metadata=False, file\_name\_pattern=None, name=None, max\_backlog\_size=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/gdrive#pathway.io.gdrive.read)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/gdrive/__init__.py#L518-L626)
Reads a table from a Google Drive directory or file.
Returns a table containing a binary column `data` with the binary contents of objects in the specified directory, as well as a dict `_metadata` that contains metadata corresponding to each object. Metadata is reported only if the `with_metadata` flag is set, or if the `"only_metadata"` format is chosen.
Note that if you only need to monitor changes in the given directory, you can use the `"only_metadata"` format, in which case the table will contain only metadata, and no time or resources will be spent downloading the objects.
* **Parameters**
* **object\_id** (`str`) – `id` of a directory or file. Directories will be scanned recursively.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"`, it will check for updates, deletions and new files every `refresh_interval` seconds. `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **format** (`Literal`\[`'binary'`, `'only_metadata'`\]) – the format of the resulting table. Can be either `"binary"`, which corresponds to a table with a `data` column containing the object’s contents, or `"only_metadata"`, which corresponds to a table that has only the `_metadata` column with the objects’ metadata, without downloading the objects themselves.
* **object\_size\_limit** (`int` | `None`) – Maximum size (in bytes) of a file that will be processed by this connector or `None` if no filtering by size should be made;
* **refresh\_interval** (`int` | `float` | `timedelta`) – time between scans, given as a number of seconds or a `datetime.timedelta` / `pw.Duration`. Applicable if mode is set to `"streaming"`.
* **service\_user\_credentials\_file** (`str` | `PathLike`) – Google API service user json file. Please follow the instructions provided in the [developer’s user guide](https://pathway.com/developers/user-guide/connect/connectors/gdrive-connector/#setting-up-google-drive)
to obtain them.
* **with\_metadata** (`bool`) – when set to `True`, the connector will add an additional column named `_metadata` to the table. This column will contain file metadata, such as: `id`, `name`, `mimeType`, `parents`, `modifiedTime`, `thumbnailLink`, `lastModifyingUser`.
* **file\_name\_pattern** (`list` | `str` | `None`) – glob pattern (or list of patterns) to be used to filter files based on their names. Defaults to `None` which doesn’t filter anything. Doesn’t apply to folder names. For example, `*.pdf` will only return files that has `.pdf` extension.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
The table read.
Example:
`import pathway as pw table = pw.io.gdrive.read( object_id="0BzDTMZY18pgfcGg4ZXFRTDFBX0j", service_user_credentials_file="credentials.json" )`
[Pathway Io\
\
pw.io.fs](https://pathway.com/developers/api-docs/pathway-io/fs)
[Pathway Io\
\
pw.io.http](https://pathway.com/developers/api-docs/pathway-io/http)
---
# pw.io.leann | Pathway
pw.io.leann
===========
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
[**write**(table, index\_path, text\_column, \*, metadata\_columns=None, backend\_name='hnsw', embedding\_mode=None, embedding\_model=None, embedding\_options=None, name=None)](https://pathway.com/developers/api-docs/pathway-io/leann#pathway.io.leann.write)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/leann/__init__.py#L133-L290)
Write table data to a [LEANN](https://github.com/yichuan-w/LEANN)
vector index.
LEANN is a storage-efficient vector database that uses graph-based selective recomputation to achieve up to 97% storage reduction compared to traditional vector databases while maintaining high recall.
The connector observes every Pathway Live Data Framework minibatch. Whenever rows are added or removed, it rebuilds the full LEANN index from the current snapshot of the table. The result is written as a set of files that share `index_path` as their prefix (e.g. `./articles.leann.hnsw`, `./articles.leann.meta.json`). This keeps the index always consistent with the latest committed state of the table.
**Performance considerations.** LEANN currently builds the index from scratch on every update — there is no incremental add or delete operation. If the document set is large and changes arrive frequently, rebuilding the full index after every minibatch will be slow. Use this connector with caution in streaming pipelines:
* **Static mode** is the ideal fit. When you run the Pathway Live Data Framework once to convert a collection from one format into a LEANN index, the index is built exactly once and the cost is fully amortized.
* **Infrequent commits** also work well. If your streaming pipeline commits rarely (large `autocommit_duration_ms`, or an external commit trigger), rebuilds happen seldom and the overhead stays manageable.
* **High-frequency streaming** over a large corpus is not a good fit. Every commit triggers a full rebuild; with many small commits and thousands of documents this can become a bottleneck. In that scenario, consider a vector store that supports incremental updates.
**Limitations.** Only `str` columns are accepted for `text_column` and `metadata_columns` — passing a column of any other type raises a `ValueError` at pipeline construction time. Rows whose text column is empty or `None` are silently skipped and a warning is logged.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The Pathway Live Data Framework table to index.
* **index\_path** (`str` | `PathLike`) – Prefix for the LEANN index files. LEANN writes several files with this value as the common prefix (e.g. providing `"./articles.leann"` produces `"./articles.leann.hnsw"`, `"./articles.leann.meta.json"`, and so on).
* **text\_column** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – Column reference for the column containing text to embed (e.g. `table.body`). The column must belong to `table` and be of type `str`.
* **metadata\_columns** (`list`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\] | `None`) – Column references for additional `str` columns to store alongside each vector (e.g. `table.title, table.category`). All columns must belong to `table`.
* **backend\_name** (`Literal`\[`'hnsw'`, `'diskann'`\]) – LEANN graph backend — `"hnsw"` (default) or `"diskann"`.
* **embedding\_mode** (`Optional`\[`Literal`\[`'sentence-transformers'`, `'openai'`, `'mlx'`, `'ollama'`\]\]) – Embedding provider — `"sentence-transformers"`, `"openai"`, `"mlx"`, or `"ollama"`. When `None`, LEANN’s own default is used.
* **embedding\_model** (`str` | `None`) – Specific model name, e.g. `"facebook/contriever"`. When `None`, the provider’s default model is used.
* **embedding\_options** (`dict` | `None`) – Additional options forwarded to the embedding provider, e.g. `{"api_key": "...", "base_url": "..."}`.
* **name** (`str` | `None`) – Unique name for this connector instance, used in logs and persistence snapshots.
* **Returns**
None
Note:
* The index is fully rebuilt after every minibatch that contains changes. Existing index files are overwritten on each build.
* Requires the `leann` package. See [https://github.com/yichuan-w/LEANN](https://github.com/yichuan-w/LEANN)
for installation instructions.
Example:
Suppose you have a CSV file `articles.csv` with columns `title`, `body`, and `category`, and you want to build a LEANN vector index over the article bodies so that you can run semantic search against it.
Start by defining the schema that matches your CSV:
`import pathway as pw class ArticleSchema(pw.Schema): title: str body: str category: str`
Read the source file and register the LEANN sink. Pass the `body` column as the text to embed; `title` and `category` are stored as metadata that travels with each vector and can be returned alongside search results:
`table = pw.io.csv.read("articles.csv", schema=ArticleSchema) pw.io.leann.write( table, index_path="./articles.leann", text_column=table.body, metadata_columns=[table.title, table.category], backend_name="hnsw", embedding_model="facebook/contriever", )`
Run the pipeline. In static mode the Pathway Live Data Framework processes the file once and writes the index; in streaming mode it keeps the index up to date as new articles arrive:
`pw.run()`
[Pathway Io\
\
pw.io.kinesis](https://pathway.com/developers/api-docs/pathway-io/kinesis)
[Pathway Io\
\
pw.io.logstash](https://pathway.com/developers/api-docs/pathway-io/logstash)
---
# pw.io.milvus | Pathway
pw.io.milvus
============
[**write**(table, uri, collection\_name, \*, primary\_key, batch\_size=256, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/milvus#pathway.io.milvus.write)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/milvus/__init__.py#L136-L360)
**This connector is available when using one of the following licenses only:**[Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise](https://pathway.com/pricing)
.
Writes a Pathway Live Data Framework table to a Milvus collection.
Each row addition (`diff = 1`) is sent to Milvus as an upsert and each row deletion (`diff = -1`) is sent as a delete. The value of the `primary_key` column is used as the Milvus primary key. The column must belong to `table`; passing a column from a different table raises a `ValueError`.
The target collection must already exist before the pipeline starts and its schema must be compatible with the table’s columns. The Pathway Live Data Framework cannot create it automatically because the vector field dimension is not part of the Python type (a `list` of floats carries no size) and is only known once the first row arrives. Use `pymilvus.MilvusClient.create_collection` to create the collection upfront.
Within every mini-batch, deletes are applied before upserts so that update pairs (retraction followed by insertion of the same key) are handled correctly.
**Supported type mappings** (Pathway Live Data Framework → Milvus):
| Pathway Live Data Framework type | Milvus field type | Notes |
| --- | --- | --- |
| `int` | `INT64` | |
| `float` | `DOUBLE` | |
| `str` | `VARCHAR` | Field must declare `max_length` |
| `bool` | `BOOL` | |
| `pw.Json` | `JSON` | Wrapper unwrapped automatically |
| `list` of `float` | `FLOAT_VECTOR` | Dimension set in the collection schema |
| `bytes` | `BINARY_VECTOR` | Dimension set in the collection schema |
| `numpy.ndarray` | `FLOAT_VECTOR` or `BINARY_VECTOR` | Must be 1-D; converted to list |
Any other Pathway Live Data Framework type raises a `TypeError` before reaching pymilvus, with a message that names the offending column and lists the supported types. A multi-dimensional `numpy.ndarray` raises a `ValueError`.
The `uri` parameter is passed directly to `pymilvus.MilvusClient`. Use a local `.db` file path (e.g. `"./milvus.db"`) to use [Milvus Lite](https://milvus.io/docs/milvus_lite.md)
, an embedded single-file database that requires no server, which is convenient for development and testing. Use a server address (e.g. `"http://localhost:19530"`) to connect to a running Milvus instance for production workloads.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **uri** (`str`) – URI passed to `pymilvus.MilvusClient`. Use a local `.db` file path for Milvus Lite (e.g. `"./milvus.db"`) or a server address for a running Milvus instance (e.g. `"http://localhost:19530"`).
* **collection\_name** (`str`) – Name of the Milvus collection to write to.
* **primary\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – A column reference (e.g. `table.doc_id`) whose values are used as the Milvus primary key. The column must belong to `table`.
* **batch\_size** (`int`) – Maximum number of rows sent to Milvus in a single `upsert` or `delete` request. A mini-batch larger than this is split into several requests so that no single gRPC message exceeds Milvus’s message-size limit (64 MiB by default), which would otherwise make Milvus reject a large commit with `RESOURCE_EXHAUSTED`. Deletes are always issued before upserts within a mini-batch regardless of chunking. Must be a positive integer.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output within each mini-batch will be sorted in ascending order by the given columns. When multiple columns are provided, the corresponding value tuples are compared lexicographically.
* **Returns**
None
Example:
Suppose you are building a document search pipeline and want to store embeddings in Milvus. The example below uses Milvus Lite — a local single-file database that requires no running server, which is convenient for development. For production, replace `"./milvus.db"` with your server URI, e.g. `"http://localhost:19530"`.
Create the collection before starting the pipeline. The schema must define an integer primary key and a `FLOAT_VECTOR` field whose dimension matches the embeddings your pipeline will produce:
`import pathway as pw from pymilvus import DataType, MilvusClient client = MilvusClient("./milvus.db") schema = client.create_schema(auto_id=False) schema.add_field("doc_id", DataType.INT64, is_primary=True) schema.add_field("embedding", DataType.FLOAT_VECTOR, dim=4) index_params = client.prepare_index_params() index_params.add_index("embedding", metric_type="COSINE", index_type="FLAT") client.create_collection("docs", schema=schema, index_params=index_params) client.close()`
Define your Pathway Live Data Framework schema and build the table:
`class DocSchema(pw.Schema): doc_id: int = pw.column_definition(primary_key=True) embedding: list[float] table = pw.debug.table_from_rows( DocSchema, [(1, [0.1, 0.2, 0.3, 0.4]), (2, [0.5, 0.6, 0.7, 0.8])], )`
Attach the Milvus output connector and specify which column maps to the Milvus primary key field:
`pw.io.milvus.write( table, uri="./milvus.db", collection_name="docs", primary_key=table.doc_id, ) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
[Pathway Io\
\
pw.io.logstash](https://pathway.com/developers/api-docs/pathway-io/logstash)
[Pathway Io\
\
pw.io.minio](https://pathway.com/developers/api-docs/pathway-io/minio)
---
# pw.io.bigquery | Pathway
pw.io.bigquery
==============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
[**write**(table, dataset\_name, table\_name, service\_user\_credentials\_file, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/bigquery#pathway.io.bigquery.write)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/bigquery/__init__.py#L61-L125)
Writes `table`’s stream of changes into the specified BigQuery table. Please note that the schema of the target table must correspond to the schema of the table that is being outputted and include two additional fields: an integral field `time`, denoting the ID of the minibatch where the change occurred and an integral field `diff` which can be either 1 or -1 and which denotes if the entry was inserted to the table or if it was deleted.
Note that the modification of the row is denoted with a sequence of two operations: the deletion operation (`diff = -1`) and the insertion operation (`diff = 1`).
* **Parameters**
* **table** (`Table`) – The table to output.
* **dataset\_name** (`str`) – The name of the dataset where the table is located.
* **table\_name** (`str`) – The name of the table to be written.
* **service\_user\_credentials\_file** (`str`) – Google API service user json file. Please follow the instructions provided in the [developer’s user guide](https://pathway.com/developers/user-guide/connect/connectors/gdrive-connector/#setting-up-google-drive)
to obtain them.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
Suppose that there is a Google BigQuery project with a dataset named `animals` and you want to output the Pathway Live Data Framework table `animal_measurements` into this dataset’s table `measurements`.
Consider that the credentials are stored in the file `./credentials.json`. Then, you can configure the output as follows:
`pw.io.bigquery.write( animal_measurements, dataset_name="animals", table_name="measurements", service_user_credentials_file="./credentials.json" )`
[Pathway Io\
\
pw.io.airbyte](https://pathway.com/developers/api-docs/pathway-io/airbyte)
[Pathway Io\
\
pw.io.chroma](https://pathway.com/developers/api-docs/pathway-io/chroma)
---
# pw.io.debezium | Pathway
pw.io.debezium
==============
[**read**(rdkafka\_settings, topic\_name, \*, db\_type=, schema, debug\_data=None, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/debezium#pathway.io.debezium.read)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/debezium/__init__.py#L15-L135)
Connector, which takes a topic in the format of Debezium and maintains a corresponding table in Pathway Live Data Framework, on which you can do all the table operations provided. In order to do that, you will need a Debezium connector.
* **Parameters**
* **rdkafka\_settings** (`dict`) – Connection settings in the format of [librdkafka](https://github.com/edenhill/librdkafka/blob/master/CONFIGURATION.md)
.
* **topic\_name** (`str`) – Name of topic in Kafka to which the updates are streamed.
* **db\_type** (`DebeziumDBType`) – Type of the database from which events are streamed;
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
_Table_ – The table read.
Example:
Consider there is a need to stream a database table along with its changes directly into the Pathway Live Data Framework engine. One of the standard well-known solutions for table streaming is [Debezium](https://debezium.io/)
: it supports streaming data from MySQL, Postgres, MongoDB and a few more databases directly to a topic in Kafka. The streaming first sends a snapshot of the data and then streams changes for the specific change (namely: inserted, updated or removed) rows.
Consider there is a table in Postgres, which is created according to the following schema:
`CREATE TABLE pets ( id SERIAL PRIMARY KEY, age INTEGER, owner TEXT, pet TEXT );`
This table, by default, will be streamed to the topic with the same name. In order to read it,you need to set the settings for `rdkafka`. For the sake of demonstration, let’s take those from the example of the Kafka connector:
`import os rdkafka_settings = { "bootstrap.servers": "localhost:9092", "security.protocol": "sasl_ssl", "sasl.mechanism": "SCRAM-SHA-256", "group.id": "$GROUP_NAME", "session.timeout.ms": "60000", "sasl.username": os.environ["KAFKA_USERNAME"], "sasl.password": os.environ["KAFKA_PASSWORD"] }`
Now, using the settings you can set up a connector. It is as simple as:
`import pathway as pw class InputSchema(pw.Schema): id: str = pw.column_definition(primary_key=True) age: int owner: str pet: str t = pw.io.debezium.read( rdkafka_settings, topic_name="pets", schema=InputSchema )`
As a result, upon its start, the connector would provide the full snapshot of the table `pets` into the table `t` in Pathway. The table `t` can then be operated as usual. Throughout the run time, the rows in the table `pets` can change. In this case, the changes in the result will be provided in the output connectors by the Stream of Updates mechanism.
[Pathway Io\
\
pw.io.csv](https://pathway.com/developers/api-docs/pathway-io/csv)
[Pathway Io\
\
pw.io.deltalake](https://pathway.com/developers/api-docs/pathway-io/deltalake)
---
# pw.io.qdrant | Pathway
pw.io.qdrant
============
**This module is available when using one of the following licenses only:** [Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise](https://pathway.com/pricing)
.
[**write**(table, url, collection\_name, \*, api\_key=None, batch\_size=256, name=None)](https://pathway.com/developers/api-docs/pathway-io/qdrant#pathway.io.qdrant.write)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/qdrant/__init__.py#L13-L162)
Writes a Pathway Live Data Framework table to a [Qdrant](https://qdrant.tech/)
collection.
The collection schema is the single source of truth for what is written as a vector. At startup the connector introspects the collection and binds every declared named vector slot to the table column **with the same name**:
* a _dense_ slot is bound to a `list[float]` (or 1-D numeric `numpy.ndarray`) column;
* a _sparse_ slot is bound to a `list[tuple[int, float]]` column holding `(index, weight)` pairs;
* _multivector_ slots (`list[list[float]]` columns) are not supported yet and raise `NotImplementedError`.
Columns whose names match no vector slot are stored in the point payload. All vectors of a point are written atomically in the same upsert, which enables native hybrid (dense + sparse, e.g. BM25) search. Sparse weights are sent raw (e.g. term frequencies); when the sparse slot is configured with the IDF modifier, Qdrant applies IDF server-side.
The collection is **never created automatically** — create it beforehand with the desired named vector configuration (dimensions, distance metrics, IDF modifier, etc.). The connector fails fast at startup if the collection does not exist, declares no vector slots, uses a single unnamed vector, declares a slot with no same-named column, or a slot’s kind does not match the column’s type. A dense vector whose dimension does not match the slot’s configured dimension is rejected at write time with an error naming the slot and both dimensions.
Each row addition (`diff = 1`) is sent to Qdrant as a point upsert and each row deletion (`diff = -1`) removes the corresponding point. The point id is assigned internally rather than taken from a column, so keep any identifier you need as an ordinary column (it is stored in the payload). Within every minibatch an insertion always wins over a deletion of the same key, so an update (a retraction of the old row followed by an insertion of the new one) replaces the point rather than removing it.
Payload columns may be of any type the Pathway Live Data Framework JSON serializer supports (`int`, `float`, `str`, `bool`, `pw.Json`, lists, tuples, `bytes`, and 1-D `numpy.ndarray`).
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **url** (`str`) – URL of the Qdrant instance’s gRPC endpoint, e.g. `"http://localhost:6334"` (Qdrant’s gRPC port is `6334` by default).
* **collection\_name** (`str`) – Name of the pre-created Qdrant collection to write to.
* **api\_key** (`str` | `None`) – Optional API key used to authenticate with Qdrant Cloud or a secured instance.
* **batch\_size** (`int`) – Maximum number of points sent to Qdrant in a single upsert or delete request. A minibatch larger than this is split into several requests, keeping each request bounded for high-dimensional vectors.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **Returns**
None
Example:
Suppose you are building a hybrid document search pipeline: dense embeddings for semantic similarity plus sparse term weights for BM25-style scoring. First create the collection with a named dense slot and a named sparse slot (using the [qdrant-client](https://python-client.qdrant.tech/)
package):
`from qdrant_client import QdrantClient, models client = QdrantClient(url="http://localhost:6333") client.create_collection( collection_name="docs", vectors_config={ "embedding": models.VectorParams( size=4, distance=models.Distance.COSINE ), }, sparse_vectors_config={ "bm25": models.SparseVectorParams( modifier=models.Modifier.IDF ), }, )`
Then write a table whose column names match the slot names. The `embedding` column feeds the dense slot, `bm25` feeds the sparse slot (raw term frequencies as `(token_id, count)` pairs — IDF is applied by Qdrant), and the remaining columns (`doc_id`, `title`) are stored in the point payload:
`import pathway as pw class DocSchema(pw.Schema): doc_id: int = pw.column_definition(primary_key=True) embedding: list[float] bm25: list[tuple[int, float]] title: str table = pw.debug.table_from_rows( DocSchema, [ (1, [0.1, 0.2, 0.3, 0.4], [(7, 2.0), (21, 1.0)], "a"), (2, [0.5, 0.6, 0.7, 0.8], [(3, 1.0)], "b"), ], ) pw.io.qdrant.write( table, url="http://localhost:6334", collection_name="docs", ) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
If the collection declares only the dense `embedding` slot, drop the `bm25` column from the schema above — this is the common non-hybrid setup.
[Pathway Io\
\
pw.io.python](https://pathway.com/developers/api-docs/pathway-io/python)
[Pathway Io\
\
pw.io.questdb](https://pathway.com/developers/api-docs/pathway-io/questdb)
---
# pw.io.mqtt | Pathway
pw.io.mqtt
==========
[**read**(uri, topic, \*, qos=2, schema=None, format='raw', autocommit\_duration\_ms=1500, json\_field\_paths=None, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/mqtt#pathway.io.mqtt.read)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mqtt/__init__.py#L20-L163)
Reads data from a specified MQTT topic.
It supports three formats: `"plaintext"`, `"raw"`, and `"json"`.
For the `"raw"` format, the payload is read as raw bytes and added directly to the table. In the `"plaintext"` format, the payload decoded from UTF-8 and stored as plain text. In both cases, the table will have an autogenerated primary key and a single `"data"` column representing the payload.
If you select the `"json"` format, the connector parses the message payload as JSON and creates table columns based on the schema provided in the `schema` parameter. The column values come from the corresponding JSON fields.
* **Parameters**
* **uri** (`str`) – The connection string for the MQTT broker.
* **topic** (`str`) – The name of the MQTT topic to read data from.
* **qos** (`int`) – The [QoS (Quality of Service) value](https://www.hivemq.com/blog/mqtt-essentials-part-6-mqtt-quality-of-service-levels/)
value for the connection. Note that the final QoS is determined by the broker as the lower of the writer’s and reader’s QoS levels.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – The table schema, used only when the format is set to `"json"`.
* **format** (`Literal`\[`'plaintext'`, `'raw'`, `'json'`\]) – The input data format, which can be `"raw"`, `"plaintext"`, or `"json"`.
* **autocommit\_duration\_ms** (`int` | `None`) – The time interval (in milliseconds) between commits. After this time, the updates received by the connector are committed and added to Pathway Live Data Framework’s computation graph.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – For the `"json"` format, this allows mapping field names to paths within the JSON structure. Use the format `: ` where the path follows the [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
To run local tests, you can either install an MQTT broker like [Mosquitto](https://mosquitto.org/)
on your machine or use a [Docker image](https://hub.docker.com/_/eclipse-mosquitto)
with the communication port exposed. By default, port `1883` is commonly used.
If your MQTT broker is running on `localhost` using the default port, you can stream the `"test/data"` topic to a Pathway Live Data Framework table like this:
`import pathway as pw table = pw.io.mqtt.read("mqtt://localhost:1883/?client_id=test", "test/data")`
Keep in mind that MQTT does not guarantee message storage. In other words, you cannot assume that a message present in the queue will remain there. MQTT also lacks any concept of message offsets within a topic. As a result, when Pathway Live Data Framework persistence is enabled, it saves the message stream without making assumptions about the topic’s state at the time of a restart. Therefore, we recommend designing your data flow to tolerate at-least-once or at-most-once delivery semantics depending on the configuration.
You can also parse messages as UTF-8 during reading by using the `"format"` parameter. Here’s how the reading process would look:
`table = pw.io.mqtt.read( "mqtt://localhost:1883/?client_id=test", "test/data", format="plaintext" )`
Alternatively, you can read and parse a JSON table during the reading process by using the `"json"` format and the `schema` parameter.
For example, if your data is in JSON format with three fields - an integer `user_id` (which you’d like to use as the primary key instead of an autogenerated one), and two string fields `username` and `phone` - you can define the schema like this:
`class InputSchema(pw.Schema): user_id: int = pw.column_definition(primary_key=True) username: str phone: str`
Now, you can use the `format` and `schema` parameters of the connector like this:
`table = pw.io.mqtt.read( "mqtt://localhost:1883/?client_id=test", "data", format="json", schema=InputSchema, )`
As a result, you will have a table with three columns: `"user_id"`, `"username"`, and `"phone"`. The `"user_id"` column will also act as the primary key for the Pathway Live Data Framework table.
[**write**(table, uri, topic, \*, qos=2, retain=False, format='json', delimiter=',', value=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/mqtt#pathway.io.mqtt.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mqtt/__init__.py#L166-L314)
Writes data into the specified MQTT topic.
There are several serialization formats supported: `"json"`, `"dsv"`, `"plaintext"` and `"raw"`. The format defines how the message is formed. In case of JSON and DSV (delimiter separated values), the message is formed in accordance with the respective data format.
The produced messages consist of the payload, corresponding to the values of the table that are serialized according to the chosen format. Please note that the `time` and `diff` values aren’t reported if `"plaintext"` or `"binary"` formats are used.
If the selected format is either `"plaintext"` or `"raw"`, you also need to specify, which column of the table correspond to the payload of the produced MQTT message. It can be done by providing `value` parameter. It can also be deduced automatically if the table consists of a single column.
Please note that MQTT v5-specific features, such as user-defined message headers, are not yet supported but will be added soon. In the meantime, the connector is compatible with both older MQTT versions and v5.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table for output.
* **uri** (`str`) – The URI of the MQTT broker.
* **topic** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The MQTT topic where data will be written. This can be a specific topic name or a reference to a column whose values will be used as the topic for each message. If using a column reference, the column must contain string values.
* **qos** (`int`) – The [QoS (Quality of Service) value](https://www.hivemq.com/blog/mqtt-essentials-part-6-mqtt-quality-of-service-levels/)
value for the connection. Note that the final QoS is determined by the broker as the lower of the writer’s and reader’s QoS levels.
* **retain** (`bool`) – If set to `True`, the MQTT broker will retain the last message published to the topic.
* **format** (`Literal`\[`'json'`, `'dsv'`, `'plaintext'`, `'raw'`\]) – format in which the data is put into MQTT. Currently `"json"`, `"plaintext"`, `"raw"` and `"dsv"` are supported. If the `"raw"` format is selected, `table` must either contain exactly one binary column that will be dumped as it is into the message, or the reference to the target binary column must be specified explicitly in the `value` parameter. Similarly, if `"plaintext"` is chosen, the table should consist of a single column of the string type.
* **delimiter** (`str`) – field delimiter to be used in case of delimiter-separated values format.
* **value** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – reference to the column that should be used as a payload in the produced message in `"plaintext"` or `"raw"` format. It can be deduced automatically if the table has exactly one column. Otherwise it must be specified directly.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
Example:
Assume you have the MQTT server running locally on the default port, `1883`. Let’s explore a few ways to send the contents of a table to the topic `test/topic` on this server.
First, you’ll need to create a Pathway Live Data Framework table. You can do this using the `table_from_markdown` method to set up a test table with information about pets and their owners.
`import pathway as pw table = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | cat 8 | Alice | cat ''')`
To output the table’s contents in JSON format, use the connector like this:
`pw.io.mqtt.write( table, "mqtt://localhost:1883/?client_id=test", topic="test/topic", format="json", )`
In this case, the output will include the table’s rows in JSON format, with `time` and `diff` fields added to each JSON payload.
You can also use a single column from the table as the payload. For instance, to use the `owner` column as the MQTT message payload, implement it as follows:
`pw.io.mqtt.write( table, "mqtt://localhost:1883/?client_id=test", topic="test/topic", format="plaintext", value=table.owner, )`
Finally, if you’d like the topic to be dynamic and depend on the owner of the pet, you can specify this column definition as the topic:
`pw.io.mqtt.write( table, "mqtt://localhost:1883/?client_id=test", topic=table.owner, format="json", )`
---
# pw.io.redpanda | Pathway
pw.io.redpanda
==============
[**read**(rdkafka\_settings, topic=None, \*, schema=None, mode='streaming', format='raw', schema\_registry\_settings=None, debug\_data=None, autocommit\_duration\_ms=1500, json\_field\_paths=None, parallel\_readers=None, name=None, max\_backlog\_size=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/redpanda#pathway.io.redpanda.read)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/redpanda/__init__.py#L17-L206)
Reads table from a set of topics in Redpanda.
There are three formats currently supported: `"plaintext"`, `"raw"`, and `"json"`. If the `"raw"` format is chosen, the key and the payload are read from the topic as raw bytes and used in the table “as is”. If you choose the `"plaintext"` option, however, they are parsed from the UTF-8 into the plaintext entries. In both cases, the table consists of a primary key and two columns `"key"` and `"data"`, denoting the key and the payload read.
If `"json"` is chosen, the connector first parses the payload of the message according to the JSON format and then creates the columns corresponding to the schema defined by the `schema` parameter. The values of these columns are taken from the respective parsed JSON fields.
* **Parameters**
* **rdkafka\_settings** (`dict`) – Connection settings in the format of [librdkafka](https://github.com/edenhill/librdkafka/blob/master/CONFIGURATION.md)
.
* **topic** (`str` | `list`\[`str`\] | `None`) – Name of topic in Redpanda from which the data should be read.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Specifies how the engine retrieves data from the topic. The default value is `"streaming"`, which means the engine will constantly wait for new messages, process them as they arrive, and send them into the engine. Alternatively, if set to `"static"`, the engine will only read and process the data that is already available at the time of execution.
* **format** (`Literal`\[`'raw'`, `'csv'`, `'json'`\]) – format of the input data, `"raw"`, `"plaintext"`, or `"json"`.
* **schema\_registry\_settings** ([`SchemaRegistrySettings`](https://pathway.com/developers/api-docs/pathway-io-kafka#pathway.io.kafka.SchemaRegistrySettings)
| `None`) – settings for connecting to the Confluent Schema Registry, if this type of registry is used.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is JSON, this field allows to map field names into path in the field. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **parallel\_readers** (`int` | `None`) – number of copies of the reader to work in parallel. In case the number is not specified, min{pathway\_threads, total number of partitions} will be taken. This number also can’t be greater than the number of Pathway Live Data Framework engine threads, and will be reduced to the number of engine threads, if it exceeds.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
_Table_ – The table read.
When using the format `"raw"` or `"plaintext"`, the connector will produce a two-column table: all the payloads are saved into a column named `data`, while the keys are saved into a column `key`.
For other formats, the schema is required and defines the columns.
Example:
Consider a queue in Redpanda running locally on port 9092. Our queue uses SASL-SSL authentication with the SCRAM-SHA-256 mechanism. You can set up a managed cluster with similar parameters directly on the [Redpanda](https://www.redpanda.com/try-redpanda)
website. The rdkafka settings for the connection will look as follows:
`import os rdkafka_settings = { "bootstrap.servers": "localhost:9092", "group.id": "kafka-tests", "security.protocol": "sasl_ssl", "sasl.mechanism": "SCRAM-SHA-256", "sasl.username": os.environ["KAFKA_USERNAME"], "sasl.password": os.environ["KAFKA_PASSWORD"], }`
To connect to the topic “animals” and accept messages, the connector must be used as follows, depending on the format. Please note that this topic may need to be created beforehand in the interface, if the managed version is used.
Raw version:
`import pathway as pw t = pw.io.redpanda.read( rdkafka_settings, topic="animals", format="raw", )`
All the data will be accessible in the column data.
JSON version:
`import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.redpanda.read( rdkafka_settings, topic="animals", format="json", schema=InputSchema, )`
For the JSON connector, you can send these two messages:
`{"owner": "Alice", "pet": "cat"} {"owner": "Bob", "pet": "dog"}`
This way, you get a table which looks as follows:
`pw.debug.compute_and_print(t, include_id=False)`
Code Results
Now consider that the data about pets come in a more sophisticated way. For instance you have an owner, kind and name of an animal, along with some physical measurements.
The JSON payload in this case may look as follows:
`{ "name": "Jack", "pet": { "animal": "cat", "name": "Bob", "measurements": [100, 200, 300] } }`
Suppose you need to extract a name of the pet and the height, which is the 2nd (1-based) or the 1st (0-based) element in the array of measurements. Then, you use JSON Pointer and do a connector, which gets the data as follows:
`import pathway as pw class InputSchema(pw.Schema): pet_name: str pet_height: int t = pw.io.redpanda.read( rdkafka_settings, topic="animals", format="json", schema=InputSchema, json_field_paths={ "pet_name": "/pet/name", "pet_height": "/pet/measurements/1" }, )`
[**write**(table, rdkafka\_settings, topic\_name, \*, format='json', schema\_registry\_settings=None, subject=None, name=None, sort\_by=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/redpanda#pathway.io.redpanda.write)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/redpanda/__init__.py#L209-L295)
Write a table to a given topic on a Redpanda instance.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the table to output.
* **rdkafka\_settings** (`dict`) – Connection settings in the format of [librdkafka](https://github.com/edenhill/librdkafka/blob/master/CONFIGURATION.md)
.
* **topic\_name** (`str`) – name of topic in Redpanda to which the data should be sent.
* **format** (`Literal`\[`'json'`\]) – format of the input data, only “json” is currently supported.
* **schema\_registry\_settings** ([`SchemaRegistrySettings`](https://pathway.com/developers/api-docs/pathway-io-kafka#pathway.io.kafka.SchemaRegistrySettings)
| `None`) – settings for connecting to the Confluent Schema Registry, if this type of registry is used.
* **subject** (`str` | `None`) – the subject name for the schema in the Confluent Schema Registry, if the registry is used.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Limitations:
For future proofing, the format is configurable, but (for now) only JSON is available.
Example:
Consider a queue in Redpanda running locally on port 9092. Our queue uses SASL-SSL authentication with the SCRAM-SHA-256 mechanism. You can set up a managed cluster with similar parameters directly on the [Redpanda](https://www.redpanda.com/try-redpanda)
website. The rdkafka settings for the connection will look as follows:
`import os rdkafka_settings = { "bootstrap.servers": "localhost:9092", "security.protocol": "sasl_ssl", "sasl.mechanism": "SCRAM-SHA-256", "sasl.username": os.environ["KAFKA_USERNAME"], "sasl.password": os.environ["KAFKA_PASSWORD"], }`
You want to send a Pathway Live Data Framework table t to the Redpanda instance.
`import pathway as pw t = pw.debug.table_from_markdown("age owner pet \n 1 10 Alice dog \n 2 9 Bob cat \n 3 8 Alice cat")`
To connect to the topic “animals” and send messages, the connector must be used as follows, depending on the format:
JSON version:
`pw.io.redpanda.write( t, rdkafka_settings, "animals", format="json", )`
All the updates of table t will be sent to the Redpanda instance.
[Pathway Io\
\
pw.io.rabbitmq](https://pathway.com/developers/api-docs/pathway-io/rabbitmq)
[Pathway Io\
\
pw.io.s3](https://pathway.com/developers/api-docs/pathway-io/s3)
---
# pw.io.nats | Pathway
pw.io.nats
==========
[**read**(uri, topic, \*, schema=None, format='raw', autocommit\_duration\_ms=1500, json\_field\_paths=None, jetstream\_stream\_name=None, durable\_consumer\_name=None, parallel\_readers=None, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/nats#pathway.io.nats.read)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/nats/__init__.py#L22-L207)
Reads data from a specified NATS topic.
It supports three formats: `"plaintext"`, `"raw"`, and `"json"`.
For the `"raw"` format, the payload is read as raw bytes and added directly to the table. In the `"plaintext"` format, the payload decoded from UTF-8 and stored as plain text. In both cases, the table will have an autogenerated primary key and a single `"data"` column representing the payload.
If you select the `"json"` format, the connector parses the message payload as JSON and creates table columns based on the schema provided in the `schema` parameter. The column values come from the corresponding JSON fields.
The JetStream extension is supported. To read a NATS topic from a JetStream stream, specify the `jetstream_stream_name` parameter. When this parameter is provided, The Pathway Live Data Framework will use the given stream to read data.
You can also use your own durable JetStream pull consumer if you already have one. To do this, specify the `durable_consumer_name` parameter. Otherwise, the Pathway Live Data Framework will automatically create a durable consumer for you with an auto-generated name. This name will remain the same as long as you do not change your set of input sources.
* **Parameters**
* **uri** (`str`) – The URI of the NATS server.
* **topic** (`str`) – The name of the NATS topic to read data from.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – The table schema, used only when the format is set to `"json"`.
* **format** (`Literal`\[`'plaintext'`, `'raw'`, `'json'`\]) – The input data format, which can be `"raw"`, `"plaintext"`, or `"json"`.
* **autocommit\_duration\_ms** (`int` | `None`) – The time interval (in milliseconds) between commits. After this time, the updates received by the connector are committed and added to Pathway Live Data Framework’s computation graph.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – For the `"json"` format, this allows mapping field names to paths within the JSON structure. Use the format `: ` where the path follows the [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **jetstream\_stream\_name** (`str` | `None`) – if specified, the [JetStream](https://docs.nats.io/nats-concepts/jetstream)
extension is used. In this case, the specified stream will be used.
* **durable\_consumer\_name** (`str` | `None`) – the name of the durable pull consumer to use with JetStream. If not specified, the consumer will be created automatically with default settings. The consumer’s name will remain the same unless the set of input sources is changed.
* **parallel\_readers** (`int` | `None`) – The number of reader instances running in parallel. If not specified, it defaults to `min(pathway_threads, total_partitions)`. It can’t exceed the number of Pathway Live Data Framework engine threads and will be reduced if necessary.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
To run local tests, you can download the `nats-server` binary from the [Releases page](https://github.com/nats-io/nats-server/releases)
and start it. By default, it runs on port `4222` at `localhost`.
If your NATS server is running on `localhost` using the default port, you can stream the `"data"` topic to a Pathway Live Data Framework table like this:
`import pathway as pw table = pw.io.nats.read("nats://127.0.0.1:4222", "data")`
Keep in mind that NATS doesn’t normally store messages. So, make sure to start your The Pathway Live Data Framework program before sending any messages.
You can also parse messages as UTF-8 during reading by using the `"format"` parameter. Here’s how the reading process would look:
`table = pw.io.nats.read("nats://127.0.0.1:4222", "data", format="plaintext")`
Alternatively, you can read and parse a JSON table during the reading process by using the `"json"` format and the `schema` parameter.
For example, if your data is in JSON format with three fields - an integer `user_id` (which you’d like to use as the primary key instead of an autogenerated one), and two string fields `username` and `phone` - you can define the schema like this:
`class InputSchema(pw.Schema): user_id: int = pw.column_definition(primary_key=True) username: str phone: str`
Now, you can use the `format` and `schema` parameters of the connector like this:
`table = pw.io.nats.read( "nats://127.0.0.1:4222", "data", format="json", schema=InputSchema, )`
As a result, you will have a table with three columns: `"user_id"`, `"username"`, and `"phone"`. The `"user_id"` column will also act as the primary key for the Pathway Live Data Framework table.
If you are using the JetStream extension for your NATS connector, you need to provide the `jetstream_stream_name` field, specifying name of the persistent data stream. The code then looks as follows:
`table = pw.io.nats.read( "nats://127.0.0.1:4222", "data", format="json", schema=InputSchema, jetstream_stream_name="your_stream_name", )`
Note that the autogenerated name of the durable consumer won’t change. Therefore, if you restart your Pathway Live Data Framework program, this configuration will only read the new messages that were added after the last execution. For example, if two new messages arrived since the previous run, only those two messages will be read.
If desired, you can also specify the name of your own durable consumer by setting the `durable_consumer_name` field. This allows the Pathway Live Data Framework to use your existing durable consumer instead of creating a new one automatically.
`table = pw.io.nats.read( "nats://127.0.0.1:4222", "data", format="json", schema=InputSchema, jetstream_stream_name="your_stream_name", durable_consumer_name="your_consumer_name", )`
[**write**(table, uri, topic, \*, format='json', delimiter=',', jetstream\_stream\_name=None, value=None, headers=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/nats#pathway.io.nats.write)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/nats/__init__.py#L210-L374)
Writes data into the specified NATS topic.
The produced messages consist of the payload, corresponding to the values of the table that are serialized according to the chosen format and two headers: `pathway_time`, corresponding to the processing time of the entry and `pathway_diff` that is either `1` or `-1`. Both header values are provided as UTF-8 encoded strings. If `headers` parameter is used, additional headers can be added to the message.
There are several serialization formats supported: `"json"`, `"dsv"`, `"plaintext"` and `"raw"`. The format defines how the message is formed. In case of JSON and DSV (delimiter separated values), the message is formed in accordance with the respective data format.
If the selected format is either `"plaintext"` or `"raw"`, you also need to specify, which column of the table correspond to the payload of the produced NATS message. It can be done by providing `value` parameter. In order to output extra values from the table in these formats, NATS headers can be used. You can specify the column references in the `headers` parameter, which leads to serializing the extracted fields into UTF-8 strings and passing them as additional message headers.
When using the JetStream extension, you need to specify the name of the stream that is used for data persistence. Provide this name in the `jetstream_stream_name` field to ensure that the Pathway Live Data Framework writes to the correct persistent stream.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table for output.
* **uri** (`str`) – The URI of the NATS server.
* **topic** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The NATS topic where data will be written. This can be a specific topic name or a reference to a column whose values will be used as the topic for each message. If using a column reference, the column must contain string values.
* **format** (`Literal`\[`'json'`, `'dsv'`, `'plaintext'`, `'raw'`\]) – format in which the data is put into NATS. Currently `"json"`, `"plaintext"`, `"raw"` and `"dsv"` are supported. If the `"raw"` format is selected, `table` must either contain exactly one binary column that will be dumped as it is into the message, or the reference to the target binary column must be specified explicitly in the `value` parameter. Similarly, if `"plaintext"` is chosen, the table should consist of a single column of the string type.
* **delimiter** (`str`) – field delimiter to be used in case of delimiter-separated values format.
* **jetstream\_stream\_name** (`str` | `None`) – if specified, the [JetStream](https://docs.nats.io/nats-concepts/jetstream)
extension is used. In this case, the specified stream will be used.
* **value** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – reference to the column that should be used as a payload in the produced message in `"plaintext"` or `"raw"` format. It can be deduced automatically if the table has exactly one column. Otherwise it must be specified directly.
* **headers** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – references to the table fields that must be provided as message headers. These headers are named in the same way as fields that are forwarded and correspond to the string representations of the respective values encoded in UTF-8. Note that due to NATS constraints imposed on headers, the binary fields must also be UTF-8 serializable.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
Example:
Assume you have the NATS server running locally on the default port, `4222`. Let’s explore a few ways to send the contents of a table to the topic `test_topic` on this server.
First, you’ll need to create a Pathway Live Data Framework table. You can do this using the `table_from_markdown` method to set up a test table with information about pets and their owners.
`import pathway as pw table = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | cat 8 | Alice | cat ''')`
To output the table’s contents in JSON format, use the connector like this:
`pw.io.nats.write( table, "nats://127.0.0.1:4222", "test_topic", format="json", )`
In this case, the output will include the table’s rows in JSON format, with `time` and `diff` fields added to each JSON payload.
You can also use a single column from the table as the payload. For instance, to use the `owner` column as the NATS message payload, implement it as follows:
`pw.io.nats.write( table, "nats://127.0.0.1:4222", "test_topic", format="plaintext", value=table.owner, )`
If needed, you can also send the remaining fields as headers. To do this, modify the code to use the `headers` field, which should include all the required fields. Since `owner` is already being sent as the message payload, you can add the `age` and `pet` columns to the headers. Here’s what the code would look like:
`pw.io.nats.write( table, "nats://127.0.0.1:4222", "test_topic", format="plaintext", value=table.owner, headers=[table.age, table.pet], )`
If you are using JetStream, you need to specify an additional parameter `jetstream_stream_name`, where you indicate the name of the existing stream in the JetStream.
`pw.io.nats.write( table, "nats://127.0.0.1:4222", "test_topic", jetstream_stream_name="your_stream_name", format="plaintext", value=table.owner, headers=[table.age, table.pet], )`
[Pathway Io\
\
pw.io.mysql](https://pathway.com/developers/api-docs/pathway-io/mysql)
[Pathway Io\
\
pw.io.null](https://pathway.com/developers/api-docs/pathway-io/null)
---
# pw.io.questdb | Pathway
pw.io.questdb
=============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
All internal Pathway Live Data Framework types can be saved into QuestDB. The table below explains how the conversion is done. For the full list of QuestDB types you can refer the [official documentation](https://questdb.com/docs/reference/sql/datatypes/)
.
[Pathway Live Data Framework types serialization into QuestDB](https://pathway.com/developers/api-docs/pathway-io/questdb#pathway-live-data-framework-types-serialization-into-questdb)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
| Framework’s type | QuestDB type |
| --- | --- |
| `bool` | `boolean` |
| `int` | `long` |
| `float` | `double` |
| `pointer` | `string` |
| `str` | `string` |
| `bytes` | `string`, containing base64-encoded binary data. Please note that the `bytes` type from QuestDB is currently not supported |
| `Naive DateTime` | `timestamp`, the UTC timezone is used when passing the value to QuestDB |
| `UTC DateTime` | `timestamp` |
| `Duration` | `long`, serialized and deserialized with nanosecond precision |
| `JSON` | `string`, containing the serialized JSON value |
| `np.ndarray` | `string` containing a JSON object with two top-level fields: an integer array `shape` containing the shape of the array, and an array `elements` containing the flattened elements of the array |
| `tuple` | `string` containing a JSON array having the order of the elements corresponding to their appearance in the tuple |
| `list` | `string` containing a JSON array having the order of the elements corresponding to their appearance in the list |
| `pw.PyObjectWrapper` | `string`, containing base64-encoded serialized encoder. This value can be deserialized back, if read by other Pathway Live Data Framework connector |
[Performance](https://pathway.com/developers/api-docs/pathway-io/questdb#performance)
--------------------------------------------------------------------------------------
The QuestDB connector writes over the InfluxDB Line Protocol (ILP) and is multi-threaded, so the write stream parallelizes across Pathway workers: each worker drives its own ILP stream. Combined with the parallelized filesystem reader, the whole read-plus-write pipeline scales with the worker count.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and writing every row to QuestDB over ILP — so they reflect **Pathway + the input source + QuestDB together, out of the box**, not QuestDB’s standalone ingestion ceiling (which is considerably higher with a tuned worker pool).
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the QuestDB data directory. QuestDB ran as the stock `questdb/questdb:latest` Docker image (9.4.2) at its default configuration. The Pathway and QuestDB containers were each pinned to their own core-complex die (6 cores with a private 32 MiB L3).
**Throughput.** End-to-end wall-clock time to read a 20 M-row, 64-shard CSV dataset (**≈ 0.93 GB**) and land every row in QuestDB, swept over the number of Pathway workers (median of 3 runs):
### [QuestDB write throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/questdb#questdb-write-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 22.5 s | ≈ 890 000 rows/s | 1.00× |
| 2 | 12.5 s | ≈ 1 600 000 rows/s | 1.80× |
| 4 | 10.1 s | ≈ 1 986 000 rows/s | 2.23× |
| 8 | 9.5 s | ≈ 2 116 000 rows/s | 2.38× |
Throughput scales cleanly with the worker count, peaking at **~2.1 M rows/s** on 8 workers, and every run passed the data-integrity checks. A tuned QuestDB worker pool would push the ceiling higher still.
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/questdb-bulk-write)
.
[**write**(table, \*, connection\_string, table\_name, designated\_timestamp\_policy=None, designated\_timestamp=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/questdb#pathway.io.questdb.write)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/questdb/__init__.py#L15-L182)
Writes updates from `table` to a QuestDB table.
The output includes all columns from the input table, plus two additional columns: `time`, which contains the minibatch time from Pathway, and `diff`, which indicates the type of change (`1` for row insertion and `-1` for row deletion).
By default, the [designated timestamp column](https://questdb.com/docs/concept/designated-timestamp/)
in QuestDB is set to the current machine time when the row is written.
This behavior can be changed using the `designated_timestamp` and `designated_timestamp_policy` parameters. If `designated_timestamp` is specified, its values will be used as the timestamp. If you set `designated_timestamp_policy` to `use_pathway_time`, the Pathway Live Data Framework minibatch time will be used as the timestamp. You can also use `designated_timestamp_policy="use_now"` to be more explicit about using the current machine time.
Note that if you use `designated_timestamp_policy="use_pathway_time"`, the minibatch time will not be added as a separate column; it will only be used as the timestamp. The same applies if you set `designated_timestamp` - this column is used as the designated timestamp and is not duplicated in the output table.
If the target table does not exist, it will be created when the first write happens. If the table already exists, its schema must match the input data structure. An error will occur if the column types do not match.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The input table to write to QuestDB.
* **connection\_string** (`str`) – The [client configuration string](https://questdb.com/docs/configuration-string/)
used to connect to QuestDB.
* **table\_name** (`str`) – The name of the target table in QuestDB.
* **designated\_timestamp\_policy** (`Optional`\[`Literal`\[`'use_now'`, `'use_pathway_time'`, `'use_column'`\]\]) – Defines how the designated timestamp column is set. The value can be `"use_now"`, which means the current machine time is used as the timestamp. It can also be `"use_pathway_time"`, in which case the Pathway Live Data Framework minibatch time is used. Another option is `"use_column"`, which means a specific column will be used as the timestamp; in this case, the `designated_timestamp` parameter must be provided. If not specified, the default is `"use_now"`.
* **designated\_timestamp** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – The name of the column that will be used as the designated timestamp column. This column must have either the `DateTimeNaive` or `DateTimeUtc` type. If this parameter is set, `designated_timestamp_policy` can only be set to `"use_column"`, otherwise an error will occur.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
The easiest way to run QuestDB locally is with Docker. You can use the official image and start it like this:
`docker pull questdb/questdb docker run --name questdb -p 8812:8812 -p 9000:9000 questdb/questdb`
The first command pulls the QuestDB image from the official repository. The second command starts a container and exposes two ports: `8812` and `9000`. Port `8812` is used for connections over the Postgres wire protocol, which will be demonstrated later. Port `9000` is used for the HTTP API, which supports both data ingestion and queries.
You can now write a simple program. In this example, a table with one column called `"data"` is created and sent to the database:
`import pathway as pw table = pw.debug.table_from_markdown(''' | data 1 | Hello 2 | World ''')`
This table can now be written to QuestDB. If the output table is called `"test"`, the Pathway Live Data Framework code looks like this:
`pw.io.questdb.write( table, connection_string="http::addr=localhost:9000;", table_name="test", )`
The connection string specifies that the HTTP [InfluxDB Line Protocol](https://questdb.com/docs/reference/api/ilp/overview/)
is used for sending data.
Once the code has finished, you can connect to QuestDB using any client that supports the Postgres wire protocol. For example, with `psql`:
`psql -h localhost -p 8812 -U admin -d qdb`
The command will prompt for a password. Unless you have changed it, the default password is `quest`. Once connected, you can run:
`qdb=> select * from test;`
And see the contents of the table.
[Pathway Io\
\
pw.io.qdrant](https://pathway.com/developers/api-docs/pathway-io/qdrant)
[Pathway Io\
\
pw.io.rabbitmq](https://pathway.com/developers/api-docs/pathway-io/rabbitmq)
---
# pw.io.airbyte | Pathway
pw.io.airbyte
=============
[**read**(config\_file\_path, streams, \*, execution\_type='local', mode='streaming', env\_vars=None, service\_user\_credentials\_file=None, gcp\_region='europe-west1', gcp\_job\_name=None, enforce\_method=None, dependency\_overrides=None, refresh\_interval=60, name=None, max\_backlog\_size=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/airbyte#pathway.io.airbyte.read)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/airbyte/__init__.py#L112-L416)
Reads a table with a free tier Airbyte connector that supports the [incremental](https://docs.airbyte.com/using-airbyte/core-concepts/sync-modes/incremental-append)
mode. Please note that reusage Airbyte license is not supported at the moment.
If the local execution type is selected, Pathway Live Data Framework initially attempts to find the specified connector on PyPI and install its latest version in a separate virtual environment. If the connector isn’t written in Python or isn’t found on PyPI, it will be executed using a Docker image. Keep in mind, you can change this behavior using the `enforce_method` parameter.
Please be aware that it is highly recommended to use the `enforce_method` parameter in production deployments. This is because autodetection can fail if the PyPI service is unavailable.
* **Parameters**
* **config\_file\_path** (`PathLike` | `str`) – Path to the config file, created with [airbyte-serverless](https://github.com/unytics/airbyte_serverless)
tool or just via Pathway Live Data Framework CLI (that uses `airbyte-serverless` under the hood). The “source” section in this file must be properly configured in advance.
* **streams** (`Sequence`\[`str`\]) – Airbyte stream names to be read.
* **execution\_type** (`str`) – denotes how the airbyte connector is run. If `"local"` is specified the connector is executed on a local machine. If `"remote"` is used, the connector runs as a Google Cloud Run job.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"`, it will check for updates every `refresh_interval` seconds. `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **env\_vars** (`dict`\[`str`, `str`\] | `None`) – environment variables to be set in the Airbyte connector before its’ execution.
* **service\_user\_credentials\_file** (`str` | `None`) – Google API service user json file. You can refer the instructions provided in the [developer’s user guide](https://pathway.com/developers/user-guide/connectors/gdrive-connector/#setting-up-google-drive)
to obtain them. The credentials are required for the `"remote"` execution type.
* **gcp\_region** (`str`) – Google [region](https://cloud.google.com/compute/docs/regions-zones)
for the cloud job.
* **gcp\_job\_name** (`str` | `None`) – the name of GCP job if `"remote"` execution type is chosen. If unspecified, the name is autogenerated.
* **refresh\_interval** (`int` | `float` | `timedelta`) – time between new data queries, given as a number of seconds or a `datetime.timedelta` / `pw.Duration`. Applicable if mode is set to `"streaming"`.
* **enforce\_method** (`str` | `None`) – when set to `"docker"`, the Pathway Live Data Framework will not try to locate and run the latest connector version from PyPI. On the other hand, when set to `"pypi"`, the Pathway Live Data Framework will prefer the usage of the latest image available on PyPI. Use this option when you need to ensure certain behavior on the local run.
* **dependency\_overrides** (`list`\[`str`\] | `None`) – an optional list of pip requirement specifiers to install alongside the connector package in its virtual environment. Use this to pin a known-good version of a transitive dependency when the connector’s own metadata does not constrain it tightly enough. For example, `dependency_overrides=["airbyte-cdk==2.16.0"]` will force that exact CDK version regardless of what the connector declares. Only applies to the PyPI execution method; ignored for Docker and remote execution.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
Returns:
A table with a column `data`, containing the [pw.Json](https://pathway.com/developers/api-docs/pathway#pathway.Json)
containing the data read from the connector. The format of this data corresponds to the one used in the Airbyte.
Note:
The Airbyte connectors are typically available as Docker images and can technically be executed as containers. However, we do not recommend running such connectors in environments where the Docker image of a container is executed inside another Docker container, for example, your deployment (a setup commonly referred to as Docker-in-Docker, or DinD).
Running Docker inside a container is not a trivial configuration and requires using a special Docker-in-Docker image and starting it in `--privileged` mode. Privileged mode effectively removes most of the isolation guarantees provided by containers, grants broad access to kernel interfaces, and makes container escape relatively easy. As a result, any code executed in this setup must be considered fully trusted, which defeats the primary security benefits of using Docker.
In addition, Docker-in-Docker breaks reliable resource isolation. The inner Docker daemon is unaware of the actual CPU and memory limits imposed on the outer container, leading to nested cgroups, incorrect resource accounting, unpredictable CPU throttling, and seemingly random out-of-memory (OOM) terminations. These issues make the system harder to reason about, debug, and operate in a stable manner.
For these reasons, we consider the use of Docker-in-Docker for running Airbyte connectors a poor practice and do not provide a direct guidance for it. Instead, we recommend either using the `enforce_method="pypi"` execution mode or a default, which runs connectors as Python packages installed into a virtual environment without Docker-in-Docker, or running connectors in a managed environment such as Google Cloud Platform (GCP), where containers are executed with proper isolation and resource guarantees.
Example:
The simplest way to test this connector is to use [The Sample Data (Faker)](https://docs.airbyte.com/integrations/sources/faker)
data source provided by Airbyte.
To do that, you can use Pathway Live Data Framework CLI command `airbyte create-source`. You can create the `Faker` data source as follows:
The config file is located in `./connections/simple.yaml`. It contains the basic parameters of the test data source, such as random seed and the number of records to be generated. You don’t have to modify any of them to proceed with this testing.
Now, you can just run the read from this configured source. It contains three streams: `users`, `products`, and `purchases`. Let’s use the stream `users`, which leads us to the following code:
`import pathway as pw users_table = pw.io.airbyte.read( "./connections/simple.yaml", streams=["users"], )`
Let’s proceed to a more complex example.
Suppose that you need to read a stream of commits in a GitHub repository. To do so, you can use the [Airbyte GitHub connector](https://docs.airbyte.com/integrations/sources/github)
.
`abs create github --source "airbyte/source-github"`
Then, you need to edit the created config file, located at `./connections/github.yaml`.
To get started in the quickest way possible, you can remove uncommented `option_title`, `access_token`, `client_id` and `client_secret` fields in the config while uncommenting the section “Another valid structure for credentials”. It will require the PAT token, which can be obtained at the [Tokens](https://github.com/settings/tokens)
page in the GitHub - please note that you need to be logged in.
Then, you also need to set up the repository name in the `repositories` field. For example, you can specify `pathwaycom/pathway`. Then you need to remove the unused optional fields, and you’re ready to go.
Now, you can simply configure the Pathway Live Data Framework connector and run:
`import pathway as pw commits_table = pw.io.airbyte.read( "./connections/github.yaml", streams=["commits"], )`
The result table will contain the JSON payloads with the comprehensive information about the commit times. If the `mode` is set to `"streaming"` (the default), the new commits will be appended to this table when they are made.
In some cases, it is not necessary to poll the changes because the data is given in full in the beginning and is not updated afterwards. For instance, in the first example we used with the `users_table` table, you could also use the static mode of the connector:
`users_table = pw.io.airbyte.read( "./connections/simple.yaml", streams=["Users"], mode="static", )`
In the second example, you could use this mode to load the commits data at once and then terminate the connector:
`commits_table = pw.io.airbyte.read( "./connections/github.yaml", streams=["commits"], mode="static", )`
While it’s not the case with Github connector, which is implemented in Python, it’s worth noticing that deployment of the code running with the `"local"` execution type may be challenging because some connectors use Docker under the hood. That may lead to a situation where you use Docker to deploy the code which, in turn, uses Docker image to run Airbyte’s data extraction routines. This problem is widely known as DinD.
To avoid DinD you may use the `"remote"` type of execution. If chosen, it runs the Airbyte’s data extraction part on the Google Cloud, which also saves CPU and memory at your development machine or server. To enable the `"remote"` execution type you would need to specify the corresponding execution type and to provide a path to the service account credentials data file. Consider that the credentials are located in the file `./credentials.json`. Then, running the second example with the `"remote"` type of execution looks as follows:
`commits_table = pw.io.airbyte.read( "./connections/github.yaml", streams=["commits"], mode="static", execution_type="remote", service_user_credentials_file="./credentials.json", )`
Please keep in mind that the Google Cloud Runs are [billed](https://cloud.google.com/run/pricing)
based on the vCPU time and memory time, measured in vCPU-seconds and GiB-seconds respectively. Having that said, the usage of small values for `refresh_interval` is not advised for the remote runs, as they may result in more runs and consequently more vCPU and memory time spent, resulting in a bigger bill.
[API Docs\
\
pw.io](https://pathway.com/developers/api-docs/pathway-io)
[Pathway Io\
\
pw.io.bigquery](https://pathway.com/developers/api-docs/pathway-io/bigquery)
---
# pw.io.kinesis | Pathway
pw.io.kinesis
=============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
[**read**(stream\_name, \*, schema=None, format='raw', autocommit\_duration\_ms=1500, json\_field\_paths=None, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/kinesis#pathway.io.kinesis.read)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/kinesis/__init__.py#L23-L174)
Reads a table from an [AWS Kinesis stream](https://docs.aws.amazon.com/streams/latest/dev/introduction.html)
. The connection settings are retrieved from the environment.
There are three supported formats: `"plaintext"`, `"raw"`, and `"json"`.
For the `"raw"` format, the payload is read as raw bytes and added directly to the table. In the `"plaintext"` format, the payload decoded from UTF-8 and stored as plain text. In both cases, the table will have an autogenerated primary key and a single `"data"` column representing the payload.
If you select the `"json"` format, the connector parses the message payload as JSON and creates table columns based on the schema provided in the `schema` parameter. The column values come from the corresponding JSON fields.
* **Parameters**
* **stream\_name** (`str`) – The name of the data stream to be read.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – The table schema, used only when the format is set to `"json"`.
* **format** (`Literal`\[`'plaintext'`, `'raw'`, `'json'`\]) – The input data format, which can be `"raw"`, `"plaintext"`, or `"json"`.
* **autocommit\_duration\_ms** (`int`) – The time interval (in milliseconds) between commits. After this time, the updates received by the connector are committed and added to Pathway Live Data Framework’s computation graph. Please note that it has to be a not-None value in this connector.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – For the `"json"` format, this allows mapping field names to paths within the JSON structure. Use the format `: ` where the path follows the [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
To test the connector locally, you need a way to run Kinesis on your machine. You can use the Docker image [instructure/kinesalite](https://hub.docker.com/r/instructure/kinesalite/)
to spawn it.
Start the container as follows:
`docker pull instructure/kinesalite:latest docker run -p 4567:4567 --name kinesis-local instructure/kinesalite:latest`
The first command pulls the Kinesis image from Docker Hub. The second command starts a container and exposes port `4567`, the standard port used for the connection.
Since Kinesis now runs locally and the settings are retrieved from the environment, configure the required variables so the connector can reach the local instance:
`export AWS_ENDPOINT_URL=http://localhost:4567 export AWS_REGION=us-east-1`
Now you can start testing. First, connect to the local Kinesis instance and create a client with [boto3](https://pypi.org/project/boto3/)
:
`import boto3 client = boto3.client( "kinesis", region_name="us-east-1", endpoint_url="http://localhost:4567", )`
Use the created client to create a new stream, for example `"testing"`:
`client.create_stream(StreamName="testing", ShardCount=1)`
The stream is created asynchronously, so you need to wait until its status becomes `"ACTIVE"`. To check the status you can use the `describe_stream` method.
Once the stream is active, send a few records with `put_record`. Note that the payload must be bytes:
`client.put_record( StreamName="testing", PartitionKey="123", Data="Hello, world!".encode("utf-8"), )`
Finally, you have a stream with data. You can now read it using the Pathway Live Data Framework connector:
`import pathway as pw table = pw.io.kinesis.read("testing", format="plaintext")`
Here you first import the Pathway Live Data Framework, then read the Kinesis stream. The `"plaintext"` format decodes UTF-8 so the text `"Hello, world!"` can be viewed as plain text.
Finally, write the row to a file using a Pathway Live Data Framework output connector, for example JSONLines:
`pw.io.jsonlines.write(table, "output.jsonl")`
Do not forget to call `pw.run()` to start the pipeline. Once running, the connector continuously monitors the Kinesis stream and writes both existing and newly arriving messages to `output.jsonl`.
[**write**(table, stream\_name, \*, format='json', partition\_key=None, data=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/kinesis#pathway.io.kinesis.write)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/kinesis/__init__.py#L177-L403)
Streams `table` into an [AWS Kinesis stream](https://docs.aws.amazon.com/streams/latest/dev/introduction.html)
. The connection settings are retrieved from the environment.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **stream\_name** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The Kinesis stream where data will be written. This can be a specific stream name or a reference to a column whose values will be used as the stream for each message. If using a column reference, the column must contain string values.
* **format** (`Literal`\[`'raw'`, `'plaintext'`, `'json'`\]) – Format in which the data is put into Kinesis. Currently `"json"`, `"plaintext"`, and `"raw"` are supported. If the `"raw"` format is selected, `table` must either contain exactly one binary column that will be dumped as it is into the Kinesis record, or the reference to the target binary column must be specified explicitly in the `data` parameter. Similarly, if `"plaintext"` is chosen, the table must consist of a single column of the string type, or the reference to the target string column must be specified explicitly in the `data` parameter.
* **partition\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Reference to the column used as the partition key in the produced message. It can have any data type, because if it is not a string, the Pathway Live Data Framework will obtain its string representation and use that value. Note that the maximum length of a partition key in Kinesis is 256 bytes. If the key is not specified, internal row key will be used.
* **data** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Reference to the column that should be used as data in the produced message in `"plaintext"` or `"raw"` format. It can be deduced automatically if the table has exactly one column. Otherwise it must be specified directly. It also has to be explicitly specified, if `partition_key` is set. The type of the column must correspond to the format used: `str` for the `"plaintext"` format and `binary` for the `"raw"` format. Note that the maximum length of one message payload in Kinesis is 1 MiB.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
The local test setup is the same as for the case of the input connector: you need a way to run Kinesis on your machine. You can use the Docker image [instructure/kinesalite](https://hub.docker.com/r/instructure/kinesalite/)
to spawn it.
Start the container as follows:
`docker pull instructure/kinesalite:latest docker run -p 4567:4567 --name kinesis-local instructure/kinesalite:latest`
The first command pulls the Kinesis image from Docker Hub. The second command starts a container and exposes port `4567`, the standard port used for the connection.
Since Kinesis now runs locally and the settings are retrieved from the environment, configure the required variables so the connector can reach the local instance:
`export AWS_ENDPOINT_URL=http://localhost:4567 export AWS_REGION=us-east-1`
Now you can start testing. First, connect to the local Kinesis instance and create a client with [boto3](https://pypi.org/project/boto3/)
:
`import boto3 client = boto3.client( "kinesis", region_name="us-east-1", endpoint_url="http://localhost:4567", )`
Use the created client to create a new stream, for example `"testing"`. For easier testing, create the stream with a single shard as follows:
`client.create_stream(StreamName="testing", ShardCount=1)`
The stream is now ready and you can send messages to it with this connector. First, import the Pathway Live Data Framework and create a static table with sample data. The code would look like this:
`import pathway as pw table = pw.debug.table_from_markdown( ''' | key | value 1 | 1 | one 2 | 2 | two 3 | 3 | three ''' )`
The table is created; the next step is to write it to the Kinesis stream. You can do so as follows:
`pw.io.kinesis.write( table, stream_name="testing", format="plaintext", partition_key=table.key, data=table.value, )`
This command streams the table as follows: the column `key` is used as the partition key. Because it is an integer, the connector converts it to a string. The column `value` is sent as the payload. Remember to call `pw.run` to start the pipeline.
After the execution finishes, you can read the stream with the boto3 library. Start by listing all shards:
`shards_response = client.list_shards(StreamName="testing")`
Because the stream was created with one shard, the `"Shards"` list in the response contains only one item. You can retrieve its ID as shown below:
`shard_id = shards_response["Shards"][0]["ShardId"]`
To fetch messages, first obtain an iterator for this shard as follows:
`iterator_response = client.get_shard_iterator( StreamName="testing", ShardId=shard_id, ShardIteratorType="TRIM_HORIZON", ) shard_iterator = iterator_response["ShardIterator"]`
The parameter `TRIM_HORIZON` instructs Kinesis to read the shard from the beginning. If you rerun this example, the stream may contain more messages than expected because the connector does not clear streams. Also note that a shard iterator is valid for five minutes, so it must be refreshed if needed.
You can now request the records. Although the API is paginated, three test records can be retrieved in a single call as follows:
`records_response = client.get_records(ShardIterator=shard_iterator, Limit=100)`
To verify the contents, you can print the received messages with this code:
`for r in records_response["Records"]: print(f"Partition key: {r['PartitionKey']}; Value: {r['Data']}")`
Code Results
You could also read these messages using the Pathway Live Data Framework Kinesis input connector. Then, the reading code would look like this:
`reread_table = pw.io.kinesis.read("testing", format="plaintext")`
This table can then be written to a file or processed further.
If the table contains more than two columns and you want to keep all data, use the JSON format for serialization:
`pw.io.kinesis.write( table, stream_name="testing", format="json", )`
If you need to split the table output across multiple streams, the column containing the stream name can be provided as the `stream_name` parameter. For example, create a table with an additional column:
`table = pw.debug.table_from_markdown( ''' | key | value | stream 1 | 1 | one | testing 2 | 2 | two | other 3 | 3 | three | testing ''' )`
And then, write this table to multiple streams depending on the `stream` column as follows:
`pw.io.kinesis.write( table, stream_name=table.stream, format="json", )`
As a result, two messages with `"value"` equal to `"one"` and `"three"` are added to the `"testing"` stream. One message with `"value"` equal to `"two"` is added to the `"other"` stream, which must be created beforehand if you are testing this part locally.
---
# pw.io.weaviate | Pathway
pw.io.weaviate
==============
Pathway writes tables to a [Weaviate](https://weaviate.io/)
collection with `pw.io.weaviate.write`. The connector keeps the collection in sync with the table: additions and updates upsert objects, and deletions remove them. The target collection must already exist — the connector never creates or alters its schema or vector index.
**NOTE**: This connector is available when using one of the following licenses only: Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise. See the [pricing page](https://pathway.com/pricing)
for details.
[Object identity](https://pathway.com/developers/api-docs/pathway-io/weaviate#object-identity)
-----------------------------------------------------------------------------------------------
Weaviate addresses every object by a UUID. When a `primary_key` column is given, its value is encoded in that UUID exactly as `weaviate.util.generate_uuid5` does (`uuid5(NAMESPACE_DNS, str(key))`), so re-writing the same key upserts in place and the row for a key `k` can always be fetched with `collection.query.fetch_object_by_id(generate_uuid5(k))`. The key column is not stored as a property, which also lets it be named `id` — a name Weaviate otherwise reserves and forbids as a property.
When `primary_key` is omitted, the UUID is derived from the row’s internal Pathway key instead. Objects are still upserted in place, but there is no column-value-based UUID to look them up by.
[Authentication](https://pathway.com/developers/api-docs/pathway-io/weaviate#authentication)
---------------------------------------------------------------------------------------------
Pass `api_key` to authenticate with Weaviate. Extra request headers can be supplied through `headers` — for example to provide the API key of a server-side vectorizer module (`{"X-OpenAI-Api-Key": "..."}`).
[Type mapping](https://pathway.com/developers/api-docs/pathway-io/weaviate#type-mapping)
-----------------------------------------------------------------------------------------
Every column other than `primary_key` and `vector` becomes an object property. With Weaviate’s auto-schema, Pathway types are stored as follows. Declaring a property explicitly in the collection’s schema overrides this with the declared type (for example, declare a property as `int` to preserve integer typing).
| Pathway type | Weaviate property type | Notes |
| --- | --- | --- |
| `int` | `number` | Stored as a number under auto-schema (read back as a float); declare the property as `int` in the collection to keep integer typing. |
| `float` | `number` | |
| `bool` | `boolean` | |
| `str` | `text` | |
| `bytes` | `text` | Base64-encoded. |
| `list[float]` / `list[int]` | `number[]` | When the column is not the one passed as `vector`. |
The column passed as `vector` is stored as the object’s vector embedding (kept as 32-bit floats), not as a property. When `vector` is omitted, objects are written without an explicit vector — appropriate when the collection has a server-side vectorizer. Weaviate reserves the property names `id` and `vector`, so a non-key, non-vector column with either name is rejected.
[**write**(table, collection\_name, \*, primary\_key=None, vector=None, http\_host='localhost', http\_port=8080, http\_secure=False, api\_key=None, headers=None, batch\_size=100, concurrency=8, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/weaviate#pathway.io.weaviate.write)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/weaviate/__init__.py#L16-L179)
Writes a Pathway Live Data Framework table to a [Weaviate](https://weaviate.io/)
collection.
Each row addition (`diff = 1`) upserts an object and each row deletion (`diff = -1`) removes it, keeping the collection in sync with the table. The target collection must already exist. See the connector documentation for how objects are identified, how each Pathway type is stored, and how to authenticate.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **collection\_name** (`str`) – Name of the Weaviate collection to write to. It must already exist.
* **primary\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – An optional column reference (e.g. `table.doc_id`) whose values are used to derive each object’s UUID; the column is not stored as a property. When omitted, the UUID is derived from the row’s internal Pathway key. The column must belong to `table`.
* **vector** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – An optional column reference (e.g. `table.embedding`) holding the vector embedding for each object. When given, that column is written as the object’s vector and not as a property. The column must belong to `table`.
* **http\_host** (`str`) – Host of the Weaviate server.
* **http\_port** (`int`) – Port of the Weaviate server.
* **http\_secure** (`bool`) – Whether the connection uses TLS (`https`).
* **api\_key** (`str` | `None`) – An optional API key used to authenticate with Weaviate.
* **headers** (`dict`\[`str`, `str`\] | `None`) – Optional additional headers sent with every request, e.g. `{"X-OpenAI-Api-Key": "..."}` to authorize a server-side vectorizer.
* **batch\_size** (`int`) – Number of objects grouped together per write.
* **concurrency** (`int`) – Maximum number of writes performed in parallel per worker.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output within each mini-batch will be sorted in ascending order by the given columns. When multiple columns are provided, the corresponding value tuples are compared lexicographically.
* **Returns**
None
Example:
Suppose you are building a document search pipeline and want to store embeddings in Weaviate running locally (e.g. via the official Docker image, which serves its API on port `8080`).
Create the collection before starting the pipeline. The `none` vectorizer keeps the embeddings the pipeline sends instead of recomputing them server-side:
`import weaviate from weaviate.classes.config import Configure client = weaviate.connect_to_local() client.collections.create( "Docs", vectorizer_config=Configure.Vectorizer.none(), ) client.close()`
Define your Pathway Live Data Framework schema and build the table:
`import pathway as pw class DocSchema(pw.Schema): doc_id: int = pw.column_definition(primary_key=True) embedding: list[float] table = pw.debug.table_from_rows( DocSchema, [(1, [0.1, 0.2, 0.3, 0.4]), (2, [0.5, 0.6, 0.7, 0.8])], )`
Attach the Weaviate output connector, mapping the primary key and the vector column:
`pw.io.weaviate.write( table, collection_name="Docs", primary_key=table.doc_id, vector=table.embedding, ) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
[Pathway Io\
\
pw.io.sqlite](https://pathway.com/developers/api-docs/pathway-io/sqlite)
[API Docs\
\
pw.ml](https://pathway.com/developers/api-docs/ml)
---
# pw.io.csv | Pathway
pw.io.csv
=========
All internal Pathway Live Data Framework types can be serialized into CSV. The table below explains how the conversion is done. The values of the corresponding types can also be deserialized from CSV back into Live Data Framework values.
[Pathway types serialization into CSV](https://pathway.com/developers/api-docs/pathway-io/csv#pathway-types-serialization-into-csv)
------------------------------------------------------------------------------------------------------------------------------------
| Live Data Framework type | Serialization way |
| --- | --- |
| `bool` | Either `True` or `False` |
| `int` | Serialized as is |
| `float` | Serialized as is, with a dot (`.`) being a decimal separator |
| `pointer` | A string that can be deserialized back if the `pw.Pointer` type is specified in the Live Data Framework table schema |
| `str` | Serialized as is |
| `bytes` | Base64-encoded data |
| `Naive DateTime` | A datetime in ISO-8601 format |
| `UTC DateTime` | A datetime in ISO-8601 format |
| `Duration` | An integer representing the number of nanoseconds |
| `JSON` | A string containing the serialized JSON value |
| `np.ndarray` | A string containing the serialized JSON object with two top-level fields: an integer array `shape` containing the shape of the array, and an array `elements` containing the flattened elements of the array |
| `tuple` | A string containing the serialized JSON array, where the order of elements matches their order in the tuple |
| `list` | A string containing the serialized JSON array, where the order of elements matches their order in the list |
| `pw.PyObjectWrapper` | A string that can be deserialized back if the `pw.PyObjectWrapper` type is specified in the Live Data Framework table schema |
[**read**(path, \*, schema=None, csv\_settings=None, mode='streaming', object\_pattern='\*', with\_metadata=False, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/csv#pathway.io.csv.read)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/csv/__init__.py#L16-L167)
Reads a table from one or several files with delimiter-separated values.
In case the folder is passed to the engine, the order in which files from the directory are processed is determined according to the modification time of files within this folder: they will be processed by ascending order of the modification time.
* **Parameters**
* **path** (`str` | `PathLike`) – Path to the file or to the folder with files or [glob](https://en.wikipedia.org/wiki/Glob_(programming))
pattern for the objects to be read. The connector will read the contents of all matching files as well as recursively read the contents of all matching folders.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **csv\_settings** ([`CsvParserSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
| `None`) – Settings for the CSV parser.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"` the engine will wait for the updates in the specified directory. It will track file additions, deletions, and modifications and reflect these events in the state. For example, if a file was deleted, `"streaming"` mode will also remove rows obtained by reading this file from the table. On the other hand, the `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **object\_pattern** (`str`) – Unix shell style pattern for filtering only certain files in the directory. Ignored in case a path to a single file is specified. This value will be deprecated soon, please use glob pattern in `path` instead.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This JSON field may contain: (1) created\_at - UNIX timestamp of file creation; (2) modified\_at - UNIX timestamp of last modification; (3) seen\_at is a UNIX timestamp of when they file was found by the engine; (4) owner - Name of the file owner (only for Un); (5) path - Full file path of the source row. (6) size - File size in bytes.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Consider you want to read a dataset, stored in the filesystem in a standard CSV format. The dataset contains data about pets and their owners.
For the sake of demonstration, you can prepare a small dataset by creating a CSV file via a unix command line tool:
`printf "id,owner,pet\n1,Alice,dog\n2,Bob,dog\n3,Alice,cat\n4,Bob,dog" > dataset.csv`
In order to read it into Pathway Live Data Framework’s table, you can first do the import and then use the `pw.io.csv.read` method:
`import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.csv.read("dataset.csv", schema=InputSchema, mode="static")`
Then, you can output the table in order to check the correctness of the read:
`pw.debug.compute_and_print(t, include_id=False)`
Code Results
Now let’s try something different. Consider you have site access logs stored in a separate folder in several files. For the sake of simplicity, a log entry contains an access ID, an IP address and the login of the user.
A dataset, corresponding to the format described above can be generated, thanks to the following set of unix commands:
`mkdir logs printf "id,ip,login\n1,127.0.0.1,alice\n2,8.8.8.8,alice" > logs/part_1.csv printf "id,ip,login\n3,8.8.8.8,bob\n4,127.0.0.1,alice" > logs/part_2.csv`
Now, let’s see how you can use the connector in order to read the content of this directory into a table:
`class InputSchema(pw.Schema): ip: str login: str t = pw.io.csv.read("logs/", schema=InputSchema, mode="static")`
The only difference is that you specified the name of the directory instead of the file name, as opposed to what you had done in the previous example. It’s that simple!
But what if you are working with a real-time system, which generates logs all the time. The logs are being written and after a while they get into the log directory (this is also called “logs rotation”). Now, consider that there is a need to fetch the new files from this logs directory all the time. Would the Pathway Live Data Framework handle that? Sure!
The only difference would be in the usage of `mode` flag. So the code snippet will look as follows:
`t = pw.io.csv.read("logs/", schema=InputSchema, mode="streaming")`
With this method, you obtain a table updated dynamically. The changes in the logs would incur changes in the Business-Intelligence ‘BI’-ready data, namely, in the tables you would like to output. article.
[**write**(table, filename, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/csv#pathway.io.csv.write)
----------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/csv/__init__.py#L170-L234)
Writes `table`’s stream of updates to a file in delimiter-separated values format.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **filename** (`str` | `PathLike`) – Path to the target output file.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
In this simple example you can see how table output works. First, import the Pathway Live Data Framework and create a table:
`import pathway as pw t = pw.debug.table_from_markdown("age owner pet \n 1 10 Alice dog \n 2 9 Bob cat \n 3 8 Alice cat")`
Consider you would want to output the stream of changes of this table. In order to do that you simply do:
`pw.io.csv.write(t, "table.csv")`
Now, let’s see what you have on the output:
`cat table.csv`
`age,owner,pet,time,diff 10,"Alice","dog",0,1 9,"Bob","cat",0,1 8,"Alice","cat",0,1`
The first three columns clearly represent the data columns you have. The column time represents the number of operations minibatch, in which each of the rows was read. In this example, since the data is static: you have 0. The diff is another element of this stream of updates. In this context, it is 1 because all three rows were read from the input. All in all, the extra information in `time` and `diff` columns - in this case - shows us that in the initial minibatch (`time = 0`), you have read three rows and all of them were added to the collection (`diff = 1`).
[Pathway Io\
\
pw.io.clickhouse](https://pathway.com/developers/api-docs/pathway-io/clickhouse)
[Pathway Io\
\
pw.io.debezium](https://pathway.com/developers/api-docs/pathway-io/debezium)
---
# pw.io.jsonlines | Pathway
pw.io.jsonlines
===============
All internal Pathway Live Data Framework types can be serialized into JSON. The table below explains how the conversion is done. The values of the corresponding types can also be deserialized from JSON back into Live Data Framework values.
[Pathway types serialization into JSON](https://pathway.com/developers/api-docs/pathway-io/jsonlines#pathway-types-serialization-into-json)
--------------------------------------------------------------------------------------------------------------------------------------------
| Live Data Framework type | JSON type |
| --- | --- |
| `bool` | `boolean` |
| `int` | `number` |
| `float` | `number` |
| `pointer` | `string`, can be deserialized back if `pw.Pointer` type is specified in Live Data Framework table schema |
| `str` | `string` |
| `bytes` | `string`, containing base64-encoded binary data |
| `Naive DateTime` | `string`, containing the datetime in ISO-8601 format |
| `UTC DateTime` | `string`, containing the datetime in ISO-8601 format |
| `Duration` | `number`, serialized and deserialized with nanosecond precision |
| `JSON` | `object`, containing the JSON value |
| `np.ndarray` | `object` type with two top-level fields: an integer array `shape` containing the shape of the array, and an array `elements` containing the flattened elements of the array |
| `tuple` | `array`, the order of the elements corresponds to their appearance in the tuple |
| `list` | `array` |
| `pw.PyObjectWrapper` | `string`, can be deserialized back if the `pw.PyObjectWrapper` type is specified in Live Data Framework table schema |
[**read**(path, \*, schema=None, mode='streaming', json\_field\_paths=None, object\_pattern='\*', with\_metadata=False, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/jsonlines#pathway.io.jsonlines.read)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/jsonlines/__init__.py#L16-L177)
Reads a table from one or several files in jsonlines format.
In case the folder is passed to the engine, the order in which files from the directory are processed is determined according to the modification time of files within this folder: they will be processed by ascending order of the modification time.
The maximum supported depth of nested JSON structures is `127` levels. JSON documents with a depth of `128` or more are considered malformed and will fail to parse with a `"recursion limit exceeded"` error text. Documents with a smaller depth parse as expected.
* **Parameters**
* **path** (`str` | `PathLike`) – Path to the file or to the folder with files or [glob](https://en.wikipedia.org/wiki/Glob_(programming))
pattern for the objects to be read. The connector will read the contents of all matching files as well as recursively read the contents of all matching folders.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"` the engine will wait for the updates in the specified directory. It will track file additions, deletions, and modifications and reflect these events in the state. For example, if a file was deleted, `"streaming"` mode will also remove rows obtained by reading this file from the table. On the other hand, the `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – This field allows to map field names into path in the field. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **object\_pattern** (`str`) – Unix shell style pattern for filtering only certain files in the directory. Ignored in case a path to a single file is specified. This value will be deprecated soon, please use glob pattern in `path` instead.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field that will contain two optional fields - `created_at` and `modified_at`. These fields will have integral UNIX timestamps for the creation and modification time respectively. Additionally, the column will also have an optional field named `owner` that will contain the name of the file owner (applicable only for Un). Finally, the column will also contain a field named `path` that will show the full path to the file from where a row was filled.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Consider you want to read a dataset, stored in the filesystem in a jsonlines format. The dataset contains data about pets and their owners.
For the sake of demonstration, you can prepare a small dataset by creating a jsonlines file via a unix command line tool:
`printf "{\"id\":1,\"owner\":\"Alice\",\"pet\":\"dog\"} {\"id\":2,\"owner\":\"Bob\",\"pet\":\"dog\"} {\"id\":3,\"owner\":\"Bob\",\"pet\":\"cat\"} {\"id\":4,\"owner\":\"Bob\",\"pet\":\"cat\"}" > dataset.jsonlines`
In order to read it into Pathway Live Data Framework’s table, you can first do the import and then use the `pw.io.jsonlines.read` method:
`import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.jsonlines.read("dataset.jsonlines", schema=InputSchema, mode="static")`
Then, you can output the table in order to check the correctness of the read:
`pw.debug.compute_and_print(t, include_id=False)`
Code Results
Now let’s try something different. Consider you have site access logs stored in a separate folder in several files. For the sake of simplicity, a log entry contains an access ID, an IP address and the login of the user.
A dataset, corresponding to the format described above can be generated, thanks to the following set of unix commands:
`mkdir logs printf "{\"id\":1,\"ip\":\"127.0.0.1\",\"login\":\"alice\"} {\"id\":2,\"ip\":\"8.8.8.8\",\"login\":\"alice\"}" > logs/part_1.jsonlines printf "{\"id\":3,\"ip\":\"8.8.8.8\",\"login\":\"bob\"} {\"id\":4,\"ip\":\"127.0.0.1\",\"login\":\"alice\"}" > logs/part_2.jsonlines`
Now, let’s see how you can use the connector in order to read the content of this directory into a table:
`class InputSchema(pw.Schema): ip: str login: str t = pw.io.jsonlines.read("logs/", schema=InputSchema, mode="static")`
The only difference is that you specified the name of the directory instead of the file name, as opposed to what you had done in the previous example. It’s that simple!
But what if you are working with a real-time system, which generates logs all the time. The logs are being written and after a while they get into the log directory (this is also called “logs rotation”). Now, consider that there is a need to fetch the new files from this logs directory all the time. Would the Pathway Live Data Framework handle that? Sure!
The only difference would be in the usage of `mode` flag. So the code snippet will look as follows:
`class InputSchema(pw.Schema): ip: str login: str t = pw.io.jsonlines.read("logs/", schema=InputSchema, mode="streaming")`
With this method, you obtain a table updated dynamically. The changes in the logs would incur changes in the Business-Intelligence ‘BI’-ready data, namely, in the tables you would like to output.
[**write**(table, filename, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/jsonlines#pathway.io.jsonlines.write)
----------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/jsonlines/__init__.py#L180-L243)
Writes `table`’s stream of updates to a file in jsonlines format.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **filename** (`str` | `PathLike`) – Path to the target output file.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
In this simple example you can see how table output works. First, import Pathway Live Data Framework and create a table:
`import pathway as pw t = pw.debug.table_from_markdown("age owner pet \n 1 10 Alice dog \n 2 9 Bob cat \n 3 8 Alice cat")`
Consider you would want to output the stream of changes of this table. In order to do that you simply do:
`pw.io.jsonlines.write(t, "table.jsonlines")`
Now, let’s see what you have on the output:
`cat table.jsonlines`
`{"age":10,"owner":"Alice","pet":"dog","diff":1,"time":0} {"age":9,"owner":"Bob","pet":"cat","diff":1,"time":0} {"age":8,"owner":"Alice","pet":"cat","diff":1,"time":0}`
The columns age, owner and pet clearly represent the data columns you have. The column time represents the number of operations minibatch, in which each of the rows was read. In this example, since the data is static: you have 0. The diff is another element of this stream of updates. In this context, it is 1 because all three rows were read from the input. All in all, the extra information in `time` and `diff` columns - in this case - shows us that in the initial minibatch (`time = 0`), you have read three rows and all of them were added to the collection (`diff = 1`).
[Pathway Io\
\
pw.io.iceberg](https://pathway.com/developers/api-docs/pathway-io/iceberg)
[Pathway Io\
\
pw.io.kafka](https://pathway.com/developers/api-docs/pathway-io/kafka)
---
# pw.io.pinecone | Pathway
pw.io.pinecone
==============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
Pathway writes each row of the table as a single Pinecone record: the value of the `primary_key` column becomes the record id (converted to a string), the `vector` column becomes the record’s vector, and the metadata columns become the record metadata.
A Pinecone index stores vectors of a single kind, and the type of the `vector` column selects which one is written:
| Pathway type of `vector` | Pinecone record field | Target index |
| --- | --- | --- |
| `list[float]`, 1-D `numpy.ndarray` (length equal to the index dimension) | dense `values` | dense index |
| `list[tuple[int, float]]` of `(index, weight)` pairs | `sparse_values` | sparse index |
Sparse indices must fit in the unsigned 32-bit range and weights must be finite; a sparse vector with no pairs is valid and stored as an empty `sparse_values`. Weights are written as given — a sparse index scores by the dot product of the stored weights, so any IDF weighting is applied upstream. Multivector columns (`list[list[float]]`) have no Pinecone counterpart and raise `NotImplementedError`.
Hybrid (dense + sparse) retrieval is therefore two indexes, not one: create both, attach one `write()` call per index to the same table, and use the same `primary_key` in both so a row lands under one record id in each index and the two result lists can be fused client-side.
Metadata columns are converted by type as follows:
| Pathway type | Pinecone type |
| --- | --- |
| `int`, `float` | number |
| `bool` | boolean |
| `str` | string |
| `list[str]` | list of strings |
A `None` metadata value is omitted, as Pinecone rejects null metadata. A metadata column of any other type (for example `bytes`, a nested `pw.Json` object, or a numeric array) is not supported and raises an error that names the offending column.
[**write**(table, index\_name, \*, primary\_key=None, vector, api\_key=None, host=None, namespace='', metadata\_columns=None, batch\_size=100, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/pinecone#pathway.io.pinecone.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/pinecone/__init__.py#L127-L433)
Writes a Pathway Live Data Framework table to a [Pinecone](https://www.pinecone.io/)
index.
The Pinecone index is kept in sync with the current state of the table. When a row is added to the table it is upserted into the index, and when a row is removed from the table the corresponding record is deleted; an update replaces the previous record for that id. Only the current state is reflected — the connector does not append a change log, so no `time` or `diff` columns are written.
The Pinecone record id is taken from the `primary_key` column when given. By default (`primary_key=None`) the table’s internal row key is used as the id: it is unique by construction and matches the way the dataflow shards rows, so writing runs in parallel across workers. A `primary_key` column instead lets you choose a meaningful id, but its values must uniquely identify rows; to guarantee that, writing then runs on a single worker and a collision (two rows with the same id) raises an error rather than silently overwriting.
The `vector` column provides the vector written to the index, and its type decides which kind of record is written:
* a `list[float]` (or 1-D `numpy.ndarray`) column is written as the record’s dense `values` and requires a _dense_ index;
* a `list[tuple[int, float]]` column of `(index, weight)` pairs is written as the record’s `sparse_values` and requires a _sparse_ index. Weights are sent raw (e.g. term frequencies): a sparse index scores by the dot product of the stored weights, so IDF weighting, if wanted, is applied upstream;
* a `list[list[float]]` (multivector) column raises `NotImplementedError`, since a Pinecone record carries a single vector.
A Pinecone index holds vectors of one kind only, so a hybrid (dense + sparse) setup is two indexes: create both, then attach two `write()` calls to the same table — one naming the dense column and one naming the sparse column. The same record ids then land in both indexes, so the two result sets can be fused client-side. See the example below.
Every remaining column — or just the columns listed in `metadata_columns` — is stored as record metadata. `None` metadata values are dropped; a metadata value of a type Pinecone cannot store raises an error naming the offending column. See the connector documentation for the full type-conversion table. For high-dimensional vectors, `batch_size` may be reduced automatically so a single request stays within Pinecone’s size limit.
The target index must already exist before the pipeline starts; the connector never creates it. For a dense index its dimension must match the length of the produced vectors. If the index’s kind does not match the `vector` column’s type, the connector fails at start-up with an error naming the index, the column, and both kinds.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **index\_name** (`str`) – Name of the Pinecone index to write to.
* **primary\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – A column reference (e.g. `table.doc_id`) whose values are used as the Pinecone record id. The column must belong to `table` and its values must uniquely identify rows (the id selects the record to upsert or delete); a collision raises an error at runtime and writing runs on a single worker. When `None` (the default), the table’s internal row key is used as the id — always unique and written in parallel across workers — but the ids are then Pathway’s internal keys rather than your own values.
* **vector** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – A column reference holding the vector to write. Either a dense embedding (`list[float]` or a 1-D `numpy.ndarray`), written to a dense index, or a sparse vector (`list[tuple[int, float]]` of `(index, weight)` pairs), written to a sparse index. The column must belong to `table`.
* **api\_key** (`str` | `None`) – Pinecone API key. When `None`, the `PINECONE_API_KEY` environment variable is used.
* **host** (`str` | `None`) – Control-plane host. Leave as `None` for Pinecone cloud (`https://api.pinecone.io`); set it to a local URL such as `"http://localhost:5080"` to target Pinecone Local.
* **namespace** (`str`) – Pinecone namespace to write to. Defaults to the index’s default namespace.
* **metadata\_columns** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – Column references for the columns to store as record metadata. When `None`, every column except `primary_key` and `vector` is stored. All columns must belong to `table`.
* **batch\_size** (`int`) – Maximum number of records sent to Pinecone per `upsert` call (capped at Pinecone’s per-request limit of 1000).
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output within each mini-batch will be sorted in ascending order by the given columns.
* **Returns**
None
Example:
Suppose you have a couple of documents, each already turned into a 4-dimensional embedding, and you want them to be searchable in Pinecone — and to stay in sync as the documents change.
The first thing to take care of is the index itself: the connector never creates it, so it has to exist before the pipeline starts, and its `dimension` must match the length of your vectors (`4` here).
`from pinecone import Pinecone, ServerlessSpec pc = Pinecone(api_key="YOUR_API_KEY") pc.create_index( name="docs", dimension=4, metric="cosine", spec=ServerlessSpec(cloud="aws", region="us-east-1"), )`
With the index in place, you describe the data. Each document has an id that will become the Pinecone record id, the embedding itself, and a `title` you would like to keep around — here as a small static table, but in a real pipeline this would come from a connector:
`import pathway as pw class DocSchema(pw.Schema): doc_id: str = pw.column_definition(primary_key=True) embedding: list[float] title: str table = pw.debug.table_from_rows( DocSchema, [("a", [0.1, 0.2, 0.3, 0.4], "First"), ("b", [0.5, 0.6, 0.7, 0.8], "Second")], )`
Now you point the connector at the index, spelling out which column is the record id and which one holds the vector. Everything left over — in this case `title` — is stored as record metadata automatically, so there is nothing else to configure:
`pw.io.pinecone.write( table, index_name="docs", primary_key=table.doc_id, vector=table.embedding, api_key="YOUR_API_KEY", )`
Notice that nothing has reached Pinecone yet: like every Pathway pipeline, the write is lazy. It is the final `pw.run()` that actually starts the dataflow, upserts the two records, and from then on keeps the index in sync with any later change to `table`:
`pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
For hybrid retrieval you need two indexes, since a Pinecone index stores vectors of one kind: the dense one you already have, plus a sparse one (`vector_type="sparse"`, which is always scored by `dotproduct` and takes no dimension):
`pc.create_index( name="docs-sparse", metric="dotproduct", vector_type="sparse", spec=ServerlessSpec(cloud="aws", region="us-east-1"), )`
The table now carries both vectors — the dense embedding and, say, BM25 term weights as `(token_id, weight)` pairs:
`class HybridSchema(pw.Schema): doc_id: str = pw.column_definition(primary_key=True) embedding: list[float] bm25: list[tuple[int, float]] title: str table = pw.debug.table_from_rows( HybridSchema, [ ("a", [0.1, 0.2, 0.3, 0.4], [(7, 2.0), (21, 1.0)], "First"), ("b", [0.5, 0.6, 0.7, 0.8], [(3, 1.0)], "Second"), ], )`
Attach one `write()` per index off that single table, each naming the column it writes. Both calls use the same `primary_key`, so a document lands in the two indexes under the same record id — that is what lets you fuse the dense and the sparse result lists at query time. `metadata_columns` is spelled out here because the default would try to store the _other_ vector column as metadata, which Pinecone cannot hold. Additions, updates, and deletions are propagated to both indexes:
`pw.io.pinecone.write( table, index_name="docs", primary_key=table.doc_id, vector=table.embedding, metadata_columns=[table.title], api_key="YOUR_API_KEY", ) pw.io.pinecone.write( table, index_name="docs-sparse", primary_key=table.doc_id, vector=table.bm25, metadata_columns=[table.title], api_key="YOUR_API_KEY", ) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
[Pathway Io\
\
pw.io.null](https://pathway.com/developers/api-docs/pathway-io/null)
[Pathway Io\
\
pw.io.plaintext](https://pathway.com/developers/api-docs/pathway-io/plaintext)
---
# pw.io.chroma | Pathway
pw.io.chroma
============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
[Chroma](https://www.trychroma.com/)
stores records with a fixed shape — a string `id`, an `embedding` vector, an optional `document` text, and a set of scalar `metadata` values. The connector therefore maps the columns of the written table onto those fields explicitly: the `primary_key` column becomes the record id, the `embedding` column becomes the vector, the optional `document` column becomes the stored text, and the `metadata_columns` become the record metadata. The `primary_key` column is optional — when it is omitted, the row’s internal Pathway key is used as the record id instead. The target collection must already exist before the pipeline starts — the connector does not create it, because the vector dimension is fixed by the collection and is not part of a Pathway Live Data Framework type.
A row added to the table is stored in the collection, a row removed from the table is deleted from the collection by its id, and a changed row replaces the previous value with the same id, so the collection always mirrors the current state of the table.
The table below explains how each Pathway Live Data Framework type is stored in Chroma. Because Chroma record ids are strings, the value of the `primary_key` column is converted to its string form regardless of its Pathway type.
[Pathway Live Data Framework types serialization into Chroma](https://pathway.com/developers/api-docs/pathway-io/chroma#pathway-live-data-framework-types-serialization-into-chroma)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
| Framework’s type | Record field | Stored as |
| --- | --- | --- |
| `int` (`primary_key`) | `id` | `string` — the integer’s decimal text, e.g. `42` → `"42"` |
| `str` (`primary_key`) | `id` | `string` — used as-is |
| `bool` (`primary_key`) | `id` | `string` — `"true"` / `"false"` |
| `pointer` (`primary_key`) | `id` | `string` — the pointer’s string form |
| `list[float]` / `list[int]` | `embedding` | a 32-bit float vector; `float` values are narrowed to 32-bit precision (Chroma stores embeddings as `float32`) |
| one-dimensional `np.ndarray` (`float` or `int`) | `embedding` | a 32-bit float vector, as above; multi-dimensional arrays are rejected when the computation starts |
| `str` (`document`) | `document` | `string` |
| `str` (`metadata_columns`) | `metadata` value | `string` |
| `int` (`metadata_columns`) | `metadata` value | `integer` |
| `float` (`metadata_columns`) | `metadata` value | `float` |
| `bool` (`metadata_columns`) | `metadata` value | `boolean` |
An `Optional` metadata column whose value is missing for a given row is stored with that metadata key omitted for that record. Any other Pathway Live Data Framework type passed as an embedding, document, or metadata column is rejected when the computation starts.
[**write**(table, collection\_name, \*, primary\_key=None, embedding, document=None, metadata\_columns=None, host='localhost', port=8000, ssl=False, headers=None, tenant='default\_tenant', database='default\_database', name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/chroma#pathway.io.chroma.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/chroma/__init__.py#L25-L182)
Writes a Pathway Live Data Framework table to a [Chroma](https://www.trychroma.com/)
collection over the server’s HTTP API.
The collection always mirrors the current state of the table: a row added to the table is stored in the collection, a row removed from the table is deleted from the collection, and a changed row replaces the previous value. The `primary_key` column identifies each record; since Chroma record ids are strings, its value is stored as its string form. When `primary_key` is omitted, the row’s internal Pathway key is used as the record `id` instead.
Chroma records have a fixed shape, so the columns of `table` are mapped onto Chroma’s record fields explicitly:
* `primary_key` → the record `id`,
* `embedding` → the record `embedding` vector,
* `document` (optional) → the record `document` text,
* `metadata_columns` (optional) → the record `metadata`.
The target collection must already exist before the pipeline starts; the connector does not create it. Create it upfront, e.g. with `chromadb.HttpClient(...).create_collection(...)`.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **collection\_name** (`str`) – Name of the Chroma collection to write to. It must already exist on the server.
* **primary\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – An optional column reference (e.g. `table.doc_id`) whose values are used as the Chroma record id. The column must belong to `table`; values are converted to `str`. If omitted (the default), the row’s internal Pathway key is used as the record id instead.
* **embedding** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – A column reference (e.g. `table.vector`) holding the embedding vector for each row. Must be of Pathway type `list[float]` or a 1-D `numpy.ndarray`.
* **document** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – An optional column reference (e.g. `table.text`) holding the document text stored alongside each vector. Must be of type `str`.
* **metadata\_columns** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – Optional column references for scalar metadata stored with each vector (e.g. `table.title, table.category`). Each value must be `str`, `int`, `float`, or `bool`. A `None` value drops that key for the affected record.
* **host** (`str`) – Host of the Chroma server. Defaults to `"localhost"`.
* **port** (`int`) – Port of the Chroma server. Defaults to `8000`.
* **ssl** (`bool`) – Whether to connect over HTTPS. Defaults to `False`.
* **headers** (`dict`\[`str`, `str`\] | `None`) – Optional HTTP headers forwarded with every request, e.g. an authorization token for Chroma Cloud.
* **tenant** (`str`) – Chroma tenant to use. Defaults to `"default_tenant"`.
* **database** (`str`) – Chroma database to use. Defaults to `"default_database"`.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output within each minibatch will be sorted in ascending order by the given columns. When multiple columns are provided, the corresponding value tuples are compared lexicographically.
* **Returns**
None
Example:
Suppose you are building a document search pipeline and want to store embeddings in Chroma running in a container (`docker run -p 8000:8000 chromadb/chroma`).
Create the collection before starting the pipeline:
`import chromadb client = chromadb.HttpClient(host="localhost", port=8000) client.create_collection("docs")`
Define your Pathway Live Data Framework schema and build the table:
`import pathway as pw class DocSchema(pw.Schema): doc_id: int = pw.column_definition(primary_key=True) text: str embedding: list[float] table = pw.debug.table_from_rows( DocSchema, [(1, "hello", [0.1, 0.2, 0.3, 0.4]), (2, "world", [0.5, 0.6, 0.7, 0.8])], )`
Attach the Chroma output connector, mapping each column to a Chroma record field:
`pw.io.chroma.write( table, collection_name="docs", primary_key=table.doc_id, embedding=table.embedding, document=table.text, ) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
[Pathway Io\
\
pw.io.bigquery](https://pathway.com/developers/api-docs/pathway-io/bigquery)
[Pathway Io\
\
pw.io.clickhouse](https://pathway.com/developers/api-docs/pathway-io/clickhouse)
---
# pw.io.dynamodb | Pathway
pw.io.dynamodb
==============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
All internal Pathway Live Data Framework types, except `Any`, can be stored in DynamoDB. The table below explains how Live Data Framework types are serialized into DynamoDB. You can also refer to the [official documentation](https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/HowItWorks.NamingRulesDataTypes.html#HowItWorks.DataTypes)
to learn more about the data types supported by the database.
[Pathway types conversion into DynamoDB](https://pathway.com/developers/api-docs/pathway-io/dynamodb#pathway-types-conversion-into-dynamodb)
---------------------------------------------------------------------------------------------------------------------------------------------
| Live Data Framework type | DynamoDB type |
| --- | --- |
| `bool` | `Boolean` |
| `int` | `Number` |
| `float` | `Number` |
| `pointer` | `String`, can be deserialized back if `pw.Pointer` is read by a Live Data Framework connector |
| `str` | `String` |
| `bytes` | `Binary` |
| `Naive DateTime` | `String`, containing the datetime in ISO-8601 format |
| `UTC DateTime` | `String`, containing the datetime in ISO-8601 format |
| `Duration` | `Number`, serialized with nanosecond precision |
| `JSON` | `String`, containing the serialized JSON value |
| `np.ndarray` | `Map`, with two top-level fields: a `List` named `"shape"` denoting the shape of the stored array, and a `List` named `"elements"` denoting the elements of a flattened array |
| `tuple` | `List` with as many fields as elements in the tuple. These elements correspond to the serialized values of the tuple elements |
| `list` | `List` |
| `pw.PyObjectWrapper` | `binary`, can be deserialized back if read by a Live Data Framework connector |
[**write**(table, table\_name, partition\_key, \*, sort\_key=None, init\_mode='default', name=None)](https://pathway.com/developers/api-docs/pathway-io/dynamodb#pathway.io.dynamodb.write)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/dynamodb/__init__.py#L17-L270)
Writes `table` into a DynamoDB table. The connection settings are retrieved from the environment.
This connector supports three modes: `default` mode, which performs no preparation on the target table; `create_if_not_exists` mode, which creates the table if it does not already exist; and `replace` mode, which replaces the table and clears any previously existing data. The table is created with an [on-demand](https://docs.aws.amazon.com/amazondynamodb/latest/developerguide/capacity-mode.html)
billing mode. Be aware that this mode may not be optimal for your use case, and the provisioned mode with capacity planning might offer better performance or cost efficiency. In such cases, we recommend creating the table yourself in AWS with the desired provisioned throughput settings.
Note that if the table already exists and you use either `default` or `create_if_not_exists` mode, the schema of the table, including the primary key and optional sort key, must match the schema of the table you are writing.
The connector performs writes using the primary key, defined as a combination of the partition key and an optional sort key. Note that, due to how DynamoDB operates, entries may overwrite existing ones if their keys coincide. When an entry is deleted from the Pathway Live Data Framework table, the corresponding entry is also removed from the DynamoDB table maintained by the connector. In this sense, the connector behaves similarly to the snapshot mode in the [Delta Lake](https://pathway.com/developers/api-docs/pathway-io/deltalake/#pathway.io.deltalake.write)
output connector or the [Postgres](https://pathway.com/developers/api-docs/pathway-io/postgres#pathway.io.postgres.write_snapshot)
output connector.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **table\_name** (`str`) – The name of the destination table in DynamoDB.
* **partition\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The column to use as the [partition key](https://aws.amazon.com/blogs/database/choosing-the-right-dynamodb-partition-key/)
in the destination table. Note that only the scalar types `String`, `Number` and `Binary` can be used as index fields in DynamoDB. Therefore, the field you select in the Pathway Live Data Framework table must serialize to one of these types. You can verify this using the conversion table provided in the connector documentation. In particular, `bool` columns serialize to the DynamoDB `Boolean` type, which is not a valid key type, so they cannot be used as a partition or sort key.
* **sort\_key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – An optional sort key for the destination table. Note that only the scalar types `String`, `Number` and `Binary` can be used as the index fields in DynamoDB. Similarly to the partition key, you can only use fields that serialize into one of these scalar DynamoDB types.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – The table initialization mode, one of the three described above.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **Returns**
None
Example:
AWS provides an official DynamoDB Docker image that allows you to test locally. The image is available as `amazon/dynamodb-local` and can be run as follows:
`docker pull amazon/dynamodb-local:latest docker run -p 8000:8000 --name dynamodb-local amazon/dynamodb-local:latest`
The first command pulls the DynamoDB image from the official repository. The second command starts a container and exposes port `8000`, which will be used for the connection.
Since the database runs locally and the settings are retrieved from the environment, you will need to configure them accordingly. The easiest way to do this is by setting a few environment variables to point to the running Docker image:
`export AWS_ENDPOINT_URL=http://localhost:8000 export AWS_REGION=us-west-2`
Please note that specifying the AWS region is required; however, the exact region does not matter for the run to succeed, it simply needs to be set. The endpoint, in turn, should point to the database running in the Docker container, accessible through the exposed port.
At this point, the database is ready, and you can start writing a program. For example, you can implement a program that stores data in a table in the locally running database.
First, create a table:
`import pathway as pw table = pw.debug.table_from_markdown(''' key | value 1 | Hello 2 | World ''')`
Next, save it as follows:
`pw.io.dynamodb.write( table, table_name="test", partition_key=table.key, init_mode="create_if_not_exists", )`
Remember to run your program by calling `pw.run()`. Note that if the table does not already exist, using `init_mode="default"` will result in a failure, as Pathway Live Data Framework will not create the table and the write will fail due to its absence.
When finished, you can query the local DynamoDB for the table contents using the AWS command-line tool:
`aws dynamodb scan --table-name test`
This will display the contents of the freshly created table:
`{ "Items": [ { "value": { "S": "World" }, "key": { "N": "2" } }, { "value": { "S": "Hello" }, "key": { "N": "1" } } ], "Count": 2, "ScannedCount": 2, "ConsumedCapacity": null }`
Note that since the `table.key` field is the partition key, writing an entry with the same partition key will overwrite the existing data. For example, you can create a smaller table with a repeated key:
`table = pw.debug.table_from_markdown(''' key | value 1 | Bonjour ''')`
Then write it again in `"default"` mode:
`pw.io.dynamodb.write( table, table_name="test", partition_key=table.key, )`
Then, the contents of the target table will be updated with this new entry where `key` equals to `1`:
`{ "Items": [ { "value": { "S": "World" }, "key": { "N": "2" } }, { "value": { "S": "Bonjour" }, "key": { "N": "1" } } ], "Count": 2, "ScannedCount": 2, "ConsumedCapacity": null }`
Finally, you can run a program in `"replace"` table initialization mode, which will overwrite the existing data:
`table = pw.debug.table_from_markdown(''' key | value 3 | Hi ''') pw.io.dynamodb.write( table, table_name="test", partition_key=table.key, init_mode="replace", )`
The next run of `aws dynamodb scan --table-name test` will then return a single-row table:
`{ "Items": [ { "value": { "S": "Hi" }, "key": { "N": "3" } } ], "Count": 1, "ScannedCount": 1, "ConsumedCapacity": null }`
[Pathway Io\
\
pw.io.duckdb](https://pathway.com/developers/api-docs/pathway-io/duckdb)
[Pathway Io\
\
pw.io.elasticsearch](https://pathway.com/developers/api-docs/pathway-io/elasticsearch)
---
# Unknown
SearchK
---
# pw.io.duckdb | Pathway
pw.io.duckdb
============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
The Pathway Live Data Framework provides an **Output** connector for [DuckDB](https://duckdb.org/)
. DuckDB is an in-process analytical database, so the connector needs no external service: data is written natively into a DuckDB database file. See the `write` documentation below for the output modes (`stream_of_changes` / `snapshot`), the `init_mode` options, and the `primary_key` rules. The type conversion is given in the table below.
[Type Conversion (Output Connector)](https://pathway.com/developers/api-docs/pathway-io/duckdb#type-conversion-output-connector)
---------------------------------------------------------------------------------------------------------------------------------
The table below describes how Pathway Live Data Framework values are written into DuckDB columns. List, array, tuple and `pw.Json` values are bound as a JSON string and cast back into the destination type inside the generated SQL, because the underlying DuckDB driver cannot bind a list value as a statement parameter directly; this is transparent to the user.
### [Framework types written by the output connector](https://pathway.com/developers/api-docs/pathway-io/duckdb#framework-types-written-by-the-output-connector)
| Framework type | DuckDB type | Encoding / notes |
| --- | --- | --- |
| `bool` | `BOOLEAN` | As-is. |
| `int` | `BIGINT` | As-is. |
| `float` | `DOUBLE` | As-is. |
| `str` | `VARCHAR` | UTF-8 text. |
| `bytes` | `BLOB` | Raw bytes. |
| `pw.DateTimeNaive` | `TIMESTAMP` | Microsecond resolution. |
| `pw.DateTimeUtc` | `TIMESTAMP` | Stored as the UTC wall-clock value (microsecond resolution), independent of any session time zone. |
| `pw.Duration` | `INTERVAL` | Microsecond resolution. |
| `pw.Json` | `JSON` | A JSON document. |
| `pw.Pointer` | `VARCHAR` | Pathway Live Data Framework’s base32 pointer encoding, e.g. `^Z5QKEQ…`. |
| `list[T]` / `tuple` of one element type | `T[]` | A native DuckDB list, e.g. `list[float]` → `DOUBLE[]`. Searchable with `list_cosine_similarity` & friends. |
| `np.ndarray` (`int` / `float` elements) | `BIGINT[]` / `DOUBLE[]` | A native DuckDB list; multi-dimensional arrays become nested lists (`DOUBLE[][]` …) following the array shape. |
| heterogeneous `tuple` | `JSON` | A JSON array — tuples whose elements have different types have no natural list column type. |
| `pw.PyObjectWrapper` | `BLOB` | A `bincode` payload. |
| `None` (in optional columns) | `NULL` | Non-optional columns are created `NOT NULL`. |
[**write**(table, \*, table\_name, database, max\_batch\_size=None, init\_mode='default', output\_table\_type='stream\_of\_changes', primary\_key=None, detach\_between\_batches=False, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/duckdb#pathway.io.duckdb.write)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/duckdb/__init__.py#L40-L393)
Writes `table` into a table of a [DuckDB](https://duckdb.org/)
database file. DuckDB is an in-process analytical database, so this connector needs no external service: data is written natively into a database file. Two output table types are supported, selected with `output_table_type`.
With `"stream_of_changes"` (the default) the output table contains a log of every change seen in the Pathway table. Two extra columns, `time` (`BIGINT`) and `diff` (`SMALLINT`), are appended: `time` is the minibatch timestamp of the change and `diff` is `1` for an insertion or `-1` for a deletion. A row modification is therefore expressed as a deletion (`diff = -1`) followed by an insertion (`diff = 1`) within the same minibatch. A schema column named `time` or `diff` collides with these metadata columns and is rejected at `write()` time.
With `"snapshot"` the output table is kept in sync with the current state of the Pathway table: `+1` events are applied as `INSERT ... ON CONFLICT (primary_key) DO UPDATE` and `-1` events as `DELETE ... WHERE primary_key = ?`, so no `time` / `diff` columns are written. `primary_key` is required in this mode (and forbidden otherwise) and must list non-nullable columns of `table`: a `NULL` key makes `DELETE ... WHERE primary_key = NULL` never match on retractions, leaving stale rows behind. The destination table must carry a `PRIMARY KEY` / `UNIQUE` constraint on those columns for the upsert to target; `init_mode="create_if_not_exists"` / `"replace"` create it for you.
`init_mode` decides what state the destination table should be in before the first write. `"default"` requires the table to already exist with matching columns (plus `time` / `diff` in stream-of-changes mode); `"create_if_not_exists"` creates it if missing, with columns derived from the Pathway table (and a `PRIMARY KEY` on `primary_key` in snapshot mode); `"replace"` drops and recreates it. Once the connection is opened the destination table is validated and a clear error is raised — instead of an opaque mid-write failure — if it is a view, is missing (under `"default"`), lacks a column the writer needs (including `time` / `diff` in stream-of-changes mode), has an extra `NOT NULL` column without a default, or has a `NOT NULL` column that an `Optional` Pathway column maps onto. Pathway column names that differ only in case are rejected at `write()` time, since DuckDB compares identifiers case-insensitively.
Column types are mapped onto their natural DuckDB equivalents as described in the type-conversion table above. In particular, columns holding embeddings — whether typed as `numpy` arrays or as `list[float]` — are stored as DuckDB `DOUBLE[]` lists, which can be queried directly with DuckDB’s vector-distance functions (`list_cosine_similarity`, `list_distance`, `list_inner_product`); this makes the resulting table usable as a vector store for retrieval in a RAG pipeline.
DuckDB is an embedded, single-file database: a database file may be held read-write by one process or read-only by several processes, never both at once. The connector offers two ways to live with that constraint, selected with `detach_between_batches`. With the default `False` the writer opens the database once and holds it until the pipeline terminates — the lowest overhead, but no other process can open the file (even read-only) while the pipeline runs. With `True` the writer opens the database for each minibatch commit and fully closes it right after, checkpointing the WAL and releasing the OS file lock in the gaps between batches — so a separate process (for example a query server) can read committed data from the file while the pipeline keeps running. Readers can still race a flush, so they should open short-lived read-only connections and retry briefly on a lock error; the writer behaves symmetrically and retries acquiring the lock with a backoff (starting at 10 ms, doubling up to 1 s) for up to 30 seconds before failing. Detaching costs a per-batch file open plus a WAL checkpoint — typically milliseconds for local files — so with sub-second minibatches consider a larger `autocommit_duration_ms`. Since an in-memory database is dropped when its last connection closes, `detach_between_batches=True` together with `database=":memory:"` is rejected. All writes for a single `pw.io.duckdb.write` run on one worker even when Pathway runs with several workers; DuckDB serializes writes to a file regardless, so this costs no throughput while keeping the output complete and deterministic.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **table\_name** (`str`) – The name of the target table in the DuckDB database.
* **database** (`PathLike` | `str`) – Path to the DuckDB database file. The file is created if it does not exist. `":memory:"` opens a private in-process database (only useful within a single run). If the path resolves to an existing directory, a `ValueError` is raised at call time.
* **max\_batch\_size** (`int` | `None`) – Optional upper bound on the number of rows buffered between flushes. Each batch is committed inside a single DuckDB transaction.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – How the destination table is initialized before the first write, one of `"default"`, `"create_if_not_exists"` or `"replace"` (see above).
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – How the output table represents the data, either `"stream_of_changes"` (the default) or `"snapshot"` (see above).
* **primary\_key** (`list`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\] | `None`) – One or more columns of `table` that form the primary key in the destination table. Required for snapshot mode and forbidden otherwise.
* **detach\_between\_batches** (`bool`) – If `True`, the writer closes the database after every minibatch commit and reopens it for the next one, releasing the OS file lock in between so other processes can query the file with short-lived read-only connections while the pipeline runs (see above for the reader/writer retry semantics and the per-batch reopen cost). The default `False` keeps the database open for the whole run. Incompatible with `database=":memory:"`.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Examples:
Consider a stream of changes appended to a DuckDB file. A schema may mix arbitrary column types — here an integer, a float, a string and a boolean — and the connector adds the `time` / `diff` columns automatically:
`import pathway as pw class MeasurementSchema(pw.Schema): sensor: str temperature: float readings: int active: bool measurements = pw.debug.table_from_rows( MeasurementSchema, [("sensor-a", 21.5, 100, True), ("sensor-b", 19.0, 80, False)], ) pw.io.duckdb.write( measurements, table_name="measurements", database="./metrics.duckdb", init_mode="create_if_not_exists", ) pw.run()`
Alternatively, the destination table can be kept in sync with the current state of the Pathway table by using the snapshot output type. A `primary_key` is required, and — unlike the stream of changes — no `time` / `diff` columns are written:
`class AccountSchema(pw.Schema): account_id: int balance: float accounts = pw.debug.table_from_rows( AccountSchema, [(1, 100.0), (2, 250.0)], ) pw.io.duckdb.write( accounts, table_name="accounts", database="./bank.duckdb", output_table_type="snapshot", primary_key=[accounts.account_id], init_mode="create_if_not_exists", ) pw.run()`
The resulting table holds only the data columns — no `time` / `diff`:
`SELECT * FROM accounts; +------------+---------+ | account_id | balance | | int64 | double | +------------+---------+ | 1 | 100.0 | | 2 | 250.0 | +------------+---------+`
As a final example, a table of document chunks together with their embeddings is persisted into a DuckDB file for retrieval (RAG). `list[float]` columns are stored as native `DOUBLE[]` lists:
`class DocSchema(pw.Schema): text: str embedding: list[float] docs = pw.debug.table_from_rows( DocSchema, [("a cat sat on a mat", [1.0, 0.0, 0.0]), ("a dog in the yard", [0.0, 1.0, 0.0])], ) pw.io.duckdb.write( docs, table_name="documents", database="./docs.duckdb", init_mode="create_if_not_exists", ) pw.run()`
Afterwards the embeddings can be searched with plain DuckDB SQL:
`SELECT text, list_cosine_similarity(embedding, [1.0, 0.0, 0.0]) AS score FROM documents WHERE diff = 1 ORDER BY score DESC LIMIT 5;`
[Pathway Io\
\
pw.io.deltalake](https://pathway.com/developers/api-docs/pathway-io/deltalake)
[Pathway Io\
\
pw.io.dynamodb](https://pathway.com/developers/api-docs/pathway-io/dynamodb)
---
# pw.io.kafka | Pathway
pw.io.kafka
===========
[class **SchemaRegistryHeader**(key, value)](https://pathway.com/developers/api-docs/pathway-io/kafka#pathway.io.kafka.SchemaRegistryHeader)
---------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/_io_helpers.py#L194-L220)
Represents an additional header to be used in Confluent Schema Registry HTTP requests.
* **Parameters**
* **key** (`str`) – The header key.
* **value** (`str`) – The header value.
* **Returns**
The constructed header object
[class **SchemaRegistrySettings**(urls, token\_authorization=None, username=None, password=None, headers=None, proxy=None, timeout=None)](https://pathway.com/developers/api-docs/pathway-io/kafka#pathway.io.kafka.SchemaRegistrySettings)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/_io_helpers.py#L223-L321)
Connection settings for the Confluent Schema Registry.
* **Parameters**
* **urls** (`list`\[`str`\]) – A list of URLs for connecting to the schema registry. If multiple URLs are provided, they will be used in the specified order.
* **token\_authorization** (`str` | `None`) – Token used for token-based authorization.
* **username** (`str` | `None`) – Username for simple authorization.
* **password** (`str` | `None`) – Password for simple authorization. If specified, a username must also be provided.
* **headers** (`list`\[[`SchemaRegistryHeader`](https://pathway.com/developers/api-docs/pathway-io-kafka#pathway.io.kafka.SchemaRegistryHeader)\
\] | `None`) – Additional headers to include in HTTP requests to the schema registry.
* **proxy** (`str` | `None`) – Proxy address for registry requests.
* **timeout** (`timedelta` | `None`) – Timeout duration for network requests, in seconds.
* **Returns**
The configuration object.
[**read**(rdkafka\_settings, topic=None, \*, schema=None, mode='streaming', format='raw', schema\_registry\_settings=None, debug\_data=None, autocommit\_duration\_ms=1500, json\_field\_paths=None, autogenerate\_key=False, with\_metadata=False, start\_from\_timestamp\_ms=None, parallel\_readers=None, name=None, max\_backlog\_size=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/kafka#pathway.io.kafka.read)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/kafka/__init__.py#L31-L407)
Generalized method to read the data from the given topic in Kafka.
There are three formats currently supported: `"plaintext"`, `"raw"`, and `"json"`. If the `"raw"` format is chosen, the key and the payload are read from the topic as raw bytes and used in the table “as is”. If you choose the `"plaintext"` option, however, they are parsed from the UTF-8 into the plaintext entries. In both cases, the table consists of a primary key and two columns `"key"` and `"data"`, denoting the key and the payload read.
If `"json"` is chosen, the connector first parses the payload of the message according to the JSON format and then creates the columns corresponding to the schema defined by the `schema` parameter. The values of these columns are taken from the respective parsed JSON fields.
* **Parameters**
* **rdkafka\_settings** (`dict`) – Connection settings in the format of [librdkafka](https://github.com/edenhill/librdkafka/blob/master/CONFIGURATION.md)
.
* **topic** (`str` | `list`\[`str`\] | `None`) – Name of topic in Kafka from which the data should be read.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Specifies how the engine retrieves data from the topic. The default value is `"streaming"`, which means the engine will constantly wait for new messages, process them as they arrive, and send them into the engine. Alternatively, if set to `"static"`, the engine will only read and process the data that is already available at the time of execution.
* **format** (`Literal`\[`'plaintext'`, `'raw'`, `'json'`\]) – format of the input data, `"raw"`, `"plaintext"`, or `"json"`.
* **schema\_registry\_settings** ([`SchemaRegistrySettings`](https://pathway.com/developers/api-docs/pathway-io-kafka#pathway.io.kafka.SchemaRegistrySettings)
| `None`) – settings for connecting to the Confluent Schema Registry, if this type of registry is used.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is JSON, this field allows to map field names into path in the field. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **autogenerate\_key** (`bool`) – If `True`, Pathway Live Data Framework automatically generates unique primary key for the entries read. Otherwise it first tries to use the key from the message. This parameter is used only if the `format` is “raw” or “plaintext”.
* **with\_metadata** (`bool`) – When set to `True`, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field. It’ll contain an optional field `timestamp_millis` denoting the UNIX timestamp of a record in milliseconds, if available. It will also contain fields `topic`, `partition` and `offset` denoting the topic, partition and offset respectively, that correspond to the Kafka message that produced this row. Finally, the top level of this column’s JSON will contain a `headers` array. Each element will be a pair consisting of a string (the header name) and an optional base64-encoded string (the header value). The header value is `null` only when the header body is absent (the Kafka protocol distinguishes a missing body from an empty one); a present-but-empty body is encoded as an empty string.
* **start\_from\_timestamp\_ms** (`int` | `None`) – If defined, the read starts from entries with the given timestamp in the past, specified in milliseconds.
* **parallel\_readers** (`int` | `None`) – number of copies of the reader to work in parallel. In case the number is not specified, min{pathway\_threads, total number of partitions} will be taken. This number also can’t be greater than the number of Pathway Live Data Framework engine threads, and will be reduced to the number of engine threads, if it exceeds.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
_Table_ – The table read.
When using the format `"raw"` or `"plaintext"`, the connector will produce a two-column table: all the payloads are saved into a column named `data`, while the keys are saved into a column `key`.
For other formats, the schema is required and defines the columns.
Example:
Consider a Kafka queue running locally on port 9092. For demonstration purposes, our queue uses simple SASL/PLAIN authentication. You can set up a Kafka cluster with similar parameters in [Confluent Cloud](https://confluent.cloud/)
or run it locally using Docker or Docker Compose. The rdkafka settings in our example will look as follows:
`import os rdkafka_settings = { "bootstrap.servers": "localhost:9092", "group.id": "kafka-tests", "security.protocol": "sasl_ssl", "sasl.mechanism": "PLAIN", "sasl.username": os.environ["KAFKA_USERNAME"], "sasl.password": os.environ["KAFKA_PASSWORD"] }`
To connect to the topic “animals” and accept messages, the connector must be used as follows, depending on the format:
Raw version:
`import pathway as pw t = pw.io.kafka.read( rdkafka_settings, topic="animals", format="raw", )`
All the payload data will be accessible in the column `data`, the keys of the messages will be stored in the column `key`.
JSON version:
`class InputSchema(pw.Schema): owner: str pet: str t = pw.io.kafka.read( rdkafka_settings, topic="animals", format="json", schema=InputSchema, )`
For the JSON connector, you can send these two messages:
`{"owner": "Alice", "pet": "cat"} {"owner": "Bob", "pet": "dog"}`
This way, you get a table which looks as follows:
`pw.debug.compute_and_print(t, include_id=False)`
Code Results
Now consider that the data about pets come in a more sophisticated way. For instance you have an owner, kind and name of an animal, along with some physical measurements.
The JSON payload in this case may look as follows:
`{ "name": "Jack", "pet": { "animal": "cat", "name": "Bob", "measurements": [100, 200, 300] } }`
Suppose you need to extract a name of the pet and the height, which is the 2nd (1-based) or the 1st (0-based) element in the array of measurements. Then, you use JSON Pointer and do a connector, which gets the data as follows:
`class InputSchema(pw.Schema): pet_name: str pet_height: int t = pw.io.kafka.read( rdkafka_settings, topic="animals", format="json", schema=InputSchema, json_field_paths={ "pet_name": "/pet/name", "pet_height": "/pet/measurements/1" }, )`
Note that a Kafka message contains a key and a payload. By default, the schema fields are parsed from the payload, but this behavior can be changed. To do that, you need to specify the `source_component` parameter for the target fields. For example, if the schema is similar to the example above, but there is also a unique pet ID stored in the key JSON at the path `/pet/identification/id`, you can read it by first modifying the schema:
`class InputSchema(pw.Schema): pet_id: int = pw.column_definition(primary_key=True, source_component="key") pet_name: str pet_height: int`
And then by providing a JSONPath to this field as well in the `read` method:
`t = pw.io.kafka.read( rdkafka_settings, topic="animals", format="json", schema=InputSchema, json_field_paths={ "pet_id": "/pet/identification/id", "pet_name": "/pet/name", "pet_height": "/pet/measurements/1" }, )`
Note that you would not need to provide the JSONPath for `pet_id` if it is at the top level of the key JSON.
[**write**(table, rdkafka\_settings, topic\_name, \*, format='json', schema\_registry\_settings=None, subject=None, delimiter=',', key=None, value=None, headers=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/kafka#pathway.io.kafka.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/kafka/__init__.py#L538-L753)
Write a table to a given topic on a Kafka instance.
The produced messages consist of the key, corresponding to row’s key, the value, corresponding to the values of the table that are serialized according to the chosen format and two headers: `pathway_time`, corresponding to the logical time of the entry and `pathway_diff` that is either 1 or -1. Both header values are provided as UTF-8 encoded strings.
There are several serialization formats supported: ‘json’, ‘dsv’, ‘plaintext’ and ‘raw’. The format defines how the message is formed. In case of JSON and DSV (delimiter separated values), the message is formed in accordance with the respective data format.
If the selected format is either ‘plaintext’ or ‘raw’, you also need to specify, which columns of the table correspond to the key and the value of the produced Kafka message. It can be done by providing `key` and `value` parameters. In order to output extra values from the table in these formats, Kafka headers can be used. You can specify the column references in the `headers` parameter, which leads to serializing the extracted fields into UTF-8 strings and passing them as additional Kafka headers.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the table to output.
* **rdkafka\_settings** (`dict`) – Connection settings in the format of [librdkafka](https://github.com/edenhill/librdkafka/blob/master/CONFIGURATION.md)
.
* **topic\_name** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The Kafka topic where data will be written. This can be a specific topic name or a reference to a column whose values will be used as the topic for each message. If using a column reference, the column must contain string values.
* **format** (`Literal`\[`'raw'`, `'plaintext'`, `'json'`, `'dsv'`\]) – format in which the data is put into Kafka. Currently “json”, “plaintext”, “raw” and “dsv” are supported. If the “raw” format is selected, `table` must either contain exactly one binary column that will be dumped as it is into the Kafka message, or the reference to the target binary column must be specified explicitly in the `value` parameter. Similarly, if “plaintext” is chosen, the table should consist of a single column of the string type, or the reference to the target string column must be specified explicitly in the `value` parameter.
* **schema\_registry\_settings** ([`SchemaRegistrySettings`](https://pathway.com/developers/api-docs/pathway-io-kafka#pathway.io.kafka.SchemaRegistrySettings)
| `None`) – settings for connecting to the Confluent Schema Registry, if this type of registry is used.
* **subject** (`str` | `None`) – the subject name for the schema in the Confluent Schema Registry, if the registry is used.
* **delimiter** (`str`) – field delimiter to be used in case of delimiter-separated values format ‘dsv’.
* **key** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – reference to the column that should be used as a key in the produced message. If left empty, an internal primary key will be used.
* **value** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – reference to the column that should be used as a value in the produced message in ‘plaintext’ or ‘raw’ format. It can be deduced automatically if the table has exactly one column. Otherwise it must be specified directly. It also has to be explicitly specified, if `key` is set. The type of the column must correspond to the format used: `str` for the ‘plaintext’ format and `binary` for the ‘raw’ format.
* **headers** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – references to the table fields that must be provided as message headers. These headers are named in the same way as fields that are forwarded and correspond to the string representations of the respective values encoded in UTF-8. If a binary column is requested, it will be produced “as is” in the respective header.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Examples:
Consider a Kafka queue running locally on port 9092. For demonstration purposes, our queue uses simple SASL/PLAIN authentication. You can set up a Kafka cluster with similar parameters in [Confluent Cloud](https://confluent.cloud/)
or run it locally using Docker or Docker Compose. The rdkafka settings in our example will look as follows:
`import os rdkafka_settings = { "bootstrap.servers": "localhost:9092", "security.protocol": "sasl_ssl", "sasl.mechanism": "PLAIN", "sasl.username": os.environ["KAFKA_USERNAME"], "sasl.password": os.environ["KAFKA_PASSWORD"] }`
You want to send a Pathway Live Data Framework table `t` to the Kafka instance.
`import pathway as pw t = pw.debug.table_from_markdown("age owner pet \n 1 10 Alice dog \n 2 9 Bob cat \n 3 8 Alice cat")`
To connect to the topic “animals” and send messages, the connector must be used as follows, depending on the format:
JSON version:
`pw.io.kafka.write( t, rdkafka_settings, "animals", format="json", )`
All the updates of table `t` will be sent to the Kafka instance.
Another thing to be demonstrated is the usage of ‘raw’ format in the output. Please note that the same rules will be applicable for the ‘plaintext’ with the only difference being the requirement for the columns to have the `string` type.
Now consider that a table `t2` contains two binary columns `foo` and `bar`, and a numerical column `baz`. That is, the schema of this table looks as follows:
`class T2Schema(pw.Schema): foo: bytes bar: bytes baz: int`
This table can be generated with a Python input connector as follows:
`class T2GenerationSubject(pw.io.python.ConnectorSubject): def run(self) -> None: # TODO: define generation logic pass t2 = pw.io.python.read(T2GenerationSubject(), schema=T2Schema)`
Since there is more than one column, you need to specify which one you want to use in the output, when using the ‘raw’ format. If this is the column `foo`, you may output this table as follows:
`pw.io.kafka.write( t2, rdkafka_settings, "test", format="raw", value=t2.foo, )`
If at the same time you would prefer to have the key of the produced messages to be defined by the value of another binary column `bar`, you can use the `key` parameter as follows:
`pw.io.kafka.write( t2, rdkafka_settings, "test", format="raw", key=t2.bar, value=t2.foo, )`
Still, the table has three fields and the field `baz` is not produced. You can do it with the usage of headers. To pass it to the header with the same name `baz`, you need to specify it:
`pw.io.kafka.write( t2, rdkafka_settings, "test", format="raw", key=t2.bar, value=t2.foo, headers=[t2.baz], )`
[Pathway Io\
\
pw.io.jsonlines](https://pathway.com/developers/api-docs/pathway-io/jsonlines)
[Pathway Io\
\
pw.io.kinesis](https://pathway.com/developers/api-docs/pathway-io/kinesis)
---
# pw.io.fs | Pathway
pw.io.fs
========
[**read**(path, format, \*, schema=None, mode='streaming', csv\_settings=None, json\_field\_paths=None, object\_pattern='\*', with\_metadata=False, name=None, autocommit\_duration\_ms=1500, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/fs#pathway.io.fs.read)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/fs/__init__.py#L30-L269)
Reads a table from one or several files with the specified format.
In case the format is `"plaintext"`, the table will consist of a single column `data` with each cell containing a single line from the file.
In case the format is one of `"plaintext_by_file"` or `"binary"` the table will consist of a single column `data` with each cell containing contents of the whole file.
If the format is `"only_metadata"`, only the metadata column will be read, without opening and without reading the contents of the files. The metadata is then available in the `_metadata` column.
* **Parameters**
* **path** (`str` | `PathLike`) – Path to the file or to the folder with files or [glob](https://en.wikipedia.org/wiki/Glob_(programming))
pattern for the objects to be read. The connector will read the contents of all matching files as well as recursively read the contents of all matching folders.
* **format** (`Literal`\[`'csv'`, `'json'`, `'plaintext'`, `'plaintext_by_file'`, `'binary'`, `'only_metadata'`\]) – Format of data to be read. Currently `"csv"`, `"json"`, `"plaintext"`, `"plaintext_by_file"`, `"binary"`, and `"only_metadata"` formats are supported. The difference between `"plaintext"` and `"plaintext_by_file"` is how the input is tokenized: if the `"plaintext"` option is chosen, it’s split by the newlines. Otherwise, the files are split in full and one row will correspond to one file. In case the `"binary"` format is specified, the data is read as raw bytes without UTF-8 parsing. Finally, if `"only_metadata"` is chosen, the connector only scans the filesystem for file additions, changes, modifications, and provides them in the metadata column.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"` the engine will wait for the updates in the specified directory. It will track file additions, deletions, and modifications and reflect these events in the state. For example, if a file was deleted, `"streaming"` mode will also remove rows obtained by reading this file from the table. On the other hand, the `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **csv\_settings** ([`CsvParserSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
| `None`) – Settings for the CSV parser. This parameter is used only in case the specified format is `"csv"`.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is `"json"`, this field allows to map field names into path in the read json object. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **object\_pattern** (`str`) – Unix shell style pattern for filtering only certain files in the directory. Ignored in case a path to a single file is specified. This value will be deprecated soon, please use glob pattern in `path` instead.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This JSON field may contain: (1) `created_at` - UNIX timestamp of file creation; (2) `modified_at` - UNIX timestamp of last modification; (3) `seen_at` is a UNIX timestamp of when they file was found by the engine; (4) `owner` - Name of the file `owner` (only for Unix); (5) `path` - Full file path of the source row. (6) `size` - File size in bytes.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Consider you want to read a dataset, stored in the filesystem in a standard CSV format. The dataset contains data about pets and their owners.
For the sake of demonstration, you can prepare a small dataset by creating a CSV file via a unix command line tool:
`printf "id,owner,pet\n1,Alice,dog\n2,Bob,dog\n3,Alice,cat\n4,Bob,dog" > dataset.csv`
In order to read it into Pathway Live Data Framework’s table, you can first do the import and then use the `pw.io.fs.read` method:
`import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.fs.read("dataset.csv", format="csv", schema=InputSchema)`
Then, you can output the table in order to check the correctness of the read:
`pw.debug.compute_and_print(t, include_id=False)`
Code Results
Similarly, we can do the same for JSON format.
First, we prepare a dataset:
`printf "{\"id\":1,\"owner\":\"Alice\",\"pet\":\"dog\"} {\"id\":2,\"owner\":\"Bob\",\"pet\":\"dog\"} {\"id\":3,\"owner\":\"Bob\",\"pet\":\"cat\"} {\"id\":4,\"owner\":\"Bob\",\"pet\":\"cat\"}" > dataset.jsonlines`
And then, we use the method with the `"json"` format:
`t = pw.io.fs.read("dataset.jsonlines", format="json", schema=InputSchema)`
Now let’s try something different. Consider you have site access logs stored in a separate folder in several files. For the sake of simplicity, a log entry contains an access ID, an IP address and the login of the user.
A dataset, corresponding to the format described above can be generated, thanks to the following set of unix commands:
`mkdir logs printf "id,ip,login\n1,127.0.0.1,alice\n2,8.8.8.8,alice" > logs/part_1.csv printf "id,ip,login\n3,8.8.8.8,bob\n4,127.0.0.1,alice" > logs/part_2.csv`
Now, let’s see how you can use the connector in order to read the content of this directory into a table:
`class InputSchema(pw.Schema): ip: str login: str t = pw.io.fs.read("logs/", format="csv", schema=InputSchema)`
The only difference is that you specified the name of the directory instead of the file name, as opposed to what you had done in the previous example. It’s that simple!
Alternatively, we can do the same for the `"json"` variant:
The dataset creation would look as follows:
`mkdir logs printf "{\"id\":1,\"ip\":\"127.0.0.1\",\"login\":\"alice\"} {\"id\":2,\"ip\":\"8.8.8.8\",\"login\":\"alice\"}" > logs/part_1.jsonlines printf "{\"id\":3,\"ip\":\"8.8.8.8\",\"login\":\"bob\"} {\"id\":4,\"ip\":\"127.0.0.1\",\"login\":\"alice\"}" > logs/part_2.jsonlines`
While reading the data from logs folder can be expressed as:
`t = pw.io.fs.read("logs/", format="json", schema=InputSchema, mode="static")`
But what if you are working with a real-time system, which generates logs all the time. The logs are being written and after a while they get into the log directory (this is also called “logs rotation”). Now, consider that there is a need to fetch the new files from this logs directory all the time. Would the Pathway Live Data Framework handle that? Sure!
The only difference would be in the usage of `mode` field. So the code snippet will look as follows:
`t = pw.io.fs.read("logs/", format="csv", schema=InputSchema, mode="streaming")`
Or, for the `"json"` format case:
`t = pw.io.fs.read("logs/", format="json", schema=InputSchema, mode="streaming")`
With this method, you obtain a table updated dynamically. The changes in the logs would incur changes in the Business-Intelligence ‘BI’-ready data, namely, in the tables you would like to output. Finally, a simple example for the plaintext format would look as follows:
`t = pw.io.fs.read("raw_dataset/lines.txt", format="plaintext")`
[**write**(table, filename, format, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/fs#pathway.io.fs.write)
----------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/fs/__init__.py#L272-L382)
Writes `table`’s stream of updates to a file in the given format.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **filename** (`str` | `PathLike`) – Path to the target output file.
* **format** (`Literal`\[`'json'`, `'csv'`\]) – Format to use for data output. Currently, there are two supported formats: `"json"` and `"csv"`.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
In this simple example you can see how table output works. First, import Pathway Live Data Framework and create a table:
`import pathway as pw t = pw.debug.table_from_markdown("age owner pet \n1 10 Alice dog \n2 9 Bob cat \n3 8 Alice cat")`
Consider you would want to output the stream of changes of this table in `"csv"` format. In order to do that you simply do:
`pw.io.fs.write(t, "table.csv", format="csv")`
Now, let’s see what you have on the output:
`cat table.csv`
`age,owner,pet,time,diff 10,"Alice","dog",0,1 9,"Bob","cat",0,1 8,"Alice","cat",0,1`
The first three columns clearly represent the data columns you have. The column `time` represents the number of operations minibatch, in which each of the rows was read. In this example, since the data is static: you have `0`. The `diff` is another element of this stream of updates. In this context, it is `1` because all three rows were read from the input. All in all, the extra information in `time` and `diff` columns - in this case - shows us that in the initial minibatch (`time = 0`), you have read three rows and all of them were added to the collection (`diff = 1`).
Alternatively, this data can be written in `"json"` format:
`pw.io.fs.write(t, "table.jsonlines", format="json")`
Then, we can also check the output file by executing the command:
`cat table.jsonlines`
`{"age":10,"owner":"Alice","pet":"dog","diff":1,"time":0} {"age":9,"owner":"Bob","pet":"cat","diff":1,"time":0} {"age":8,"owner":"Alice","pet":"cat","diff":1,"time":0}`
As one can easily see, the values remain the same, while the format has changed to a plain JSON.
[Pathway Io\
\
pw.io.elasticsearch](https://pathway.com/developers/api-docs/pathway-io/elasticsearch)
[Pathway Io\
\
pw.io.gdrive](https://pathway.com/developers/api-docs/pathway-io/gdrive)
---
# pw.io.elasticsearch | Pathway
pw.io.elasticsearch
===================
**This module is available when using one of the following licenses only:** [Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise](https://pathway.com/pricing)
.
The Pathway Live Data Framework provides both **Input** and **Output** connectors for Elasticsearch. See the `read` and `write` documentation below for the modes, requirements, and options specific to each.
Both connectors exchange documents as JSON: the output connector serializes each row into a JSON document, and the input connector parses each document’s `_source` back into Live Data Framework values according to your `pw.Schema`. The type conversions below therefore apply to both directions, and every type produced by the output connector round-trips back through the input connector when the original schema type is specified.
[Type Conversion](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#type-conversion)
----------------------------------------------------------------------------------------------------
### [Pathway types serialization into JSON documents](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway-types-serialization-into-json-documents)
| Live Data Framework type | JSON type |
| --- | --- |
| `bool` | `boolean` |
| `int` | `number` |
| `float` | `number` |
| `pointer` | `string`, can be deserialized back if `pw.Pointer` type is specified in Live Data Framework table schema |
| `str` | `string` |
| `bytes` | `string`, containing base64-encoded binary data |
| `Naive DateTime` | `string`, containing the datetime in ISO-8601 format |
| `UTC DateTime` | `string`, containing the datetime in ISO-8601 format |
| `Duration` | `number`, serialized and deserialized with nanosecond precision |
| `JSON` | `object`, containing the JSON value |
| `np.ndarray` | `object` type with two top-level fields: an integer array `shape` containing the shape of the array, and an array `elements` containing the flattened elements of the array |
| `tuple` | `array`, the order of the elements corresponds to their appearance in the tuple |
| `list` | `array` |
| `pw.PyObjectWrapper` | `string`, can be deserialized back if the `pw.PyObjectWrapper` type is specified in Live Data Framework table schema |
The input connector additionally relies on two of these columns to drive its polling: `timestamp_column` must be a numeric (`number`) field — for example, epoch milliseconds — because the connector orders and watermarks documents by it, and `id_column` must be a unique, sortable field (a `keyword` or numeric mapping) because it is used both to deduplicate the polling overlap window and as the Live Data Framework row key. At startup the connector inspects the index mapping and logs a warning if either column is mapped in a way it cannot use (for example an `id_column` dynamically mapped as `text`, which Elasticsearch cannot sort by — use its `.keyword` sub-field instead).
[When the input connector is a good fit](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#when-the-input-connector-is-a-good-fit)
--------------------------------------------------------------------------------------------------------------------------------------------------
Elasticsearch exposes no change-data-capture API, so the input connector ingests by **polling**: it repeatedly queries a sliding window of the most recent documents and reconciles the overlap between consecutive queries so that no document is missed and none is delivered twice. This approach is **append-only** and rests on a few assumptions — check them before relying on it.
It is a good fit when:
* **The index is append-only.** Documents are added, not updated in place or deleted (or such changes need not reach Pathway). The connector deduplicates by `id_column`, so a document re-indexed under the same id is treated as already-seen and is _not_ re-delivered, and a deletion is never observed. To capture updates or deletes, use a change-data-capture source instead — polling cannot see them.
* **\`\`timestamp\_column\`\` is a trustworthy, non-decreasing clock** that advances as documents are indexed. A single document with a timestamp far in the future (for example from a clock-skewed producer) pushes the connector’s watermark past all normal documents and silently drops everything indexed afterwards, so guard against out-of-range timestamps upstream.
* **Each \`\`id\_column\`\` value is unique and unambiguous.** Two different documents whose ids reduce to the same string (e.g. the number `1` in one document and the string `"1"` in another) are treated as one, and one of them is dropped.
* **The number of documents written within any \`\`max\_transaction\_duration\`\` window is modest** (thousands, not millions). The connector keeps that many documents in memory for deduplication and re-reads them on each poll.
* **Documents spread out over time** — the time span of live data is larger than `max_transaction_duration`. If every document falls within a single `max_transaction_duration` window (for example a one-shot bulk load whose timestamps are all close together), nothing ever settles: the deduplication set and the persisted offset grow to the size of the whole load, and the window is re-read in full on every poll.
It is **not** a good fit when you need to capture updates or deletes, when `timestamp_column` is missing, non-numeric, or can move backwards / jump arbitrarily, or when a single `timestamp_column` value can hold more documents than fit comfortably in memory (the connector reads all documents sharing one timestamp as a single batch).
[Tuning the polling parameters](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#tuning-the-polling-parameters)
--------------------------------------------------------------------------------------------------------------------------------
* `max_transaction_duration` should be the real upper bound on how late a document may become visible relative to the newest one. Too small risks missing a genuinely late document; too large only widens the re-read window — it costs memory and read traffic but is never unsafe.
* `read_batch_size` should comfortably exceed the number of documents in one `max_transaction_duration` window. Correctness does not depend on it, but a larger value lets each poll read the window in a single request.
* `poll_interval` trades latency against load: each in-window document is re-read on every poll until it settles, so the read amplification on Elasticsearch is roughly `max_transaction_duration / poll_interval`. A longer interval reduces load at the cost of higher delivery latency.
[class **ElasticSearchAuth**(engine\_es\_auth)](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway.io.elasticsearch.ElasticSearchAuth)
-------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/elasticsearch/__init__.py#L24-L92)
Elasticsearch authentication object to be used in the `write` method.
### [classmethod **apikey**(apikey\_id, apikey)](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway.io.elasticsearch.ElasticSearchAuth.apikey)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/elasticsearch/__init__.py#L32-L50)
Constructs API key-based Elasticsearch authorization.
* **Parameters**
* **apikey\_id** – The ID of the API key.
* **apikey** – The API key.
* **Returns**
An authentication object to use for Elasticsearch authorization.
### [classmethod **basic**(username, password)](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway.io.elasticsearch.ElasticSearchAuth.basic)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/elasticsearch/__init__.py#L52-L70)
Constructs basic Elasticsearch authorization using a username and password.
* **Parameters**
* **username** – The username to use for authentication.
* **password** – The password for the specified user.
* **Returns**
An authentication object to use for Elasticsearch authorization.
### [classmethod **bearer**(bearer)](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway.io.elasticsearch.ElasticSearchAuth.bearer)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/elasticsearch/__init__.py#L72-L88)
Constructs Elasticsearch authorization using the specified bearer token.
* **Parameters**
**bearer** – The bearer token.
* **Returns**
An authentication object to use for Elasticsearch authorization.
[**read**(host, auth, index\_name, schema, \*, timestamp\_column, id\_column, max\_transaction\_duration, mode='streaming', poll\_interval=datetime.timedelta(seconds=1), read\_batch\_size=10000, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None)](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway.io.elasticsearch.read)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/elasticsearch/__init__.py#L188-L374)
Reads an index from Elasticsearch into a Pathway Live Data Framework table.
Elasticsearch exposes no change-data-capture (CDC) API, so this connector ingests incrementally by _polling_: it repeatedly queries the index for rows at or after a watermark and reconciles the overlap between consecutive queries so that no row is missed and no row is delivered twice. The reconciliation is driven by two columns that the index must contain:
* `timestamp_column` — a numeric field (e.g. epoch milliseconds) recording when a row was indexed. The connector orders and watermarks rows by this value, so it must be a sortable integer field, not a date string.
* `id_column` — a unique, sortable identifier (a `keyword` or numeric field). It is used both to deduplicate rows seen in the overlap window and as the Pathway Live Data Framework row key.
This is an **append-only** mechanism: it ingests new documents, but does not observe in-place updates or deletes (a document re-indexed under the same `id_column` is treated as already-seen and is not re-delivered). It also assumes `timestamp_column` is trustworthy and non-decreasing — a single document timestamped far in the future pushes the watermark past all normal documents and silently drops everything indexed afterwards. See the connector documentation for the full list of cases this mechanism fits, the cases it does not, and how to tune the parameters below.
The third polling parameter, `max_transaction_duration`, is the largest amount of time within which a concurrent writer may still commit a row whose `timestamp_column` is older than the current watermark (i.e. the maximum clock skew / transaction duration to tolerate). The connector keeps re-reading rows newer than `now - max_transaction_duration` until they settle, guaranteeing that a slow-to-commit row is never skipped. Set it conservatively: too small a value can miss rows committed late, while too large a value only widens the re-read window and costs a little extra work.
When persistence is enabled, the connector saves the watermark together with the set of ids still inside the overlap window as its offset. On restart it resumes from that state and delivers only the rows that arrived since the last checkpoint, deduplicating anything that was already emitted. The `name` parameter is required when using persistence so the engine can match the connector to its saved state.
* **Parameters**
* **host** (`str`) – The host and port on which the Elasticsearch server works, e.g. `"http://localhost:9200"`.
* **auth** ([`ElasticSearchAuth`](https://pathway.com/developers/api-docs/pathway-io-elasticsearch#pathway.io.elasticsearch.ElasticSearchAuth)
) – Credentials for Elasticsearch authorization.
* **index\_name** (`str`) – The name of the index to read from.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table. Column names must match the field names in the Elasticsearch documents. Both `timestamp_column` and `id_column` must be present. Do not declare a primary key in the schema — the connector keys the table by `id_column`.
* **timestamp\_column** (`str`) – Name of the numeric column recording when each row was written or last updated. Used to order and watermark the polled rows.
* **id\_column** (`str`) – Name of the unique, sortable identifier column. Used to deduplicate the overlap window and as the Pathway Live Data Framework row key.
* **max\_transaction\_duration** (`int` | `float` | `timedelta`) – Maximum time within which a concurrent writer may still commit a row with a timestamp older than the current watermark. Given as a number of seconds or a `datetime.timedelta` / `pw.Duration`.
* **mode** (`Literal`\[`'static'`, `'streaming'`\]) – If set to `"streaming"` (the default), the connector keeps polling for new rows. If set to `"static"`, it reads the index once and terminates.
* **poll\_interval** (`int` | `float` | `timedelta`) – How long to wait between two consecutive polls in streaming mode. Given as a number of seconds or a `datetime.timedelta` / `pw.Duration`.
* **read\_batch\_size** (`int`) – Maximum number of documents fetched per query. The connector pages through the index in blocks of this size — each block becomes one minibatch — instead of pulling the whole index at once, which bounds memory on a cold start over a large index. If a single `timestamp_column` value holds more rows than this, the connector transparently enlarges the query until that timestamp is fully read, so the value is a throughput/latency knob, not a correctness one; it must be positive.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every `autocommit_duration_ms` milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards, and as the name for the persisted snapshot.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes.
* **debug\_data** (`Any`) – Static data replacing the original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Consider an Elasticsearch instance running locally on port `9200` with an index `"logs"` whose documents carry an integer `ts` field (epoch milliseconds) and a unique `doc_id` field:
`import datetime import pathway as pw class LogSchema(pw.Schema): doc_id: str ts: int message: str table = pw.io.elasticsearch.read( host="http://localhost:9200", auth=pw.io.elasticsearch.ElasticSearchAuth.basic("admin", "admin"), index_name="logs", schema=LogSchema, timestamp_column="ts", id_column="doc_id", max_transaction_duration=datetime.timedelta(minutes=5), )`
[**write**(table, host, auth, index\_name, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/elasticsearch#pathway.io.elasticsearch.write)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/elasticsearch/__init__.py#L95-L185)
Write a table to a given index in ElasticSearch.
The rows of the table are serialized into JSON. Type conversions are the same as in the [JSON output connector](https://pathway.com/developers/api-docs/pathway-io/jsonlines)
.
Note that two additional fields are included in the generated JSON: `time`, which indicates the time of the Pathway Live Data Framework minibatch, and `diff`, which can be either `1` (row addition) or `-1` (row deletion).
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the table to output.
* **host** (`str`) – the host and port, on which Elasticsearch server works.
* **auth** ([`ElasticSearchAuth`](https://pathway.com/developers/api-docs/pathway-io-elasticsearch#pathway.io.elasticsearch.ElasticSearchAuth)
) – credentials for Elasticsearch authorization.
* **index\_name** (`str`) – name of the index, which gets the docs.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
Consider there is an instance of Elasticsearch, running locally on a port `9200`. There we have an index `"animals"`, containing an information about pets and their owners.
For the sake of simplicity we will also consider that the cluster has a simple username-password authentication having both username and password equal to `"admin"`.
Now suppose we want to send a Pathway Live Data Framework table pets to this local instance of Elasticsearch.
`import pathway as pw pets = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | cat 8 | Alice | cat ''')`
It can be done as follows:
`pw.io.elasticsearch.write( table=pets, host="http://localhost:9200", auth=pw.io.elasticsearch.ElasticSearchAuth.basic("admin", "admin"), index_name="animals", )`
All the updates of table `"pets"` will be indexed to `"animals"` as well.
[Pathway Io\
\
pw.io.dynamodb](https://pathway.com/developers/api-docs/pathway-io/dynamodb)
[Pathway Io\
\
pw.io.fs](https://pathway.com/developers/api-docs/pathway-io/fs)
---
# pw.io.rabbitmq | Pathway
pw.io.rabbitmq
==============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
[Performance](https://pathway.com/developers/api-docs/pathway-io/rabbitmq#performance)
---------------------------------------------------------------------------------------
The output connector publishes over the RabbitMQ **Stream** protocol and is multi-threaded, so the publish stream parallelizes across Pathway workers: each worker publishes in parallel. Combined with the parallelized filesystem reader, the whole read-plus-write pipeline scales with the worker count.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and publishing every row as one JSON message to a RabbitMQ stream — so they reflect **Pathway + the input source + RabbitMQ together, out of the box**, not RabbitMQ’s standalone ingestion ceiling. RabbitMQ streams persist to disk, so this is a durable publish rate.
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the RabbitMQ data directory. RabbitMQ ran as the stock `rabbitmq:4-management` Docker image with the `rabbitmq_stream` plugin enabled, at its default configuration. The Pathway and RabbitMQ containers were each pinned to their own core-complex die (6 cores with a private 32 MiB L3).
**Throughput.** End-to-end wall-clock time to read a 20 M-row, 64-shard CSV dataset (**≈ 0.93 GB**) and publish every row to a RabbitMQ stream, swept over the number of Pathway workers (median of 3 runs):
### [RabbitMQ stream publish throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/rabbitmq#rabbitmq-stream-publish-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 41.7 s | ≈ 479 400 rows/s | 1.00× |
| 2 | 35.3 s | ≈ 566 700 rows/s | 1.18× |
| 4 | 21.5 s | ≈ 930 700 rows/s | 1.94× |
| 8 | 19.8 s | ≈ 1 010 600 rows/s | 2.11× |
Throughput scales monotonically across the whole sweep, reaching **~1 M rows/s** on 8 workers (2.11×), and every run committed exactly the expected number of messages to the stream.
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/rabbitmq-bulk-write)
.
[**read**(uri, stream\_name, \*, schema=None, format='raw', mode='streaming', autocommit\_duration\_ms=1500, json\_field\_paths=None, with\_metadata=False, start\_from='beginning', start\_from\_timestamp\_ms=None, name=None, max\_backlog\_size=None, tls\_settings=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/rabbitmq#pathway.io.rabbitmq.read)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/rabbitmq/__init__.py#L25-L246)
Reads data from a [RabbitMQ](https://www.rabbitmq.com/docs/streams)
stream.
This connector supports plain RabbitMQ Streams. Super Streams (partitioned streams) are not supported in the current version.
There are three formats supported: `"plaintext"`, `"raw"`, and `"json"`.
For the `"raw"` format, the payload is read as raw bytes and added directly to the table. In the `"plaintext"` format, the payload is decoded from UTF-8 and stored as plain text. In both cases, the table will have a `"data"` column representing the payload.
If `"json"` is chosen, the connector parses the message payload as JSON and creates table columns based on the schema provided in the `schema` parameter.
**Application properties (headers).** When `with_metadata=True`, the `_metadata` column includes `application_properties` — a dict of all AMQP 1.0 application properties set by the writer. This is consistent with how `pw.io.kafka.read()` exposes Kafka headers in `_metadata`.
**Persistence.** When persistence is enabled, the connector saves the current stream offset (a single integer) to the snapshot. On restart, it resumes from the saved offset, so already-processed messages are not re-read.
* **Parameters**
* **uri** (`str`) – The URI of the RabbitMQ server with Streams enabled, e.g. `"rabbitmq-stream://guest:guest@localhost:5552"`.
* **stream\_name** (`str`) – The name of the RabbitMQ stream to read data from. The stream must already exist on the server.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – The table schema, used only when the format is set to `"json"`.
* **format** (`Literal`\[`'plaintext'`, `'raw'`, `'json'`\]) – The input data format, which can be `"raw"`, `"plaintext"`, or `"json"`.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – The reading mode, which can be `"streaming"` or `"static"`. In `"streaming"` mode, the connector reads messages continuously. In `"static"` mode, it reads all existing messages and then stops.
* **autocommit\_duration\_ms** (`int` | `None`) – The time interval (in milliseconds) between commits. After this time, the updates received by the connector are committed and added to Pathway Live Data Framework’s computation graph.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – For the `"json"` format, this allows mapping field names to paths within the JSON structure. Use the format `: ` where the path follows the [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **with\_metadata** (`bool`) – If `True`, adds a `_metadata` column containing a JSON dict with `offset`, `stream_name`, AMQP 1.0 message properties when available (`message_id`, `correlation_id`, `content_type`, `content_encoding`, `subject`, `reply_to`, `priority`, `durable`), and `application_properties` — a dict of string key-value pairs containing the AMQP application properties set by the writer. Values produced by [`write()`](https://pathway.com/developers/api-docs/pathway-io-rabbitmq#pathway.io.rabbitmq.write)
are JSON-encoded strings (see `headers` parameter of [`write()`](https://pathway.com/developers/api-docs/pathway-io-rabbitmq#pathway.io.rabbitmq.write)
), so they can be parsed back with `json.loads`.
* **start\_from** (`Literal`\[`'beginning'`, `'end'`, `'timestamp'`\]) – Where to start reading from. `"beginning"` starts from the first message in the stream. `"end"` skips all existing messages and only reads new ones arriving after the reader starts. `"timestamp"` starts from messages at or after the time given in `start_from_timestamp_ms`.
* **start\_from\_timestamp\_ms** (`int` | `None`) – Timestamp in milliseconds since epoch. Required when `start_from="timestamp"`, must not be set otherwise.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment.
* **tls\_settings** ([`TLSSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.TLSSettings)
| `None`) – TLS connection settings. Use `TLSSettings` to configure root certificates, client certificates, and verification mode.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Read messages in raw format (the default). The table will have `key` and `data` columns:
`import pathway as pw table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", )`
Read messages as UTF-8 plaintext:
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", format="plaintext", )`
Read and parse JSON messages with a schema:
`class InputSchema(pw.Schema): owner: str pet: str`
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", format="json", schema=InputSchema, )`
Extract nested JSON fields using JSON Pointer paths:
`class InputSchema(pw.Schema): name: str age: int`
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", format="json", schema=InputSchema, json_field_paths={"name": "/user/name", "age": "/user/age"}, )`
Read in static mode (bounded snapshot):
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", mode="static", )`
Read only new messages, ignoring all existing data in the stream:
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", start_from="end", )`
Read with persistence enabled, so progress is saved across restarts:
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", format="json", schema=InputSchema, name="my-rabbitmq-source", ) # Then run with persistence: # pw.run(persistence_config=pw.persistence.Config( # pw.persistence.Backend.filesystem("./PStorage") # ))`
Read with metadata column:
`table = pw.io.rabbitmq.read( "rabbitmq-stream://guest:guest@localhost:5552", "events", with_metadata=True, )`
[**write**(table, uri, stream\_name, \*, format='json', value=None, headers=None, name=None, sort\_by=None, tls\_settings=None)](https://pathway.com/developers/api-docs/pathway-io/rabbitmq#pathway.io.rabbitmq.write)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/rabbitmq/__init__.py#L249-L387)
Writes data into the specified RabbitMQ stream.
The produced messages consist of the payload, corresponding to the values of the table that are serialized according to the chosen format. Two AMQP 1.0 application properties are always added: `pathway_time` (processing time) and `pathway_diff` (either `1` or `-1`). If `headers` parameter is used, additional properties can be added to the message.
There are several serialization formats supported: `"json"`, `"plaintext"` and `"raw"`.
If the selected format is either `"plaintext"` or `"raw"`, you also need to specify which column of the table corresponds to the payload of the produced message. It can be done by providing the `value` parameter.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table for output.
* **uri** (`str`) – The URI of the RabbitMQ server with Streams enabled, e.g. `"rabbitmq-stream://guest:guest@localhost:5552"`.
* **stream\_name** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The RabbitMQ stream where data will be written. The stream must already exist on the server. Can be a column reference for dynamic routing — each row will be written to the stream named by that column’s value. All target streams must be pre-created.
* **format** (`Literal`\[`'json'`, `'plaintext'`, `'raw'`\]) – Format in which the data is put into RabbitMQ. Currently `"json"`, `"plaintext"` and `"raw"` are supported.
* **value** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Reference to the column that should be used as a payload in the produced message in `"plaintext"` or `"raw"` format.
* **headers** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – References to the table fields that must be provided as AMQP 1.0 application properties (analogous to Kafka headers). Values are serialized as AMQP strings using their JSON representation, following the same encoding as `pw.io.jsonlines.write()` (e.g. `42` for an int, `""hello""` for a string, `null` for None, base64-encoded string for bytes). RabbitMQ Streams does not reliably confirm messages with non-string application property values, so all types are JSON-encoded. On the reader side, header values are available in `_metadata.application_properties` (when `with_metadata=True`).
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch.
* **tls\_settings** ([`TLSSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.TLSSettings)
| `None`) – TLS connection settings. Use `TLSSettings` to configure root certificates, client certificates, and verification mode.
Examples:
Consider a RabbitMQ server with Streams enabled running locally on port `5552`. First, create a Pathway Live Data Framework table:
`import pathway as pw table = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | cat 8 | Alice | cat ''')`
Write the table in JSON format. Each row is serialized as a JSON object:
`pw.io.rabbitmq.write( table, "rabbitmq-stream://guest:guest@localhost:5552", "events", format="json", )`
Use the `"plaintext"` format to send a single column as the message payload. When the table has more than one column, you must specify which column to use via the `value` parameter. Additional columns can be forwarded as AMQP application properties using the `headers` parameter:
`pw.io.rabbitmq.write( table, "rabbitmq-stream://guest:guest@localhost:5552", "events", format="plaintext", value=table.owner, headers=[table.age, table.pet], )`
Write each row to a different stream based on a column value (dynamic topics). All target streams must already exist on the server:
`table_with_targets = pw.debug.table_from_markdown(''' value | target_stream hello | stream-a world | stream-b ''') pw.io.rabbitmq.write( table_with_targets, "rabbitmq-stream://guest:guest@localhost:5552", table_with_targets.target_stream, format="json", )`
[Pathway Io\
\
pw.io.questdb](https://pathway.com/developers/api-docs/pathway-io/questdb)
[Pathway Io\
\
pw.io.redpanda](https://pathway.com/developers/api-docs/pathway-io/redpanda)
---
# pw.io.clickhouse | Pathway
pw.io.clickhouse
================
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
The table below explains how each Pathway Live Data Framework type is stored in ClickHouse. Optional columns are stored as the `Nullable` wrapper of the type below, except `bytes`, which is always stored as `Nullable(String)`. The array-like types (`list`, `tuple` and `np.ndarray`) are supported in specific forms only, described in the table; because ClickHouse arrays cannot be wrapped in `Nullable`, an optional array-like column is not supported. For the full list of ClickHouse types you can refer to the [official documentation](https://clickhouse.com/docs/en/sql-reference/data-types)
.
[Pathway Live Data Framework types serialization into ClickHouse](https://pathway.com/developers/api-docs/pathway-io/clickhouse#pathway-live-data-framework-types-serialization-into-clickhouse)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
| Framework’s type | ClickHouse type |
| --- | --- |
| `bool` | `Bool` |
| `int` | `Int64` |
| `float` | `Float64` |
| `pointer` | `String` |
| `str` | `String` |
| `bytes` | `Nullable(String)`, containing the raw binary data |
| `Naive DateTime` | `DateTime64(9, 'UTC')`, the UTC timezone is used when passing the value to ClickHouse |
| `UTC DateTime` | `DateTime64(9, 'UTC')` |
| `Duration` | `Int64`, serialized and deserialized with nanosecond precision |
| `JSON` | `String`, containing the serialized JSON value |
| `pw.PyObjectWrapper` | `String`, containing base64-encoded serialized encoder. This value can be deserialized back, if read by other Pathway Live Data Framework connector |
| `list[T]` | `Array()`, where `T` is one of `bool`, `int`, `float`, `str`, `pointer`, `JSON`, `Duration` or `pw.PyObjectWrapper`; each element is stored exactly as that scalar type is stored on its own. Datetime elements (`list[Naive DateTime]` / `list[UTC DateTime]`) are not supported because the array column would only keep second precision. Only one level of nesting is supported: a list whose element type is itself a list, an optional, or `bytes` (i.e. `list[list[...]]`, `list[T \| None]`, `list[bytes]`) is not supported either. All of these unsupported cases are rejected when the computation starts |
| `tuple` | a fixed-length tuple whose elements are **all the same** supported scalar type (one of `bool`, `int`, `float`, `str`, `pointer`, `JSON`, `Duration` or `pw.PyObjectWrapper`) — for example `tuple[float, float, float]` — is stored as `Array()` exactly like a `list[T]` (the tuple length is not preserved, because a ClickHouse `Array` is variable-length). A variable-length `tuple[T, ...]` is treated as a `list[T]`. A heterogeneous tuple (mixed element types, e.g. `tuple[int, str]`) would require a ClickHouse `Tuple`, which the connector does not support; it, and tuples of an unsupported element type, are rejected when the computation starts |
| `np.ndarray` | a **one-dimensional**, element-typed `int` or `float` array (e.g. `np.ndarray[tuple[int], np.dtype[np.float64]]`) is stored as `Array(Int64)` / `Array(Float64)`, which ClickHouse vector functions such as `cosineDistance` and `L2Distance` can operate on. Multi-dimensional arrays, arrays of unknown dimensionality (a bare `np.ndarray`), and other element types are not supported and are rejected when the computation starts |
[Performance](https://pathway.com/developers/api-docs/pathway-io/clickhouse#performance)
-----------------------------------------------------------------------------------------
The ClickHouse connector writes over ClickHouse’s native protocol and is multi-threaded, so the write stream parallelizes across Pathway workers. Combined with the parallelized filesystem reader, the whole read-plus-write pipeline scales with the worker count.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and writing every row to ClickHouse over the native protocol — so they reflect **Pathway + the input source + ClickHouse together, out of the box**, not ClickHouse’s standalone ingestion ceiling (which is considerably higher with a tuned configuration).
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the ClickHouse data directory. ClickHouse ran at its default, untuned configuration. The Pathway and ClickHouse containers were each pinned to their own core-complex die (6 cores with a private 32 MiB L3).
**Throughput.** End-to-end wall-clock time to read a 20 M-row, 64-shard CSV dataset (**≈ 0.93 GB**) and land every row in ClickHouse, swept over the number of Pathway workers (median of 3 runs):
### [ClickHouse write throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/clickhouse#clickhouse-write-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 29.2 s | ≈ 685 000 rows/s | 1.00× |
| 2 | 27.4 s | ≈ 731 000 rows/s | 1.07× |
| 4 | 16.6 s | ≈ 1 206 000 rows/s | 1.76× |
| 8 | 12.4 s | ≈ 1 619 000 rows/s | 2.36× |
Throughput scales with the worker count, peaking at **~1.6 M rows/s** on 8 workers, and every run passed the data-integrity checks. A tuned ClickHouse configuration would push the ceiling higher still.
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/clickhouse-bulk-write)
.
[**write**(table, \*, connection\_string, table\_name, output\_table\_type='stream\_of\_changes', primary\_key=None, init\_mode='default', max\_batch\_size=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/clickhouse#pathway.io.clickhouse.write)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/clickhouse/__init__.py#L17-L281)
Writes `table` to a ClickHouse table.
The output table supports two formats, controlled by `output_table_type`: a `"stream_of_changes"` format that appends the full history of updates, and a `"snapshot"` format that maintains the current state of the table.
In `"stream_of_changes"` mode (the default) the output includes every column of the input table plus two additional columns: `time`, which holds the Pathway Live Data Framework minibatch time of the change, and `diff`, which describes the type of change (`1` for a row insertion and `-1` for a row deletion). A row update is represented as a deletion of the old value followed by an insertion of the new one, both within the same minibatch. Because `time` and `diff` are reserved column names in this format, the input table must not contain columns with these names; otherwise a `ValueError` is raised at construction time. Each `pw.run()` invocation appends to the table; use `init_mode="replace"` to recreate it from scratch instead.
In `"snapshot"` mode the connector maintains the current state of the table rather than its history. ClickHouse is an insert-only, append-oriented store with no synchronous primary-key upsert or delete, so the current state is maintained with a [ReplacingMergeTree(version, is\_deleted)](https://clickhouse.com/docs/engines/table-engines/mergetree-family/replacingmergetree)
engine ordered by the `primary_key` columns, plus two bookkeeping columns the connector appends to every row:
* `version` — a 64-bit counter that increases by one with every change, in the order changes are produced. It is _not_ the minibatch `time` used in `"stream_of_changes"` mode; see below for why a separate counter is needed.
* `is_deleted` — `1` if the row is a retraction (deletion), `0` if it is a live state row. This is exactly the `diff` of `"stream_of_changes"` mode re-expressed as a flag (`diff = -1` becomes `is_deleted = 1`, `diff = 1` becomes `is_deleted = 0`).
Every Pathway change is just appended as a row (no in-place update). What turns that append-only stream into a live snapshot is how `ReplacingMergeTree` behaves at the ClickHouse level: when it merges data parts in the background, it collapses all rows that share the same `ORDER BY` key (here the `primary_key`) down to the single row with the **largest** `version`, and if that surviving row has `is_deleted = 1` it is physically dropped. Both columns are therefore required, and each does a specific job:
* `version` makes “the newest write wins” deterministic, and is the reason this mode needs a dedicated counter rather than reusing `time`. An update to a row is emitted as a retraction of the old value followed by an insertion of the new one — both with the same primary key _and the same_ minibatch `time` — so `time` cannot tell the engine which one is newer. `version` can: the connector assigns each change the next counter value in production order, emitting retractions before insertions within a minibatch, so the insertion always gets the higher `version` and the merge keeps the new values. (The counter only ever has to break ties between rows of the _same_ primary key; identical `version` values across different keys are irrelevant, since `ReplacingMergeTree` collapses each `ORDER BY` key independently.) Reusing `time` would give the retraction and the insertion an equal `version`, and `ReplacingMergeTree` breaks such ties arbitrarily — it could keep the retraction and silently drop the update.
* `is_deleted` lets a key be removed at all. Because only inserts are possible, a deletion is represented as an appended row with the highest `version` and `is_deleted = 1`; the merge then removes that key. Without it a deleted key could never leave the table.
Because merges run asynchronously, query the table with [SELECT … FINAL](https://clickhouse.com/docs/sql-reference/statements/select/from#final-modifier)
to observe the current, deduplicated state on demand — `FINAL` applies the same keep-largest-version / drop-`is_deleted` logic at query time. A plain `SELECT` (without `FINAL`) may still return superseded or deleted rows until a merge has run.
`version` and `is_deleted` are reserved column names in this format, so the input table must not contain columns with these names. This mode requires the `primary_key` parameter and runs on a single worker so that the `version` counter is globally monotonic; on start-up it is seeded above the table’s current maximum `version` so that a restart against an existing table keeps producing winning rows.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write to ClickHouse.
* **connection\_string** (`str`) – The connection string for the ClickHouse server, in the native-protocol form `"tcp://user:password@host:9000/database"`. Connection options such as `compression` may be appended as query parameters, e.g. `"tcp://localhost:9000/default?compression=lz4"`.
* **table\_name** (`str`) – The name of the target table in ClickHouse.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – Either `"stream_of_changes"` (the default), which appends the full history of changes with `time`/`diff` columns, or `"snapshot"`, which maintains the current state of the table in a `ReplacingMergeTree` keyed by `primary_key` (queried with `SELECT ... FINAL`).
* **primary\_key** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – The columns identifying each row. Required when `output_table_type="snapshot"` (they become the table’s `ORDER BY`); must not be set otherwise.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – Determines how the table is initialized before the first write. `"default"` (the default) does nothing and requires the table to already exist. `"create_if_not_exists"` creates the table if it is not present. `"replace"` drops the table if it exists and recreates it. In the two latter modes the table is created with the engine and metadata columns for the chosen `output_table_type`: a `MergeTree` with `time`/`diff` columns for `"stream_of_changes"`, or a `ReplacingMergeTree(version, is_deleted)` ordered by `primary_key` with `version`/`is_deleted` columns for `"snapshot"`. Regardless of `init_mode`, the connector validates the destination table when the computation starts: it must exist and contain every output column (the input columns plus the metadata columns) with a compatible type, and in `"snapshot"` mode it must use the `ReplacingMergeTree` engine. A missing table, an absent column, an incompatible column type, or a wrong engine is reported immediately rather than on the first write. ClickHouse inserts perform almost no implicit conversion, so a pre-existing column must have exactly the type the connector produces for it (a `String` column may also be `FixedString(N)`, and a datetime column may be any `DateTime`/`DateTime64` variant).
* **max\_batch\_size** (`int` | `None`) – The maximum number of changes to accumulate before sending an insertion block to the server.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output is sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples are compared lexicographically.
* **Returns**
None
Example:
The easiest way to run ClickHouse locally is with Docker. You can use the official image and start it like this:
`docker pull clickhouse/clickhouse-server docker run -d --name clickhouse \ -p 8123:8123 -p 9000:9000 \ clickhouse/clickhouse-server`
Port `9000` is used for the native protocol, which this connector relies on. Port `8123` exposes the HTTP interface, which is convenient for inspecting the data afterwards.
You can now write a simple program. In this example a table with one column called `"data"` is created and sent to the database:
`import pathway as pw table = pw.debug.table_from_markdown(''' | data 1 | Hello 2 | World ''')`
This table can now be written to ClickHouse. If the output table is called `"test"` and you want the connector to create it for you, the code looks like this:
`pw.io.clickhouse.write( table, connection_string="tcp://localhost:9000/default", table_name="test", init_mode="create_if_not_exists", )`
You can run this pipeline with `pw.run()`.
Once the program has finished, you can inspect the data with any ClickHouse client, for example over the HTTP interface:
`curl 'http://localhost:8123/?query=SELECT%20*%20FROM%20test'`
Note that if you run the program again it will append data to the table. To recreate the table from scratch, use `init_mode="replace"`.
If instead of the history of changes you want to maintain the current state of the table, use `output_table_type="snapshot"` and provide the column(s) that identify each row via `primary_key`:
`pets = pw.debug.table_from_markdown(''' | name | owner 1 | Cat | Alice 2 | Dog | Bob ''') pw.io.clickhouse.write( pets, connection_string="tcp://localhost:9000/default", table_name="pets", output_table_type="snapshot", primary_key=[pets.name], init_mode="create_if_not_exists", )`
Because the deduplication happens during background merges, query the snapshot with `FINAL` to always observe the current state:
`curl 'http://localhost:8123/?query=SELECT%20name,owner%20FROM%20pets%20FINAL'`
[Pathway Io\
\
pw.io.chroma](https://pathway.com/developers/api-docs/pathway-io/chroma)
[Pathway Io\
\
pw.io.csv](https://pathway.com/developers/api-docs/pathway-io/csv)
---
# pw.io.python | Pathway
pw.io.python
============
[class **AsyncConnectorObserver**](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.AsyncConnectorObserver)
---------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L736-L760)
An abstract class for creating custom Python async writers. At least `on_change` method must be implemented. Use with [`write()`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.write)
.
### [abstract async **on\_change**(key, row, time, is\_addition)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.AsyncConnectorObserver.on_change)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L742-L760)
Called on every change in the table. It is called on table entries in order of increasing processing time. For entries with the same processing time (the same batch) the method can be called in any order. The function must accept:
* **Parameters**
* **key** (`Pointer`) – the key of the changed row;
* **row** (`dict`\[`str`, `Any`\]) – the changed row as a dict mapping from the field name to the value;
* **time** (`int`) – the processing time of the modification, also can be referred as minibatch ID of the change;
* **is\_addition** (`bool`) – boolean value, equals to true if the row is inserted into the table, false otherwise. Please note that update is basically two operations: the deletion of the old value and the insertion of a new value, which happen within a single batch;
### [**on\_end**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.AsyncConnectorObserver.on_end)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L702-L706)
Called when the stream of changes ends.
### [**on\_time\_end**(time)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.AsyncConnectorObserver.on_time_end)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L693-L700)
Called when a processing time is closed.
* **Parameters**
**time** (`int`) – The finished processing time.
[class **ConnectorObserver**](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorObserver)
-----------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L709-L733)
An abstract class for creating custom Python writers. At least `on_change` method must be implemented. Use with [`write()`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.write)
.
### [abstract **on\_change**(key, row, time, is\_addition)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorObserver.on_change)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L715-L733)
Called on every change in the table. It is called on table entries in order of increasing processing time. For entries with the same processing time (the same batch) the method can be called in any order. The function must accept:
* **Parameters**
* **key** (`Pointer`) – the key of the changed row;
* **row** (`dict`\[`str`, `Any`\]) – the changed row as a dict mapping from the field name to the value;
* **time** (`int`) – the processing time of the modification, also can be referred as minibatch ID of the change;
* **is\_addition** (`bool`) – boolean value, equals to true if the row is inserted into the table, false otherwise. Please note that update is basically two operations: the deletion of the old value and the insertion of a new value, which happen within a single batch;
### [**on\_end**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorObserver.on_end)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L702-L706)
Called when the stream of changes ends.
### [**on\_time\_end**(time)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorObserver.on_time_end)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L693-L700)
Called when a processing time is closed.
* **Parameters**
**time** (`int`) – The finished processing time.
[class **ConnectorSubject**(datasource\_name='python')](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject)
------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L49-L328)
An abstract class allowing to create custom python input connectors. Use with [`read()`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.read)
.
Custom python connector can be created by extending this class and implementing `run()` function responsible for filling the buffer with data. This function will be started by pathway engine in a separate thread. When the `run()` function terminates, the connector will be considered finished and pathway won’t wait for new messages from it.
In order to send a message [`next()`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.ConnectorSubject.next)
method can be used.
If the subject won’t delete records, set the class property `deletions_enabled` to `False` as it may help to improve the performance.
**Note**: If the `read` method is called with this subject and `max_backlog_size` is set, many method calls may block when the number of events waiting to be processed reaches `max_backlog_size`. They will resume only after the queue size drops below the limit.
### [**close**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.close)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L207-L212)
Sends a sentinel message.
Should be called to indicate that no new messages will be sent.
### [**commit**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.commit)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L186-L188)
Sends a commit message.
### [**end**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.end)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L237-L245)
Joins a thread running `run()`.
Should not be called directly.
### [**next**(\*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.next)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L115-L143)
Sends a message to the engine.
The arguments should be compatible with the schema passed to [`read()`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.read)
. Values for all fields should be passed to this method unless they have a default value specified in the schema.
Example:
`import pathway as pw import pandas as pd class InputSchema(pw.Schema): a: pw.DateTimeNaive b: bytes c: int class InputSubject(pw.io.python.ConnectorSubject): def run(self): self.next(a=pd.Timestamp("2021-03-21T18:34:12"), b="abc".encode(), c=3) self.next(a=pd.Timestamp("2022-04-01T11:12:12"), b="def".encode(), c=42) t = pw.io.python.read(InputSubject(), schema=InputSchema) pw.debug.compute_and_print(t, include_id=False)`
Code Results
### [**next\_bytes**(message)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.next_bytes)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L173-L184)
Sends a message.
* **Parameters**
**message** (`bytes`) – a message represented as bytes.
### [**next\_json**(message)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.next_json)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L145-L158)
Sends a message.
* **Parameters**
**message** (`dict`) – Dict representing json.
### [**next\_str**(message)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.next_str)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L160-L171)
Sends a message.
* **Parameters**
**message** (`str`) – a message represented as a string.
### [**on\_persisted\_run**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.on_persisted_run)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L98-L102)
This method is called by Rust core to notify that the state will be persisted in this run.
### [**on\_stop**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.on_stop)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L104-L106)
Called after the end of the `run()` function.
### [final **seek**(state)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.seek)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L88-L92)
Called by Rust core on start to resume reading from the last stopping point.
### [**start**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.ConnectorSubject.start)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L217-L235)
Runs a separate thread with function feeding data into buffer.
Should not be called directly.
[class **InteractiveCsvPlayer**(csv\_file='')](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer)
-------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L632-L689)
### [**close**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.close)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L207-L212)
Sends a sentinel message.
Should be called to indicate that no new messages will be sent.
### [**commit**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.commit)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L186-L188)
Sends a commit message.
### [**end**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.end)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L237-L245)
Joins a thread running `run()`.
Should not be called directly.
### [**next**(\*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.next)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L115-L143)
Sends a message to the engine.
The arguments should be compatible with the schema passed to [`read()`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.read)
. Values for all fields should be passed to this method unless they have a default value specified in the schema.
Example:
`import pathway as pw import pandas as pd class InputSchema(pw.Schema): a: pw.DateTimeNaive b: bytes c: int class InputSubject(pw.io.python.ConnectorSubject): def run(self): self.next(a=pd.Timestamp("2021-03-21T18:34:12"), b="abc".encode(), c=3) self.next(a=pd.Timestamp("2022-04-01T11:12:12"), b="def".encode(), c=42) t = pw.io.python.read(InputSubject(), schema=InputSchema) pw.debug.compute_and_print(t, include_id=False)`
Code Results
### [**next\_bytes**(message)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.next_bytes)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L173-L184)
Sends a message.
* **Parameters**
**message** (`bytes`) – a message represented as bytes.
### [**next\_json**(message)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.next_json)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L145-L158)
Sends a message.
* **Parameters**
**message** (`dict`) – Dict representing json.
### [**next\_str**(message)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.next_str)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L160-L171)
Sends a message.
* **Parameters**
**message** (`str`) – a message represented as a string.
### [**on\_persisted\_run**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.on_persisted_run)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L98-L102)
This method is called by Rust core to notify that the state will be persisted in this run.
### [**on\_stop**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.on_stop)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L688-L689)
Called after the end of the `run()` function.
### [**seek**(state)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.seek)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L88-L92)
Called by Rust core on start to resume reading from the last stopping point.
### [**start**()](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.InteractiveCsvPlayer.start)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L217-L235)
Runs a separate thread with function feeding data into buffer.
Should not be called directly.
[**read**(subject, \*, schema=None, format=None, autocommit\_duration\_ms=1500, debug\_data=None, name=None, max\_backlog\_size=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.read)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L519-L629)
Reads a table from a ConnectorSubject.
* **Parameters**
* **subject** ([`ConnectorSubject`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.ConnectorSubject)
) – An instance of a `ConnectorSubject`.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **format** (`Optional`\[`Literal`\[`'json'`, `'raw'`, `'binary'`\]\]) – Deprecated. Pass values of proper types to `subject`’s `next` instead. Format of the data produced by a subject, “json”, “raw” or “binary”. In case of a “raw”/”binary” format, table with single “data” column will be produced.
* **debug\_data** – Static data replacing original one when debug mode is active.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes. **Note**: The `next`, `next_json`, `next_str`, and `next_bytes` methods of `subject` will block when the internal queue holding events before they are sent to the processing reaches `max_backlog_size`. These methods will resume only when the queue size drops below this limit.
* **Returns**
_Table_ – The table read.
Example:
`import pathway as pw from pathway.io.python import ConnectorSubject class MySchema(pw.Schema): a: int b: str class MySubject(ConnectorSubject): def run(self) -> None: for i in range(4): self.next(a=i, b=f"x{i}") @property def _deletions_enabled(self) -> bool: return False s = MySubject() table = pw.io.python.read(s, schema=MySchema) pw.debug.compute_and_print(table, include_id=False)`
Code Results
[**write**(table, observer, \*, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/python#pathway.io.python.write)
----------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/python/__init__.py#L763-L822)
Writes stream of changes from a table to a Python observer.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write.
* **observer** ([`ConnectorObserver`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.ConnectorObserver)
| [`AsyncConnectorObserver`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.AsyncConnectorObserver)
) – An instance of a [`ConnectorObserver`](https://pathway.com/developers/api-docs/pathway-io-python#pathway.io.python.ConnectorObserver)
.
* **name** (`str` | `None`) – A unique name for the writer. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the writer’s progress.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
Example:
`import pathway as pw table = pw.debug.table_from_markdown(''' | pet | owner | age | __time__ | __diff__ 1 | dog | Alice | 10 | 0 | 1 2 | cat | Alice | 8 | 2 | 1 3 | dog | Bob | 7 | 4 | 1 2 | cat | Alice | 8 | 6 | -1 ''') class Observer(pw.io.python.ConnectorObserver): def on_change(self, key: pw.Pointer, row: dict, time: int, is_addition: bool): print(f"{row}, {time}, {is_addition}") def on_end(self): print("End of stream.") pw.io.python.write(table, Observer()) pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
Code Results
[Pathway Io\
\
pw.io.pyfilesystem](https://pathway.com/developers/api-docs/pathway-io/pyfilesystem)
[Pathway Io\
\
pw.io.qdrant](https://pathway.com/developers/api-docs/pathway-io/qdrant)
---
# pw.io.http | Pathway
pw.io.http
==========
[class **EndpointDocumentation**(\*, summary=None, description=None, tags=None, method\_types=None, examples=None)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.EndpointDocumentation)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L129-L304)
The settings for the automatic OpenAPI v3 docs generation for an endpoint.
* **Parameters**
* **summary** (`str` | `None`) – Short endpoint description shown as a hint in the endpoints list.
* **description** (`str` | `None`) – Comprehensive description for the endpoint.
* **tags** (`Optional`\[`Sequence`\[`str`\]\]) – Tags for grouping the endpoints.
* **method\_types** (`Optional`\[`Sequence`\[`str`\]\]) – If set, Pathway Live Data Framework will document only the given method types. This way, one can exclude certain endpoints and methods from being documented.
[class **EndpointExamples**](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.EndpointExamples)
-----------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L92-L126)
Examples for endpoint documentation.
### [**add\_example**(id, summary, values)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.EndpointExamples.add_example)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L100-L123)
Adds an example to the collection.
* **Parameters**
* **id** – Short and unique ID for the example. It is used for naming the example within the Open API schema. By using `default` as an ID, you can set the example default for the readers, while users will be able to select another ones via the dropdown menu.
* **summary** – Human-readable summary of the example, describing what is shown. It is shown in the automatically generated dropdown menu.
* **values** – The key-value dictionary, a mapping from the fields described in schema to their values in the example.
* **Returns**
_EndpointExamples_ – The current instance, allowing method chaining.
[class **PathwayWebserver**(host, port, with\_schema\_endpoint=True, with\_cors=False)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.PathwayWebserver)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L496-L665)
The basic configuration class for `pw.io.http.rest_connector`.
It contains essential information about the host and the port on which the webserver should run and accept queries.
* **Parameters**
* **host** – TCP/IP host or a sequence of hosts for the created endpoint.
* **port** – Port for the created endpoint.
* **with\_schema\_endpoint** – If set to `True`, the server will also provide `/_schema` endpoint containing Open API 3.0.3 schema for the handlers generated with `pw.io.http.rest_connector` calls.
* **with\_cors** – If set to `True`, the server will allow cross-origin requests on the added endpoints.
### [**openapi\_description**(origin)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.PathwayWebserver.openapi_description)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L661-L665)
Returns Open API description for the added set of endpoints in yaml format.
### [**openapi\_description\_json**(origin)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.PathwayWebserver.openapi_description_json)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L652-L659)
Returns Open API description for the added set of endpoints in JSON format.
[class **RetryPolicy**(first\_delay\_ms, backoff\_factor, jitter\_ms)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.RetryPolicy)
------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_common.py#L16-L56)
Represents a retry policy defining delays or backoff strategies for retries.
* **Parameters**
* **first\_delay\_ms** (`int`) – Duration of the initial retry delay, in milliseconds.
* **backoff\_factor** (`float`) – Factor by which the retry delay increases after each attempt.
* **jitter\_ms** (`int`) – Maximum random jitter (in milliseconds) to add to the scaled delay.
* **Returns**
A retry policy object.
### [classmethod **default**()](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.RetryPolicy.default)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_common.py#L34-L48)
Constructs the default retry settings:
* The initial delay between calls is 1 second.
* The backoff factor is 1.5, meaning each subsequent retry will wait at least 1.5 times longer than the previous one.
* The maximum jitter added to the delay is 300 milliseconds.
[**read**(url, \*, schema=None, method='GET', payload=None, headers=None, response\_mapper=None, format='json', delimiter=None, n\_retries=0, retry\_policy=, connect\_timeout\_ms=None, request\_timeout\_ms=None, allow\_redirects=True, retry\_codes=(429, 500, 502, 503, 504), autocommit\_duration\_ms=10000, debug\_data=None, name=None, max\_backlog\_size=None)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.read)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/__init__.py#L26-L146)
Reads a table from an HTTP stream.
* **Parameters**
* **url** (`str`) – the full URL of streaming endpoint to fetch data from.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table.
* **method** (`str`) – request method for streaming. It should be one of [HTTP request methods](https://developer.mozilla.org/en-US/docs/Web/HTTP/Methods)
.
* **payload** (`Any` | `None`) – data to be send in the body of the request.
* **headers** (`dict`\[`str`, `str`\] | `None`) – request headers in the form of dict. Wildcards are allowed both, in keys and in values.
* **response\_mapper** (`Callable`\[\[`str` | `bytes`\], `bytes`\] | `None`) – in case a response needs to be processed, this method can be provided. It will be applied to each slice of a stream.
* **format** (`Literal`\[`'json'`, `'raw'`\]) – format of the data, “json” or “raw”. In case of a “raw” format, table with single “data” column will be produced. For “json” format, bytes encoded json is expected.
* **delimiter** (`str` | `bytes` | `None`) – delimiter used to split stream into messages.
* **n\_retries** (`int`) – how many times to retry the failed request.
* **retry\_policy** ([`RetryPolicy`](https://pathway.com/developers/api-docs/pathway-io-http#pathway.io.http.RetryPolicy)
) – policy of delays or backoffs for the retries.
* **connect\_timeout\_ms** (`int` | `None`) – connection timeout, specified in milliseconds. In case it’s None, no restrictions on connection duration will be applied.
* **request\_timeout\_ms** (`int` | `None`) – request timeout, specified in milliseconds. In case it’s None, no restrictions on request duration will be applied.
* **allow\_redirects** (`bool`) – whether to allow redirects.
* **retry\_codes** (`tuple` | `None`) – HTTP status codes that trigger retries.
* **content\_type** – content type of the data to send. In case the chosen format is JSON, it will be defaulted to “application/json”.
* **autocommit\_duration\_ms** (`int`) – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **debug\_data** – static data replacing original one when debug mode is active.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
Examples:
Raw format:
`import os import pathway as pw table = pw.io.http.read( "https://localhost:8000/stream", method="GET", headers={"Authorization": f"Bearer {os.environ['BEARER_TOKEN']}"}, format="raw", )`
JSON with response mapper:
Input can be adjusted using a mapping function that will be applied to each slice of a stream. The mapping function should return bytes.
`def mapper(msg: bytes) -> bytes: result = json.loads(msg.decode()) return json.dumps({"key": result["id"], "text": result["data"]}).encode() class InputSchema(pw.Schema): key: int text: str t = pw.io.http.read( "https://localhost:8000/stream", method="GET", headers={"Authorization": f"Bearer {os.environ['BEARER_TOKEN']}"}, schema=InputSchema, response_mapper=mapper )`
[**rest\_connector**(host=None, port=None, \*, webserver=None, route='/', schema=None, methods=('POST', ), autocommit\_duration\_ms=1500, documentation=, keep\_queries=None, delete\_completed\_queries=None, request\_validator=None, cache\_strategy=None)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.rest_connector)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/_server.py#L722-L875)
Runs a lightweight HTTP server and inputs a collection from the HTTP endpoint, configured by the parameters of this method.
On the output, the method provides a table and a callable, which needs to accept the result table of the computation, which entries will be tracked and put into respective request’s responses.
* **Parameters**
* **webserver** ([`PathwayWebserver`](https://pathway.com/developers/api-docs/pathway-io-http#pathway.io.http.PathwayWebserver)
| `None`) – configuration object containing host and port information. You only need to create only one instance of this class per single host-port pair;
* **route** (`str`) – route which will be listened to by the web server;
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – schema of the resulting table;
* **methods** (`Sequence`\[`str`\]) – HTTP methods that this endpoint will accept;
* **autocommit\_duration\_ms** – the maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph;
* **keep\_queries** (`bool` | `None`) – whether to keep queries after processing; defaults to `False`. \[deprecated\]
* **delete\_completed\_queries** (`bool` | `None`) – whether to send a deletion entry after the query is processed. Allows to remove it from the system if it is stored by operators such as `join` or `groupby`;
* **request\_validator** (`Callable` | `None`) – a callable that can verify requests. A return value of `None` accepts payload. Any other returned value is treated as error and used as the response. Any exception is caught and treated as validation failure.
* **cache\_strategy** ([`CacheStrategy`](https://pathway.com/developers/api-docs/udfs#pathway.udfs.CacheStrategy)
| `None`) – one of available request caching strategies or None if no caching is required. If enabled, caches responses for the requests with the same `schema`\-defined payload.
* **Returns**
_tuple_ – A tuple containing two elements. The table read and a `response_writer`, a callable, where the result table should be provided. The `id` column of the result table must contain the primary keys of the objects from the input table and a `result` column, corresponding to the endpoint’s return value.
Example:
Let’s consider the following example: there is a collection of words that are received through HTTP REST endpoint `/uppercase` located at `127.0.0.1`, port `9999`. The Pathway Live Data Framework program processes this table by converting these words to the upper case. This conversion result must be provided to the user on the output.
Then, you can proceed with the following REST connector configuration code.
First, the schema and the webserver object need to be created:
`import pathway as pw class WordsSchema(pw.Schema): word: str webserver = pw.io.http.PathwayWebserver(host="127.0.0.1", port=9999)`
Then, the endpoint that inputs this collection can be configured:
`words, response_writer = pw.io.http.rest_connector( webserver=webserver, route="/uppercase", schema=WordsSchema, )`
Finally, you can define the logic that takes the input table `words`, calculates the result in the form of a table, and provides it for the endpoint’s output:
`uppercase_words = words.select( query_id=words.id, result=pw.apply(lambda x: x.upper(), pw.this.word) ) response_writer(uppercase_words)`
Please note that you don’t need to create another web server object if you need to have more than one endpoint running on the same host and port. For example, if you need to create another endpoint that converts words to lower case, in the same way, you need to reuse the existing `webserver` object. That is, the configuration would start with:
`words_for_lowercase, response_writer_for_lowercase = pw.io.http.rest_connector( webserver=webserver, route="/lowercase", schema=WordsSchema, )`
[**write**(table, url, \*, method='POST', format='json', request\_payload\_template=None, n\_retries=0, retry\_policy=, connect\_timeout\_ms=None, request\_timeout\_ms=None, content\_type=None, headers=None, allow\_redirects=True, retry\_codes=(429, 500, 502, 503, 504), name=None)](https://pathway.com/developers/api-docs/pathway-io/http#pathway.io.http.write)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/http/__init__.py#L149-L287)
Sends the stream of updates from the table to the specified HTTP API.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – table to be tracked.
* **method** (`str`) – request method for streaming. It should be one of [HTTP request methods](https://developer.mozilla.org/en-US/docs/Web/HTTP/Methods)
.
* **url** (`str`) – the full URL of the endpoint to push data into. Can contain wildcards.
* **format** (`Literal`\[`'json'`, `'custom'`\]) – the payload format, one of {“json”, “custom”}. If “json” is specified, the plain JSON will be formed and sent. Otherwise, the contents of the field request\_payload\_template will be used.
* **request\_payload\_template** (`str` | `None`) – the template to format and send in case “custom” was specified in the format field. Can include wildcards.
* **n\_retries** (`int`) – how many times to retry the failed request.
* **retry\_policy** ([`RetryPolicy`](https://pathway.com/developers/api-docs/pathway-io-http#pathway.io.http.RetryPolicy)
) – policy of delays or backoffs for the retries.
* **connect\_timeout\_ms** (`int` | `None`) – connection timeout, specified in milliseconds. In case it’s None, no restrictions on connection duration will be applied.
* **request\_timeout\_ms** (`int` | `None`) – request timeout, specified in milliseconds. In case it’s None, no restrictions on request duration will be applied.
* **allow\_redirects** (`bool`) – Whether to allow redirects.
* **retry\_codes** (`tuple` | `None`) – HTTP status codes that trigger retries.
* **content\_type** (`str` | `None`) – content type of the data to send. In case the chosen format is JSON, it will be defaulted to “application/json”.
* **headers** (`dict`\[`str`, `str`\] | `None`) – request headers in the form of dict. Wildcards are allowed both, in keys and in values.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
Wildcards:
Wildcards are the proposed way to customize the HTTP requests composed. The engine will replace all entries of `{table.}` with a value from the column `` in the row sent. This wildcard resolving will happen in url, request payload template and headers.
Examples:
For the sake of demonstration, let’s try different ways to send the stream of changes on a table `pets`, containing data about pets and their owners. The table contains just two columns: the pet and the owner’s name.
`import pathway as pw pets = pw.debug.table_from_markdown("owner pet \n Alice dog \n Bob cat \n Alice cat")`
Consider that there is a need to send the stream of changes on such table to the external API endpoint (let’s pick some exemplary URL for the sake of demonstration).
To keep things simple, we can suppose that this API accepts flat JSON objects, which are sent in POST requests. Then, the communication can be done with a simple code snippet:
`pw.io.http.write(pets, "http://www.example.com/api/event")`
Now let’s do something more custom. Suppose that the API endpoint requires us to communicate via PUT method and to pass the values as CGI-parameters. In this case, wildcards are the way to go:
`pw.io.http.write( pets, "http://www.example.com/api/event?owner={table.owner}&pet={table.pet}", method="PUT" )`
A custom payload can also be formed from the outside. What if the endpoint requires the data in tskv format in request body?
First of all, let’s form a template for the message body:
`message_template_tokens = [ "owner={table.owner}", "pet={table.pet}", "time={table.time}", "diff={table.diff}", ] message_template = "\t".join(message_template_tokens)`
Now, we can use this template and the custom format, this way:
`pw.io.http.write( pets, "http://www.example.com/api/event", method="POST", format="custom", request_payload_template=message_template )`
[Pathway Io\
\
pw.io.gdrive](https://pathway.com/developers/api-docs/pathway-io/gdrive)
[Pathway Io\
\
pw.io.iceberg](https://pathway.com/developers/api-docs/pathway-io/iceberg)
---
# pw.io.s3 | Pathway
pw.io.s3
========
[class **AwsS3Settings**(\*, bucket\_name=None, access\_key=None, secret\_access\_key=None, with\_path\_style=False, region=None, endpoint=None, session\_token=None)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.AwsS3Settings)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/_io_helpers.py#L84-L191)
Stores Amazon S3 connection settings. You may also use this class to store configuration settings for any custom S3 installation, however you will need to specify the region and the endpoint.
* **Parameters**
* **bucket\_name** – Name of S3 bucket.
* **access\_key** – Access key for the bucket.
* **secret\_access\_key** – Secret access key for the bucket.
* **with\_path\_style** – Whether to use path-style requests.
* **region** – Region of the bucket.
* **endpoint** – Custom endpoint in case of self-hosted storage.
* **session\_token** – Session token, an alternative way to authenticate to S3.
### [classmethod **new\_from\_path**(s3\_path)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.AwsS3Settings.new_from_path)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/_io_helpers.py#L131-L174)
Constructs settings from S3 path. The engine will look for the credentials in environment variables and in local AWS profiles. It will also automatically detect the region of the bucket.
This method may fail if there are no credentials or they are incorrect. It may also fail if the bucket does not exist.
* **Parameters**
**s3\_path** (`str`) – full path to the object in the form `s3:///`.
* **Returns**
Configuration object.
[class **DigitalOceanS3Settings**(bucket\_name, \*, access\_key=None, secret\_access\_key=None, region=None)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.DigitalOceanS3Settings)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/s3/__init__.py#L23-L55)
Stores Digital Ocean S3 connection settings.
* **Parameters**
* **bucket\_name** – Name of Digital Ocean S3 bucket.
* **access\_key** – Access key for the bucket.
* **secret\_access\_key** – Secret access key for the bucket.
* **region** – Region of the bucket.
[class **WasabiS3Settings**(bucket\_name, \*, access\_key=None, secret\_access\_key=None, region=None)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.WasabiS3Settings)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/s3/__init__.py#L58-L90)
Stores Wasabi S3 connection settings.
* **Parameters**
* **bucket\_name** – Name of Wasabi S3 bucket.
* **access\_key** – Access key for the bucket.
* **secret\_access\_key** – Secret access key for the bucket.
* **region** – Region of the bucket.
[**read**(path, format, \*, aws\_s3\_settings=None, schema=None, mode='streaming', with\_metadata=False, csv\_settings=None, json\_field\_paths=None, path\_filter=None, downloader\_threads\_count=None, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.read)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/s3/__init__.py#L93-L330)
Reads a table from one or several objects in Amazon S3 bucket in the given format.
In case the prefix of S3 path is specified, and there are several objects lying under this prefix, their order is determined according to their modification times: the smaller the modification time is, the earlier the file will be passed to the engine.
Note that if you only need to monitor changes in the bucket, you can use the `"only_metadata"` format, in which case the table will contain only metadata, and no time or traffic will be spent on downloading the objects.
* **Parameters**
* **path** (`str`) – Path to an object or to a folder of objects in Amazon S3 bucket.
* **aws\_s3\_settings** ([`AwsS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.AwsS3Settings)
| `None`) – Connection parameters for the S3 account and the bucket.
* **format** (`Literal`\[`'csv'`, `'json'`, `'plaintext'`, `'plaintext_by_object'`, `'binary'`, `'only_metadata'`\]) – Format of data to be read. Currently `csv`, `json`, `plaintext`, `plaintext_by_object`, `binary` and `only_metadata` formats are supported. The difference between `plaintext` and `plaintext_by_object` is how the input is tokenized: if the `plaintext` option is chosen, it’s split by the newlines. Otherwise, the files are split in full and one row will correspond to one file. In case the `binary` format is specified, the data is read as raw bytes without UTF-8 parsing. If the `only_metadata` format is chosen, the objects are not downloaded at all: the resulting table contains only the `_metadata` column, which is useful when you only need to track changes in the bucket without spending time and traffic on fetching the objects’ contents.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table. Not required for `plaintext_by_object` and `binary` formats: if they are chosen, the contents of the read objects are stored in the column `data`.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – If set to `streaming`, the engine waits for the new objects under the given path prefix. Set it to `static`, it only considers the available data and ingest all of it. Default value is `streaming`.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field that will contain an optional field `modified_at`. Additionally, the column will also have an optional field named `owner` containing an ID of the object owner. Finally, the column will also contain a field named `path` that will show the full path to the object within a bucket from where a row was filled.
* **csv\_settings** ([`CsvParserSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
| `None`) – Settings for the CSV parser. This parameter is used only in case the specified format is `csv`.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is `json`, this field allows to map field names into path in the read json object. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **path\_filter** (`str` | `None`) – A wildcard pattern used to match full object paths. Supports `*` (any number of any characters, including none) and `?` (any single character). If specified, only paths matching this pattern will be included. Applied as an additional filter after the initial `path` matching.
* **downloader\_threads\_count** (`int` | `None`) – The number of threads created to download the contents of the bucket under the given path. It defaults to the number of cores available on the machine. It is recommended to increase the number of threads if your bucket contains many small files.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Let’s consider an object store, which is hosted in Amazon S3. The store contains datasets in the respective bucket and is located in the region `eu-west-3`. The goal is to read the dataset, located under the path `animals/` in this bucket.
Let’s suppose that the format of the dataset rows is jsonlines.
Then, the code may look as follows:
`import os import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.s3.read( "animals/", aws_s3_settings=pw.io.s3.AwsS3Settings( bucket_name="datasets", region="eu-west-3", access_key=os.environ["S3_ACCESS_KEY"], secret_access_key=os.environ["S3_SECRET_ACCESS_KEY"], ), format="json", schema=InputSchema, )`
In case you are dealing with a public bucket, the parameters `access_key` and `secret_access_key` can be omitted. In this case, the read part will look as follows:
`t = pw.io.s3.read( "animals/", aws_s3_settings=pw.io.s3.AwsS3Settings( bucket_name="datasets", region="eu-west-3", ), format="json", schema=InputSchema, )`
It’s not obligatory to choose one of the available input tokenizations. You can also read the objects in full, thus creating a `pw.Table` where each row corresponds to a single object read in full. To do that, you need to specify `binary` as a format:
`t = pw.io.s3.read( "animals/", aws_s3_settings=pw.io.s3.AwsS3Settings( bucket_name="datasets", region="eu-west-3", ), format="binary", )`
Similarly you can also enable the UTF-8 parsing of the objects read, resulting in having a table of plaintext files:
`t = pw.io.s3.read( "animals/", aws_s3_settings=pw.io.s3.AwsS3Settings( bucket_name="datasets", region="eu-west-3", ), format="plaintext_by_object", )`
Note that it’s also possible to infer the bucket name and credentials from the path, if it’s given in a full form with `s3://` prefix. For instance, in the example above you can also connect as follows:
`t = pw.io.s3.read("s3://datasets/animals", format="binary")`
Note that you need to be logged in S3 for the credentials auto-detection to work.
Finally, you can also read the data from self-hosted S3 buckets, or generally those where the endpoint path differs from the standard AWS paths. To do that, you can make use of the `endpoint` field of `pw.io.s3.AwsS3Settings` class. One of the natural examples for that may be the min.io S3 buckets. That is, if you have a min.io S3 bucket instance, one of the ways to connect to it via this connector would be the first to create the settings object with the custom endpoint and path style:
`custom_settings = pw.io.s3.AwsS3Settings( endpoint="avv749.stackhero-network.com", bucket_name="datasets", access_key=os.environ["MINIO_S3_ACCESS_KEY"], secret_access_key=os.environ["MINIO_S3_SECRET_ACCESS_KEY"], with_path_style=True, region="eu-west-3", )`
And you can connect with the usage of this created custom settings format:
`t = pw.io.s3.read( "animals/", aws_s3_settings=custom_settings, format="binary", )`
Please note that the min.io connection via generic S3 connector is given only as an example: you may use `pw.io.minio.read` connector which wouldn’t require any custom settings object creation from you.
[**read\_from\_digital\_ocean**(path, do\_s3\_settings, format, \*, schema=None, mode='streaming', with\_metadata=False, csv\_settings=None, json\_field\_paths=None, downloader\_threads\_count=None, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.read_from_digital_ocean)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/s3/__init__.py#L333-L484)
Reads a table from one or several objects in Digital Ocean S3 bucket.
In case the prefix of S3 path is specified, and there are several objects lying under this prefix, their order is determined according to their modification times: the smaller the modification time is, the earlier the file will be passed to the engine.
Note that if you only need to monitor changes in the bucket, you can use the `"only_metadata"` format, in which case the table will contain only metadata, and no time or traffic will be spent on downloading the objects.
* **Parameters**
* **path** (`str`) – Path to an object or to a folder of objects in S3 bucket.
* **do\_s3\_settings** ([`DigitalOceanS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.DigitalOceanS3Settings)
) – Connection parameters for the account and the bucket.
* **format** (`Literal`\[`'csv'`, `'json'`, `'plaintext'`, `'plaintext_by_object'`, `'binary'`, `'only_metadata'`\]) – Format of data to be read. Currently `csv`, `json`, `plaintext`, `plaintext_by_object`, `binary` and `only_metadata` formats are supported. The difference between `plaintext` and `plaintext_by_object` is how the input is tokenized: if the `plaintext` option is chosen, it’s split by the newlines. Otherwise, the files are split in full and one row will correspond to one file. In case the `binary` format is specified, the data is read as raw bytes without UTF-8 parsing. If the `only_metadata` format is chosen, the objects are not downloaded at all: the resulting table contains only the `_metadata` column, which is useful when you only need to track changes in the bucket without spending time and traffic on fetching the objects’ contents.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table. Not required for `plaintext_by_object` and `binary` formats: if they are chosen, the contents of the read objects are stored in the column `data`.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – If set to `streaming`, the engine waits for the new objects under the given path prefix. Set it to `static`, it only considers the available data and ingest all of it. Default value is `streaming`.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field that will contain an optional field `modified_at`. Additionally, the column will also have an optional field named `owner` containing an ID of the object owner. Finally, the column will also contain a field named `path` that will show the full path to the object within a bucket from where a row was filled.
* **csv\_settings** ([`CsvParserSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
| `None`) – Settings for the CSV parser. This parameter is used only in case the specified format is “csv”.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is “json”, this field allows to map field names into path in the read json object. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **downloader\_threads\_count** (`int` | `None`) – The number of threads created to download the contents of the bucket under the given path. It defaults to the number of cores available on the machine. It is recommended to increase the number of threads if your bucket contains many small files.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Let’s consider an object store, which is hosted in Digital Ocean S3. The store contains CSV datasets in the respective bucket and is located in the region ams3. The goal is to read the dataset, located under the path `animals/` in this bucket.
Then, the code may look as follows:
`import os import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.s3.read_from_digital_ocean( "animals/", do_s3_settings=pw.io.s3.DigitalOceanS3Settings( bucket_name="datasets", region="ams3", access_key=os.environ["DO_S3_ACCESS_KEY"], secret_access_key=os.environ["DO_S3_SECRET_ACCESS_KEY"], ), format="csv", schema=InputSchema, )`
Please note that this connector is **interoperable** with the **AWS S3** connector, therefore all examples concerning different data formats in `pw.io.s3.read` also work with Digital Ocean version.
[**read\_from\_wasabi**(path, wasabi\_s3\_settings, format, \*, schema=None, mode='streaming', with\_metadata=False, csv\_settings=None, json\_field\_paths=None, downloader\_threads\_count=None, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/s3#pathway.io.s3.read_from_wasabi)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/s3/__init__.py#L487-L637)
Reads a table from one or several objects in Wasabi S3 bucket.
In case the prefix of S3 path is specified, and there are several objects lying under this prefix, their order is determined according to their modification times: the smaller the modification time is, the earlier the file will be passed to the engine.
Note that if you only need to monitor changes in the bucket, you can use the `"only_metadata"` format, in which case the table will contain only metadata, and no time or traffic will be spent on downloading the objects.
* **Parameters**
* **path** (`str`) – Path to an object or to a folder of objects in S3 bucket.
* **wasabi\_s3\_settings** ([`WasabiS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.WasabiS3Settings)
) – Connection parameters for the account and the bucket.
* **format** (`Literal`\[`'csv'`, `'json'`, `'plaintext'`, `'plaintext_by_object'`, `'binary'`, `'only_metadata'`\]) – Format of data to be read. Currently `csv`, `json`, `plaintext`, `plaintext_by_object`, `binary` and `only_metadata` formats are supported. The difference between `plaintext` and `plaintext_by_object` is how the input is tokenized: if the `plaintext` option is chosen, it’s split by the newlines. Otherwise, the files are split in full and one row will correspond to one file. In case the `binary` format is specified, the data is read as raw bytes without UTF-8 parsing. If the `only_metadata` format is chosen, the objects are not downloaded at all: the resulting table contains only the `_metadata` column, which is useful when you only need to track changes in the bucket without spending time and traffic on fetching the objects’ contents.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Schema of the resulting table. Not required for `plaintext_by_object` and `binary` formats: if they are chosen, the contents of the read objects are stored in the column `data`.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – If set to `streaming`, the engine waits for the new objects under the given path prefix. Set it to `static`, it only considers the available data and ingest all of it. Default value is `streaming`.
* **with\_metadata** (`bool`) – When set to true, the connector will add an additional column named `_metadata` to the table. This column will be a JSON field that will contain an optional field `modified_at`. Additionally, the column will also have an optional field named `owner` containing an ID of the object owner. Finally, the column will also contain a field named `path` that will show the full path to the object within a bucket from where a row was filled.
* **csv\_settings** ([`CsvParserSettings`](https://pathway.com/developers/api-docs/pathway-io#pathway.io.CsvParserSettings)
| `None`) – Settings for the CSV parser. This parameter is used only in case the specified format is “csv”.
* **json\_field\_paths** (`dict`\[`str`, `str`\] | `None`) – If the format is “json”, this field allows to map field names into path in the read json object. For the field which require such mapping, it should be given in the format `: `, where the path to be mapped needs to be a [JSON Pointer (RFC 6901)](https://www.rfc-editor.org/rfc/rfc6901)
.
* **downloader\_threads\_count** (`int` | `None`) – The number of threads created to download the contents of the bucket under the given path. It defaults to the number of cores available on the machine. It is recommended to increase the number of threads if your bucket contains many small files.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Let’s consider an object store, which is hosted in Wasabi S3. The store contains CSV datasets in the respective bucket and is located in the region `us-west-1`. The goal is to read the dataset, located under the path `animals/` in this bucket.
Then, the code may look as follows:
`import os import pathway as pw class InputSchema(pw.Schema): owner: str pet: str t = pw.io.s3.read_from_wasabi( "animals/", wasabi_s3_settings=pw.io.s3.WasabiS3Settings( bucket_name="datasets", region="us-west-1", access_key=os.environ["WASABI_S3_ACCESS_KEY"], secret_access_key=os.environ["WASABI_S3_SECRET_ACCESS_KEY"], ), format="csv", schema=InputSchema, )`
Please note that this connector is **interoperable** with the **AWS S3** connector, therefore all examples concerning different data formats in `pw.io.s3.read` also work with Wasabi version.
[Pathway Io\
\
pw.io.redpanda](https://pathway.com/developers/api-docs/pathway-io/redpanda)
[Pathway Io\
\
pw.io.slack](https://pathway.com/developers/api-docs/pathway-io/slack)
---
# pw.io.iceberg | Pathway
pw.io.iceberg
=============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
All internal Pathway Live Data Framework types, except `Any`, can be stored in Apache Iceberg. The table below explains how Live Data Framework engine data is saved in Iceberg when Live Data Framework creates the destination table. You can also find descriptions of the corresponding Iceberg types in the [specification](https://iceberg.apache.org/spec/#primitive-types)
. The values of the corresponding types can also be deserialized from Iceberg storage into Live Data Framework values.
[Pathway types conversion into Iceberg](https://pathway.com/developers/api-docs/pathway-io/iceberg#pathway-types-conversion-into-iceberg)
------------------------------------------------------------------------------------------------------------------------------------------
| Live Data Framework type | Iceberg type |
| --- | --- |
| `bool` | `boolean` |
| `int` | `long` (8-byte signed integer number) |
| `float` | `double` (8-byte double-precision floating-point number) |
| `pointer` | `string`, can be deserialized back if `pw.Pointer` type is specified in Live Data Framework table schema |
| `str` | `string` |
| `bytes` | `binary` |
| `Naive DateTime` | `timestamp` or `timestamp_ns` depending on the chosen `timestamp_unit` |
| `UTC DateTime` | `timestamptz` or `timestamptz_ns` depending on the chosen `timestamp_unit`. Not supported with the Glue catalog, since the backing Hive metastore has no timezone-aware timestamp type. |
| `Duration` | `long`, serialized and deserialized with microsecond precision |
| `JSON` | `string`, containing the serialized JSON value |
| `np.ndarray` | `struct` with two top-level fields: `shape` denoting the shape of the stored array, and `elements` denoting the elements of a flattened array. Same on-disk encoding as [`pathway.io.deltalake.write()`](https://pathway.com/developers/api-docs/pathway-io-deltalake#pathway.io.deltalake.write)
. |
| `tuple` | `struct` with as many top-level fields as the elements of the tuple. The elements are named \[0\], \[1\], and so on, the order of the elements corresponds to the appearance of the types in the tuple |
| `list` | `list` |
| `pw.PyObjectWrapper` | `binary`, can be deserialized back if the `pw.PyObjectWrapper` type is specified in Live Data Framework table schema |
Iceberg `map` is **not supported** on either read or write — Live Data Framework has no native map type. Columns of this type can’t be included in a Live Data Framework schema.
[Reading Iceberg tables produced by other tools](https://pathway.com/developers/api-docs/pathway-io/iceberg#reading-iceberg-tables-produced-by-other-tools)
------------------------------------------------------------------------------------------------------------------------------------------------------------
Iceberg tables produced by Spark, Flink, pyiceberg, and similar tools commonly use storage types Live Data Framework never writes itself. `pw.io.iceberg.read` accepts the following extra Iceberg types and projects them onto Live Data Framework types according to the Live Data Framework type declared in the schema:
### [Additional Iceberg-to-Pathway conversions (read only)](https://pathway.com/developers/api-docs/pathway-io/iceberg#additional-iceberg-to-pathway-conversions-read-only)
| Iceberg type | Live Data Framework schema type | Notes |
| --- | --- | --- |
| `int` (32-bit) / `float` (32-bit) | `int` / `float` | Widened to 64-bit; lossless. |
| `date` | `Naive DateTime` | Live Data Framework has no native `Date`; values are materialized at midnight on the calendar day. A date outside Live Data Framework’s representable timestamp range (roughly years 1678–2262) surfaces a per-row conversion error instead of an out-of-range value. |
| `time` | `Duration` | Microseconds since midnight, same convention as the Postgres `TIME` mapping. |
| `uuid` | `str` | Canonical 8-4-4-4-12 hex string. |
| `uuid` | `bytes` | Raw 16 bytes. |
| `fixed(N)` | `bytes` | Length-N byte string. |
| `decimal(p, s)` | `float` | Goes through 64-bit float: lossy in general (binary representation, ~15-17 significant decimal digits of mantissa). The reader emits a one-time warning at startup naming each affected column. |
| `decimal(p, s)` | `str` | Lossless. The unscaled integer is formatted with the column’s scale and passed through as decimal text. Supports the full Iceberg range of up to 38 digits of precision. |
[Writing into existing typed columns](https://pathway.com/developers/api-docs/pathway-io/iceberg#writing-into-existing-typed-columns)
--------------------------------------------------------------------------------------------------------------------------------------
When `pw.io.iceberg.write` is pointed at an Iceberg table that already exists (created by another writer with a hand-rolled schema, or by `pyiceberg`, Spark, etc.), the writer reconciles each Live Data Framework column type against the destination column’s declared type. If the destination is one of the following narrow or specialized Iceberg types, the writer encodes the value into the existing column’s type:
### [Pathway-to-existing-Iceberg-column conversions (write only)](https://pathway.com/developers/api-docs/pathway-io/iceberg#pathway-to-existing-iceberg-column-conversions-write-only)
| Live Data Framework type | Existing Iceberg column | Notes |
| --- | --- | --- |
| `int` | `int` (32-bit) | Out-of-range values raise an error rather than silently truncating. |
| `float` | `float` (32-bit) | Cast to 32-bit float; precision beyond ~7 significant decimal digits is lost. Values outside the 32-bit float range materialize as ±∞ (IEEE 754 semantics). |
| `str` | `decimal(p, s)` | Each row’s text is parsed as a decimal of the destination’s precision and scale. |
| `str` | `uuid` | Canonical 8-4-4-4-12 hex. |
| `bytes` | `fixed(N)` | Length-checked at write time. |
| `Duration` | `time` | Microseconds since midnight, same convention as [`pathway.io.postgres.write()`](https://pathway.com/developers/api-docs/pathway-io-postgres#pathway.io.postgres.write)
for `TIME` columns. |
| `Naive DateTime` | `date` | The time-of-day component is silently truncated. Same convention as [`pathway.io.postgres.write()`](https://pathway.com/developers/api-docs/pathway-io-postgres#pathway.io.postgres.write)
for `DATE` columns. |
When the destination column is a `struct` (bound to a Live Data Framework `tuple`) or a `list>`, the same overrides apply recursively to each tuple position or inner element type. Iceberg `date` is not supported when Live Data Framework is creating the destination table, since Live Data Framework has no date-only type to derive from.
[Preflight validation](https://pathway.com/developers/api-docs/pathway-io/iceberg#preflight-validation)
--------------------------------------------------------------------------------------------------------
At construction time, both `pw.io.iceberg.read` and `pw.io.iceberg.write` compare the Live Data Framework schema against the Iceberg table’s actual schema and fail fast with a targeted error rather than producing per-row parse errors that don’t surface to `pw.run()`. The detected mismatches are: a Live Data Framework column not present in the Iceberg table, a Live Data Framework type that has no defined encoding/decoding against the Iceberg column’s type (checked recursively into the inner types of `tuple`/`struct`, `list`, and `np.ndarray` columns), and a `tuple`/`struct` arity mismatch. `pw.io.iceberg.write` additionally rejects: a required (non-null) Iceberg column the Live Data Framework table doesn’t produce, and a `timestamp_unit` choice that doesn’t match the destination column’s precision (`timestamp` vs `timestamp_ns`).
[class **GlueCatalog**(warehouse, uri=None, catalog\_id=None, aws\_settings=None)](https://pathway.com/developers/api-docs/pathway-io/iceberg#pathway.io.iceberg.GlueCatalog)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/iceberg/__init__.py#L51-L97)
Configuration settings for a Glue Iceberg catalog.
* **Parameters**
* **warehouse** (`str`) – The path to the data warehouse.
* **uri** (`str` | `None`) – The URI of the Glue catalog endpoint.
* **catalog\_id** (`str` | `None`) – The ID of the Glue catalog.
* **aws\_settings** ([`AwsS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.AwsS3Settings)
| `None`) – The AWS connection settings.
* **Returns**
A configuration object.
Example:
Suppose you need to connect to a Glue catalog running in the `datalake` AWS bucket, located in the `eu-central-1` region.
If the data warehouse path is `storage/root`, the configuration object can be constructed as follows:
`settings = pw.io.iceberg.GlueCatalog( warehouse="s3://datalake/storage/root", aws_settings=pw.io.s3.AwsS3Settings(region="eu-central-1"), )`
If possible, the AWS credentials are inferred from the environment. You can also specify the credentials explicitly in the `AwsS3Settings` object.
[class **RestCatalog**(uri, warehouse=None)](https://pathway.com/developers/api-docs/pathway-io/iceberg#pathway.io.iceberg.RestCatalog)
----------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/iceberg/__init__.py#L21-L48)
Configuration settings for a REST Iceberg catalog.
* **Parameters**
* **uri** (`str`) – The URI of the catalog.
* **warehouse** (`str` | `None`) – Optional data warehouse path.
* **Returns**
A configuration object.
Example:
Suppose you need to connect to a REST catalog running at `http://localhost:8181`. The connection settings can be constructed as follows:
`settings = pw.io.iceberg.RestCatalog(uri="http://localhost:8181")`
[**read**(catalog, namespace, table\_name, schema, \*, mode='streaming', autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/iceberg#pathway.io.iceberg.read)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/iceberg/__init__.py#L100-L223)
Reads a table from Apache Iceberg. In `"streaming"` mode the connector polls the catalog for new snapshots and reflects the diff between the previous and new snapshot’s **data files** in the Pathway Live Data Framework table: files added to the new plan become row additions, files removed from it become row deletions. Note that this is a file-level diff — Iceberg V2 row-level delete files (positional or equality deletes added alongside the same data files) are not separately tracked.
Note that the connector requires primary key fields to be specified in the schema. You can specify the fields to be used in the primary key with `pw.column_definition` function.
Side effect: if the namespace passed in `namespace` doesn’t exist in the catalog at construction time, the connector creates it. The table itself must already exist — a missing table surfaces as a catalog error.
* **Parameters**
* **catalog** ([`RestCatalog`](https://pathway.com/developers/api-docs/pathway-io-iceberg#pathway.io.iceberg.RestCatalog)
| [`GlueCatalog`](https://pathway.com/developers/api-docs/pathway-io-iceberg#pathway.io.iceberg.GlueCatalog)
) – Settings for Iceberg catalog connection.
* **namespace** (`list`\[`str`\]) – The name of the namespace containing the table read.
* **table\_name** (`str`) – The name of the table to be read.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"` the engine will wait for the updates in the specified lake. It will track new row additions and reflect these events in the state. On the other hand, the `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every `autocommit_duration_ms` milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – Table read from the Iceberg source.
Example:
Consider a users data table stored in the Iceberg storage. The table is located in the `app` namespace and is named `users`. The catalog URI is `http://localhost:8181`. Below is an example of how to read this table into the Pathway Live Data Framework.
First, the schema of the table needs to be created. The schema doesn’t have to contain all the columns of the table, you can only specify the ones that are needed for the computation:
`import pathway as pw class InputSchema(pw.Schema): user_id: int = pw.column_definition(primary_key=True) name: str`
Then, this table must be read from the Iceberg storage.
`input_table = pw.io.iceberg.read( catalog=pw.io.iceberg.RestCatalog(uri="http://localhost:8181/"), namespace=["app"], table_name="users", schema=InputSchema, mode="static", )`
Don’t forget to run your program with `pw.run` once you define all necessary computations. Note that you can also change the mode to `"streaming"` if you want the changes in the table to be reflected in your computational pipeline.
[**write**(table, catalog, namespace, table\_name, \*, timestamp\_unit='ns', min\_commit\_frequency=60000, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/iceberg#pathway.io.iceberg.write)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/iceberg/__init__.py#L226-L337)
Writes the stream of changes from `table` into [Iceberg](https://iceberg.apache.org/)
data storage. The data storage must be defined with the catalog, the namespace, and the table name.
If the namespace or the table doesn’t exist, they will be created by the connector. The schema of the new table is inferred from the `table`’s schema.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **catalog** ([`RestCatalog`](https://pathway.com/developers/api-docs/pathway-io-iceberg#pathway.io.iceberg.RestCatalog)
| [`GlueCatalog`](https://pathway.com/developers/api-docs/pathway-io-iceberg#pathway.io.iceberg.GlueCatalog)
) – The catalog of the target storage.
* **namespace** (`list`\[`str`\]) – The name of the namespace containing the target table. If the namespace doesn’t exist, it will be created by the connector.
* **table\_name** (`str`) – The name of the table to be written. If a table with such a name doesn’t exist, it will be created by the connector.
* **timestamp\_unit** (`Literal`\[`'us'`, `'ns'`\]) – The precision used for timestamp serialization. It can be either `"us"` for microseconds or `"ns"` for nanoseconds. When selecting the precision, ensure that your catalog supports the chosen unit, as different underlying data types are used: `timestamp` for microsecond precision and `timestamp_ns` for nanosecond precision. Note that some catalogs only support a specific timestamp format. In the case of the Glue catalog, only **nanoseconds** are supported.
* **min\_commit\_frequency** (`int` | `None`) – Specifies the minimum time interval between two data commits in storage, measured in milliseconds. If set to `None`, finalized minibatches will be committed as soon as possible. Keep in mind that each commit in Iceberg creates a new Parquet file and writes an entry in the transaction log. Therefore, it is advisable to limit the frequency of commits to reduce the overhead of processing the resulting table.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
Consider a users data table stored locally in a file called `users.txt` in CSV format. The Iceberg output connector provides the capability to place this table into Iceberg storage, defined by the REST catalog with URI `http://localhost:8181`. The target table is `users`, located in the `app` namespace.
First, the table must be read. To do this, you need to define the schema. For simplicity, consider that it consists of two fields: the user ID and the name.
The schema definition may look as follows:
`import pathway as pw class InputSchema(pw.Schema): user_id: int = pw.column_definition(primary_key=True) name: str`
Using this schema, you can read the table from the input file. You need to use the `pw.io.csv.read` connector. Here, you can use the static mode since the text file with the users doesn’t change dynamically.
`users = pw.io.csv.read("./users.txt", schema=InputSchema, mode="static")`
Once the table is read, you can use `pw.io.iceberg.write` to save this table into Iceberg storage.
`pw.io.iceberg.write( users, catalog=pw.io.iceberg.RestCatalog(uri="http://localhost:8181/"), namespace=["app"], table_name="users", )`
Don’t forget to run your program with `pw.run` once you define all necessary computations. After execution, you will be able to see the users’ data in the Iceberg storage.
[Pathway Io\
\
pw.io.http](https://pathway.com/developers/api-docs/pathway-io/http)
[Pathway Io\
\
pw.io.jsonlines](https://pathway.com/developers/api-docs/pathway-io/jsonlines)
---
# pw.io.deltalake | Pathway
pw.io.deltalake
===============
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
All internal Pathway Live Data Framework types, except `Any`, can be stored in Delta Lake. The table below explains how Live Data Framework engine data is saved in Delta Lake. You can also find descriptions of the corresponding Delta types in the [protocol description](https://github.com/delta-io/delta/blob/master/PROTOCOL.md#schema-serialization-format)
. The values of the corresponding types can also be deserialized from Delta Lake into Live Data Framework values.
[Pathway types conversion into Delta Lake](https://pathway.com/developers/api-docs/pathway-io/deltalake#pathway-types-conversion-into-delta-lake)
--------------------------------------------------------------------------------------------------------------------------------------------------
| Live Data Framework type | Delta table type |
| --- | --- |
| `bool` | `boolean` |
| `int` | `long` (8-byte signed integer number) |
| `float` | `double` (8-byte double-precision floating-point number) |
| `pointer` | `string`, can be deserialized back if `pw.Pointer` type is specified in Live Data Framework table schema |
| `str` | `string` |
| `bytes` | `binary` |
| `Naive DateTime` | `timestamp without time zone` |
| `UTC DateTime` | `timestamp` |
| `Duration` | `long`, serialized and deserialized with microsecond precision |
| `JSON` | `string`, containing the serialized JSON value |
| `np.ndarray` | `struct` type with two top-level fields: `shape` denoting the shape of the stored array, and `elements` denoting the elements of a flattened array |
| `tuple` | `struct` with as many top-level fields as the elements of the tuple. The elements are named \[0\], \[1\], and so on, the order of the elements corresponds to the appearance of the types in the tuple |
| `list` | `array` |
| `pw.PyObjectWrapper` | `binary`, can be deserialized back if the `pw.PyObjectWrapper` type is specified in Live Data Framework table schema |
[Reading Delta tables produced by other tools](https://pathway.com/developers/api-docs/pathway-io/deltalake#reading-delta-tables-produced-by-other-tools)
----------------------------------------------------------------------------------------------------------------------------------------------------------
Delta tables produced by Spark, DuckDB, pandas, and similar tools commonly use storage types Live Data Framework never writes itself. `pw.io.deltalake.read` accepts the following extra Delta types and projects them onto Live Data Framework types according to the Live Data Framework type declared in the schema:
### [Additional Delta-to-Pathway conversions (read only)](https://pathway.com/developers/api-docs/pathway-io/deltalake#additional-delta-to-pathway-conversions-read-only)
| Delta table type | Live Data Framework schema type | Notes |
| --- | --- | --- |
| `byte` / `short` / `integer` (1/2/4-byte signed) | `int` | Widened to `i64`; lossless. |
| unsigned 1/2/4/8-byte integers (Parquet `UINT_8` … `UINT_64`) | `int` | Widened to `i64`; values exceeding `i64::MAX` (only possible for `UINT_64`) raise a conversion error. |
| `float` (4-byte) / `float16` (2-byte) | `float` | Widened to `f64`; lossless. |
| `date` | `Naive DateTime` or `UTC DateTime` | Live Data Framework has no native `Date`; values are materialized at midnight on the calendar day. |
| `timestamp` with millisecond precision | `Naive DateTime` or `UTC DateTime` | Sub-second precision preserved to the millisecond. |
| `decimal(p, s)` | `float` | Goes through `f64`: lossy in general (binary representation, ~15-17 significant decimal digits of mantissa). The reader emits a one-time warning at startup naming each affected column. |
| `decimal(p, s)` | `str` | Lossless. The unscaled integer is formatted with the column’s scale and passed through as decimal text (`decimal(8, 2)` value `10050` → `"100.50"`). Supports the full Delta range of up to 38 digits of precision. |
Partition columns of all types in the first table round-trip through `pw.io.deltalake.read`, including `pointer`, `Duration`, and `JSON` partitions, which are stored as their underlying `string` or `long` Delta types in the partition path.
[Writing to existing decimal columns](https://pathway.com/developers/api-docs/pathway-io/deltalake#writing-to-existing-decimal-columns)
----------------------------------------------------------------------------------------------------------------------------------------
When the destination Delta table already has a `decimal(p, s)` column and the Live Data Framework column written into it has type `str`, the writer parses each row’s decimal text into the unscaled integer and stores it as a fixed-point value of the column’s declared precision and scale. This is the symmetric counterpart to reading a Delta `decimal` column as `str`: a Delta `decimal` column read into Live Data Framework, processed as text, and written back into the same Delta column round-trips with no precision loss.
A string that can’t be parsed as a decimal of the column’s shape (non-digit characters, more fractional digits than the column’s scale, or more total digits than its precision) fails the write with an error message naming the offending value, the column’s precision and scale, and the specific constraint it violated. Tables that don’t contain a `decimal` column are unaffected: writing a Live Data Framework `str` column into a fresh table or into an existing Delta `string` column behaves exactly as before.
[class **TableOptimizer**(tracked\_column, time\_format, quick\_access\_window, compression\_frequency, retention\_period=datetime.timedelta(0), remove\_old\_checkpoints=False)](https://pathway.com/developers/api-docs/pathway-io/deltalake#pathway.io.deltalake.TableOptimizer)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/deltalake/__init__.py#L92-L321)
The table optimizer is used to optimize partitioned Delta tables created by the output connector. This optimization is limited to tables that are partitioned by a string column, where the values represent date and time in a specific format.
After a `WRITE` operation and once the specified interval has passed, the optimizer runs [OPTIMIZE](https://delta.io/blog/delta-lake-optimize/)
and [VACUUM](https://docs.delta.io/latest/delta-utility.html#id1)
operations. If these operations fail, they will be retried during the next write. Keep in mind that running `OPTIMIZE` and `VACUUM` may cause a delay in the output because they take time to complete, but they do not slow down the overall computational pipeline. This approach is necessary to prevent conflicts that could occur from simultaneous writes to the Delta log.
If `remove_old_checkpoints` is enabled, the background process will also make sure that only the most recent checkpoint file is kept.
Please note that `remove_old_checkpoints` is currently an experimental feature and it works only when the backend uses a filesystem.
* **Parameters**
* **tracked\_column** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – The partition column for the observed table.
* **time\_format** (`str`) – A [strftime-like](https://strftime.org/)
format string that defines how values in the tracked column are interpreted.
* **quick\_access\_window** (`int` | `float` | `timedelta`) – All partition values older than this window will be compressed using the `OPTIMIZE` Delta Lake operation, followed by `VACUUM`. Given as a number of seconds or a `datetime.timedelta` / `pw.Duration`.
* **compression\_frequency** (`int` | `float` | `timedelta`) – Determines how often the compression process is triggered. If a compression attempt fails, it will be retried immediately without waiting. Given as a number of seconds or a `datetime.timedelta` / `pw.Duration`.
* **retention\_period** (`int` | `float` | `timedelta`) – Retention period for the `VACUUM` operation. Given as a number of seconds or a `datetime.timedelta` / `pw.Duration`.
* **remove\_old\_checkpoints** (`bool`) – If `True`, Pathway Live Data Framework will keep only the most recent checkpoint file to reduce storage usage.
Example:
Suppose you are writing to a table that is partitioned by the column `day_utc`, where the values follow the ISO-8601 format: `YYYY-MM-DD`. You want to compress data older than 7 days and run this compression once per day.
In that case, the optimizer settings would be configured as follows:
`import pathway as pw optimizer = pw.io.deltalake.TableOptimizer( tracked_column=table.day_utc, time_forma2t="%Y-%m-%d", quick_access_window=datetime.timedelta(days=7), compression_frequency=datetime.timedelta(days=1), )`
This optimizer object needs to be passed to the `pw.io.deltalake.write` function.
Note: Background cleanup of old snapshots will not run automatically in this setup. To enable it, you can turn it on explicitly:
`optimizer = pw.io.deltalake.TableOptimizer( tracked_column=table.day_utc, time_format="%Y-%m-%d", quick_access_window=datetime.timedelta(days=7), compression_frequency=datetime.timedelta(days=1), remove_old_checkpoints=True, )`
[**read**(uri, schema=None, \*, mode='streaming', s3\_connection\_settings=None, start\_from\_timestamp\_ms=None, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-io/deltalake#pathway.io.deltalake.read)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/deltalake/__init__.py#L324-L501)
Reads a table from Delta Lake. Currently, local and S3 lakes are supported. The table doesn’t have to be append only, however, the deletion vectors are not supported yet.
Reads are atomic with respect to the data version. This means that if a data update - such as inserting, deleting, or modifying rows - is made within a single Delta transaction, all those changes will be applied together, as one atomic operation, in a single minibatch.
Note that the connector requires either the table to be append-only or the primary key fields to be specified in the schema. You can define the primary key fields using the `pw.column_definition` function.
* **Parameters**
* **uri** (`str` | `PathLike`) – URI of the Delta Lake source that must be read.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\] | `None`) – Defines the schema of the resulting table. You can omit this parameter if the table is created using `pw.io.deltalake.write`, as the schema (excluding the special `time` and `diff` fields) will then be automatically stored in the Delta Table’s columns metadata.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Denotes how the engine polls the new data from the source. Currently `"streaming"` and `"static"` are supported. If set to `"streaming"` the engine will wait for the updates in the specified lake. It will track new row additions and reflect these events in the state. On the other hand, the `"static"` mode will only consider the available data and ingest all of it in one commit. The default value is `"streaming"`.
* **s3\_connection\_settings** ([`AwsS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.AwsS3Settings)
| [`MinIOSettings`](https://pathway.com/developers/api-docs/pathway-io-minio#pathway.io.minio.MinIOSettings)
| [`WasabiS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.WasabiS3Settings)
| [`DigitalOceanS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.DigitalOceanS3Settings)
| `None`) – Configuration for S3 credentials when using S3 storage. In addition to the access key and secret access key, you can specify a custom endpoint, which is necessary for buckets hosted outside of Amazon AWS. If the custom endpoint is left blank, the authorized user’s credentials for S3 will be used.
* **start\_from\_timestamp\_ms** (`int` | `None`) – If defined, only changes that occurred after the specified timestamp are read. When used with **non-append-only tables**, the state of the table at the given timestamp is loaded first, and then all updates are read incrementally.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every `autocommit_duration_ms` milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
Examples:
Consider an example with a stream of changes on a simple key-value table, streamed by another Pathway Live Data Framework program with `pw.io.deltalake.write` method.
Let’s start writing Pathway Live Data Framework code. First, the schema of the table needs to be created:
`import pathway as pw class KVSchema(pw.Schema): key: str = pw.column_definition(primary_key=True) value: str`
Then, this table must be written into a Delta Lake storage. In the example, it can be created from the static data with `pw.debug.table_from_markdown` method and saved into the locally located lake:
`output_table = pw.debug.table_from_markdown("key value \n one Hello \n two World") lake_path = "./local-lake" pw.io.deltalake.write(output_table, lake_path)`
Now the producer code can be run with a simple `pw.run`:
`pw.run(monitoring_level=pw.MonitoringLevel.NONE)`
After that, you can read this table with the Pathway Live Data Framework as well. It requires the specification of the URI and the schema that was created above. In addition, you can use the `"static"` mode, so that the program finishes after the data is read:
`input_table = pw.io.deltalake.read(lake_path, KVSchema, mode="static")`
Please note that the table doesn’t necessary have to be created by the Pathway Live Data Framework: an append-only Delta Table created in any other way will also be processed correctly.
Finally, you can check that the resulting table contains the same set of rows by displaying it with `pw.debug.compute_and_print`:
`pw.debug.compute_and_print(input_table, include_id=False)`
Code Results
Please note that you can use the same communication approach if S3 is used as a data storage. To do this, specify an S3 path starting with `s3://` or `s3a://`, and provide the credentials object as a parameter. If no credentials are provided but the path starts with `s3://` or `s3a://`, the Pathway Live Data Framework will use the credentials of the currently authenticated user.
**Reading Delta** `decimal(p, s)` **columns.** Pathway has no native `Decimal` type, so a Delta `decimal` column has to be projected onto something else, and the choice is driven by the Pathway Live Data Framework type declared in the schema:
* Declaring the column as `float` converts each value through `f64`. This is lossy in general — both because `f64` is binary (e.g. `0.1` is not exact) and because its mantissa carries only ~15-17 significant decimal digits. The reader emits a one-time warning at startup naming each affected column.
* Declaring the column as `str` formats the unscaled integer with the column’s scale and passes the resulting decimal text through unchanged (e.g. `decimal(8, 2)` value `10050` becomes `"100.50"`). This is lossless for the full Delta precision range (up to 38 digits).
The symmetric write path, described in `pw.io.deltalake.write`, lets you preserve a Delta `decimal(p, s)` column type across a Pathway pipeline: read it as `str`, process it as text, and write it back into the same Delta column.
[**write**(table, uri, \*, s3\_connection\_settings=None, partition\_columns=None, min\_commit\_frequency=60000, name=None, sort\_by=None, output\_table\_type='stream\_of\_changes', table\_optimizer=None)](https://pathway.com/developers/api-docs/pathway-io/deltalake#pathway.io.deltalake.write)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/deltalake/__init__.py#L525-L700)
Writes the stream of changes from `table` into Delta Lake [https://delta.io/](https://delta.io/)
\_ data storage at the location specified by `uri`. Supported storage types are S3 and the local filesystem.
The storage type is determined by the URI: paths starting with `s3://` or `s3a://` are for S3 storage, while all other paths use the filesystem.
If the specified storage location doesn’t exist, it will be created. The schema of the new table is inferred from the `table`’s schema. Additionally, when the connector creates a table, its Pathway Live Data Framework schema is stored in the column metadata. This allows the table to be read using `pw.io.deltalake.read` without explicitly specifying a `schema`.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **uri** (`str` | `PathLike`) – URI of the target Delta Lake.
* **s3\_connection\_settings** ([`AwsS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.AwsS3Settings)
| [`MinIOSettings`](https://pathway.com/developers/api-docs/pathway-io-minio#pathway.io.minio.MinIOSettings)
| [`WasabiS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.WasabiS3Settings)
| [`DigitalOceanS3Settings`](https://pathway.com/developers/api-docs/pathway-io-s3#pathway.io.s3.DigitalOceanS3Settings)
| `None`) – Configuration for S3 credentials when using S3 storage. In addition to the access key and secret access key, you can specify a custom endpoint, which is necessary for buckets hosted outside of Amazon AWS. If the custom endpoint is left blank, the authorized user’s credentials for S3 will be used.
* **partition\_columns** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – Partition columns for the table. Used if the table is created by the Pathway Live Data Framework.
* **min\_commit\_frequency** (`int` | `None`) – Specifies the minimum time interval between two data commits in storage, measured in milliseconds. If set to `None`, finalized minibatches will be committed as soon as possible. Keep in mind that each commit in Delta Lake creates a new file and writes an entry in the transaction log. Therefore, it is advisable to limit the frequency of commits to reduce the overhead of processing the resulting table. Note that to further optimize performance and reduce the number of chunks in the table, you can use [vacuum](https://docs.delta.io/latest/delta-utility.html#remove-files-no-longer-referenced-by-a-delta-table)
or [optimize](https://docs.delta.io/2.0.2/optimizations-oss.html#optimize-performance-with-file-management)
operations afterwards.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – Defines how the output table manages its data. If set to `"stream_of_changes"` (the default), the system outputs a stream of modifications to the target table. This stream includes two additional integer columns: `time`, representing the computation minibatch, and `diff`, indicating the type of change (`1` for row addition and `-1` for row deletion). If set to `"snapshot"`, the table maintains the current state of the data, updated atomically with each minibatch and ensuring that no partial minibatch updates are visible. To correctly track the relationship between the Pathway Live Data Framework’s primary key and the output table in this mode, an additional `_id` field of the `Pointer` type is added. **Please note that this mode may be slower when there are many deletions, because a deletion in a minibatch causes the entire table to be rewritten once that minibatch reaches the output. Please also note that this method is not suitable for the tables that don’t fit in memory.**
* **table\_optimizer** ([`TableOptimizer`](https://pathway.com/developers/api-docs/pathway-io-deltalake#pathway.io.deltalake.TableOptimizer)
| `None`) – The optimization parameters for the output table.
* **Returns**
None
Example:
Consider a table `access_log` that needs to be output to a Delta Lake storage located locally at the folder `./logs/access-log`. It can be done as follows:
`pw.io.deltalake.write(access_log, "./logs/access-log")`
Please note that if there is no filesystem object at this path, the corresponding folder will be created. However, if you run this code twice, the new data will be appended to the storage created during the first run.
It is also possible to save the table to S3 storage. To save the table to the `access-log` path within the `logs` bucket in the `eu-west-3` region, modify the code as follows:
`pw.io.deltalake.write( access_log, "s3://logs/access-log/", s3_connection_settings=pw.io.s3.AwsS3Settings( bucket_name="logs", region="eu-west-3", access_key=os.environ["S3_ACCESS_KEY"], secret_access_key=os.environ["S3_SECRET_ACCESS_KEY"], ) )`
Note that it is not necessary to specify the credentials explicitly if you are logged into S3. The Pathway Live Data Framework can deduce them for you. For an authorized user, the code can be simplified as follows:
`pw.io.deltalake.write(access_log, "s3://logs/access-log/")`
**Writing to existing Delta** `decimal(p, s)` **columns.** When the destination Delta table already has a `decimal(p, s)` column and the Pathway Live Data Framework column written into it has type `str`, the writer parses each row’s decimal text into the underlying unscaled integer and stores it as a fixed-point value of the column’s declared precision and scale — no f64 detour, no precision loss. This is the symmetric counterpart to reading a Delta `decimal` column as `str`: a Delta `decimal` column read into the Pathway Live Data Framework, processed as text, and written back into the same Delta column round-trips with no loss.
A string that can’t be parsed as a decimal of the column’s shape (non-digit characters, more fractional digits than the column’s scale, or more total digits than its precision) fails the write with an error message naming the offending value, the column’s precision and scale, and the specific constraint it violated. Tables that don’t contain a `decimal` column are unaffected: writing a Pathway Live Data Framework `str` column into a fresh table or into an existing Delta `string` column behaves exactly as before.
---
# pw.io.mssql | Pathway
pw.io.mssql
===========
**This module is available when using one of the following licenses only:** [Pathway Scale, Pathway Enterprise](https://pathway.com/pricing)
.
Pathway Live Data Framework provides both **Input** and **Output** connectors for Microsoft SQL Server (MSSQL).
The **Input connector** supports two operating modes:
* **Streaming mode** (default) — uses SQL Server’s Change Data Capture (CDC) feature to track row-level changes in real time via the transaction log. Requires SQL Server Developer or Enterprise edition with CDC enabled at the database and table level:
`-- Enable CDC on the database EXEC sys.sp_cdc_enable_db; -- Enable CDC on the table EXEC sys.sp_cdc_enable_table @source_schema = N'dbo', @source_name = N'', @role_name = NULL;`
* **Static mode** — reads the full table once as a snapshot, then terminates.
**Primary key requirement**: the schema passed to the input connector must declare at least one primary key column using `pw.column_definition(primary_key=True)`. The connector uses these columns to track which rows have been inserted, updated, or deleted — without them it cannot maintain a consistent snapshot of the table.
**Persistence**: the input connector supports Live Data Framework persistence in both modes. When a `persistence_config` is supplied to `pw.run`, the connector saves the CDC Log Sequence Number (LSN) of the last processed change as its offset; on restart it skips the full table snapshot and resumes from that LSN, so downstream sees only the rows that changed since the last checkpoint. Persistence requires CDC to be enabled on the source table (the offset is the CDC LSN) — see the `read` docstring below for the behavior when CDC is missing or when the saved offset has fallen outside the CDC retention window.
The **Output connector** supports two operating modes:
* **Stream of changes mode** — appends every Live Data Framework update as a row with `time` and `diff` columns.
* **Snapshot mode** — maintains the current state of the Live Data Framework table using atomic `MERGE` upserts.
The connector uses a pure Rust TDS implementation (no ODBC drivers required) and is compatible with SQL Server 2017, 2019, 2022, and Azure SQL Edge.
[Type Conversion (Input Connector)](https://pathway.com/developers/api-docs/pathway-io/mssql#type-conversion-input-connector)
------------------------------------------------------------------------------------------------------------------------------
The table below describes how MS SQL Server column types are parsed into Live Data Framework values, and what type to declare in your `pw.Schema` to receive them correctly.
### [MS SQL Server types parsed by the input connector](https://pathway.com/developers/api-docs/pathway-io/mssql#ms-sql-server-types-parsed-by-the-input-connector)
| MS SQL Server type | Live Data Framework schema type and notes |
| --- | --- |
| `BIT` | `bool` |
| `TINYINT` | `int`. May also be declared as `float`. |
| `SMALLINT` / `INT2` | `int`. May also be declared as `float`. |
| `INT` / `INT4` | `int`. May also be declared as `float`. |
| `BIGINT` / `INT8` | `int`. May also be declared as `float`. Alternatively, declare as `pw.Duration` to interpret the value as **microseconds** — use this when the column was written by Live Data Framework’s output connector, which serializes `pw.Duration` as a `BIGINT` microsecond count. |
| `REAL` / `FLOAT4` | `float` |
| `FLOAT` / `DOUBLE PRECISION` / `FLOAT8` | `float` |
| `NUMERIC` / `DECIMAL` | `float` — converted via string representation. Precision loss is possible for values with more than ~15 significant digits. A scale-0 column (`NUMERIC(N, 0)`) may instead be declared as `int`; a value that does not fit in a 64-bit integer is reported as a per-row conversion error and the row is dropped. |
| `NVARCHAR` / `VARCHAR` / `CHAR` / `TEXT` / `NTEXT` | `str` |
| `NVARCHAR` / `VARCHAR` | `pw.Json` — the string is parsed as a JSON literal. The string form is what Live Data Framework’s output connector produces for `pw.Json` columns. |
| `NVARCHAR` / `VARCHAR` | `pw.Pointer` — the string is decoded as a Live Data Framework pointer. The string must have been produced by Live Data Framework’s output connector for a `pw.Pointer` column. |
| `NVARCHAR(MAX)` | `list` / `tuple` — the column must contain a JSON array as produced by Live Data Framework’s output connector. Elements are parsed recursively according to the declared inner types. |
| `NVARCHAR(MAX)` | `np.ndarray` — the column must contain a JSON object with keys `shape` (array dimension sizes) and `elements` (flat list of values), as produced by Live Data Framework’s output connector. Only `int` and `float` element types are supported. |
| `VARBINARY` / `BINARY` / `IMAGE` | `bytes` |
| `VARBINARY(MAX)` | `pw.PyObjectWrapper` — the binary payload is deserialized with bincode. The field must have been written by Live Data Framework’s output connector for a `pw.PyObjectWrapper` column. |
| `UNIQUEIDENTIFIER` | `str` — formatted as a standard hyphenated lowercase GUID string, e.g. `"6f9619ff-8b86-d011-b42d-00c04fc964ff"`. |
| `XML` | `str` — the raw XML text. |
| `DATETIME` / `DATETIME2` / `SMALLDATETIME` | `pw.DateTimeNaive` |
| `DATE` | `pw.DateTimeNaive` — midnight (`00:00:00`) on the given date. |
| `DATETIMEOFFSET` | `pw.DateTimeUtc` — the timezone offset is applied so that the result is in UTC. |
| `TIME` | `pw.Duration` — microseconds elapsed since midnight. |
| Any nullable column | Declare the field as optional in the schema. It will be parsed as `None` if the MSSQL value is `NULL`; otherwise the value is parsed as type `T`. If the schema field is **not** declared as optional and a `NULL` is received, an error is raised. |
[Type Conversion (Output Connector)](https://pathway.com/developers/api-docs/pathway-io/mssql#type-conversion-output-connector)
--------------------------------------------------------------------------------------------------------------------------------
The table below describes how Live Data Framework types are mapped to MS SQL Server column types in the output connector. All listed types can be round-tripped back via the input connector when the original schema type is specified.
### [Pathway types conversion into MS SQL Server](https://pathway.com/developers/api-docs/pathway-io/mssql#pathway-types-conversion-into-ms-sql-server)
| Live Data Framework type | MS SQL Server type and notes |
| --- | --- |
| `bool` | `BIT` |
| `int` | `BIGINT` |
| `float` | `FLOAT` |
| `str` | `NVARCHAR(MAX)`. When the column is part of the primary key, `NVARCHAR(450)` is used instead (SQL Server’s maximum index key width). |
| `pw.Pointer` | `NVARCHAR(MAX)`. When used as primary key, `NVARCHAR(450)`. |
| `bytes` | `VARBINARY(MAX)` |
| `pw.Json` | `NVARCHAR(MAX)` — the JSON value is serialized to a string. |
| `pw.DateTimeNaive` | `DATETIME2(6)` — microsecond precision. |
| `pw.DateTimeUtc` | `DATETIMEOFFSET(6)` — stored as UTC with a zero offset, microsecond precision. |
| `pw.Duration` | `BIGINT` — serialized as **microseconds**. Declare the column as `pw.Duration` on read to restore the original value. |
| `pw.PyObjectWrapper` | `VARBINARY(MAX)` — serialized with bincode. Declare the column as `pw.PyObjectWrapper` on read to restore the original value. |
| `Optional` | Nullable column of the corresponding non-optional type. `None` values are stored as `NULL`. |
| `tuple` | `NVARCHAR(MAX)` — serialized as a JSON array. Elements are converted recursively. Declare the column as `tuple` on read to restore the original value. |
| `list` | `NVARCHAR(MAX)` — serialized as a JSON array. Elements are converted recursively. Declare the column as a typed `list` on read to restore the original value. |
| `np.ndarray` | `NVARCHAR(MAX)` — serialized as a JSON object with keys `shape` (array dimension sizes) and `elements` (flat list of values). Declare the column as `np.ndarray` on read to restore the original value. |
[Performance](https://pathway.com/developers/api-docs/pathway-io/mssql#performance)
------------------------------------------------------------------------------------
The output connector streams each batch to SQL Server through the native bulk-load protocol (`INSERT BULK`) and is multi-threaded, so the write stream parallelizes across Pathway workers: each worker drives its own connection and its own bulk-load stream. Combined with the parallelized filesystem reader, the whole read-plus-write pipeline scales with the worker count.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and writing every row to SQL Server via the native bulk-load protocol — so they reflect **Pathway + the input source + SQL Server together, out of the box**, not SQL Server’s standalone ingestion ceiling.
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the SQL Server data directory. SQL Server ran as the stock `mcr.microsoft.com/mssql/server:2022-latest` Docker image (Developer edition) at its default configuration. The Pathway and SQL Server containers were each pinned to their own core-complex die (6 cores with a private 32 MiB L3).
**Throughput.** End-to-end wall-clock time to read a 3 M-row, 64-shard CSV dataset (**≈ 0.14 GB**) and land every row in SQL Server, swept over the number of Pathway workers (median of 3 runs):
### [SQL Server write throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/mssql#sql-server-write-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 15.3 s | ≈ 196 600 rows/s | 1.00× |
| 2 | 13.0 s | ≈ 230 200 rows/s | 1.17× |
| 4 | 11.3 s | ≈ 264 600 rows/s | 1.35× |
| 8 | 10.2 s | ≈ 293 500 rows/s | 1.49× |
Throughput increases at every step of the sweep, reaching **~293 500 rows/s** on 8 workers (1.49×), and every run passed the data-integrity checks. The scaling is sub-linear — one bulk writer already moves a large share of the data, so each added worker contributes less — but SQL Server sits among the faster sinks measured, within range of the binary-`COPY`/native-bulk sinks (PostgreSQL, ClickHouse, QuestDB).
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/mssql-bulk-write)
.
[**read**(connection\_string, table\_name, schema, \*, mode='streaming', schema\_name='dbo', autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None)](https://pathway.com/developers/api-docs/pathway-io/mssql#pathway.io.mssql.read)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mssql/__init__.py#L36-L271)
Reads a table from a Microsoft SQL Server database.
In `"static"` mode, the connector issues a plain `SELECT` against the table, emits all rows, and terminates. No special database configuration is required beyond normal read access to the table. Works on any SQL Server edition, including Express.
In `"streaming"` mode (the default), the connector uses MSSQL’s Change Data Capture (CDC) feature to track changes via the transaction log. This requires:
* SQL Server Developer or Enterprise edition
* CDC enabled on the database: `EXEC sys.sp_cdc_enable_db;`
* CDC enabled on the table: `EXEC sys.sp_cdc_enable_table @source_schema=N'dbo', @source_name=N'', @role_name=NULL;`
**Primary key**: the schema must declare at least one primary key column via `pw.column_definition(primary_key=True)`. The connector uses these columns to track which rows have been inserted, updated, or deleted — without them it cannot maintain a consistent snapshot of the table.
**Persistence**: when persistence is enabled, the connector saves the CDC Log Sequence Number (LSN) of the last processed change as its offset. On restart it skips the full table snapshot and resumes from that LSN, so downstream sees only the rows that changed since the last checkpoint — no re-delivery of the original table contents. Passing an explicit `name` is optional — Pathway Live Data Framework will auto-generate one if omitted — but setting it makes the saved state easier to identify in the persistence directory and protects against accidental mismatches when the pipeline graph changes between runs.
Persistence applies to both modes. In `"streaming"` mode the connector keeps running after the catch-up and continues delivering live CDC events. In `"static"` mode it emits the delta accumulated since the previous run and terminates.
Persistence requires CDC on the target table — the LSN comes from CDC. If you pass a `persistence_config` to `pw.run` but CDC has not been enabled on the table, the pipeline aborts at startup with an error pointing you at `sp_cdc_enable_table`; it does not silently fall back to re-reading the whole table on every restart.
If the saved LSN predates the capture instance’s current retention window (SQL Server’s CDC cleanup job runs independently of any consumer and drops changes older than the configured retention, 4320 minutes by default), the connector raises an error on startup asking you to clear the persistence directory and re-snapshot. Pick a retention long enough to cover your longest expected downtime.
The connection uses the TDS protocol via a pure Rust implementation (no ODBC drivers required), so it works on any Linux environment without additional system dependencies. Compatible with SQL Server 2017, 2019, 2022, and Azure SQL Edge.
* **Parameters**
* **connection\_string** (`str`) – ADO.NET-style connection string for the MSSQL database. Example: `"Server=tcp:localhost,1433;Database=mydb;User Id=sa;Password=pass;TrustServerCertificate=true"`
* **table\_name** (`str`) – Name of the table to read from.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **mode** (`Literal`\[`'static'`, `'streaming'`\]) – `"streaming"` (the default) uses CDC for real-time change tracking via the transaction log; requires CDC to be enabled on the database and table. `"static"` reads the full table once as a snapshot, then terminates; no CDC setup is needed.
* **schema\_name** (`str`) – Name of the database schema containing the table. Defaults to `"dbo"`, which is the default schema in MSSQL.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment.
* **debug\_data** (`Any`) – Static data to use instead of the external source (for testing).
* **Returns**
_Table_ – The table read.
Example:
To test this connector locally, you can run a MSSQL instance using Docker:
`docker run -e 'ACCEPT_EULA=Y' -e 'MSSQL_SA_PASSWORD=YourStrong!Passw0rd' \ -p 1433:1433 mcr.microsoft.com/mssql/server:2022-latest`
For static snapshot mode (no CDC setup required):
`import pathway as pw class MySchema(pw.Schema): id: int = pw.column_definition(primary_key=True) name: str value: float table = pw.io.mssql.read( connection_string="Server=tcp:localhost,1433;Database=testdb;" "User Id=sa;Password=YourStrong!Passw0rd;TrustServerCertificate=true", table_name="my_table", schema=MySchema, mode="static", )`
For streaming mode with CDC, first enable CDC on the database and the table (run these once in SQL Server Management Studio or via `sqlcmd`):
`-- Enable CDC on the database EXEC sys.sp_cdc_enable_db; -- Enable CDC on the table EXEC sys.sp_cdc_enable_table @source_schema = N'dbo', @source_name = N'my_table', @role_name = NULL;`
Then read from it using streaming mode:
`table = pw.io.mssql.read( connection_string="Server=tcp:localhost,1433;Database=testdb;" "User Id=sa;Password=YourStrong!Passw0rd;TrustServerCertificate=true", table_name="my_table", schema=MySchema, )`
**Persistence.** Pass a `persistence_config` to `pw.run`. CDC must be enabled on the table — without it the pipeline aborts at startup with a clear error. Persistence works the same way in both modes, the only difference is what the pipeline does once the delta is consumed:
`persistence_config = pw.persistence.Config( backend=pw.persistence.Backend.filesystem("./PStorage") )`
_Streaming mode_ (the default). The first run delivers the initial snapshot and then keeps running to push live CDC events; every subsequent run skips the snapshot and starts with the delta since the previous checkpoint before continuing to stream:
`table = pw.io.mssql.read( connection_string="Server=tcp:localhost,1433;Database=testdb;" "User Id=sa;Password=YourStrong!Passw0rd;TrustServerCertificate=true", table_name="my_table", schema=MySchema, ) pw.io.jsonlines.write(table, "output.jsonl") pw.run(persistence_config=persistence_config)`
_Static mode._ The first run dumps the full table and terminates; every subsequent run emits only the CDC delta accumulated since the previous run and terminates — handy for scheduled batch pipelines that want change-set semantics without a long-lived process:
`table = pw.io.mssql.read( connection_string="Server=tcp:localhost,1433;Database=testdb;" "User Id=sa;Password=YourStrong!Passw0rd;TrustServerCertificate=true", table_name="my_table", schema=MySchema, mode="static", ) pw.io.jsonlines.write(table, "output.jsonl") pw.run(persistence_config=persistence_config)`
[**write**(table, connection\_string, table\_name, \*, schema\_name='dbo', max\_batch\_size=None, init\_mode='default', output\_table\_type='stream\_of\_changes', primary\_key=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/mssql#pathway.io.mssql.write)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mssql/__init__.py#L274-L494)
Writes `table` to a Microsoft SQL Server table.
The connector works in two modes: **snapshot** mode and **stream of changes**. In **snapshot** mode, the table maintains the current snapshot of the data using MSSQL’s `MERGE` statement for atomic upserts. In **stream of changes** mode, the table contains the log of all data updates with `time` and `diff` columns.
Compatible with all MSSQL versions on Linux (SQL Server 2017, 2019, 2022, and Azure SQL Edge). Uses pure Rust TDS implementation — no ODBC drivers required.
Writes use SQL Server’s native bulk-load protocol (`INSERT BULK`): each minibatch is streamed to the server in a single bulk transfer instead of row-by-row `INSERT` statements. In **stream of changes** mode the rows are bulk-loaded straight into the target table when possible; otherwise (and always in **snapshot** mode) they are bulk-loaded into a temporary staging table and applied to the target with one set-based `INSERT` / `MERGE` / `DELETE`. Throughput scales with minibatch size, so larger `max_batch_size` values (or fewer, larger commits) write faster.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **connection\_string** (`str`) – ADO.NET-style connection string for the MSSQL database. Example: `"Server=tcp:localhost,1433;Database=mydb;User Id=sa;Password=pass;TrustServerCertificate=true"`
* **table\_name** (`str`) – Name of the target table.
* **schema\_name** (`str`) – Name of the database schema containing the table. Defaults to `"dbo"`, which is the default schema in MSSQL.
* **max\_batch\_size** (`int` | `None`) – Maximum number of entries allowed to be committed within a single transaction. Larger values mean fewer, larger bulk transfers and therefore higher write throughput.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – `"default"`: The default initialization mode; `"create_if_not_exists"`: creates the table if it does not exist; `"replace"`: drops and recreates the table.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – Defines how the output table manages its data. If set to `"stream_of_changes"` (the default), the system outputs a stream of modifications with `time` and `diff` columns. If set to `"snapshot"`, the table maintains the current state using atomic MERGE upserts.
* **primary\_key** (`list`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\] | `None`) – When using snapshot mode, one or more columns that form the primary key in the target MSSQL table.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
To test this connector locally, run a MSSQL instance using Docker:
`docker run -e 'ACCEPT_EULA=Y' -e 'MSSQL_SA_PASSWORD=YourStrong!Passw0rd' \ -p 1433:1433 mcr.microsoft.com/mssql/server:2022-latest`
Then write to it:
`import pathway as pw table = pw.debug.table_from_markdown(''' key | value 1 | Hello 2 | World ''')`
Stream of changes mode:
`pw.io.mssql.write( table, "Server=tcp:localhost,1433;Database=testdb;" "User Id=sa;Password=YourStrong!Passw0rd;TrustServerCertificate=true", table_name="test", init_mode="create_if_not_exists", )`
Snapshot mode:
`pw.io.mssql.write( table, "Server=tcp:localhost,1433;Database=testdb;" "User Id=sa;Password=YourStrong!Passw0rd;TrustServerCertificate=true", table_name="test_snapshot", init_mode="create_if_not_exists", output_table_type="snapshot", primary_key=[table.key], )`
You can run this pipeline with `pw.run()`.
[Pathway Io\
\
pw.io.mqtt](https://pathway.com/developers/api-docs/pathway-io/mqtt)
[Pathway Io\
\
pw.io.mysql](https://pathway.com/developers/api-docs/pathway-io/mysql)
---
# pw.io.mysql | Pathway
pw.io.mysql
===========
**This module is available when using one of the following licenses only:** [Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise](https://pathway.com/pricing)
.
The Pathway Live Data Framework provides both **Input** and **Output** connectors for MySQL. See the `read` and `write` documentation below for the modes, requirements, and options specific to each. The type conversions for both directions are given in the tables below.
[Type Conversion (Input Connector)](https://pathway.com/developers/api-docs/pathway-io/mysql#type-conversion-input-connector)
------------------------------------------------------------------------------------------------------------------------------
The table below describes how MySQL column types are parsed into Pathway Live Data Framework values, and what type to declare in your `pw.Schema` to receive them correctly. Every type produced by the output connector round-trips back through the input connector when the original schema type is specified.
### [MySQL types parsed by the input connector](https://pathway.com/developers/api-docs/pathway-io/mysql#mysql-types-parsed-by-the-input-connector)
| MySQL type | Pathway Live Data Framework schema type and notes |
| --- | --- |
| `TINYINT(1)` / `BOOLEAN` | `bool` |
| `TINYINT` / `SMALLINT` / `MEDIUMINT` / `INT` / `BIGINT` (incl. `UNSIGNED`) | `int`. May also be declared as `float`. An `UNSIGNED BIGINT` value above the signed 64-bit maximum (`9223372036854775807`) is reported as a per-row conversion error. |
| `DECIMAL` / `NUMERIC` | `float` — parsed from the textual representation; precision loss is possible beyond ~15 significant digits. A scale-0 column may instead be declared as `int`. |
| `FLOAT` | `float` |
| `DOUBLE` | `float` |
| `CHAR` / `VARCHAR` / `TINYTEXT` / `TEXT` / `MEDIUMTEXT` / `LONGTEXT` / `ENUM` / `SET` | `str` |
| `VARCHAR` / `TEXT` | `pw.Json` — the string is parsed as a JSON literal. This is what the output connector produces for `pw.Json` columns stored in a non-`JSON` column. |
| `JSON` | `pw.Json` |
| `VARCHAR` / `TEXT` | `pw.Pointer` — the string is decoded as a Pathway Live Data Framework pointer. The string must have been produced by the output connector for a `pw.Pointer` column. |
| `BINARY` / `VARBINARY` / `TINYBLOB` / `BLOB` / `MEDIUMBLOB` / `LONGBLOB` | `bytes` |
| `BLOB` | `pw.PyObjectWrapper` — the binary payload is deserialized with bincode. The field must have been written by the output connector for a `pw.PyObjectWrapper` column. |
| `DATE` | `pw.DateTimeNaive` — midnight (`00:00:00`) on the given date. |
| `DATETIME` / `TIMESTAMP` | `pw.DateTimeNaive` |
| `DATETIME` | `pw.DateTimeUtc` — the stored wall-clock value is interpreted as UTC. This matches how the output connector stores `pw.DateTimeUtc`. |
| `TIME` | `pw.Duration` — MySQL’s `TIME` range is limited to ±838:59:59, so durations outside that range do not round-trip. |
| `YEAR` | `int` |
| Any nullable column | Declare the field as optional in the schema. It is parsed as `None` if the MySQL value is `NULL`; otherwise the value is parsed as type `T`. If the field is **not** declared optional and a `NULL` is received, a per-row conversion error is raised. |
[Type Conversion (Output Connector)](https://pathway.com/developers/api-docs/pathway-io/mysql#type-conversion-output-connector)
--------------------------------------------------------------------------------------------------------------------------------
The table below explains how Pathway Live Data Framework engine data is serialized into MySQL. You can convert unsupported types to supported ones yourself (for example, serialize an array to JSON) using [user-defined functions](https://pathway.com/developers/user-guide/data-transformation/user-defined-functions/)
if needed.
### [Pathway Live Data Framework types conversion into MySQL](https://pathway.com/developers/api-docs/pathway-io/mysql#pathway-live-data-framework-types-conversion-into-mysql)
| Pathway Live Data Framework type | MySQL type |
| --- | --- |
| `bool` | `BOOLEAN` (`TINYINT(1)`) |
| `int` | `BIGINT`. If the field type corresponds to a different integral type, the connector will also attempt to cast the value accordingly. |
| `float` | `DOUBLE`. If the field type is `FLOAT`, the connector will also attempt to cast the value accordingly. |
| `pointer` | `TEXT`. If the type is `VARCHAR`, the connector will cast the value accordingly. Declare the column as `pw.Pointer` on read to restore the original value. |
| `str` | `TEXT`. If the type is `VARCHAR`, the connector will cast the value accordingly. |
| `bytes` | `BLOB` |
| `Naive DateTime` | `DATETIME(6)`, serialized with microsecond precision. |
| `UTC DateTime` | `DATETIME(6)`, serialized with microsecond precision. The value is casted into the UTC time zone. Declare the column as `pw.DateTimeUtc` on read to restore the original value. |
| `Duration` | `TIME(6)`, serialized with a microsecond precision. MySQL’s `TIME` range is limited to ±838:59:59. |
| `JSON` | `JSON` |
| `np.ndarray` | Not supported, as there are no array types in MySQL. |
| `tuple` | Not supported, as there are no array types in MySQL. |
| `list` | Not supported, as there are no array types in MySQL. |
| `pw.PyObjectWrapper` | `BLOB` — serialized with bincode. Declare the column as `pw.PyObjectWrapper` on read to restore the original value. |
[Performance](https://pathway.com/developers/api-docs/pathway-io/mysql#performance)
------------------------------------------------------------------------------------
The output connector bulk-writes each batch and is multi-threaded, so the write stream parallelizes across Pathway workers: each worker drives its own MySQL connection. At start-up the connector probes the server and selects a write path — `LOAD DATA LOCAL INFILE` when the server allows it (`local_infile=ON`), chunked multi-row `INSERT` otherwise. Combined with the parallelized filesystem reader, the whole read-plus-write pipeline scales with the worker count.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and writing every row to MySQL — so they reflect **Pathway + the input source + MySQL together**, not MySQL’s standalone ingestion ceiling.
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the MySQL data directory. MySQL ran as the `mysql:8.0` Docker image configured for write throughput — relaxed durability (`innodb_flush_log_at_trx_commit=2`, `sync_binlog=0`, `innodb_doublewrite=0`) plus a 4 GiB buffer pool and a 4 GiB redo log — so the write is not gated by a per-commit `fsync`. The Pathway and MySQL containers were each pinned to their own core-complex die (6 cores with a private 32 MiB L3).
**Throughput.** End-to-end wall-clock time to read a 5 M-row, 64-shard CSV dataset (**≈ 0.23 GB**) and land every row in MySQL, swept over the number of Pathway workers (median of 3 runs):
### [MySQL write throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/mysql#mysql-write-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 26.0 s | ≈ 192 300 rows/s | 1.00× |
| 2 | 21.9 s | ≈ 228 700 rows/s | 1.19× |
| 4 | 20.5 s | ≈ 244 400 rows/s | 1.27× |
| 8 | 17.9 s | ≈ 278 900 rows/s | 1.45× |
Throughput scales across the whole sweep, reaching **~279 000 rows/s** on 8 workers (1.45×), and every run passed the data-integrity checks. The scaling is sub-linear because all workers write into a single InnoDB table and contend on its redo buffer and clustered-index hot spot; partitioning the target table (or writing to several tables) would let concurrent writers scale further.
**NOTE**: These numbers are measured with relaxed durability — a benchmark-only server configuration with no per-commit `fsync`. On the stock `mysql:8.0` durability settings the same pipeline lands ≈ 52 800 rows/s at one worker and does not scale with workers: the default `innodb_flush_log_at_trx_commit=1` / `sync_binlog=1` perform an `fsync` of the redo and binary logs on every commit, so throughput is bounded by the disk’s durable-commit rate — a server-wide ceiling that a single bulk writer already reaches.
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/mysql-bulk-write)
.
[**read**(connection\_string, table\_name, schema, \*, mode='streaming', server\_id=None, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None)](https://pathway.com/developers/api-docs/pathway-io/mysql#pathway.io.mysql.read)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mysql/__init__.py#L23-L242)
Reads a table from a MySQL database.
In `"static"` mode, the connector issues a plain `SELECT` against the table, emits all rows, and terminates. No special server configuration is required beyond read access to the table.
In `"streaming"` mode (the default), the connector performs Change Data Capture by reading MySQL’s **binary log** (binlog). It first reads a snapshot of the table, then continuously tails the binary log, delivering every insert, update, and delete as it happens. This requires the MySQL server to be configured for row-based binary logging:
* `log_bin` enabled (start `mysqld` with `--log-bin`; on by default in MySQL 8.0+),
* `binlog_format=ROW` (the default in MySQL 8.0+),
* `binlog_row_image=FULL` (the default),
and the connecting user to hold the `REPLICATION SLAVE` and `REPLICATION CLIENT` privileges (`GRANT REPLICATION SLAVE, REPLICATION CLIENT ON *.* TO `).
**Primary key**: the schema must declare at least one primary-key column via `pw.column_definition(primary_key=True)`. These columns identify each row so the connector can correlate snapshot rows with subsequent binlog inserts, updates, and deletes.
**No server-side footprint**: unlike PostgreSQL logical replication, reading the MySQL binary log creates **no persistent state on the server** — there is no replication slot to leave behind. A disconnected or idle reader therefore cannot cause the server’s disk to fill up: binary-log retention is governed solely by the server’s own `binlog_expire_logs_seconds` / `max_binlog_size` settings, independently of any reader.
**Persistence**: when persistence is enabled (by passing a `persistence_config` to `pw.run`), the streaming connector saves the binary-log coordinates (file name and position) of the last processed change as its offset. On restart it skips the snapshot and resumes tailing from that position. If the saved binary-log file has since been purged by the server’s normal log expiry — which happens only if Pathway was offline longer than the server’s binary-log retention — the connector raises a clear error at startup asking you to clear the persistence directory and re-snapshot, rather than silently losing data. Choose a binary-log retention long enough to cover your longest expected downtime. Binary-log coordinates are specific to one MySQL server: if you restore the server from a backup or fail over to a different host, clear the persistence directory. Persistence applies to `"streaming"` mode; in `"static"` mode every run re-reads the full table.
* **Parameters**
* **connection\_string** (`str`) – [Connection string](https://dev.mysql.com/doc/connector-j/en/connector-j-reference-jdbc-url-format.html)
for the MySQL database. It must include the database name, e.g. `"mysql://user:password@localhost:3306/mydb"`.
* **table\_name** (`str`) – Name of the table to read from.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table.
* **mode** (`Literal`\[`'static'`, `'streaming'`\]) – `"streaming"` (the default) reads a snapshot and then tails the binary log for live changes; requires row-based binary logging. `"static"` reads the full table once as a snapshot, then terminates; no binary-log configuration is needed.
* **server\_id** (`int` | `None`) – The replica server id used when registering for the binary-log stream. It must be unique among everything replicating from the source server. If omitted, a random value is chosen on each run; set it explicitly if you run several readers against the same server and want stable identifiers.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every `autocommit_duration_ms` milliseconds, the updates received by the connector are committed and pushed into Pathway’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment.
* **debug\_data** (`Any`) – Static data to use instead of the external source (for testing).
* **Returns**
_Table_ – The table read.
Example:
To test this connector locally, run a MySQL instance with binary logging enabled (it is on by default in the `mysql:8.0` image):
`docker run --name mysql-container \ -e MYSQL_ROOT_PASSWORD=rootpass \ -e MYSQL_DATABASE=testdb \ -e MYSQL_USER=testuser \ -e MYSQL_PASSWORD=testpass \ -p 3306:3306 \ mysql:8.0`
Grant the replication privileges the binary-log reader needs (run once):
`GRANT REPLICATION SLAVE, REPLICATION CLIENT ON *.* TO 'testuser'@'%';`
For a one-off static read (no binary-log setup required):
`import pathway as pw class MySchema(pw.Schema): id: int = pw.column_definition(primary_key=True) name: str value: float table = pw.io.mysql.read( "mysql://testuser:testpass@localhost:3306/testdb", table_name="my_table", schema=MySchema, mode="static", )`
For streaming change data capture from the binary log, simply use the default mode:
`table = pw.io.mysql.read( "mysql://testuser:testpass@localhost:3306/testdb", table_name="my_table", schema=MySchema, )`
The resulting table can be transformed with the usual Pathway operators and written to any sink. For example, to mirror the table into another MySQL table in real time:
`pw.io.mysql.write( table, "mysql://testuser:testpass@localhost:3306/testdb", table_name="my_table_copy", init_mode="create_if_not_exists", output_table_type="snapshot", primary_key=[table.id], ) pw.run()`
To enable persistence so a restarted pipeline resumes from where it left off, pass a `persistence_config` to `pw.run`:
`persistence_config = pw.persistence.Config( backend=pw.persistence.Backend.filesystem("./PStorage") ) table = pw.io.mysql.read( "mysql://testuser:testpass@localhost:3306/testdb", table_name="my_table", schema=MySchema, name="my_mysql_source", ) pw.io.jsonlines.write(table, "output.jsonl") pw.run(persistence_config=persistence_config)`
[**write**(table, connection\_string, table\_name, \*, max\_batch\_size=None, init\_mode='default', output\_table\_type='stream\_of\_changes', primary\_key=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/mysql#pathway.io.mysql.write)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mysql/__init__.py#L245-L441)
Writes `table` to a MySQL table.
The connector works in two modes: **snapshot** mode and **stream of changes**. In **snapshot** mode, the table maintains the current snapshot of the data. In **stream of changes** mode, the table contains the log of all data updates. For stream of changes you also need to have two columns, `time` and `diff` of the integer type, where `time` stores the transactional minibatch time and `diff` is `1` for row insertion or `-1` for row deletion.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **connection\_string** (`str`) – [Connection string](https://dev.mysql.com/doc/connector-j/en/connector-j-reference-jdbc-url-format.html)
for MySQL database.
* **table\_name** (`str`) – Name of the target table.
* **max\_batch\_size** (`int` | `None`) – Maximum number of entries allowed to be committed within a single transaction.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – `"default"`: The default initialization mode; `"create_if_not_exists"`: initializes the SQL writer by creating the necessary table if they do not already exist; `"replace"`: Initializes the SQL writer by replacing any existing table.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – Defines how the output table manages its data. If set to `"stream_of_changes"` (the default), the system outputs a stream of modifications to the target table. This stream includes two additional integer columns: `time`, representing the computation minibatch, and `diff`, indicating the type of change (`1` for row addition and `-1` for row deletion). If set to `"snapshot"`, the table maintains the current state of the data, updated atomically with each minibatch and ensuring that no partial minibatch updates are visible.
* **primary\_key** (`list`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\] | `None`) – When using snapshot mode, one or more columns that form the primary key in the target MySQL table.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
To test this connector locally, you will need a MySQL instance. The easiest way to do this is to run a Docker image. For example, you can use the mysql image. Pull and run it as follows:
`docker pull mysql docker run --name mysql-container -e MYSQL_ROOT_PASSWORD=rootpass -e MYSQL_DATABASE=testdb -e MYSQL_USER=testuser -e MYSQL_PASSWORD=testpass -p 3306:3306 mysql:8.0`
The first command pulls the image from the Docker repository while the second runs it, setting the credentials for the user and the database name.
The database is now created and you can use the connector to write data to a table. First, you will need a Pathway Live Data Framework table for testing. You can create it as follows:
`import pathway as pw table = pw.debug.table_from_markdown(''' key | value 1 | Hello 2 | World ''')`
You can write this table using:
`pw.io.mysql.write( table, "mysql://testuser:testpass@localhost:3306/testdb", table_name="test", init_mode="create_if_not_exists", )`
The `init_mode` parameter set to `"create_if_not_exists"` ensures that the table is created by the framework if it does not already exist.
You can run this pipeline with `pw.run()`.
After the pipeline completes, you can connect to the database from the command line:
`docker exec -it mysql-container mysql -u testuser -p`
Enter the password set when creating the database, in this example it is `testpass`.
You can check the data in the table with a simple command:
`select * from test;`
Note that if you run the code again, it will append data to this table. To overwrite the entire table, use `init_mode` set to `"replace"`.
Now suppose that the table is dynamic and you need to maintain a snapshot of the data. In this case it makes sense to use snapshot mode. For snapshot mode you need to choose which columns will form the primary key. For this example suppose it is the `key` column. If the output table is called `test_snapshot` the code will look as follows:
`pw.io.mysql.write( table, "mysql://testuser:testpass@localhost:3306/testdb", table_name="test_snapshot", init_mode="create_if_not_exists", output_table_type="snapshot", primary_key=[table.key], )`
**Note**: The table can be created in MySQL by the Pathway Live Data Framework when `init_mode` is set to `"replace"` or when it is set to `"create_if_not_exists"`. However, when creating a table for snapshot mode, the Pathway Live Data Framework defines the primary key. If you use string or binary objects as a primary key, there is a limitation because these fields cannot serve as a primary key. Instead, you need to use for example a `VARCHAR` with a length limit depending on your specific use case. Therefore, if you plan to use strings or blobs as primary keys, make sure that the table with the correct schema is created manually in advance.
[Pathway Io\
\
pw.io.mssql](https://pathway.com/developers/api-docs/pathway-io/mssql)
[Pathway Io\
\
pw.io.nats](https://pathway.com/developers/api-docs/pathway-io/nats)
---
# pw.io.sqlite | Pathway
pw.io.sqlite
============
Pathway Live Data Framework provides both **Input** and **Output** connectors for [SQLite](https://www.sqlite.org/)
.
[Storage Classes](https://pathway.com/developers/api-docs/pathway-io/sqlite#storage-classes)
---------------------------------------------------------------------------------------------
SQLite only has five native storage classes — `NULL`, `INTEGER`, `REAL`, `TEXT` and `BLOB` (see [Datatypes In SQLite](https://www.sqlite.org/datatype3.html)
). Pathway has many more value variants, so types that lack a native mapping are stored as `TEXT` using the exact JSON encoding produced by [`pathway.io.jsonlines.write()`](https://pathway.com/developers/api-docs/pathway-io-jsonlines#pathway.io.jsonlines.write)
. The same encoding is understood by the input connector, so a `write` / `read` pair round-trips every supported Pathway Live Data Framework type losslessly.
[Type Conversion (Input Connector)](https://pathway.com/developers/api-docs/pathway-io/sqlite#type-conversion-input-connector)
-------------------------------------------------------------------------------------------------------------------------------
The table below describes how SQLite column values are parsed into Pathway Live Data Framework values, and what type to declare in your `pw.Schema` to receive them correctly.
### [SQLite storage parsed by the input connector](https://pathway.com/developers/api-docs/pathway-io/sqlite#sqlite-storage-parsed-by-the-input-connector)
| Framework schema type | SQLite storage class | Encoding / notes |
| --- | --- | --- |
| `int` | `INTEGER` | As-is. |
| `float` | `REAL` or `INTEGER` | As-is for `REAL`; `INTEGER` values are implicitly widened to `f64` so integer-valued literals in a float column still parse. |
| `bool` | `INTEGER` or `TEXT` | `0` / `1` in `INTEGER`; or PostgreSQL-style literals in `TEXT` — `true` / `false`, `yes` / `no`, `on` / `off`, `t` / `f`, `y` / `n`, `1` / `0` (case-insensitive, surrounding whitespace ignored). |
| `str` | `TEXT` | UTF-8 text. |
| `bytes` | `BLOB` | Raw bytes. |
| `pw.DateTimeNaive` | `TEXT` | `%Y-%m-%dT%H:%M:%S%.f` (ISO-8601, written by the framework), or `%Y-%m-%d %H:%M:%S%.f` (SQL-92 with space separator, as produced by SQLite’s `CURRENT_TIMESTAMP` / `datetime()`). Fractional seconds are optional in both forms. |
| `pw.DateTimeUtc` | `TEXT` | `%Y-%m-%dT%H:%M:%S%.f%z` or `%Y-%m-%d %H:%M:%S%.f%z` — e.g. `2026-01-15T10:30:00+0000` or `2026-01-15 10:30:00+0000`. |
| `pw.Duration` | `INTEGER` | Nanoseconds. |
| `pw.Json` | `TEXT` | A JSON document stored verbatim. |
| `pw.Pointer` | `TEXT` | Pathway Live Data Framework’s base32 pointer encoding, e.g. `^Z5QKEQ…`. |
| `tuple` or `list` (generic) | `TEXT` | JSON array — each element is encoded as it would be in [`pathway.io.jsonlines.write()`](https://pathway.com/developers/api-docs/pathway-io-jsonlines#pathway.io.jsonlines.write)
(e.g. `bytes` as base64, nested tuples as nested arrays). |
| `np.ndarray` | `TEXT` | JSON object with a `shape` integer array and a flat `elements` array, row-major. Only `int` and `float` element types are supported. |
| `pw.PyObjectWrapper` | `TEXT` | Base64-encoded `bincode` payload produced by the output connector. |
| Any nullable column | `NULL` or any of the above | `NULL` is read as `None`; non-null values follow the mapping above. |
[Type Conversion (Output Connector)](https://pathway.com/developers/api-docs/pathway-io/sqlite#type-conversion-output-connector)
---------------------------------------------------------------------------------------------------------------------------------
Pathway Live Data Framework values are written back into the storage classes the input connector accepts — all types round-trip losslessly when the destination column has the encoding shown below.
### [Framework types written by the output connector](https://pathway.com/developers/api-docs/pathway-io/sqlite#framework-types-written-by-the-output-connector)
| Framework type | SQLite storage class | Encoding |
| --- | --- | --- |
| `bool` | `INTEGER` | `1` for `True`, `0` for `False`. |
| `int` | `INTEGER` | As-is. |
| `float` | `REAL` | As-is. |
| `str` | `TEXT` | UTF-8. |
| `bytes` | `BLOB` | Raw bytes. |
| `pw.DateTimeNaive` | `TEXT` | `%Y-%m-%dT%H:%M:%S.%9f` — nanosecond precision. |
| `pw.DateTimeUtc` | `TEXT` | `%Y-%m-%dT%H:%M:%S.%9f%z`. |
| `pw.Duration` | `INTEGER` | Nanoseconds. |
| `pw.Json` | `TEXT` | Serialized JSON document. |
| `pw.Pointer` | `TEXT` | Pathway Live Data Framework’s base32 pointer encoding. |
| `tuple` or `list` (generic) | `TEXT` | JSON array; leaf values encoded per the jsonlines rules. |
| `np.ndarray` | `TEXT` | JSON object with a `shape` integer array and a flat `elements` array. |
| `pw.PyObjectWrapper` | `TEXT` | Base64-encoded `bincode` payload. |
| `None` (in optional columns) | `NULL` | — |
[Output Connector: Initialization and Schema Checks](https://pathway.com/developers/api-docs/pathway-io/sqlite#output-connector-initialization-and-schema-checks)
------------------------------------------------------------------------------------------------------------------------------------------------------------------
The output connector uses `init_mode` to decide what state the destination table should be in before the first write:
* `"default"` — the table must already exist. The writer verifies at construction time that it is present and carries every column it will `INSERT` into (the columns of the Live Data Framework table, plus `time` / `diff` in `stream_of_changes` mode). A `ValueError` is raised if the table is missing or its columns do not match.
* `"create_if_not_exists"` — equivalent to a `CREATE TABLE IF NOT EXISTS` with columns derived from the Live Data Framework table. If the SQLite table already exists, the same compatibility check as `"default"` runs.
* `"replace"` — drops the existing SQLite table first, then recreates it from the Live Data Framework table.
For every mode, the path must point at a valid SQLite 3 database (an empty or missing file is accepted — SQLite treats it as a new empty database that the writer may populate). Pointing the writer at a `VIEW`, index, or trigger is rejected at construction: SQLite does not accept direct `INSERT` into these objects.
**Generated columns.** Columns declared as `GENERATED ALWAYS AS (...)` (stored or virtual) cannot be written to. If the Live Data Framework table has a column that matches a generated column in the SQLite table, the writer raises `ValueError` and asks you to drop that column from the Live Data Framework table — the reader still returns its computed value on `SELECT`.
**NOT NULL columns.** When the destination SQLite table has an extra `NOT NULL` column without a `DEFAULT` that the Live Data Framework table does not have, the writer raises `ValueError` naming the missing column(s). The `INTEGER PRIMARY KEY` rowid alias is exempt (SQLite auto-assigns it), but only for a _single_\-column `INTEGER PRIMARY KEY` on a regular (rowid) table — `WITHOUT ROWID` tables and composite primary keys have no rowid alias, so every `NOT NULL` column there must be supplied. The mirror case is also caught: if a column is optional in the Live Data Framework table, but the matching destination column is `NOT NULL` and not the rowid alias, the writer rejects it — relax one side or the other.
[Output Connector: Concurrency and the Single-Writer Constraint](https://pathway.com/developers/api-docs/pathway-io/sqlite#output-connector-concurrency-and-the-single-writer-constraint)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
SQLite permits only one writer per database _file_ at a time — the write lock is taken on the whole file, not on the individual table. Pathway accounts for this in two ways:
* All writes for a single `pw.io.sqlite.write` run on one worker, even when Pathway runs with several workers. SQLite cannot write to a file in parallel regardless, so this costs no throughput while keeping the output complete and deterministic.
* When more than one writer targets the same file — most commonly two `pw.io.sqlite.write` calls writing to different tables in the same database — each writer waits up to 30 seconds for the file’s write lock before giving up, so independent writers take turns instead of failing immediately with `database is locked`.
Writing several tables into a single database file therefore works, but is **not recommended**. The writers serialize on the one file lock, so there is no concurrency benefit, and a writer that holds the lock for longer than 30 seconds (for example while committing a very large batch) can still make a waiting writer time out and abort the run. When you need independent tables, prefer a separate database file per table.
[Output Connector: Snapshot Mode](https://pathway.com/developers/api-docs/pathway-io/sqlite#output-connector-snapshot-mode)
----------------------------------------------------------------------------------------------------------------------------
When `output_table_type="snapshot"`, `primary_key` must list one or more columns of `table` that identify each row in the destination. It is required in snapshot mode and not allowed otherwise.
Primary-key columns must be non-nullable: SQLite’s `INTEGER PRIMARY KEY` silently replaces a `NULL` value with an auto-assigned rowid, which can collide with later UPSERTs and cause silent data loss. A `ValueError` is raised at `write()` time if any primary-key column is declared nullable.
When `init_mode="default"` or `"create_if_not_exists"` is used and the destination table already exists, it must carry a _full_ (non-partial) `PRIMARY KEY` or `UNIQUE` constraint whose columns equal `primary_key` (compared case-insensitively, per SQLite’s identifier rules). Partial indexes (`CREATE UNIQUE INDEX ... WHERE ...`) and functional / expression-based unique indexes (`CREATE UNIQUE INDEX ... ON t(expr)`) are not accepted — SQLite refuses `ON CONFLICT` against them, so the writer rejects them at construction.
[Performance](https://pathway.com/developers/api-docs/pathway-io/sqlite#performance)
-------------------------------------------------------------------------------------
SQLite is an embedded, **single-writer** database: only one connection may write to a database file at a time, so Pathway funnels the whole output through a single writer regardless of the worker count (see the concurrency section above). The single-worker figure is therefore the reference number for this sink; adding workers cannot parallelize the write.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and writing every row to a SQLite database file — so they reflect **Pathway + the input source + SQLite together, out of the box**.
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the output file. SQLite is embedded (no server process), so only the Pathway container was pinned — to one core-complex die (6 cores with a private 32 MiB L3), the same placement the engine uses in the other connector benchmarks.
**Throughput.** End-to-end wall-clock time to read a 20 M-row, 64-shard CSV dataset (**≈ 0.93 GB**) and land every row in a SQLite file, swept over the number of Pathway workers (median of 3 runs):
### [SQLite write throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/sqlite#sqlite-write-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 65.5 s | ≈ 305 300 rows/s | 1.00× |
| 2 | 84.9 s | ≈ 235 500 rows/s | 0.77× |
| 4 | 81.7 s | ≈ 244 800 rows/s | 0.80× |
| 8 | 83.1 s | ≈ 240 600 rows/s | 0.79× |
A single worker lands **~305 000 rows/s**, and every run passed the data-integrity checks. Beyond one worker throughput settles at ~0.77–0.80× of the single-worker rate: the write itself cannot run in parallel, so extra workers only add a gather-and-consolidate step — output rows produced across all workers must be collected and merged into one deterministic stream before the single writer lands them in the file. For this sink a single worker is both the fastest and the recommended configuration; this is a property of SQLite rather than of Pathway.
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/sqlite-bulk-write)
.
[**read**(path, table\_name, schema, \*, autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None)](https://pathway.com/developers/api-docs/pathway-io/sqlite#pathway.io.sqlite.read)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/sqlite/__init__.py#L41-L181)
Reads a table or view from a [SQLite](https://www.sqlite.org/)
database. Both rowid tables and `WITHOUT ROWID` tables / views are supported — the latter require a primary key declared in the Pathway Live Data Framework schema (see below).
The reader polls the database for changes and tracks each row by an identity so it can emit insertions, updates, and deletions. That identity is chosen from the Pathway Live Data Framework schema passed as `schema`:
* If the Pathway Live Data Framework schema declares one or more columns with `pw.column_definition(primary_key=True)`, those columns form the identity. The SQLite table must carry a matching `PRIMARY KEY` or `UNIQUE` constraint; otherwise the reader would silently conflate rows that share a key value, so `pw.io.sqlite.read` rejects the setup up-front. This mode is required for SQLite objects that don’t expose an implicit row id — e.g. `WITHOUT ROWID` tables and views; for views, which can’t carry constraints, the reader trusts the user’s declaration.
* Otherwise, SQLite’s implicit `_rowid_` column is used. `pw.io.sqlite.read` raises `ValueError` at call time if the target object has neither a primary key in the Pathway Live Data Framework schema nor `_rowid_`. The same error fires when the target table has a user-defined column named `rowid`, `_rowid_`, or `oid` (case-insensitive — these are SQLite’s rowid aliases): the user column shadows the implicit alias, so the reader cannot fetch the integer rowid identity. Declare a primary key in the The Pathway Live Data Framework schema to read such tables.
The column names of the Pathway Live Data Framework schema are verified against the target SQLite object’s columns (via `PRAGMA table_xinfo`, which exposes generated columns too) at connector construction; if the The Pathway Live Data Framework schema declares a column the SQLite table does not carry, the reader refuses to start and names the offending column(s) in the error. Identifier comparison is ASCII case-insensitive, matching SQLite’s own rules — e.g. declaring `ID` in the Pathway Live Data Framework schema matches a table column named `id`. The path must point at a valid SQLite 3 database — the connector runs `PRAGMA schema_version` up-front and surfaces a clear error if the file is non-SQLite or encrypted with a key this connection doesn’t have. Empty files are NOT rejected here, because SQLite treats them as brand-new empty databases; in that case the reader raises `ValueError` because `table_name` does not exist in the (empty) database.
Datetime values in `TEXT` columns are accepted in either the ISO-8601 form the writer emits (`YYYY-MM-DDTHH:MM:SS`, optionally followed by `.`\-prefixed fractional seconds, with a `T` separator) or the SQL-92 form SQLite itself produces via `CURRENT_TIMESTAMP` / `datetime()` (`YYYY-MM-DD HH:MM:SS`, optionally followed by `.`\-prefixed fractional seconds, with a space separator). The reader normalizes the separator before parsing so pre-existing SQLite tables round-trip without a schema change.
**Duplicate primary-key values within a single poll.** A matching `UNIQUE` constraint does not fully rule these out: SQLite permits _multiple_ `NULL` values in a `UNIQUE` column (its longstanding historical behavior), and rowid-less primary-key declarations on regular tables share the same leniency. When the reader sees two or more rows with identical primary-key values in one poll, the first row is tracked in the usual way and each subsequent duplicate is forwarded downstream as a per-row error: the primary-key columns on that event are replaced with an error value (the same marker that `pw.fill_error` and `pw.global_error_log` surface) naming the duplication, and the row is not added to the reader’s tracked snapshot. This way a single `NULL` (or any otherwise-legal repeat) still reaches the table while genuine collisions surface as visible parse errors without aborting the pipeline or dropping the rest of the batch.
**Persistence is not supported.** SQLite has no change-log history to replay, so a pipeline that uses `pw.io.sqlite.read` cannot be resumed from a Pathway Live Data Framework snapshot. Enabling `pw.persistence.Config` against such a pipeline raises `ValueError` at startup.
* **Parameters**
* **path** (`PathLike` | `str`) – Path to the database file. If the path resolves to an existing directory (directly or via a symlink), a `ValueError` is raised at call time.
* **table\_name** (`str`) – Name of the table in the database to be read. SQLite resolves identifiers case-insensitively, so a mixed-case `table_name` (e.g. `"Users"`) matches a table created as `users`.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Pathway Live Data Framework schema. Optionally annotate one or more columns with `pw.column_definition(primary_key=True)` to drive row-identity tracking (see above).
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **Returns**
_Table_ – The table read.
[**write**(table, path, table\_name, \*, max\_batch\_size=None, init\_mode='default', output\_table\_type='stream\_of\_changes', primary\_key=None, name=None)](https://pathway.com/developers/api-docs/pathway-io/sqlite#pathway.io.sqlite.write)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/sqlite/__init__.py#L184-L416)
Writes `table` to a table in a [SQLite](https://www.sqlite.org/)
database file. Two types of output tables are supported: **stream of changes** and **snapshot**.
When using **stream of changes**, the output table contains a log of every change seen in the Pathway Live Data Framework table. Two extra `INTEGER` columns, `time` and `diff`, are appended: `time` is the minibatch timestamp and `diff` is `1` for an insertion or `-1` for a deletion.
When using **snapshot**, the output table holds the current state of the Pathway Live Data Framework table. Insertions are emitted as `INSERT ... ON CONFLICT (primary_key) DO UPDATE SET ...` and deletions as `DELETE ... WHERE primary_key = ?`, so the destination table always mirrors the logical contents of the Pathway Live Data Framework table.
Values are encoded using the same storage-class mapping that [`pathway.io.sqlite.read()`](https://pathway.com/developers/api-docs/pathway-io-sqlite#pathway.io.sqlite.read)
expects, so a `write` / `read` pair is a lossless round-trip for every supported Pathway Live Data Framework type.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to write. Its column names must be unique under SQLite’s ASCII-case-insensitive identifier rules — a pair like `A` / `a` is rejected at `write()` time because `CREATE TABLE` would treat them as the same destination column.
* **path** (`PathLike` | `str`) – Path to the SQLite database file. The file is created if it does not exist. If the path resolves to an existing directory (directly or via a symlink), a `ValueError` is raised at call time.
* **table\_name** (`str`) – Name of the destination table. SQLite resolves identifiers case-insensitively, so a mixed-case name (e.g. `"Users"`) targets a table created as `users`.
* **max\_batch\_size** (`int` | `None`) – Optional upper bound on the number of rows buffered between flushes. Each batch is committed inside a single SQLite transaction.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – Controls how the destination SQLite table is initialized. `"default"` requires the SQLite table to already exist with columns matching the Pathway Live Data Framework table; `"create_if_not_exists"` creates it if missing; `"replace"` drops and recreates it. See Output Connector: Initialization and Schema Checks above for the full set of compatibility checks.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – Defines how the output table manages its data. `"stream_of_changes"` (the default) appends every change with its `time` and `diff` metadata. `"snapshot"` maintains the current state of the table: `+1` events become an UPSERT and `-1` events become a DELETE.
* **primary\_key** (`list`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\] | `None`) – One or more columns of `table` that form the primary key in the destination SQLite table. Required for snapshot mode and forbidden otherwise. See Output Connector: Snapshot Mode above for the rules on nullability and the matching destination constraint.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
Examples:
**Stream of changes.** Every event from the Pathway Live Data Framework table is appended to the destination table together with its `time` and `diff` metadata, so the result is a complete log of insertions and deletions. The destination table is created on demand when `init_mode` allows it:
`import pathway as pw t = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | cat 8 | Alice | cat ''') pw.io.sqlite.write( t, "pets.db", "pets", init_mode="create_if_not_exists", )`
The resulting `pets` table has the original columns plus the two `INTEGER` columns `time` and `diff` automatically added by the connector.
**Snapshot.** The destination table is kept in sync with the current state of the Pathway Live Data Framework table: every `+1` event UPSERTs on the primary key and every `-1` event issues a DELETE against the matching row. A primary key must be supplied via `primary_key`:
`pw.io.sqlite.write( t, "pets.db", "pets_snapshot", output_table_type="snapshot", primary_key=[t.owner, t.pet], init_mode="replace", )`
Here `(owner, pet)` is the primary key, so at any point in time the `pets_snapshot` table contains one row per live `(owner, pet)` pair — no history, no `time` / `diff` columns.
[Pathway Io\
\
pw.io.slack](https://pathway.com/developers/api-docs/pathway-io/slack)
[Pathway Io\
\
pw.io.weaviate](https://pathway.com/developers/api-docs/pathway-io/weaviate)
---
# pw.Table | Pathway
pw.Table
========
The Live Data Framework is organized around work with data tables. This page contains reference for the Live Data Framework **Table** class.
[class **Table**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
-----------------------------------------------------------------------------------------
[\[source\]](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L53-L3159)
Collection of named columns over identical universes.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') isinstance(t1, pw.Table)`
Code Results
### [property **C**: ColumnNamespace](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.C)
Returns the namespace of all the columns of a joinable. Allows accessing column names that might otherwise be a reserved methods.
`import pathway as pw tab = pw.debug.table_from_markdown(''' age | owner | pet | filter 10 | Alice | dog | True 9 | Bob | dog | True 8 | Alice | cat | False 7 | Bob | dog | True ''') isinstance(tab.C.age, pw.ColumnReference)`
Code Results
`pw.debug.compute_and_print(tab.filter(tab.C.filter), include_id=False)`
Code Results
### [**add\_update\_timestamp\_utc**(refresh\_rate=Timedelta('0 days 00:00:01'), update\_timestamp\_column\_name='updated\_timestamp\_utc')](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.add_update_timestamp_utc)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/time_utils.py#L189-L229)
Adds a column with the UTC timestamp of the last row update
* **Parameters**
* **refresh\_rate** (`pw.Duration, optional`) – The interval at which the UTC timestamp is refreshed. Defaults to 1 second.
* **update\_timestamp\_column\_name** (`str, optional`) – The name of the column to store the update timestamp. Defaults to “updated\_timestamp\_utc”.
* **Returns**
_pw.Table_ –
A new table with an additional column containing the UTC
`timestamp of the last update for each row. The id column is preserved.`
### [**assert\_append\_only**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.assert_append_only)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L3015-L3052)
Sets the append\_only property of all columns from a table to `True`.
Sometimes the Pathway Live Data Framework can’t automatically deduce that a table is append only. If you know that the table is append-only (contains only insertions), you can tell the Pathway Live Data Framework about it by using this method. At runtime the Pathway Live Data Framework will check if the table is really append-only and exit with an error otherwise.
* **Returns**
_Table_ – A table with the same columns as the original one but with append\_only property of the columns set to `True`.
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' a | b | __time__ | __diff__ 1 | 2 | 2 | 1 3 | 4 | 2 | 1 5 | 6 | 4 | 1 3 | 4 | 4 | -1 3 | 5 | 4 | 1 ''', id_from=["a"], ) # t is not append only due to the update (row with a=3) t.is_append_only`
Code Results
`t_filtered = t.filter(pw.this.a != 3) t_append_only = t_filtered.assert_append_only() t_append_only.is_append_only`
Code Results
### [**await\_futures**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.await_futures)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2779-L2833)
Waits for the results of asynchronous computation.
It strips the `Future` wrapper from table columns where applicable. In practice, it filters out the `Pending` values and produces a column with a data type that was the argument of Future.
Columns of Future data type are produced by fully asynchronous UDFs. Columns of this type can be propagated further, but can’t be used in most expressions (e.g. arithmetic operations). You can wait for their results using this method and later use the results in expressions you want.
Example:
`import pathway as pw import asyncio t = pw.debug.table_from_markdown( ''' a | b 1 | 2 3 | 4 5 | 6 ''' ) @pw.udf(executor=pw.udfs.fully_async_executor()) async def long_running_async_function(a: int, b: int) -> int: c = a * b await asyncio.sleep(0.1 * c) return c result = t.with_columns(res=long_running_async_function(pw.this.a, pw.this.b)) print(result.schema)`
Code Results
`awaited_result = result.await_futures() print(awaited_result.schema)`
Code Results
`pw.debug.compute_and_print(awaited_result, include_id=False)`
Code Results
### [**buffer**(time\_column, threshold)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.buffer)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L919-L964)
Buffers the values until the condition `time_column <= max(time_column) - threshold` is met.
This is a stateful operator. It stores the entries if their `time_column > max(time_column) - threshold`. Otherwise the entries can pass immediately. Once the current time (defined as max over all `time_column` values so far) advances and some of the stored entries start to satisfy the condition, they are sent for further processing.
* **Parameters**
* **time\_column** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – `ColumnExpression` that specifies the event time.
* **threshold** (`Union`\[`int`, `float`, `timedelta`\]) – value used to determine which entries are old enough to be sent for further processing. Should match the type of the `time_column` (`int -> int`, `float -> float`, `datetime -> timedelta`).
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' t | v | __time__ 1 | 1 | 2 2 | 2 | 4 5 | 3 | 6 2 | 4 | 8 7 | 5 | 10 ''' ) res = t.buffer(pw.this.t, 3) pw.debug.compute_and_print_update_stream(res)`
Code Results
The values of processing time for rows with event time 5, 7 are equal to 18446744073709551614 because there’s no more input and they are released only at the end of the processing. 18446744073709551614 is the maximum possible time.
### [**cast\_to\_types**(\*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.cast_to_types)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2262-L2275)
Casts columns to types.
### [**concat**(\*others)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.concat)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1584-L1666)
Concats self with every other ∊ others.
Semantics:
* result.columns == self.columns == other.columns
* result.id == self.id ∪ other.id
if self.id and other.id collide, throws an exception.
Requires:
* other.columns == self.columns
* self.id disjoint with other.id
* **Parameters**
**other** – the other table.
* **Returns**
_Table_ – The concatenated table. Id’s of rows from original tables are preserved.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | age | owner | pet 11 | 11 | Alice | 30 12 | 12 | Tom | 40 ''') pw.universes.promise_are_pairwise_disjoint(t1, t2) t3 = t1.concat(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**concat\_reindex**(\*tables)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.concat_reindex)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L313-L357)
Concatenate contents of several tables.
This is similar to PySpark union. All tables must have the same schema. Each row is reindexed.
* **Parameters**
**tables** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – List of tables to concatenate. All tables must have the same schema.
* **Returns**
_Table_ – The concatenated table. It will have new, synthetic ids.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | pet 1 | Dog 7 | Cat ''') t2 = pw.debug.table_from_markdown(''' | pet 1 | Manul 8 | Octopus ''') t3 = t1.concat_reindex(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**copy**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.copy)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1152-L1178)
Returns a copy of a table.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t2 = t1.copy() pw.debug.compute_and_print(t2, include_id=False)`
Code Results
`t1 is t2`
Code Results
### [**deduplicate**(\*, value, instance=None, acceptor, name=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.deduplicate)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1311-L1413)
Deduplicates rows in self on value column using acceptor function.
It keeps rows which where accepted by the acceptor function. Acceptor operates on two arguments - _CURRENT_ value and _PREVIOUS_ value.
* **Parameters**
* **value** (`Union`\[[`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)\
, `None`, `int`, `float`, `str`, `bytes`, `bool`, `Pointer`, `datetime`, `timedelta`, `ndarray`, [`Json`](https://pathway.com/developers/api-docs/pathway#pathway.Json)\
, `dict`\[`str`, `Any`\], `tuple`\[`Any`, `...`\], `Error`, `Pending`\]) – column expression used for deduplication.
* **instance** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
| `None`) – Grouping column. For rows with different values in this column, deduplication will be performed separately. Defaults to None.
* **acceptor** (`Callable`\[\[`TypeVar`(`T`, bound= `Union`\[`None`, `int`, `float`, `str`, `bytes`, `bool`, `Pointer`, `datetime`, `timedelta`, `ndarray`, [`Json`](https://pathway.com/developers/api-docs/pathway#pathway.Json)\
, `dict`\[`str`, `Any`\], `tuple`\[`Any`, `...`\], `Error`, `Pending`\]), `TypeVar`(`T`, bound= `Union`\[`None`, `int`, `float`, `str`, `bytes`, `bool`, `Pointer`, `datetime`, `timedelta`, `ndarray`, [`Json`](https://pathway.com/developers/api-docs/pathway#pathway.Json)\
, `dict`\[`str`, `Any`\], `tuple`\[`Any`, `...`\], `Error`, `Pending`\])\], `bool`\]) – callback telling whether two values are different.
* **name** (`str` | `None`) – An identifier, under which the state of the table will be persisted or `None`, if there is no need to persist the state of this table. When a program restarts, it restores the state for all input tables according to what was saved for their `name`. This way it’s possible to configure the start of computations from the moment they were terminated last time.
* **Returns**
_Table_ – the result of deduplication.
Example:
`import pathway as pw table = pw.debug.table_from_markdown( ''' val | __time__ 1 | 2 2 | 4 3 | 6 4 | 8 ''' ) def acceptor(new_value, old_value) -> bool: return new_value >= old_value + 2 result = table.deduplicate(value=pw.this.val, acceptor=acceptor) pw.debug.compute_and_print_update_stream(result, include_id=False)`
Code Results
`table = pw.debug.table_from_markdown( ''' val | instance | __time__ 1 | 1 | 2 2 | 1 | 4 3 | 2 | 6 4 | 1 | 8 4 | 2 | 8 5 | 1 | 10 ''' ) def acceptor(new_value, old_value) -> bool: return new_value >= old_value + 2 result = table.deduplicate( value=pw.this.val, instance=pw.this.instance, acceptor=acceptor ) pw.debug.compute_and_print_update_stream(result, include_id=False)`
Code Results
### [**diff**(timestamp, \*values, instance=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.diff)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/ordered/diff.py#L8-L123)
Compute the difference between the values in the `values` columns and the previous values according to the order defined by the column `timestamp`.
* **Parameters**
* **timestamp** (`pw.ColumnReference[int | float | datetime | str | bytes]`) – The column reference to the `timestamp` column on which the order is computed.
* **\*values** (`pw.ColumnReference[int | float | datetime]`) – Variable-length argument representing the column references to the `values` columns.
* **instance** (`pw.ColumnReference`) – Can be used to group the values. The difference is only computed between rows with the same `instance` value.
* **Returns**
`Table` – A new table where each column is replaced with a new column containing the difference and whose name is the concatenation of diff\_ and the former name.
* **Raises**
**ValueError** – If the columns are not ColumnReference.
**NOTE**: \* The value of the “first” value (the row with the lowest value in the `timestamp` column) is `None`.
Example:
`import pathway as pw table = pw.debug.table_from_markdown(''' timestamp | values 1 | 1 2 | 2 3 | 4 4 | 7 5 | 11 6 | 16 ''') table += table.diff(pw.this.timestamp, pw.this.values) pw.debug.compute_and_print(table, include_id=False)`
Code Results
`table = pw.debug.table_from_markdown( ''' timestamp | instance | values 1 | 0 | 1 2 | 1 | 2 3 | 1 | 4 3 | 0 | 7 6 | 1 | 11 6 | 0 | 16 ''' ) table += table.diff(pw.this.timestamp, pw.this.values, instance=pw.this.instance) pw.debug.compute_and_print(table, include_id=False)`
Code Results
### [**difference**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.difference)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L986-L1022)
Restrict self universe to keys not appearing in the other table.
* **Parameters**
**other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – table with ids to remove from self.
* **Returns**
_Table_ – table with restricted universe, with the same set of columns
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | cost 2 | 100 3 | 200 4 | 300 ''') t3 = t1.difference(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**empty**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.empty)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L359-L383)
Creates an empty table with a schema specified by kwargs.
* **Parameters**
**kwargs** (`DType`) – Dict whose keys are column names and values are column types.
* **Returns**
_Table_ – Created empty table.
Example:
`import pathway as pw t1 = pw.Table.empty(age=float, pet=float) pw.debug.compute_and_print(t1, include_id=False)`
Code Results
### [**filter**(filter\_expression)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.filter)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L494-L533)
Filter a table according to filter\_expression condition.
* **Parameters**
**filter\_expression** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – ColumnExpression that specifies the filtering condition.
* **Returns**
_Table_ – Result has the same schema as self and its ids are subset of self.id.
Example:
`import pathway as pw vertices = pw.debug.table_from_markdown(''' label outdegree 1 3 7 0 ''') filtered = vertices.filter(vertices.outdegree == 0) pw.debug.compute_and_print(filtered, include_id=False)`
Code Results
### [**filter\_out\_results\_of\_forgetting**(ensure\_consistency=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.filter_out_results_of_forgetting)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L789-L848)
Remove all row-deletion events from the table that were produced by the `forget` method.
This method has an effect only if `forget` was previously called with `mark_forgetting_records` parameter set to `True`. Only the deletions that are triggered by forgetting will be removed.
* **Parameters**
* **ensure\_consistency** (`bool`) – When enabled, the Pathway Live Data Framework keeps track of the latest value for
* **removed** (`each key. This ensures that when entries emitted by forgetting are`) –
: the sequence of remaining additions and deletions stays consistent.: For example: if an entry is removed due to forgetting and another entry with: the same key appears afterward: the stream would normally have two additions: for the same key: which is inconsistent. With the flag enabled: the Pathway Live Data Framework: tracks the state of each key. It will emit a deletion before the second: addition: guaranteeing that the stream remains consistent. Note that this: feature uses additional memory to store the current snapshot of the table.: If your data and use case guarantee that such inconsistencies won’t occur: : you can leave this check disabled.:
Note:
Using `forget` with a set `mark_forgetting_records` immediately followed by `filter_out_results_of_forgetting` is effectively a no-op.
The first call produces a table that temporarily contains both original and “forgotten” records, each forgotten record appears as an event with the `diff` equal to `-1`. The second call removes those deletion events and restores the table to its original state.
The method is, however, useful when you perform intermediate computations between these two calls. For example, you can call `forget` with a certain time window to limit the scope of processing, effectively creating a bounded window of data. Within that window, you can perform computations that benefit from this limited dataset. After those computations, calling `filter_out_results_of_forgetting` removes all deletion events and restores the table to a consistent state in which the previous forgetting operation is undone, and you have the complete set of rows, no longer limited to the forgetting window.
This approach lets you compute metrics inside a bounded window and then continue processing the entire data stream without carrying forward deletions for old records. Downstream consumers will receive fewer events because only insertions are propagated further.
### [**flatten**(to\_flatten, \*, origin\_id=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.flatten)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2338-L2377)
Performs a flatmap operation on a column or expression given as a first argument. Datatype of this column or expression has to be iterable or Json array. Other columns of the table are duplicated as many times as the length of the iterable.
It is possible to get ids of source rows by passing origin\_id argument, which is a new name of the column with the source ids.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | pet | age 1 | Dog | 2 7 | Cat | 5 ''') t2 = t1.flatten(t1.pet) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [**forget**(time\_column, threshold, mark\_forgetting\_records=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.forget)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L669-L755)
Remove old entries when they start to satisfy `time_column <= max(time_column) - threshold`.
This operator is useful for removing old entries from the stateful operators downstream (like joins, groupbys etc.). It stores the entries and when the current time (defined as max over all `time_column` values so far) reaches their time plus `threshold`, a deletion of entries is emitted.
* **Parameters**
* **time\_column** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – `ColumnExpression` that specifies the event time.
* **threshold** (`Union`\[`int`, `float`, `timedelta`\]) – value used to determine which entries are old enough to be removed. Should match the type of the `time_column` (`int -> int`, `float -> float`, `datetime -> timedelta`).
* **mark\_forgetting\_records** (`bool`) – If set to `True`, Pathway Live Data Framework marks records corresponding to the deletion of expired entries in a special way, without changing their visible representation. This flag is useful when combined with `filter_out_results_of_forgetting`, which can later remove those marked deletion records. In other words, it allows you to revert the effects of forgetting at a later stage.
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' t | v | __time__ 1 | 1 | 2 2 | 1 | 2 4 | 2 | 4 3 | 3 | 6 ''' ) t_with_forgetting = t.forget(pw.this.t, 3) s = pw.debug.table_from_markdown( ''' v | a | __time__ 1 | 1 | 2 2 | 2 | 4 1 | 3 | 8 ''' ) res = t_with_forgetting.join(s, pw.left.v == pw.right.v).select( pw.left.t, pw.left.v, pw.right.a ) pw.debug.compute_and_print_update_stream(res)`
Code Results
The entry `t=1,v=1` is forgotten at the processing time 6. It gets removed from the join. When at the processing time 8, there’s a new entry with the join key equal to 1, it only gets joined with `t=2,v=1` entry because the other entry was already removed.
The removal of `t=1,v=1` entry resulted in the retraction of all its results from a join (only `t=1,v=1,a=1` in this case). If you would like to filter out retractions, you can do `to_stream().filter(pw.this.is_upsert)` on the result of a join.
For cases where you don’t need to permanently forget data across the entire pipeline, but only want to temporarily limit the dataset to a specific time window for a computation, and then return to processing the full data stream, you can use the parameter `mark_forgetting_records` set to `True` to achieve this.
For example:
`t_with_forgetting = t.forget(pw.this.t, 3) # You computation on a t_with_forgetting, bounded by the 3 time units t = t_with_forgetting.filter_out_results_of_forgetting()`
This way, your table will be temporarily windowed, computations can be applied, and then the stream will return to its normal state.
### [**from\_columns**(\*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.from_columns)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L269-L311)
Build a table from columns.
All columns must have the same ids. Columns’ names must be pairwise distinct.
* **Parameters**
* **args** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – List of columns.
* **kwargs** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – Columns with their new names.
* **Returns**
_Table_ – Created table.
Example:
`import pathway as pw t1 = pw.Table.empty(age=float, pet=float) t2 = pw.Table.empty(foo=float, bar=float).with_universe_of(t1) t3 = pw.Table.from_columns(t1.pet, qux=t2.foo) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**from\_streams**(deletion\_stream)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.from_streams)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2964-L3013)
Converts streams of changes (updates and deletions) into a table.
This method reconstructs the current state of the table from such streams by applying the updates and deletions in order. It is a stateful operation: the operator keeps track of the latest value for each id. If there are multiple events for a single id in a single batch in the input streams, the order of applying the actions is not specified.
* **Parameters**
* **self** – A stream with updates (insertions or modifications).
* **deletion\_stream** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – A stream with deletions. Only ids in this stream are important. The columns don’t have to be compatible with the updates stream.
* **Returns**
_Table_ – A table with the same columns as the updates stream, representing the current state.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' id | pet | age | __time__ 1 | cat | 3 | 2 2 | dog | 11 | 2 1 | cat | 4 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' id | pet | __time__ 2 | dog | 4 ''' ) t3 = pw.Table.from_streams(t1, t2) pw.debug.compute_and_print_update_stream(t3, include_id=False)`
Code Results
### [**groupby**(\*args, id=None, sort\_by=None, instance=None, )](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.groupby)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1188-L1271)
Groups table by columns from args.
**NOTE**: Usually followed by .reduce() that aggregates the result and returns a table.
* **Parameters**
* **args** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – columns to group by.
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – if provided, is the column used to set id’s of the rows of the result
* **sort\_by** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – if provided, column values are used as sorting keys for particular reducers
* **instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – optional argument describing partitioning of the data into separate instances
* **Returns**
_GroupedTable_ – Groupby object.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t2 = t1.groupby(t1.pet, t1.owner).reduce(t1.owner, t1.pet, ageagg=pw.reducers.sum(t1.age)) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [property **id**:](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.id)
[ColumnReference](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
Get reference to pseudocolumn containing id’s of a table.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t2 = t1.select(ids = t1.id) t2.typehints()['ids']`
Code Results
`pw.debug.compute_and_print(t2.select(test=t2.id == t2.ids), include_id=False)`
Code Results
### [**ignore\_late**(time\_column, threshold)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.ignore_late)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L850-L895)
Filter out entries that satisfy `time_column <= max(time_column) - threshold`.
In contrast to `forget`, this operator doesn’t store the entries. It just checks if the entries match the condition and, if they do, allows them to pass. The only value stored by this operator is the current time (defined as max over all `time_column` values so far).
Please note that if the table is non-append-only and there’s a difference in processing time between an insertion and a deletion for some key, the insertion may pass through but the deletion may be filtered out. It’ll happen if the max value in `time_column` advanced between the insertion and deletion and the insertion didn’t satisfy the filtering-out criterion but the deletion did.
* **Parameters**
* **time\_column** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – `ColumnExpression` that specifies the event time.
* **threshold** (`Union`\[`int`, `float`, `timedelta`\]) – value used to determine which entries should be filtered out. Should match the type of the `time_column` (`int -> int`, `float -> float`, `datetime -> timedelta`).
Example:
`import pathway as pw t = pw.debug.table_from_markdown( ''' t | v | __time__ 1 | 1 | 2 2 | 2 | 4 5 | 3 | 6 2 | 4 | 8 7 | 5 | 10 ''' ) res = t.ignore_late(pw.this.t, 3) pw.debug.compute_and_print_update_stream(res)`
Code Results
### [**inactivity\_detection**(allowed\_inactivity\_period, refresh\_rate=Timedelta('0 days 00:00:01'), instance=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.inactivity_detection)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/time_utils.py#L70-L186)
Monitor append only table additions to detect inactivity periods and identify when activity resumes, optionally with instance argument.
This function periodically checks for table additions according to the provided refresh rate. It is limited to append only tables since the function is mostly intended to monitor input data streams. Inactivity periods that exceed the specified threshold are reported. The output table lists the inactivity periods with the UTC timestamp of the last detected activity before the threshold was exceeded and the UTC timestamp of the first detected activity that ends the inactivity period, or None if the inactivity period not yet ended.
Note: the inactivity period limits may differ from the actual values when the refresh rate is lower than the table update rate. It is also assumed that the system latency is neglectable compared to the specified threshold. When used with instance, an inactivity period since the stream start (_i.e._ no incoming data) is reported with a None value in the instance column.
* **Parameters**
* **allowed\_inactivity\_period** (`pw.Duration`) – maximum allowed inactivity duration. If no activity occurs within this duration, an inactivity period is flagged.
* **refresh\_rate** (`pw.Duration, optional`) – frequency with which table activities are checked to detect an inactivity period. Defaults to 1 second.
* **instance** (`pw.ColumnExpression | None, optional`) – group column to detect inactivity periods separately. Defaults to None.
* **Returns**
_Table_ – inactivity periods table with inactivity\_timestamp\_utc and resumed\_activity\_timestamp\_utc columns, optionally instance column.
### [**interpolate**(timestamp, \*values, mode=InterpolateMode.LINEAR)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.interpolate)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/statistical/_interpolate.py#L55-L167)
Interpolates missing values in a column using the previous and next values based on a timestamps column.
* **Parameters**
* **timestamp** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – Reference to the column containing timestamps.
* **\*values** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – References to the columns containing values to be interpolated.
* **mode** (`InterpolateMode, optional`) – The interpolation mode. Currently, only InterpolateMode.LINEAR is supported. Default is InterpolateMode.LINEAR.
* **Returns**
_Table_ – A new table with the interpolated values.
* **Raises**
**ValueError** – If the columns are not ColumnReference or if the interpolation mode is not supported.
**NOTE**: \* The interpolation is performed based on linear interpolation between the previous and next values.
* If a value is missing at the beginning or end of the column, no interpolation is performed.
Example:
`import pathway as pw table = pw.debug.table_from_markdown(''' timestamp | values_a | values_b 1 | 1 | 10 2 | | 3 | 3 | 4 | | 5 | | 6 | 6 | 60 ''') table = table.interpolate(pw.this.timestamp, pw.this.values_a, pw.this.values_b) pw.debug.compute_and_print(table, include_id=False)`
Code Results
### [**intersect**(\*tables)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.intersect)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1024-L1071)
Restrict self universe to keys appearing in all of the tables.
* **Parameters**
**tables** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – tables keys of which are used to restrict universe.
* **Returns**
_Table_ – table with restricted universe, with the same set of columns
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | cost 2 | 100 3 | 200 4 | 300 ''') t3 = t1.intersect(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**ix**(expression, \*, optional=False, context=None, allow\_misses=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.ix)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1415-L1525)
Reindexes the table using expression values as keys. Uses keys from context, or tries to infer proper context from the expression. If optional is True, then None in expression values result in None values in the result columns. Missing values in table keys result in RuntimeError. If `allow_misses` is set to True, they result in None value on the output.
Context can be anything that allows for select or reduce, or pathway.this construct (latter results in returning a delayed operation, and should be only used when using ix inside join().select() or groupby().reduce() sequence).
* **Returns**
Reindexed table with the same set of columns.
Example:
`import pathway as pw t_animals = pw.debug.table_from_markdown(''' | epithet | genus 1 | upupa | epops 2 | acherontia | atropos 3 | bubo | scandiacus 4 | dynastes | hercules ''') t_birds = pw.debug.table_from_markdown(''' | desc 2 | hoopoe 4 | owl ''') ret = t_birds.select(t_birds.desc, latin=t_animals.ix(t_birds.id).genus) pw.debug.compute_and_print(ret, include_id=False)`
Code Results
### [**ix\_ref**(\*args, optional=False, context=None, instance=None, allow\_misses=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.ix_ref)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2661-L2749)
Reindexes the table using expressions as primary keys. Uses keys from context, or tries to infer proper context from the expression. If `optional` is True, then None in expression values result in None values in the result columns. Missing values in table keys result in RuntimeError. If `allow_misses` is set to True, they result in None value on the output.
Context can be anything that allows for select or reduce, or pathway.this construct (latter results in returning a delayed operation, and should be only used when using ix inside join().select() or groupby().reduce() sequence).
* **Parameters**
**args** (`Union`\[[`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)\
, `None`, `int`, `float`, `str`, `bytes`, `bool`, `Pointer`, `datetime`, `timedelta`, `ndarray`, [`Json`](https://pathway.com/developers/api-docs/pathway#pathway.Json)\
, `dict`\[`str`, `Any`\], `tuple`\[`Any`, `...`\], `Error`, `Pending`\]) – Column references.
* **Returns**
_Row_ – indexed row.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' name | pet Alice | dog Bob | cat Carole | cat David | dog ''') t2 = t1.with_id_from(pw.this.name) t2 = t2.select(*pw.this, new_value=pw.this.ix_ref("Alice").pet) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
Tables obtained by a groupby/reduce scheme always have primary keys:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' name | pet Alice | dog Bob | cat Carole | cat David | cat ''') t2 = t1.groupby(pw.this.pet).reduce(pw.this.pet, count=pw.reducers.count()) t3 = t1.select(*pw.this, new_value=t2.ix_ref(t1.pet).count) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
Single-row tables can be accessed via ix\_ref():
`import pathway as pw t1 = pw.debug.table_from_markdown(''' name | pet Alice | dog Bob | cat Carole | cat David | cat ''') t2 = t1.reduce(count=pw.reducers.count()) t3 = t1.select(*pw.this, new_value=t2.ix_ref(context=t1).count) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**join**(other, \*on, id=None, how=JoinMode.INNER, left\_instance=None, right\_instance=None, left\_exactly\_once=False, right\_exactly\_once=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.join)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/joins.py#L132-L202)
Join self with other using the given join expression.
* **Parameters**
* **other** ([`Joinable`](https://pathway.com/developers/api-docs/pathway#pathway.Joinable)
) – the right side of the join, `Table` or `JoinResult`.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – optional argument for id of result, can be only self.id or other.id
* **how** ([`JoinMode`](https://pathway.com/developers/api-docs/pathway#pathway.JoinMode)
) – by default, inner join is performed. Possible values are JoinMode.{INNER,LEFT,RIGHT,OUTER} correspond to inner, left, right and outer join respectively.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **left\_exactly\_once** (`bool`) – if you can guarantee that each row on the left side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **right\_exactly\_once** (`bool`) – if you can guarantee that each row on the right side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **Returns**
_JoinResult_ – an object on which .select() may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' age | owner | pet | size 10 | Alice | 3 | M 9 | Bob | 1 | L 8 | Tom | 1 | XL ''') t3 = t1.join( t2, t1.pet == t2.pet, t1.owner == t2.owner, how=pw.JoinMode.INNER ).select(age=t1.age, owner_name=t2.owner, size=t2.size) pw.debug.compute_and_print(t3, include_id = False)`
Code Results
### [**join\_inner**(other, \*on, id=None, left\_instance=None, right\_instance=None, left\_exactly\_once=False, right\_exactly\_once=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.join_inner)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/joins.py#L204-L271)
Inner-joins two tables or join results.
* **Parameters**
* **other** ([`Joinable`](https://pathway.com/developers/api-docs/pathway#pathway.Joinable)
) – the right side of the join, `Table` or `JoinResult`.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – optional argument for id of result, can be only self.id or other.id
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **left\_exactly\_once** (`bool`) – if you can guarantee that each row on the left side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **right\_exactly\_once** (`bool`) – if you can guarantee that each row on the right side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **Returns**
_JoinResult_ – an object on which .select() may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' age | owner | pet | size 10 | Alice | 3 | M 9 | Bob | 1 | L 8 | Tom | 1 | XL ''') t3 = t1.join_inner(t2, t1.pet == t2.pet, t1.owner == t2.owner).select( age=t1.age, owner_name=t2.owner, size=t2.size ) pw.debug.compute_and_print(t3, include_id = False)`
Code Results
### [**join\_left**(other, \*on, id=None, left\_instance=None, right\_instance=None, left\_exactly\_once=False, right\_exactly\_once=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.join_left)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/joins.py#L273-L360)
Left-joins two tables or join results.
* **Parameters**
* **other** ([`Joinable`](https://pathway.com/developers/api-docs/pathway#pathway.Joinable)
) – the right side of the join, `Table` or `JoinResult`.
* **\*on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – Columns to join, syntax self.col1 == other.col2
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – optional id column of the result
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **left\_exactly\_once** (`bool`) – if you can guarantee that each row on the left side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **right\_exactly\_once** (`bool`) – if you can guarantee that each row on the right side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
Remarks: args cannot contain id column from either of tables, as the result table has id column with auto-generated ids; it can be selected by assigning it to a column with defined name (passed in kwargs)
Behavior:
* for rows from the left side that were not matched with the right side, missing values on the right are replaced with None
* rows from the right side that were not matched with the left side are skipped
* for rows that were matched the behavior is the same as that of an inner join.
* **Returns**
_JoinResult_ – an object on which .select() may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | a | b 1 | 11 | 111 2 | 12 | 112 3 | 13 | 113 4 | 13 | 114 ''' ) t2 = pw.debug.table_from_markdown( ''' | c | d 1 | 11 | 211 2 | 12 | 212 3 | 14 | 213 4 | 14 | 214 ''' ) pw.debug.compute_and_print(t1.join_left(t2, t1.a == t2.c ).select(t1.a, t2_c=t2.c, s=pw.require(t1.b + t2.d, t2.id)), include_id=False)`
Code Results
### [**join\_outer**(other, \*on, id=None, left\_instance=None, right\_instance=None, left\_exactly\_once=False, right\_exactly\_once=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.join_outer)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/joins.py#L454-L541)
Outer-joins two tables or join results.
* **Parameters**
* **other** ([`Joinable`](https://pathway.com/developers/api-docs/pathway#pathway.Joinable)
) – the right side of the join, `Table` or `JoinResult`.
* **\*on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – Columns to join, syntax self.col1 == other.col2
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – optional id column of the result
* **instance** – optional argument describing partitioning of the data into separate instances
* **left\_exactly\_once** (`bool`) – if you can guarantee that each row on the left side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **right\_exactly\_once** (`bool`) – if you can guarantee that each row on the right side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
Remarks: args cannot contain id column from either of tables, as the result table has id column with auto-generated ids; it can be selected by assigning it to a column with defined name (passed in kwargs)
Behavior:
* for rows from the left side that were not matched with the right side, missing values on the right are replaced with None
* for rows from the right side that were not matched with the left side, missing values on the left are replaced with None
* for rows that were matched the behavior is the same as that of an inner join.
* **Returns**
_JoinResult_ – an object on which .select() may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | a | b 1 | 11 | 111 2 | 12 | 112 3 | 13 | 113 4 | 13 | 114 ''' ) t2 = pw.debug.table_from_markdown( ''' | c | d 1 | 11 | 211 2 | 12 | 212 3 | 14 | 213 4 | 14 | 214 ''' ) pw.debug.compute_and_print(t1.join_outer(t2, t1.a == t2.c ).select(t1.a, t2_c=t2.c, s=pw.require(t1.b + t2.d, t1.id, t2.id)), include_id=False)`
Code Results
### [**join\_right**(other, \*on, id=None, left\_instance=None, right\_instance=None, left\_exactly\_once=False, right\_exactly\_once=False)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.join_right)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/joins.py#L362-L452)
Outer-joins two tables or join results.
* **Parameters**
* **other** ([`Joinable`](https://pathway.com/developers/api-docs/pathway#pathway.Joinable)
) – the right side of the join, `Table` or `JoinResult`.
* **\*on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – Columns to join, syntax self.col1 == other.col2
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – optional id column of the result
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **left\_exactly\_once** (`bool`) – if you can guarantee that each row on the left side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
* **right\_exactly\_once** (`bool`) – if you can guarantee that each row on the right side of the join will be joined at most once, then you can set this parameter to `True`. Then each row after getting a match is removed from the join state. As a result, less memory is needed. Works only for append-only tables.
Remarks: args cannot contain id column from either of tables, as the result table has id column with auto-generated ids; it can be selected by assigning it to a column with defined name (passed in kwargs)
Behavior:
* rows from the left side that were not matched with the right side are skipped
* for rows from the right side that were not matched with the left side, missing values on the left are replaced with None
* for rows that were matched the behavior is the same as that of an inner join.
* **Returns**
_JoinResult_ – an object on which .select() may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | a | b 1 | 11 | 111 2 | 12 | 112 3 | 13 | 113 4 | 13 | 114 ''' ) t2 = pw.debug.table_from_markdown( ''' | c | d 1 | 11 | 211 2 | 12 | 212 3 | 14 | 213 4 | 14 | 214 ''' ) pw.debug.compute_and_print(t1.join_right(t2, t1.a == t2.c ).select(t1.a, t2_c=t2.c, s=pw.require(pw.coalesce(t1.b,0) + t2.d,t1.id)), include_id=False)`
Code Results
* **Returns**
OuterJoinResult object
### [**plot**(plotting\_function, sorting\_col=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.plot)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/viz/plotting.py#L32-L139)
Allows for plotting contents of the table visually in e.g. jupyter. If the table depends only on the bounded data sources, the plot will be generated right away. Otherwise (in streaming scenario), the plot will be auto-updating after running pw.run()
* **Parameters**
* **self** (`pw.Table`) – a table serving as a source of data
* **plotting\_function** (`Callable[[ColumnDataSource], Plot]`) – function for creating plot from ColumnDataSource
* **Returns**
_pn.Column_ – visualization which can be displayed immediately or passed as a dashboard widget
Example:
`import pathway as pw from bokeh.plotting import figure def func(source): plot = figure(height=400, width=400, title="CPU usage over time") plot.scatter('a', 'b', source=source, line_width=3, line_alpha=0.6) return plot viz = pw.debug.table_from_pandas(pd.DataFrame({"a":[1,2,3],"b":[3,1,2]})).plot(func) type(viz)`
Code Results
### [**pointer\_from**(\*args, optional=False, instance=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.pointer_from)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2632-L2659)
Pseudo-random hash of its argument. Produces pointer types. Applied column-wise.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age owner pet 1 10 Alice dog 2 9 Bob dog 3 8 Alice cat 4 7 Bob dog''') g = t1.groupby(t1.owner).reduce(refcol = t1.pointer_from(t1.owner)) # g.id == g.refcol pw.debug.compute_and_print(g.select(test = (g.id == g.refcol)), include_id=False)`
Code Results
### [**promise\_universe\_is\_equal\_to**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.promise_universe_is_equal_to)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table_like.py#L127-L176)
Asserts to the Pathway Live Data Framework that an universe of self is a subset of universe of each of the others.
Semantics: Used in situations where the Pathway Live Data Framework cannot deduce one universe being a subset of another.
* **Returns**
None
**NOTE**: The assertion works in place.
Example:
`import pathway as pw import pytest t1 = pw.debug.table_from_markdown( ''' | age | owner | pet 1 | 8 | Alice | cat 2 | 9 | Bob | dog 3 | 15 | Alice | tortoise 4 | 99 | Bob | seahorse ''' ).filter(pw.this.age<30) t2 = pw.debug.table_from_markdown( ''' | age | owner 1 | 11 | Alice 2 | 12 | Tom 3 | 7 | Eve ''' ) t3 = t2.filter(pw.this.age > 10) with pytest.raises(ValueError): t1.update_cells(t3) t1 = t1.promise_universe_is_equal_to(t2) result = t1.update_cells(t3) pw.debug.compute_and_print(result, include_id=False)`
Code Results
### [**promise\_universe\_is\_subset\_of**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.promise_universe_is_subset_of)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table_like.py#L88-L125)
Asserts to the Pathway Live Data Framework that an universe of self is a subset of universe of each of the other.
Semantics: Used in situations where the Pathway Live Data Framework cannot deduce one universe being a subset of another.
* **Returns**
self
**NOTE**: The assertion works in place.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 30 ''').promise_universe_is_subset_of(t1) t3 = t1 << t2 pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**promise\_universes\_are\_disjoint**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.promise_universes_are_disjoint)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table_like.py#L48-L86)
Asserts to Pathway Live Data Framework that an universe of self is disjoint from universe of other.
Semantics: Used in situations where the Pathway Live Data Framework cannot deduce universes are disjoint.
* **Returns**
self
**NOTE**: The assertion works in place.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | age | owner | pet 11 | 11 | Alice | 30 12 | 12 | Tom | 40 ''').promise_universes_are_disjoint(t1) t3 = t1.concat(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**reduce**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.reduce)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1273-L1309)
Reduce a table to a single row.
Equivalent to self.groupby().reduce(\*args, \*\*kwargs).
* **Parameters**
* **args** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – reducer to reduce the table with
* **kwargs** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – reducer to reduce the table with. Its key is the new name of a column.
* **Returns**
_Table_ – Reduced table.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t2 = t1.reduce(ageagg=pw.reducers.argmin(t1.age)) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
`t3 = t2.select(t1.ix(t2.ageagg).age, t1.ix(t2.ageagg).pet) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**remove\_errors**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.remove_errors)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2751-L2777)
Filters out rows that contain errors.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' a | b 3 | 3 4 | 0 5 | 5 6 | 2 ''' ) t2 = t1.with_columns(x=pw.this.a // pw.this.b) res = t2.remove_errors() pw.debug.compute_and_print(res, include_id=False, terminate_on_error=False)`
Code Results
### [**rename**(names\_mapping=None, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.rename)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2145-L2167)
Rename columns according either a dictionary or kwargs.
If a mapping is provided using a dictionary, `rename_by_dict` will be used. Otherwise, `rename_columns` will be used with kwargs. Columns not in keys(kwargs) are not changed. New name of a column must not be `id`.
* **Parameters**
* **names\_mapping** (`dict`\[`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
, `str`\] | `None`) – mapping from old column names to new names.
* **kwargs** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – mapping from old column names to new names.
* **Returns**
_Table_ – self with columns renamed.
### [**rename\_by\_dict**(names\_mapping)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.rename_by_dict)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2067-L2099)
Rename columns according to a dictionary.
Columns not in keys(kwargs) are not changed. New name of a column must not be id.
* **Parameters**
**names\_mapping** (`dict`\[`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
, `str`\]) – mapping from old column names to new names.
* **Returns**
_Table_ – self with columns renamed.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = t1.rename_by_dict({"age": "years_old", t1.pet: "animal"}) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [**rename\_columns**(\*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.rename_columns)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2011-L2065)
Rename columns according to kwargs.
Columns not in keys(kwargs) are not changed. New name of a column must not be id.
* **Parameters**
**kwargs** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – mapping from old column names to new names.
* **Returns**
_Table_ – self with columns renamed.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = t1.rename_columns(years_old=t1.age, animal=t1.pet) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [**restrict**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.restrict)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1085-L1136)
Restrict self universe to keys appearing in other.
* **Parameters**
**other** ([`TableLike`](https://pathway.com/developers/api-docs/pathway#pathway.TableLike)
) – table which universe is used to restrict universe of self.
* **Returns**
_Table_ – table with restricted universe, with the same set of columns
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''' ) t2 = pw.debug.table_from_markdown( ''' | cost 2 | 100 3 | 200 ''' ) t2.promise_universe_is_subset_of(t1)`
Code Results
`t3 = t1.restrict(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [property **schema**: type\[](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.schema)\
[pathway.internals.schema.Schema](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]
Get schema of the table.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t1.schema`
Code Results
`t1.typehints()['age']`
Code Results
### [**select**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.select)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L385-L428)
Build a new table with columns specified by kwargs.
Output columns’ names are keys(kwargs). values(kwargs) can be raw values, boxed values, columns. Assigning to id reindexes the table.
* **Parameters**
* **args** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – Column references.
* **kwargs** (`Any`) – Column expressions with their new assigned names.
* **Returns**
_Table_ – Created table.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' pet Dog Cat ''') t2 = t1.select(animal=t1.pet, desc="fluffy") pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [**show**(\*, snapshot=True, include\_id=True, short\_pointers=True, sorters=None, page\_size=10, table\_height=400)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.show)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/viz/table_viz.py#L21-L185)
Allows for displaying table visually in e.g. jupyter. If the table depends only on the bounded data sources, the table preview will be generated right away. Otherwise (in streaming scenario), the table will be auto-updating after running pw.run()
* **Parameters**
* **self** (`pw.Table`) – a table to be displayed
* **snapshot** (`bool, optional`) – whether only current snapshot or all changes to the table should be displayed. Defaults to True.
* **include\_id** (`bool, optional`) – whether to show ids of rows. Defaults to True.
* **short\_pointers** (`bool, optional`) – whether to shorten printed ids. Defaults to True.
* **sorters** (`list, optional`) – a list of sorter definitions mapping where each item should declare the column to sort on and the direction to sort. Defaults to None.
* **page\_size** (`int, optional`) – number of rows on each page. Defaults to 10.
* **table\_height** (`int, optional`) – fixed height of the table widget. Defaults to 400.
* **Returns**
_pn.Column_ – visualization which can be displayed immediately or passed as a dashboard widget
Example:
`import pathway as pw table_viz = pw.debug.table_from_pandas(pd.DataFrame({"a":[1,2,3],"b":[3,1,2]})).show() type(table_viz)`
Code Results
### [property **slice**:](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.slice)
[TableSlice](https://pathway.com/developers/api-docs/pathway#pathway.TableSlice)
Creates a collection of references to self columns. Supports basic column manipulation methods.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t1.slice.without("age")`
Code Results
### [**sort**(key, instance=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.sort)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2405-L2477)
Sorts a table by the specified keys.
* **Parameters**
* **table** – pw.Table The table to be sorted.
* **key** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
`[int | float | datetime | str | bytes]`) – An expression to sort by.
* **instance** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
| `None`) – ColumnReference or None An expression with instance. Rows are sorted within an instance. `prev` and `next` columns will only point to rows that have the same instance.
* **Returns**
_pw.Table_ – The sorted table. Contains two columns: `prev` and `next`, containing the pointers to the previous and next rows.
Example:
`import pathway as pw table = pw.debug.table_from_markdown(''' name | age | score Alice | 25 | 80 Bob | 20 | 90 Charlie | 30 | 80 ''') table = table.with_id_from(pw.this.name) table += table.sort(key=pw.this.age) pw.debug.compute_and_print(table, include_id=True)`
Code Results
`table = pw.debug.table_from_markdown(''' name | age | score Alice | 25 | 80 Bob | 20 | 90 Charlie | 30 | 80 David | 35 | 90 Eve | 15 | 80 ''') table = table.with_id_from(pw.this.name) table += table.sort(key=pw.this.age, instance=pw.this.score) pw.debug.compute_and_print(table, include_id=True)`
Code Results
### [**split**(split\_expression)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.split)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L535-L575)
Split a table according to split\_expression condition.
* **Parameters**
**split\_expression** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – ColumnExpression that specifies the split condition.
* **Returns**
_positive\_table, negative\_table_ – tuple of tables, with the same schemas as self and with ids that are subsets of self.id, and provably disjoint.
Example:
`import pathway as pw vertices = pw.debug.table_from_markdown(''' label outdegree 1 3 7 0 ''') positive, negative = vertices.split(vertices.outdegree == 0) pw.debug.compute_and_print(positive, include_id=False)`
Code Results
`pw.debug.compute_and_print(negative, include_id=False)`
Code Results
### [**stream\_to\_table**(is\_upsert)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.stream_to_table)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2907-L2962)
Converts a stream of changes (updates and deletions) into a table.
In the Pathway Live Data Framework, a stream is a sequence of row changes, where each row has an id and a boolean column (e.g., “is\_upsert”) indicating whether the row is an update (`True`) or a deletion (`False`).
This method reconstructs the current state of the table from such a stream by applying the updates and deletions in order. It is a stateful operation: the operator keeps track of the latest value for each id. If there are multiple events for a single id in a single batch in a stream, the order of applying the actions is not specified. For deletions, only ids are important. The values in columns are ignored.
* **Parameters**
**is\_upsert** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – An expression that evaluates to a boolean value. `True` means the row is an upsert (insert or update), `False` means the row is a deletion.
* **Returns**
_Table_ – A table with the same columns as the original stream, representing the current state.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' id | pet | age | is_upsert | __time__ 1 | cat | 3 | True | 2 2 | dog | 11 | True | 2 1 | cat | 4 | True | 4 2 | dog | 0 | False | 4 ''' ) t2 = t1.stream_to_table(pw.this.is_upsert) pw.debug.compute_and_print_update_stream(t2, include_id=False)`
Code Results
### [**to\_stream**(upsert\_column\_name='is\_upsert')](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.to_stream)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2854-L2905)
Converts a table to a stream of changes.
If in a given batch there is:
* an insert or an update for a given key, a row with `True` in the `update_column_name` column is produced
* a delete for a given key, a row with `False` in the `update_column_name` column is produced.
The values in all other columns are kept. This is a stateless operation.
* **Parameters**
**upsert\_column\_name** (`str`) – name of the boolean column that will be added to the table and contain information about the type of action.
* **Returns**
_Table_ – An append only table with an additional column informing about the action type.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' id | age | owner | pet | __time__ | __diff__ 1 | 10 | Alice | dog | 2 | 1 2 | 9 | Bob | cat | 2 | 1 1 | 10 | Alice | dog | 4 | -1 1 | 11 | Alice | dog | 4 | 1 2 | 9 | Bob | cat | 4 | -1 2 | 10 | Bob | cat | 4 | 1 1 | 11 | Alice | dog | 6 | -1 1 | 12 | Alice | dog | 6 | 1 2 | 10 | Bob | cat | 6 | -1 ''') t2 = t1.to_stream() pw.debug.compute_and_print_update_stream(t2, include_id=False)`
Code Results
### [**typehints**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.typehints)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L3119-L3136)
Return the types of the columns as a dictionary.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | dog 8 | Alice | cat 7 | Bob | dog ''') t1.typehints()`
Code Results
### [**unpack\_snapshots**()](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.unpack_snapshots)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L3054-L3109)
Transforms a table representation from a change stream into a snapshot stream. A snapshot is the full state of the table after all additions, deletions, and updates corresponding to a specific changes minibatch that has been applied.
For example, suppose that at time `T` the table contains three rows: `A`, `B`, and `C`. At the next Pathway minibatch, time `T+1`, row `C` is replaced by row `D`. The table produced by this operator will then contain six rows as follows: at time `T` the rows `A`, `B`, and `C`, and at time `T+1` the rows `A`, `B`, and `D`.
Use caution when applying this method to large tables that change frequently. Any Pathway Live Data Framework minibatch in which at least one row is modified will emit a snapshot containing all rows in the table, which can result in a very large output.
Example:
You can create a table streamed in three minibatches with three rows as follows:
`import pathway as pw class DataColumnSchema(pw.Schema): data: str table = pw.demo.generate_custom_stream( value_generators={"data": lambda x: str(x + 1)}, schema=DataColumnSchema, nb_rows=3, )`
Then, the snapshot representation can be obtained:
`snapshot_representation = table.unpack_snapshots()`
Use an output connector to write the snapshots grouped by time:
`pw.io.csv.write(snapshot_representation, "snapshots.txt") pw.run() with open("snapshots.txt", "r") as f: print(f.read())`
Code Results
The output shows three time-based snapshots: first the initial state with row `"1"`, then an updated state with rows `"1"` and `"2"`, and finally the state with rows `"1"`, `"2"`, and `"3"`.
### [**update\_cells**(other, )](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.update_cells)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1689-L1754)
Updates cells of self, breaking ties in favor of the values in other.
Semantics:
`* result.columns == self.columns * result.id == self.id * conflicts are resolved preferring other’s values`
Requires:
`* other.columns ⊆ self.columns * other.id ⊆ self.id`
* **Parameters**
**other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the other table.
* **Returns**
_Table_ – self updated with cells form other.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' age | owner | pet 1 | 10 | Alice | 30 ''') pw.universes.promise_is_subset_of(t2, t1) t3 = t1.update_cells(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**update\_rows**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.update_rows)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1774-L1850)
Updates rows of self, breaking ties in favor for the rows in other.
Semantics:
* result.columns == self.columns == other.columns
* result.id == self.id ∪ other.id
Requires:
* other.columns == self.columns
* **Parameters**
**other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
\[`TypeVar`(`TSchema`, bound= [`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
)\]) – the other table.
* **Returns**
_Table_ – self updated with rows form other.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 30 12 | 12 | Tom | 40 ''') t3 = t1.update_rows(t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**update\_types**(\*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.update_types)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2230-L2251)
Updates types in schema. Has no effect on the runtime.
### [**with\_columns**(\*args, \*\*kwargs)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.with_columns)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1863-L1894)
Updates columns of self, according to args and kwargs. See table.select specification for evaluation of args and kwargs.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | owner | pet | size 1 | Tom | 1 | 10 2 | Bob | 1 | 9 3 | Tom | 2 | 8 ''') t3 = t1.with_columns(*t2) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
### [**with\_id**(new\_index)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.with_id)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1896-L1937)
Set new ids based on another column containing id-typed values.
To generate ids based on arbitrary valued columns, use with\_id\_from.
Values assigned must be row-wise unique. The uniqueness is not checked by pathway. Failing to provide unique ids can cause unexpected errors downstream.
* **Parameters**
**new\_id** – column to be used as the new index.
* **Returns**
Table with updated ids.
Example:
`import pytest; pytest.xfail("with_id is hard to test") import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = pw.debug.table_from_markdown(''' | new_id 1 | 2 2 | 3 3 | 4 ''') t3 = t1.promise_universe_is_subset_of(t2).with_id(t2.new_id) pw.debug.compute_and_print(t3)`
Code Results
### [**with\_id\_from**(\*args, instance=None)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.with_id_from)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L1939-L1989)
Compute new ids based on values in columns. Ids computed from columns must be row-wise unique. The uniqueness is not checked by pathway. Failing to provide unique ids can cause unexpected errors downstream.
* **Parameters**
**columns** – columns to be used as primary keys.
* **Returns**
_Table_ – self updated with recomputed ids.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | age | owner | pet 1 | 10 | Alice | 1 2 | 9 | Bob | 1 3 | 8 | Alice | 2 ''') t2 = t1 + t1.select(old_id=t1.id) t3 = t2.with_id_from(t2.age) pw.debug.compute_and_print(t3)`
Code Results
`t4 = t3.select(t3.age, t3.owner, t3.pet, same_as_old=(t3.id == t3.old_id), same_as_new=(t3.id == t3.pointer_from(t3.age))) pw.debug.compute_and_print(t4)`
Code Results
### [**with\_prefix**(prefix)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.with_prefix)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2101-L2121)
Rename columns by adding prefix to each name of column.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = t1.with_prefix("u_") pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [**with\_suffix**(suffix)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.with_suffix)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2123-L2143)
Rename columns by adding suffix to each name of column.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = t1.with_suffix("_current") pw.debug.compute_and_print(t2, include_id=False)`
Code Results
### [**with\_universe\_of**(other)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.with_universe_of)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2287-L2320)
Returns a copy of self with exactly the same universe as others.
Semantics: Required precondition self.universe == other.universe Used in situations where the Pathway Live Data Framework cannot deduce equality of universes, but those are equal as verified during runtime.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' | pet 1 | Dog 7 | Cat ''') t2 = pw.debug.table_from_markdown(''' | age 1 | 10 7 | 3 8 | 100 ''') t3 = t2.filter(pw.this.age < 30).with_universe_of(t1) t4 = t1 + t3 pw.debug.compute_and_print(t4, include_id=False)`
Code Results
### [**without**(\*columns)](https://pathway.com/developers/api-docs/pathway-table#pathway.Table.without)
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/internals/table.py#L2169-L2209)
Selects all columns without named column references.
* **Parameters**
**columns** (`str` | [`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – columns to be dropped provided by table.column\_name notation.
* **Returns**
_Table_ – self without specified columns.
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | 1 9 | Bob | 1 8 | Alice | 2 ''') t2 = t1.without(t1.age, pw.this.pet) pw.debug.compute_and_print(t2, include_id=False)`
Code Results
[Pathway Xpacks LLM\
\
pw.xpacks.llm.rerankers](https://pathway.com/developers/api-docs/pathway-xpacks-llm/rerankers)
[API Docs\
\
pw.debug](https://pathway.com/developers/api-docs/debug)
---
# pw.temporal | Pathway
pw.temporal
===========
This section covers a suite of temporal helper functions, allowing you to establish temporal relationships, group data in time intervals, and create custom time-bound sessions, all with a variety of options for customization and flexibility. Examples of each function in use are provided to help you better understand their applications.
[**add\_update\_timestamp\_utc**(self, refresh\_rate=Timedelta('0 days 00:00:01'), update\_timestamp\_column\_name='updated\_timestamp\_utc')](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.add_update_timestamp_utc)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/time_utils.py#L189-L229)
Adds a column with the UTC timestamp of the last row update
* **Parameters**
* **refresh\_rate** (`pw.Duration, optional`) – The interval at which the UTC timestamp is refreshed. Defaults to 1 second.
* **update\_timestamp\_column\_name** (`str, optional`) – The name of the column to store the update timestamp. Defaults to “updated\_timestamp\_utc”.
* **Returns**
_pw.Table_ –
A new table with an additional column containing the UTC
`timestamp of the last update for each row. The id column is preserved.`
[**asof\_join**(self, other, self\_time, other\_time, \*on, how, behavior=None, defaults={}, direction=Direction.BACKWARD, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_join)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_join.py#L477-L652)
Perform an ASOF join of two tables.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to join with self, both must contain a column val
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines the temporal behavior of a join - features like delaying entries or ignoring late entries.
* **how** ([`JoinMode`](https://pathway.com/developers/api-docs/pathway#pathway.JoinMode)
) – mode of the join (LEFT, RIGHT, FULL)
* **defaults** (`dict`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
, `Any`\]) – dictionary column-> default value. Entries in the resulting table that not have a predecessor in the join will be set to this default value. If no default is provided, None will be used.
* **direction** ([`Direction`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Direction)
) – direction of the join, accepted values: Direction.BACKWARD, Direction.FORWARD, Direction.NEAREST
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | K | val | t 1 | 0 | 1 | 1 2 | 0 | 2 | 4 3 | 0 | 3 | 5 4 | 0 | 4 | 6 5 | 0 | 5 | 7 6 | 0 | 6 | 11 7 | 0 | 7 | 12 8 | 1 | 8 | 5 9 | 1 | 9 | 7 ''' ) t2 = pw.debug.table_from_markdown( ''' | K | val | t 21 | 1 | 7 | 2 22 | 1 | 3 | 8 23 | 0 | 0 | 2 24 | 0 | 6 | 3 25 | 0 | 2 | 7 26 | 0 | 3 | 8 27 | 0 | 9 | 9 28 | 0 | 7 | 13 29 | 0 | 4 | 14 ''' ) res = t1.asof_join( t2, t1.t, t2.t, t1.K == t2.K, how=pw.JoinMode.LEFT, defaults={t2.val: -1}, ).select( pw.this.instance, pw.this.t, val_left=t1.val, val_right=t2.val, sum=t1.val + t2.val, ) pw.debug.compute_and_print(res, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an asof join. Then, each side of the asof join keeps track of the maximal already seen time (self\_time and other\_time). In the context of asof\_join the arguments of behavior are defined as follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, the asof join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Examples without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | event_time | __time__ 2 | 2 | 4 3 | 5 | 6 4 | 1 | 8 5 | 7 | 14 ''' ) t2 = pw.debug.table_from_markdown( ''' value | event_time | __time__ 42 | 1 | 2 8 | 4 | 10 ''' ) result_without_cutoff = t1.asof_join( t2, t1.event_time, t2.event_time, how=pw.JoinMode.LEFT ).select( left_value=t1.value, right_value=t2.value, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_without_cutoff = t1.asof_join( t2, t1.event_time, t2.event_time, how=pw.JoinMode.LEFT, behavior=pw.temporal.common_behavior(cutoff=2), ).select( left_value=t1.value, right_value=t2.value, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
The record with `value=4` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`1 <= 5-2`).
[**asof\_join\_left**(self, other, self\_time, other\_time, \*on, behavior=None, defaults={}, direction=Direction.BACKWARD, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_join_left)
-----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_join.py#L655-L824)
Perform a left ASOF join of two tables.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to join with self, both must contain a column val
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines the temporal behavior of a join - features like delaying entries or ignoring late entries.
* **defaults** (`dict`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
, `Any`\]) – dictionary column-> default value. Entries in the resulting table that not have a predecessor in the join will be set to this default value. If no default is provided, None will be used.
* **direction** ([`Direction`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Direction)
) – direction of the join, accepted values: Direction.BACKWARD, Direction.FORWARD, Direction.NEAREST
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | K | val | t 1 | 0 | 1 | 1 2 | 0 | 2 | 4 3 | 0 | 3 | 5 4 | 0 | 4 | 6 5 | 0 | 5 | 7 6 | 0 | 6 | 11 7 | 0 | 7 | 12 8 | 1 | 8 | 5 9 | 1 | 9 | 7 ''' ) t2 = pw.debug.table_from_markdown( ''' | K | val | t 21 | 1 | 7 | 2 22 | 1 | 3 | 8 23 | 0 | 0 | 2 24 | 0 | 6 | 3 25 | 0 | 2 | 7 26 | 0 | 3 | 8 27 | 0 | 9 | 9 28 | 0 | 7 | 13 29 | 0 | 4 | 14 ''' ) res = t1.asof_join_left( t2, t1.t, t2.t, t1.K == t2.K, defaults={t2.val: -1}, ).select( pw.this.instance, pw.this.t, val_left=t1.val, val_right=t2.val, sum=t1.val + t2.val, ) pw.debug.compute_and_print(res, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an asof join. Then, each side of the asof join keeps track of the maximal already seen time (self\_time and other\_time). In the context of asof\_join the arguments of behavior are defined as follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, the asof join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Examples without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | event_time | __time__ 2 | 2 | 4 3 | 5 | 6 4 | 1 | 8 5 | 7 | 14 ''' ) t2 = pw.debug.table_from_markdown( ''' value | event_time | __time__ 42 | 1 | 2 8 | 4 | 10 ''' ) result_without_cutoff = t1.asof_join_left(t2, t1.event_time, t2.event_time).select( left_value=t1.value, right_value=t2.value, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_without_cutoff = t1.asof_join_left( t2, t1.event_time, t2.event_time, behavior=pw.temporal.common_behavior(cutoff=2), ).select( left_value=t1.value, right_value=t2.value, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
The record with `value=4` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`1 <= 5-2`).
[**asof\_join\_outer**(self, other, self\_time, other\_time, \*on, behavior=None, defaults={}, direction=Direction.BACKWARD, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_join_outer)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_join.py#L998-L1109)
Perform an outer ASOF join of two tables.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to join with self, both must contain a column val
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines the temporal behavior of a join - features like delaying entries or ignoring late entries.
* **defaults** (`dict`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
, `Any`\]) – dictionary column-> default value. Entries in the resulting table that not have a predecessor in the join will be set to this default value. If no default is provided, None will be used.
* **direction** ([`Direction`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Direction)
) – direction of the join, accepted values: Direction.BACKWARD, Direction.FORWARD, Direction.NEAREST
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | K | val | t 1 | 0 | 1 | 1 2 | 0 | 2 | 4 3 | 0 | 3 | 5 4 | 0 | 4 | 6 5 | 0 | 5 | 7 6 | 0 | 6 | 11 7 | 0 | 7 | 12 8 | 1 | 8 | 5 9 | 1 | 9 | 7 ''' ) t2 = pw.debug.table_from_markdown( ''' | K | val | t 21 | 1 | 7 | 2 22 | 1 | 3 | 8 23 | 0 | 0 | 2 24 | 0 | 6 | 3 25 | 0 | 2 | 7 26 | 0 | 3 | 8 27 | 0 | 9 | 9 28 | 0 | 7 | 13 29 | 0 | 4 | 14 ''' ) res = t1.asof_join_outer( t2, t1.t, t2.t, t1.K == t2.K, defaults={t1.val: -1, t2.val: -1}, ).select( pw.this.instance, pw.this.t, val_left=t1.val, val_right=t2.val, sum=t1.val + t2.val, ) pw.debug.compute_and_print(res, include_id=False)`
Code Results
[**asof\_join\_right**(self, other, self\_time, other\_time, \*on, behavior=None, defaults={}, direction=Direction.BACKWARD, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_join_right)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_join.py#L827-L995)
Perform a right ASOF join of two tables.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to join with self, both must contain a column val
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time-like column expression to do the join against
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines the temporal behavior of a join - features like delaying entries or ignoring late entries.
* **defaults** (`dict`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
, `Any`\]) – dictionary column-> default value. Entries in the resulting table that not have a predecessor in the join will be set to this default value. If no default is provided, None will be used.
* **direction** ([`Direction`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Direction)
) – direction of the join, accepted values: Direction.BACKWARD, Direction.FORWARD, Direction.NEAREST
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
Example:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | K | val | t 1 | 0 | 1 | 1 2 | 0 | 2 | 4 3 | 0 | 3 | 5 4 | 0 | 4 | 6 5 | 0 | 5 | 7 6 | 0 | 6 | 11 7 | 0 | 7 | 12 8 | 1 | 8 | 5 9 | 1 | 9 | 7 ''' ) t2 = pw.debug.table_from_markdown( ''' | K | val | t 21 | 1 | 7 | 2 22 | 1 | 3 | 8 23 | 0 | 0 | 2 24 | 0 | 6 | 3 25 | 0 | 2 | 7 26 | 0 | 3 | 8 27 | 0 | 9 | 9 28 | 0 | 7 | 13 29 | 0 | 4 | 14 ''' ) res = t1.asof_join_right( t2, t1.t, t2.t, t1.K == t2.K, defaults={t1.val: -1}, ).select( pw.this.instance, pw.this.t, val_left=t1.val, val_right=t2.val, sum=t1.val + t2.val, ) pw.debug.compute_and_print(res, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an asof join. Then, each side of the asof join keeps track of the maximal already seen time (self\_time and other\_time). In the context of asof\_join the arguments of behavior are defined as follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, the asof join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Examples without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | event_time | __time__ 42 | 1 | 2 8 | 4 | 10 ''' ) t2 = pw.debug.table_from_markdown( ''' value | event_time | __time__ 2 | 2 | 4 3 | 5 | 6 4 | 1 | 8 5 | 7 | 14 ''' ) result_without_cutoff = t1.asof_join_right(t2, t1.event_time, t2.event_time).select( left_value=t1.value, right_value=t2.value, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_without_cutoff = t1.asof_join_right( t2, t1.event_time, t2.event_time, behavior=pw.temporal.common_behavior(cutoff=2), ).select( left_value=t1.value, right_value=t2.value, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
The record with `value=4` from table `t2` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`1 <= 5-2`).
[**asof\_now\_join**(self, other, \*on, how=JoinMode.INNER, id=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_now_join)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_now_join.py#L172-L254)
Performs an asof now join between `self` and `other` using the provided join expressions.
In an asof now join, each row of `self` is joined with rows from `other` that are available at the processing time of that row. Rows from `self` are not stored: they are joined with the current state of `other` at their processing time, and will not be updated if `other` changes in the future. The `self` table has to be append-only. Rows from `other` are stored and can be joined with future rows of `self`.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The right side of the join.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – One or more column expressions, each of the form `LHS: ColumnReference == RHS: ColumnReference`. Each must use `==` as the top-level operation.
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Specifies the id column of the result; can be only `self.id` or `other.id`.
* **how** ([`JoinMode`](https://pathway.com/developers/api-docs/pathway#pathway.JoinMode)
) – Specifies the join mode. By default, an inner join is performed. Possible values are `JoinMode.INNER` and `JoinMode.LEFT`, corresponding to inner and left joins, respectively.
* **left\_instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Determines the partitioning of the left table and is used in a join condition.
* **right\_instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Determines the partitioning of the right table and is used in a join condition. If provided, both `left_instance` and `right_instance` must be specified
* **Returns**
_AsofNowJoinResult_ – An object on which `.select()` may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw data = pw.debug.table_from_markdown( ''' id | value | instance | __time__ | __diff__ 2 | 4 | 1 | 4 | 1 2 | 4 | 1 | 10 | -1 5 | 5 | 1 | 10 | 1 7 | 2 | 2 | 14 | 1 7 | 2 | 2 | 22 | -1 11 | 3 | 2 | 26 | 1 5 | 5 | 1 | 30 | -1 14 | 9 | 1 | 32 | 1 ''' ) queries = pw.debug.table_from_markdown( ''' value | instance | __time__ 1 | 1 | 2 2 | 1 | 6 4 | 1 | 12 5 | 2 | 16 10 | 1 | 26 ''' ) result = queries.asof_now_join( data, pw.left.instance == pw.right.instance, how=pw.JoinMode.LEFT ).select(query=pw.left.value, ans=pw.right.value) pw.debug.compute_and_print_update_stream(result, include_id=False)`
Code Results
[**asof\_now\_join\_inner**(self, other, \*on, id=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_now_join_inner)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_now_join.py#L257-L335)
Performs an asof now inner join between `self` and `other` using the provided join expressions.
In an asof now join, each row of `self` is joined with rows from `other` that are available at the processing time of that row. Rows from `self` are not stored: they are joined with the current state of `other` at their processing time, and will not be updated if `other` changes in the future. The `self` table has to be append-only. Rows from `other` are stored and can be joined with future rows of `self`.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The right side of the join.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – One or more column expressions, each of the form `LHS: ColumnReference == RHS: ColumnReference`. Each must use `==` as the top-level operation.
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Specifies the id column of the result; can be only `self.id` or `other.id`.
* **left\_instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Determines the partitioning of the left table and is used in a join condition.
* **right\_instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Determines the partitioning of the right table and is used in a join condition. If provided, both `left_instance` and `right_instance` must be specified
* **Returns**
_AsofNowJoinResult_ – An object on which `.select()` may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw data = pw.debug.table_from_markdown( ''' id | value | instance | __time__ | __diff__ 2 | 4 | 1 | 4 | 1 2 | 4 | 1 | 10 | -1 5 | 5 | 1 | 10 | 1 7 | 2 | 2 | 14 | 1 7 | 2 | 2 | 22 | -1 11 | 3 | 2 | 26 | 1 5 | 5 | 1 | 30 | -1 14 | 9 | 1 | 32 | 1 ''' ) queries = pw.debug.table_from_markdown( ''' value | instance | __time__ 1 | 1 | 2 2 | 1 | 6 4 | 1 | 12 5 | 2 | 16 10 | 1 | 26 ''' ) result = queries.asof_now_join_inner( data, pw.left.instance == pw.right.instance ).select(query=pw.left.value, ans=pw.right.value) pw.debug.compute_and_print_update_stream(result, include_id=False)`
Code Results
[**asof\_now\_join\_left**(self, other, \*on, id=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.asof_now_join_left)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_asof_now_join.py#L338-L419)
Performs an asof now left join between `self` and `other` using the provided join expressions.
In an asof now join, each row of `self` is joined with rows from `other` that are available at the processing time of that row. Rows from `self` are not stored: they are joined with the current state of `other` at their processing time, and will not be updated if `other` changes in the future. The `self` table has to be append-only. Rows from `other` are stored and can be joined with future rows of `self`.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The right side of the join.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – One or more column expressions, each of the form `LHS: ColumnReference == RHS: ColumnReference`. Each must use `==` as the top-level operation.
* **id** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Specifies the id column of the result; can be only `self.id` or `other.id`.
* **how** – Specifies the join mode. By default, an inner join is performed. Possible values are `JoinMode.INNER` and `JoinMode.LEFT`, corresponding to inner and left joins, respectively.
* **left\_instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Determines the partitioning of the left table and is used in a join condition.
* **right\_instance** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
| `None`) – Optional. Determines the partitioning of the right table and is used in a join condition. If provided, both `left_instance` and `right_instance` must be specified
* **Returns**
_AsofNowJoinResult_ – An object on which `.select()` may be called to extract relevant columns from the result of the join.
Example:
`import pathway as pw data = pw.debug.table_from_markdown( ''' id | value | instance | __time__ | __diff__ 2 | 4 | 1 | 4 | 1 2 | 4 | 1 | 10 | -1 5 | 5 | 1 | 10 | 1 7 | 2 | 2 | 14 | 1 7 | 2 | 2 | 22 | -1 11 | 3 | 2 | 26 | 1 5 | 5 | 1 | 30 | -1 14 | 9 | 1 | 32 | 1 ''' ) queries = pw.debug.table_from_markdown( ''' value | instance | __time__ 1 | 1 | 2 2 | 1 | 6 4 | 1 | 12 5 | 2 | 16 10 | 1 | 26 ''' ) result = queries.asof_now_join_left( data, pw.left.instance == pw.right.instance ).select(query=pw.left.value, ans=pw.right.value) pw.debug.compute_and_print_update_stream(result, include_id=False)`
Code Results
[**common\_behavior**(delay=None, cutoff=None, keep\_results=True)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.common_behavior)
--------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/temporal_behavior.py#L29-L75)
Creates an instance of `CommonBehavior`, which contains a basic configuration of a behavior of temporal operators (like `windowby` or `asof_join`). Each temporal operator tracks its own time (defined as a maximum time that arrived to the operator) and this configuration tells it that some of its inputs or outputs may be delayed or ignored. The decisions are based on the current time of the operator and the time associated with an input/output entry. Additionally, it allows the operator to free up memory by removing parts of internal state that cannot interact with any future input entries.
Remark: for the sake of temporal behavior, the current time of each operator is updated only after it processes all the data that arrived on input. In other words, if several new input entries arrived to the system simultaneously, each of those entries will be processed using last recorded time, and the recorded time is upda
* **Parameters**
* **delay** (`Union`\[`int`, `float`, `timedelta`, `None`\]) – Optional.
For windows, delays initial output by `delay` with respect to the beginning of the window. Setting it to `None` does not enable delaying mechanism.
For interval joins and asof joins, it delays the time the record is joined by `delay`.
Using delay is useful when updates are too frequent.
* **cutoff** (`Union`\[`int`, `float`, `timedelta`, `None`\]) – Optional.
For windows, stops updating windows which end earlier than maximal seen time minus `cutoff`. Setting cutoff to `None` does not enable cutoff mechanism.
For interval joins and asof joins, it ignores entries that are older than maximal seen time minus `cutoff`. This parameter is also used to clear memory. It allows to release memory used by entries that won’t change.
* **keep\_results** (`bool`) – If set to True, keeps all results of the operator. If set to False, keeps only results that are newer than maximal seen time minus `cutoff`. Can’t be set to `False`, when `cutoff` is `None`.
[**exactly\_once\_behavior**(shift=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.exactly_once_behavior)
------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/temporal_behavior.py#L83-L98)
Creates an instance of class ExactlyOnceBehavior, indicating that each non empty window should produce exactly one output.
* **Parameters**
**shift** (`Union`\[`int`, `float`, `timedelta`, `None`\]) – optional, defines the moment in time (`window end + shift`) in which the window stops accepting the data and sends the results to the output. Setting it to `None` is interpreted as `shift=0`.
Remark:
``note that setting a non-zero shift and demanding exactly one output results in the output being delivered only when the time in the time column reaches `window end + shift`.``
[**inactivity\_detection**(self, allowed\_inactivity\_period, refresh\_rate=Timedelta('0 days 00:00:01'), instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.inactivity_detection)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/time_utils.py#L70-L186)
Monitor append only table additions to detect inactivity periods and identify when activity resumes, optionally with instance argument.
This function periodically checks for table additions according to the provided refresh rate. It is limited to append only tables since the function is mostly intended to monitor input data streams. Inactivity periods that exceed the specified threshold are reported. The output table lists the inactivity periods with the UTC timestamp of the last detected activity before the threshold was exceeded and the UTC timestamp of the first detected activity that ends the inactivity period, or None if the inactivity period not yet ended.
Note: the inactivity period limits may differ from the actual values when the refresh rate is lower than the table update rate. It is also assumed that the system latency is neglectable compared to the specified threshold. When used with instance, an inactivity period since the stream start (_i.e._ no incoming data) is reported with a None value in the instance column.
* **Parameters**
* **allowed\_inactivity\_period** (`pw.Duration`) – maximum allowed inactivity duration. If no activity occurs within this duration, an inactivity period is flagged.
* **refresh\_rate** (`pw.Duration, optional`) – frequency with which table activities are checked to detect an inactivity period. Defaults to 1 second.
* **instance** (`pw.ColumnExpression | None, optional`) – group column to detect inactivity periods separately. Defaults to None.
* **Returns**
_Table_ – inactivity periods table with inactivity\_timestamp\_utc and resumed\_activity\_timestamp\_utc columns, optionally instance column.
[**interval**(lower\_bound, upper\_bound)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.interval)
------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_interval_join.py#L61-L108)
Allows testing whether two times are within a certain distance.
**NOTE**: Usually used as an argument of .interval\_join().
* **Parameters**
* **lower\_bound** (`int` | `float` | `timedelta`) – a lower bound on other\_time - self\_time.
* **upper\_bound** (`int` | `float` | `timedelta`) – an upper bound on other\_time - self\_time.
* **Returns**
_Window_ – object to pass as an argument to .interval\_join()
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 3 2 | 4 3 | 5 4 | 11 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 0 2 | 1 3 | 4 4 | 7 ''' ) t3 = t1.interval_join(t2, t1.t, t2.t, pw.temporal.interval(-2, 1)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
[**interval\_join**(self, other, self\_time, other\_time, interval, \*on, behavior=None, how=JoinMode.INNER, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.interval_join)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_interval_join.py#L573-L775)
Performs an interval join of self with other using a time difference and join expressions. If self\_time + lower\_bound <= other\_time <= self\_time + upper\_bound and conditions in on are satisfied, the rows are joined.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** (`pw.ColumnExpression[int | float | datetime]`) – time expression in self.
* **other\_time** (`pw.ColumnExpression[int | float | datetime]`) – time expression in other.
* **lower\_bound** – a lower bound on time difference between other\_time and self\_time.
* **upper\_bound** – an upper bound on time difference between other\_time and self\_time.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines a temporal behavior of a join - features like delaying entries or ignoring late entries. You can see examples below or read more in the [temporal behavior of interval join tutorial](https://pathway.com/developers/user-guide/temporal-data/temporal_behavior)
.
* **how** ([`JoinMode`](https://pathway.com/developers/api-docs/pathway#pathway.JoinMode)
) – decides whether to run interval\_join\_inner, interval\_join\_left, interval\_join\_right or interval\_join\_outer. Default is INNER.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_IntervalJoinResult_ – a result of the interval join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 3 2 | 4 3 | 5 4 | 11 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 0 2 | 1 3 | 4 4 | 7 ''' ) t3 = t1.interval_join(t2, t1.t, t2.t, pw.temporal.interval(-2, 1)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 3 2 | 1 | 4 3 | 1 | 5 4 | 1 | 11 5 | 2 | 2 6 | 2 | 3 7 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 0 2 | 1 | 1 3 | 1 | 4 4 | 1 | 7 5 | 2 | 0 6 | 2 | 2 7 | 4 | 2 ''' ) t3 = t1.interval_join( t2, t1.t, t2.t, pw.temporal.interval(-2, 1), t1.a == t2.b, how=pw.JoinMode.INNER ).select(t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an interval join. Then, each side of the interval join keeps track of the maximal already seen time (self\_time and other\_time). The arguments of behavior mean in the context of an interval join what follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, interval join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Example without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 1 | 1 | 0 | 2 2 | 2 | 2 | 4 3 | 1 | 4 | 4 4 | 2 | 8 | 8 5 | 1 | 0 | 10 6 | 1 | 4 | 10 ''' ) t2 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 42 | 1 | 2 | 2 8 | 2 | 10 | 14 10 | 2 | 4 | 30 ''' ) result_without_cutoff = t1.interval_join( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_with_cutoff = t1.interval_join( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, behavior=pw.temporal.common_behavior(cutoff=6), ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_with_cutoff, include_id=False)`
Code Results
The record with `value=5` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`0 <= 8-6`). The record with `value=10` from table `t2` was not joined because its `event_time` was equal to the maximal already seen time minus `cutoff` (`4 <= 10-6`).
[**interval\_join\_inner**(self, other, self\_time, other\_time, interval, \*on, behavior=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.interval_join_inner)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_interval_join.py#L778-L974)
Performs an interval join of self with other using a time difference and join expressions. If self\_time + lower\_bound <= other\_time <= self\_time + upper\_bound and conditions in on are satisfied, the rows are joined.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **lower\_bound** – a lower bound on time difference between other\_time and self\_time.
* **upper\_bound** – an upper bound on time difference between other\_time and self\_time.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines temporal behavior of a join - features like delaying entries or ignoring late entries.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_IntervalJoinResult_ – a result of the interval join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 3 2 | 4 3 | 5 4 | 11 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 0 2 | 1 3 | 4 4 | 7 ''' ) t3 = t1.interval_join_inner(t2, t1.t, t2.t, pw.temporal.interval(-2, 1)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 3 2 | 1 | 4 3 | 1 | 5 4 | 1 | 11 5 | 2 | 2 6 | 2 | 3 7 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 0 2 | 1 | 1 3 | 1 | 4 4 | 1 | 7 5 | 2 | 0 6 | 2 | 2 7 | 4 | 2 ''' ) t3 = t1.interval_join_inner( t2, t1.t, t2.t, pw.temporal.interval(-2, 1), t1.a == t2.b ).select(t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an interval join. Then, each side of the interval join keeps track of the maximal already seen time (self\_time and other\_time). The arguments of behavior mean in the context of an interval join what follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, interval join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Example without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 1 | 1 | 0 | 2 2 | 2 | 2 | 4 3 | 1 | 4 | 4 4 | 2 | 8 | 8 5 | 1 | 0 | 10 6 | 1 | 4 | 10 ''' ) t2 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 42 | 1 | 2 | 2 8 | 2 | 10 | 14 10 | 2 | 4 | 30 ''' ) result_without_cutoff = t1.interval_join_inner( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_with_cutoff = t1.interval_join_inner( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, behavior=pw.temporal.common_behavior(cutoff=6), ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_with_cutoff, include_id=False)`
Code Results
The record with `value=5` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`0 <= 8-6`). The record with `value=10` from table `t2` was not joined because its `event_time` was equal to the maximal already seen time minus `cutoff` (`4 <= 10-6`).
[**interval\_join\_left**(self, other, self\_time, other\_time, interval, \*on, behavior=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.interval_join_left)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_interval_join.py#L977-L1191)
Performs an interval left join of self with other using a time difference and join expressions. If self\_time + lower\_bound <= other\_time <= self\_time + upper\_bound and conditions in on are satisfied, the rows are joined. Rows from the left side that haven’t been matched with the right side are returned with missing values on the right side replaced with None.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of the join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **lower\_bound** – a lower bound on time difference between other\_time and self\_time.
* **upper\_bound** – an upper bound on time difference between other\_time and self\_time.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines temporal behavior of a join - features like delaying entries or ignoring late entries.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_IntervalJoinResult_ – a result of the interval join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 3 2 | 4 3 | 5 4 | 11 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 0 2 | 1 3 | 4 4 | 7 ''' ) t3 = t1.interval_join_left(t2, t1.t, t2.t, pw.temporal.interval(-2, 1)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 3 2 | 1 | 4 3 | 1 | 5 4 | 1 | 11 5 | 2 | 2 6 | 2 | 3 7 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 0 2 | 1 | 1 3 | 1 | 4 4 | 1 | 7 5 | 2 | 0 6 | 2 | 2 7 | 4 | 2 ''' ) t3 = t1.interval_join_left( t2, t1.t, t2.t, pw.temporal.interval(-2, 1), t1.a == t2.b ).select(t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an interval join. Then, each side of the interval join keeps track of the maximal already seen time (self\_time and other\_time). The arguments of behavior mean in the context of an interval join what follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, interval join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Example without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 1 | 1 | 0 | 2 2 | 2 | 2 | 4 3 | 1 | 4 | 4 4 | 2 | 8 | 8 5 | 1 | 0 | 10 6 | 1 | 4 | 10 ''' ) t2 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 42 | 1 | 2 | 2 8 | 2 | 10 | 14 10 | 2 | 4 | 30 ''' ) result_without_cutoff = t1.interval_join_left( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_with_cutoff = t1.interval_join_left( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, behavior=pw.temporal.common_behavior(cutoff=6), ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, )`
`pw.debug.compute_and_print_update_stream(result_with_cutoff, include_id=False)`
Code Results
The record with `value=5` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`0 <= 8-6`). The record with `value=10` from table `t2` was not joined because its `event_time` was equal to the maximal already seen time minus `cutoff` (`4 <= 10-6`).
Notice also the entries with `__diff__=-1`. They’re deletion entries caused by the arrival of matching entries on the right side of the join. The matches caused the removal of entries without values in the fields from the right side and insertion of entries with values in these fields.
[**interval\_join\_outer**(self, other, self\_time, other\_time, interval, \*on, behavior=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.interval_join_outer)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_interval_join.py#L1400-L1619)
Performs an interval outer join of self with other using a time difference and join expressions. If self\_time + lower\_bound <= other\_time <= self\_time + upper\_bound and conditions in on are satisfied, the rows are joined. Rows that haven’t been matched with the other side are returned with missing values on the other side replaced with None.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of the join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **lower\_bound** – a lower bound on time difference between other\_time and self\_time.
* **upper\_bound** – an upper bound on time difference between other\_time and self\_time.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines temporal behavior of a join - features like delaying entries or ignoring late entries.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_IntervalJoinResult_ – a result of the interval join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 3 2 | 4 3 | 5 4 | 11 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 0 2 | 1 3 | 4 4 | 7 ''' ) t3 = t1.interval_join_outer(t2, t1.t, t2.t, pw.temporal.interval(-2, 1)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 3 2 | 1 | 4 3 | 1 | 5 4 | 1 | 11 5 | 2 | 2 6 | 2 | 3 7 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 0 2 | 1 | 1 3 | 1 | 4 4 | 1 | 7 5 | 2 | 0 6 | 2 | 2 7 | 4 | 2 ''' ) t3 = t1.interval_join_outer( t2, t1.t, t2.t, pw.temporal.interval(-2, 1), t1.a == t2.b ).select(t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an interval join. Then, each side of the interval join keeps track of the maximal already seen time (self\_time and other\_time). The arguments of behavior mean in the context of an interval join what follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, interval join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Example without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 1 | 1 | 0 | 2 2 | 2 | 2 | 4 3 | 1 | 4 | 4 4 | 2 | 8 | 8 5 | 1 | 0 | 10 6 | 1 | 4 | 10 ''' ) t2 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 42 | 1 | 2 | 2 8 | 2 | 10 | 14 10 | 2 | 4 | 30 ''' ) result_without_cutoff = t1.interval_join_outer( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_with_cutoff = t1.interval_join_outer( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, behavior=pw.temporal.common_behavior(cutoff=6), ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, )`
`pw.debug.compute_and_print_update_stream(result_with_cutoff, include_id=False)`
Code Results
The record with `value=5` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`0 <= 8-6`). The record with `value=10` from table `t2` was not joined because its `event_time` was equal to the maximal already seen time minus `cutoff` (`4 <= 10-6`).
Notice also the entries with `__diff__=-1`. They’re deletion entries caused by the arrival of matching entries on the right side of the join. The matches caused the removal of entries without values in the fields from the right side and insertion of entries with values in these fields.
[**interval\_join\_right**(self, other, self\_time, other\_time, interval, \*on, behavior=None, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.interval_join_right)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_interval_join.py#L1194-L1397)
Performs an interval right join of self with other using a time difference and join expressions. If self\_time + lower\_bound <= other\_time <= self\_time + upper\_bound and conditions in on are satisfied, the rows are joined. Rows from the right side that haven’t been matched with the left side are returned with missing values on the left side replaced with None.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of the join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **lower\_bound** – a lower bound on time difference between other\_time and self\_time.
* **upper\_bound** – an upper bound on time difference between other\_time and self\_time.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == as the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **behavior** ([`CommonBehavior`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.temporal_behavior.CommonBehavior)
| `None`) – defines temporal behavior of a join - features like delaying entries or ignoring late entries.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_IntervalJoinResult_ – a result of the interval join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 3 2 | 4 3 | 5 4 | 11 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 0 2 | 1 3 | 4 4 | 7 ''' ) t3 = t1.interval_join_right(t2, t1.t, t2.t, pw.temporal.interval(-2, 1)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 3 2 | 1 | 4 3 | 1 | 5 4 | 1 | 11 5 | 2 | 2 6 | 2 | 3 7 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 0 2 | 1 | 1 3 | 1 | 4 4 | 1 | 7 5 | 2 | 0 6 | 2 | 2 7 | 4 | 2 ''' ) t3 = t1.interval_join_right( t2, t1.t, t2.t, pw.temporal.interval(-2, 1), t1.a == t2.b ).select(t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
Setting behavior allows to control temporal behavior of an interval join. Then, each side of the interval join keeps track of the maximal already seen time (self\_time and other\_time). The arguments of behavior mean in the context of an interval join what follows:
* **delay** - buffers results until the maximal already seen time is greater than or equal to their time plus delay.
* **cutoff** - ignores records with times less or equal to the maximal already seen time minus cutoff; it is also used to garbage collect records that have times lower or equal to the above threshold. When cutoff is not set, interval join will remember all records from both sides.
* **keep\_results** - if set to True, keeps all results of the operator. If set to False, keeps only results that are newer than the maximal seen time minus cutoff.
Example without and with forgetting:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 1 | 1 | 0 | 2 2 | 2 | 2 | 4 3 | 1 | 4 | 4 4 | 2 | 8 | 8 5 | 1 | 0 | 10 6 | 1 | 4 | 10 ''' ) t2 = pw.debug.table_from_markdown( ''' value | instance | event_time | __time__ 42 | 1 | 2 | 2 8 | 2 | 10 | 14 10 | 2 | 4 | 30 ''' ) result_without_cutoff = t1.interval_join_right( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_without_cutoff, include_id=False)`
Code Results
`result_with_cutoff = t1.interval_join_right( t2, t1.event_time, t2.event_time, pw.temporal.interval(-2, 2), t1.instance == t2.instance, behavior=pw.temporal.common_behavior(cutoff=6), ).select( left_value=t1.value, right_value=t2.value, instance=t1.instance, left_time=t1.event_time, right_time=t2.event_time, ) pw.debug.compute_and_print_update_stream(result_with_cutoff, include_id=False)`
Code Results
The record with `value=5` from table `t1` was not joined because its `event_time` was less than the maximal already seen time minus `cutoff` (`0 <= 8-6`). The record with `value=10` from table `t2` was not joined because its `event_time` was equal to the maximal already seen time minus `cutoff` (`4 <= 10-6`).
[**intervals\_over**(\*, at, lower\_bound, upper\_bound, is\_outer=True)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.intervals_over)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window.py#L697-L761)
Allows grouping together elements within a window.
Windows are created for each time t in at, by taking values with times within \[t+lower\_bound, t+upper\_bound\].
Note: If a tuple reducer will be used on grouped elements within a window, values in the tuple will be sorted according to their time column.
* **Parameters**
* **lower\_bound** (`int` | `float` | `timedelta`) – lower bound for interval
* **upper\_bound** (`int` | `float` | `timedelta`) – upper bound for interval
* **at** ([`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)
) – column of times for which windows are to be created
* **is\_outer** (`bool`) – decides whether empty windows should return None or be omitted
* **Returns**
_Window_ – object to pass as an argument to .windowby()
Examples:
`import pathway as pw t = pw.debug.table_from_markdown( ''' | t | v 1 | 1 | 10 2 | 2 | 1 3 | 4 | 3 4 | 8 | 2 5 | 9 | 4 6 | 10| 8 7 | 1 | 9 8 | 2 | 16 ''') probes = pw.debug.table_from_markdown( ''' t 2 4 6 8 10 ''') result = ( pw.temporal.windowby(t, t.t, window=pw.temporal.intervals_over( at=probes.t, lower_bound=-2, upper_bound=1 )) .reduce(pw.this._pw_window_location, v=pw.reducers.sorted_tuple(pw.this.v)) ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**session**(\*, predicate=None, max\_gap=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.session)
-----------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window.py#L499-L560)
Allows grouping together elements within a window across ordered time-like data column by locally grouping adjacent elements either based on a maximum time difference or using a custom predicate.
**NOTE**: Usually used as an argument of .windowby(). Exactly one of the arguments predicate or max\_gap should be provided.
* **Parameters**
* **predicate** (`Callable`\[\[`Any`, `Any`\], `bool`\] | `None`) – function taking two adjacent entries that returns a boolean saying whether the two entries should be grouped
* **max\_gap** (`int` | `float` | `timedelta` | `None`) – Two adjacent entries will be grouped if b - a < max\_gap
* **Returns**
_Window_ – object to pass as an argument to .windowby()
Examples:
`import pathway as pw t = pw.debug.table_from_markdown( ''' | instance | t | v 1 | 0 | 1 | 10 2 | 0 | 2 | 1 3 | 0 | 4 | 3 4 | 0 | 8 | 2 5 | 0 | 9 | 4 6 | 0 | 10| 8 7 | 1 | 1 | 9 8 | 1 | 2 | 16 ''') result = t.windowby( t.t, window=pw.temporal.session(predicate=lambda a, b: abs(a-b) <= 1), instance=t.instance ).reduce( pw.this._pw_instance, pw.this._pw_window_start, pw.this._pw_window_end, min_t=pw.reducers.min(pw.this.t), max_v=pw.reducers.max(pw.this.v), count=pw.reducers.count(), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**sliding**(hop, duration=None, ratio=None, origin=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.sliding)
---------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window.py#L563-L636)
Allows grouping together elements within a window of a given length sliding across ordered time-like data column according to a specified interval (hop) starting from a given origin.
**NOTE**: Usually used as an argument of .windowby(). Exactly one of the arguments hop or ratio should be provided.
* **Parameters**
* **hop** (`int` | `float` | `timedelta`) – frequency of a window
* **duration** (`int` | `float` | `timedelta` | `None`) – length of the window
* **ratio** (`int` | `None`) – used as an alternative way to specify duration as hop \* ratio
* **origin** (`int` | `float` | `datetime` | `None`) – a point in time at which the first window begins
* **Returns**
_Window_ – object to pass as an argument to .windowby()
Examples:
`import pathway as pw t = pw.debug.table_from_markdown( ''' | instance | t 1 | 0 | 12 2 | 0 | 13 3 | 0 | 14 4 | 0 | 15 5 | 0 | 16 6 | 0 | 17 7 | 1 | 10 8 | 1 | 11 ''') result = t.windowby( t.t, window=pw.temporal.sliding(duration=10, hop=3), instance=t.instance ).reduce( pw.this._pw_instance, pw.this._pw_window_start, pw.this._pw_window_end, min_t=pw.reducers.min(pw.this.t), max_t=pw.reducers.max(pw.this.t), count=pw.reducers.count(), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**tumbling**(duration, origin=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.tumbling)
-------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window.py#L639-L694)
Allows grouping together elements within a window of a given length tumbling across ordered time-like data column starting from a given origin.
**NOTE**: Usually used as an argument of .windowby().
* **Parameters**
* **duration** (`int` | `float` | `timedelta`) – length of the window
* **origin** (`int` | `float` | `datetime` | `None`) – a point in time at which the first window begins
* **Returns**
_Window_ – object to pass as an argument to .windowby()
Examples:
`import pathway as pw t = pw.debug.table_from_markdown( ''' | instance | t 1 | 0 | 12 2 | 0 | 13 3 | 0 | 14 4 | 0 | 15 5 | 0 | 16 6 | 0 | 17 7 | 1 | 12 8 | 1 | 13 ''') result = t.windowby( t.t, window=pw.temporal.tumbling(duration=5), instance=t.instance ).reduce( pw.this._pw_instance, pw.this._pw_window_start, pw.this._pw_window_end, min_t=pw.reducers.min(pw.this.t), max_t=pw.reducers.max(pw.this.t), count=pw.reducers.count(), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[**utc\_now**(refresh\_rate=datetime.timedelta(seconds=60), initial\_delay=datetime.timedelta(0))](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.utc_now)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/time_utils.py#L41-L63)
Provides a continuously updating stream of the current UTC time.
This function generates a real-time feed of the current UTC timestamp, refreshing at a specified interval.
* **Parameters**
**refresh\_rate** (`timedelta`) – The interval at which the current UTC time is refreshed. Defaults to 60 seconds.
* **Returns**
A table containing a stream of the current UTC timestamps, updated according to the specified refresh rate.
[**window\_join**(self, other, self\_time, other\_time, window, \*on, how=JoinMode.INNER, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.window_join)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window_join.py#L152-L353)
Performs a window join of self with other using a window and join expressions. If two records belong to the same window and meet the conditions specified in the on clause, they will be joined. Note that if a sliding window is used and there are pairs of matching records that appear in more than one window, they will be included in the result multiple times (equal to the number of windows they appear in).
When using a session window, the function creates sessions by concatenating records from both sides of a join. Only pairs of records that meet the conditions specified in the on clause can be part of the same session. The result of a given session will include all records from the left side of a join that belong to this session, joined with all records from the right side of a join that belong to this session.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **window** ([`Window`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Window)
) – a window to use.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == on the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **how** ([`JoinMode`](https://pathway.com/developers/api-docs/pathway#pathway.JoinMode)
) – decides whether to run window\_join\_inner, window\_join\_left, window\_join\_right or window\_join\_outer. Default is INNER.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_WindowJoinResult_ – a result of the window join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 1 2 | 2 3 | 3 4 | 7 5 | 13 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 2 2 | 5 3 | 6 4 | 7 ''' ) t3 = t1.window_join(t2, t1.t, t2.t, pw.temporal.tumbling(2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t4 = t1.window_join(t2, t1.t, t2.t, pw.temporal.sliding(1, 2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t4, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 2 3 | 1 | 3 4 | 1 | 7 5 | 1 | 13 6 | 2 | 1 7 | 2 | 2 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 2 2 | 1 | 5 3 | 1 | 6 4 | 1 | 7 5 | 2 | 2 6 | 2 | 3 7 | 4 | 3 ''' ) t3 = t1.window_join(t2, t1.t, t2.t, pw.temporal.tumbling(2), t1.a == t2.b).select( key=t1.a, left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | t 0 | 0 1 | 5 2 | 10 3 | 15 4 | 17 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 0 | -3 1 | 2 2 | 3 3 | 6 4 | 16 ''' ) t3 = t1.window_join( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2) ).select(left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 4 3 | 1 | 7 4 | 2 | 0 5 | 2 | 3 6 | 2 | 4 7 | 2 | 7 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | -1 2 | 1 | 6 3 | 2 | 2 4 | 2 | 10 5 | 4 | 3 ''' ) t3 = t1.window_join( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2), t1.a == t2.b ).select(key=t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
[**window\_join\_inner**(self, other, self\_time, other\_time, window, \*on, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.window_join_inner)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window_join.py#L356-L554)
Performs a window join of self with other using a window and join expressions. If two records belong to the same window and meet the conditions specified in the on clause, they will be joined. Note that if a sliding window is used and there are pairs of matching records that appear in more than one window, they will be included in the result multiple times (equal to the number of windows they appear in).
When using a session window, the function creates sessions by concatenating records from both sides of a join. Only pairs of records that meet the conditions specified in the on clause can be part of the same session. The result of a given session will include all records from the left side of a join that belong to this session, joined with all records from the right side of a join that belong to this session.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **window** ([`Window`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Window)
) – a window to use.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == on the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_WindowJoinResult_ – a result of the window join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 1 2 | 2 3 | 3 4 | 7 5 | 13 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 2 2 | 5 3 | 6 4 | 7 ''' ) t3 = t1.window_join_inner(t2, t1.t, t2.t, pw.temporal.tumbling(2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t4 = t1.window_join_inner(t2, t1.t, t2.t, pw.temporal.sliding(1, 2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t4, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 2 3 | 1 | 3 4 | 1 | 7 5 | 1 | 13 6 | 2 | 1 7 | 2 | 2 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 2 2 | 1 | 5 3 | 1 | 6 4 | 1 | 7 5 | 2 | 2 6 | 2 | 3 7 | 4 | 3 ''' ) t3 = t1.window_join_inner(t2, t1.t, t2.t, pw.temporal.tumbling(2), t1.a == t2.b).select( key=t1.a, left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | t 0 | 0 1 | 5 2 | 10 3 | 15 4 | 17 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 0 | -3 1 | 2 2 | 3 3 | 6 4 | 16 ''' ) t3 = t1.window_join_inner( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2) ).select(left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 4 3 | 1 | 7 4 | 2 | 0 5 | 2 | 3 6 | 2 | 4 7 | 2 | 7 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | -1 2 | 1 | 6 3 | 2 | 2 4 | 2 | 10 5 | 4 | 3 ''' ) t3 = t1.window_join_inner( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2), t1.a == t2.b ).select(key=t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
[**window\_join\_left**(self, other, self\_time, other\_time, window, \*on, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.window_join_left)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window_join.py#L557-L774)
Performs a window left join of self with other using a window and join expressions. If two records belong to the same window and meet the conditions specified in the on clause, they will be joined. Note that if a sliding window is used and there are pairs of matching records that appear in more than one window, they will be included in the result multiple times (equal to the number of windows they appear in).
When using a session window, the function creates sessions by concatenating records from both sides of a join. Only pairs of records that meet the conditions specified in the on clause can be part of the same session. The result of a given session will include all records from the left side of a join that belong to this session, joined with all records from the right side of a join that belong to this session.
Rows from the left side that didn’t match with any record on the right side in a given window, are returned with missing values on the right side replaced with None. The multiplicity of such rows equals the number of windows they belong to and don’t have a match in them.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **window** ([`Window`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Window)
) – a window to use.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == on the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_WindowJoinResult_ – a result of the window join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 1 2 | 2 3 | 3 4 | 7 5 | 13 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 2 2 | 5 3 | 6 4 | 7 ''' ) t3 = t1.window_join_left(t2, t1.t, t2.t, pw.temporal.tumbling(2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t4 = t1.window_join_left(t2, t1.t, t2.t, pw.temporal.sliding(1, 2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t4, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 2 3 | 1 | 3 4 | 1 | 7 5 | 1 | 13 6 | 2 | 1 7 | 2 | 2 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 2 2 | 1 | 5 3 | 1 | 6 4 | 1 | 7 5 | 2 | 2 6 | 2 | 3 7 | 4 | 3 ''' ) t3 = t1.window_join_left(t2, t1.t, t2.t, pw.temporal.tumbling(2), t1.a == t2.b).select( key=t1.a, left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | t 0 | 0 1 | 5 2 | 10 3 | 15 4 | 17 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 0 | -3 1 | 2 2 | 3 3 | 6 4 | 16 ''' ) t3 = t1.window_join_left( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2) ).select(left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 4 3 | 1 | 7 4 | 2 | 0 5 | 2 | 3 6 | 2 | 4 7 | 2 | 7 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | -1 2 | 1 | 6 3 | 2 | 2 4 | 2 | 10 5 | 4 | 3 ''' ) t3 = t1.window_join_left( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2), t1.a == t2.b ).select(key=t1.a, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
[**window\_join\_outer**(self, other, self\_time, other\_time, window, \*on, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.window_join_outer)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window_join.py#L992-L1217)
Performs a window outer join of self with other using a window and join expressions. If two records belong to the same window and meet the conditions specified in the on clause, they will be joined. Note that if a sliding window is used and there are pairs of matching records that appear in more than one window, they will be included in the result multiple times (equal to the number of windows they appear in).
When using a session window, the function creates sessions by concatenating records from both sides of a join. Only pairs of records that meet the conditions specified in the on clause can be part of the same session. The result of a given session will include all records from the left side of a join that belong to this session, joined with all records from the right side of a join that belong to this session.
Rows from both sides that didn’t match with any record on the other side in a given window, are returned with missing values on the other side replaced with None. The multiplicity of such rows equals the number of windows they belong to and don’t have a match in them.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **window** ([`Window`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Window)
) – a window to use.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == on the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_WindowJoinResult_ – a result of the window join. A method .select() can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 1 2 | 2 3 | 3 4 | 7 5 | 13 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 2 2 | 5 3 | 6 4 | 7 ''' ) t3 = t1.window_join_outer(t2, t1.t, t2.t, pw.temporal.tumbling(2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t4 = t1.window_join_outer(t2, t1.t, t2.t, pw.temporal.sliding(1, 2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t4, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 2 3 | 1 | 3 4 | 1 | 7 5 | 1 | 13 6 | 2 | 1 7 | 2 | 2 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 2 2 | 1 | 5 3 | 1 | 6 4 | 1 | 7 5 | 2 | 2 6 | 2 | 3 7 | 4 | 3 ''' ) t3 = t1.window_join_outer(t2, t1.t, t2.t, pw.temporal.tumbling(2), t1.a == t2.b).select( key=pw.coalesce(t1.a, t2.b), left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | t 0 | 0 1 | 5 2 | 10 3 | 15 4 | 17 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 0 | -3 1 | 2 2 | 3 3 | 6 4 | 16 ''' ) t3 = t1.window_join_outer( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2) ).select(left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 4 3 | 1 | 7 4 | 2 | 0 5 | 2 | 3 6 | 2 | 4 7 | 2 | 7 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | -1 2 | 1 | 6 3 | 2 | 2 4 | 2 | 10 5 | 4 | 3 ''' ) t3 = t1.window_join_outer( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2), t1.a == t2.b ).select(key=pw.coalesce(t1.a, t2.b), left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
[**window\_join\_right**(self, other, self\_time, other\_time, window, \*on, left\_instance=None, right\_instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.window_join_right)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window_join.py#L777-L989)
Performs a window right join of self with other using a window and join expressions. If two records belong to the same window and meet the conditions specified in the on clause, they will be joined. Note that if a sliding window is used and there are pairs of matching records that appear in more than one window, they will be included in the result multiple times (equal to the number of windows they appear in).
When using a session window, the function creates sessions by concatenating records from both sides of a join. Only pairs of records that meet the conditions specified in the on clause can be part of the same session. The result of a given session will include all records from the left side of a join that belong to this session, joined with all records from the right side of a join that belong to this session.
Rows from the right side that didn’t match with any record on the left side in a given window, are returned with missing values on the left side replaced with None. The multiplicity of such rows equals the number of windows they belong to and don’t have a match in them.
* **Parameters**
* **other** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – the right side of a join.
* **self\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in self.
* **other\_time** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – time expression in other.
* **window** ([`Window`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Window)
) – a window to use.
* **on** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
) – a list of column expressions. Each must have == on the top level operation and be of the form LHS: ColumnReference == RHS: ColumnReference.
* **left\_instance/right\_instance** – optional arguments describing partitioning of the data into separate instances
* **Returns**
_WindowJoinResult_ – a result of the window join. A method `.select()` can be called on it to extract relevant columns from the result of a join.
Examples:
`import pathway as pw t1 = pw.debug.table_from_markdown( ''' | t 1 | 1 2 | 2 3 | 3 4 | 7 5 | 13 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 1 | 2 2 | 5 3 | 6 4 | 7 ''' ) t3 = t1.window_join_right(t2, t1.t, t2.t, pw.temporal.tumbling(2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t4 = t1.window_join_right(t2, t1.t, t2.t, pw.temporal.sliding(1, 2)).select( left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t4, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 2 3 | 1 | 3 4 | 1 | 7 5 | 1 | 13 6 | 2 | 1 7 | 2 | 2 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | 2 2 | 1 | 5 3 | 1 | 6 4 | 1 | 7 5 | 2 | 2 6 | 2 | 3 7 | 4 | 3 ''' ) t3 = t1.window_join_right(t2, t1.t, t2.t, pw.temporal.tumbling(2), t1.a == t2.b).select( key=t2.b, left_t=t1.t, right_t=t2.t ) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | t 0 | 0 1 | 5 2 | 10 3 | 15 4 | 17 ''' ) t2 = pw.debug.table_from_markdown( ''' | t 0 | -3 1 | 2 2 | 3 3 | 6 4 | 16 ''' ) t3 = t1.window_join_right( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2) ).select(left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
`t1 = pw.debug.table_from_markdown( ''' | a | t 1 | 1 | 1 2 | 1 | 4 3 | 1 | 7 4 | 2 | 0 5 | 2 | 3 6 | 2 | 4 7 | 2 | 7 8 | 3 | 4 ''' ) t2 = pw.debug.table_from_markdown( ''' | b | t 1 | 1 | -1 2 | 1 | 6 3 | 2 | 2 4 | 2 | 10 5 | 4 | 3 ''' ) t3 = t1.window_join_right( t2, t1.t, t2.t, pw.temporal.session(predicate=lambda a, b: abs(a - b) <= 2), t1.a == t2.b ).select(key=t2.b, left_t=t1.t, right_t=t2.t) pw.debug.compute_and_print(t3, include_id=False)`
Code Results
[**windowby**(self, time\_expr, \*, window, behavior=None, instance=None)](https://pathway.com/developers/api-docs/temporal#pathway.stdlib.temporal.windowby)
--------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/stdlib/temporal/_window.py#L764-L815)
Create a GroupedTable by windowing the table (based on expr and window), optionally with instance argument.
* **Parameters**
* **time\_expr** (`pw.ColumnExpression[int | float | datetime]`) – Column expression used for windowing
* **window** ([`Window`](https://pathway.com/developers/api-docs/pathway-stdlib-temporal#pathway.stdlib.temporal.Window)
) – type window to use
* **instance** ([`ColumnExpression`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnExpression)
| `None`) – optional column expression to act as a shard key
Examples:
`import pathway as pw t = pw.debug.table_from_markdown( ''' | instance | t | v 1 | 0 | 1 | 10 2 | 0 | 2 | 1 3 | 0 | 4 | 3 4 | 0 | 8 | 2 5 | 0 | 9 | 4 6 | 0 | 10| 8 7 | 1 | 1 | 9 8 | 1 | 2 | 16 ''') result = t.windowby( t.t, window=pw.temporal.session(predicate=lambda a, b: abs(a-b) <= 1), instance=t.instance ).reduce( pw.this.instance, min_t=pw.reducers.min(pw.this.t), max_v=pw.reducers.max(pw.this.v), count=pw.reducers.count(), ) pw.debug.compute_and_print(result, include_id=False)`
Code Results
[API Docs\
\
pw.sql](https://pathway.com/developers/api-docs/sql-api)
[API Docs\
\
pw.udfs](https://pathway.com/developers/api-docs/udfs)
---
# pw.io.mongodb | Pathway
pw.io.mongodb
=============
Pathway Live Data Framework provides both **Input** and **Output** connectors for MongoDB. The tables below describe how the data is converted between the BSON format, used by MongoDB and the Live Data Framework values.
[Type Conversion (Input Connector)](https://pathway.com/developers/api-docs/pathway-io/mongodb#type-conversion-input-connector)
--------------------------------------------------------------------------------------------------------------------------------
The table below describes how BSON field values are parsed into Live Data Framework values, and what type to declare in your `pw.Schema` to receive them correctly.
### [BSON types parsed by the input connector](https://pathway.com/developers/api-docs/pathway-io/mongodb#bson-types-parsed-by-the-input-connector)
| BSON type in document | Live Data Framework schema type and notes |
| --- | --- |
| `Boolean` | `bool` |
| `Int32` / `Int64` | `int` |
| `Double` (also `Int32` / `Int64`) | `float` |
| `String` | `str` |
| `Binary` | `bytes` |
| `String` starting with `^` | `pw.Pointer` — the string is decoded as a Live Data Framework pointer. The string must have been produced by Live Data Framework’s output connector for a `pw.Pointer` column. |
| `DateTime` | `pw.DateTimeNaive` or `pw.DateTimeUtc` — parsed from the millisecond timestamp stored in the BSON `DateTime` value. Sub-millisecond precision is not preserved. |
| `Int64` | `pw.Duration` — interpreted as a number of **milliseconds**. This matches the precision used by the output connector when serializing `pw.Duration` values. |
| `Document`, `Array`, or `String` | `pw.Json` — a BSON `Document` or `Array` is converted directly to a JSON value; a `String` is parsed as a JSON literal. The `String` form is what Live Data Framework’s output connector produces for `pw.Json` columns. |
| `Array` | `tuple` — elements are parsed recursively according to the declared inner types. The array length must match the tuple arity exactly. |
| `Array` | `list` — elements are parsed recursively according to the declared element type. |
| `Array` (nested, rectangular) | `np.ndarray` — the nesting depth of the BSON arrays determines the number of dimensions. A flat BSON array maps to a 1-D ndarray; a BSON array of same-length arrays maps to a 2-D ndarray; and so on. All inner arrays at the same depth must have the same length; jagged arrays raise a parse error. Only `int` and `float` element types are supported. Declare the column as `np.ndarray` with `int` or `float` as the element type in the schema. |
| `Binary` | `pw.PyObjectWrapper` — the binary payload is deserialized with bincode. The field must have been written by Live Data Framework’s output connector for a `pw.PyObjectWrapper` column. |
| `ObjectId` | `str` — the 24-character lowercase hex form (e.g. `"507f1f77bcf86cd799439011"`). Round-trips back as `Bson::String`, not `Bson::ObjectId` — i.e. on subsequent writes the BSON type changes, but the textual value is preserved. |
| `Decimal128` | `str` — the canonical decimal string (e.g. `"1.5E+3"`). This preserves full precision; mapping to `float` is intentionally not offered because it would silently lose digits. |
| `RegularExpression` | `str` — formatted as `"//"` (Perl-style). Both the pattern and the options characters are preserved verbatim; consumers wanting them split need to re-parse this single string. |
| `Timestamp` | `int` — the seconds-since-epoch `time` component of the BSON `Timestamp`. The 32-bit `increment` companion field is dropped; BSON `Timestamp` is primarily a server-internal replication marker and the increment is rarely meaningful at the user-data level. |
| Any nullable field | Declare the field as an optional in the schema. It will be parsed as `None` if the BSON value is `null`; otherwise the value is parsed as type `T`. If the schema field is **not** declared as optional and a `null` is received, an error is raised. |
[Type Conversion (Output Connector)](https://pathway.com/developers/api-docs/pathway-io/mongodb#type-conversion-output-connector)
----------------------------------------------------------------------------------------------------------------------------------
The table below describes how Live Data Framework types are serialized into BSON when writing to MongoDB. All listed types can be round-tripped back via the input connector when the original schema type is specified.
### [Pathway types serialized by the output connector](https://pathway.com/developers/api-docs/pathway-io/mongodb#pathway-types-serialized-by-the-output-connector)
| Live Data Framework type | BSON type and notes |
| --- | --- |
| `bool` | `Boolean` |
| `int` | `Int64` |
| `float` | `Double` |
| `pointer` | `String`, formatted as a `^`\-prefixed hex string. Can be deserialized back if `pw.Pointer` is declared in the schema on read. |
| `str` | `String` |
| `bytes` | `Binary` (generic subtype) |
| `Naive DateTime` | `DateTime`, serialized with **millisecond** precision. Sub-millisecond components are truncated. |
| `UTC DateTime` | `DateTime`, serialized with **millisecond** precision. Sub-millisecond components are truncated. |
| `Duration` | `Int64`, the number of **milliseconds**. The millisecond granularity matches that of the BSON `DateTime` type. Declare the field as `pw.Duration` on read to restore the original value. |
| `JSON` | `String`, containing the serialized JSON value. Declare the field as `pw.Json` on read — the input connector accepts both a `String` containing a JSON literal and a native BSON `Document`. |
| `np.ndarray` | Nested `Array` that preserves the shape of the ndarray. A 1-D array is stored as a flat BSON array; a 2-D array is stored as a BSON array of arrays; and so on for higher dimensions. Element type is `Int64` for integer arrays and `Double` for float arrays. Can be round-tripped back as `np.ndarray` via the input connector when the column is declared as `np.ndarray` with `int` or `float` as the element type in the schema. |
| `tuple` | `Array` — elements are serialized recursively. |
| `list` | `Array` — elements are serialized recursively. |
| `pw.PyObjectWrapper` | `Binary` (generic subtype), serialized with bincode. Can be deserialized back if `pw.PyObjectWrapper` is declared in the schema on read. |
[MongoDB Atlas and Vector Search](https://pathway.com/developers/api-docs/pathway-io/mongodb#mongodb-atlas-and-vector-search)
------------------------------------------------------------------------------------------------------------------------------
[MongoDB Atlas](https://www.mongodb.com/atlas)
is the fully managed, cloud-hosted version of MongoDB. It speaks the same wire protocol as a self-managed deployment, so **the same** `pw.io.mongodb.read` **and** `pw.io.mongodb.write` **connectors target Atlas directly** — there is no separate Atlas connector to import. To point Pathway at an Atlas cluster, pass the cluster’s `mongodb+srv://` connection string (copy it from the Atlas UI under _Connect → Drivers_) as `connection_string`:
`import pathway as pw pw.io.mongodb.write( table, connection_string="mongodb+srv://USER:PASSWORD@cluster0.xxxxx.mongodb.net/?retryWrites=true&w=majority", database="my_database", collection="my_collection", )`
The `mongodb+srv://` seed-list (SRV) scheme is resolved by the underlying driver out of the box, including TLS and SCRAM authentication — no extra configuration is required on the Pathway side.
### [Writing vector embeddings](https://pathway.com/developers/api-docs/pathway-io/mongodb#writing-vector-embeddings)
Atlas’s flagship capability is **Atlas Vector Search**: an approximate nearest-neighbor index over embedding vectors, queried with the `$vectorSearch` aggregation stage. Pathway can populate the vectors for that index with no special handling — a `numpy` array column is serialized to a BSON array of numbers (see the `np.ndarray` row of the output type-conversion table above), which is exactly the on-disk shape Atlas Vector Search expects:
``import numpy as np import numpy.typing as npt import pathway as pw class Embeddings(pw.Schema): doc_id: int embedding: npt.NDArray[np.float64] # e.g. a 736-dimensional vector # `embeddings` is any table whose `embedding` column holds numpy float vectors, # for example the output of an embedder UDF in a RAG pipeline. pw.io.mongodb.write( embeddings, connection_string="mongodb+srv://...", database="vector_db", collection="embeddings", output_table_type="snapshot", )``
Use `output_table_type="snapshot"` for a vector store: it keeps exactly one document per Pathway row (upserting and deleting by `_id`), so the collection always mirrors the current state of the table and never accumulates stale vectors.
### [Creating the Atlas Vector Search index](https://pathway.com/developers/api-docs/pathway-io/mongodb#creating-the-atlas-vector-search-index)
Written vectors become searchable once a `vectorSearch` index exists on the embedding field. That index is **not** created by Pathway — it is an Atlas object created once through the Atlas UI, the Atlas Administration API, or the standard MongoDB driver. The `numDimensions` must match the length of the vectors Pathway writes (for example `736`):
`from pymongo import MongoClient from pymongo.operations import SearchIndexModel client = MongoClient("mongodb+srv://...") client["vector_db"]["embeddings"].create_search_index( SearchIndexModel( definition={ "fields": [ { "type": "vector", "path": "embedding", "numDimensions": 736, "similarity": "cosine", # or "dotProduct" / "euclidean" } ] }, name="pw_vector_index", type="vectorSearch", ) )`
Once the index reports itself as queryable, run a nearest-neighbor search with `$vectorSearch`:
`client["vector_db"]["embeddings"].aggregate([ {"$vectorSearch": { "index": "pw_vector_index", "path": "embedding", "queryVector": query_vector, # a list[float] of length 736 "numCandidates": 100, "limit": 5, }}, {"$project": {"_id": 0, "doc_id": 1, "score": {"$meta": "vectorSearchScore"}}}, ])`
### [Parallelism and throughput](https://pathway.com/developers/api-docs/pathway-io/mongodb#parallelism-and-throughput)
Under `pathway spawn -n N` the MongoDB output connector **shards the write across all workers**. The engine partitions output by row key, so every change to a given document (`_id`) is handled by exactly one worker — inserts, deletes, and the retract/insert pair of an update all co-locate — which makes both `snapshot` and `stream_of_changes` writes parallel-safe. Write throughput then scales with the worker count until the MongoDB/Atlas cluster’s own write capacity (instance tier, sharding) becomes the limit, at which point scaling the cluster is what raises it further.
The one exception is `sort_by`: asking for a global ascending order within each minibatch forces the connector onto a single worker, because that is the only way to guarantee the order across the whole output. A sorted output therefore does not parallelise.
[**read**(connection\_string, database, collection, schema, \*, mode='streaming', autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None)](https://pathway.com/developers/api-docs/pathway-io/mongodb#pathway.io.mongodb.read)
------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mongodb/__init__.py#L22-L316)
**This module is available when using one of the following licenses only:**[Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise](https://pathway.com/pricing)
.
Reads a collection from MongoDB into a Pathway Live Data Framework table.
The connector fetches all documents from the specified collection and maps each document’s fields to table columns according to the `schema` parameter. Field names in the documents must match the column names in the schema exactly.
Most BSON scalar types map to a Pathway Live Data Framework type with the same name (`Boolean` → `bool`, `Int32`/`Int64` → `int`, `Double` → `float`, `String` → `str`, `Binary` → `bytes`, `DateTime` → `pw.DateTimeNaive` or `pw.DateTimeUtc`, etc.). The following BSON-extended types are also supported when the schema declares the column as `str` (or `int` for `Timestamp`):
* `ObjectId` → `str` — the 24-character lowercase hex form.
* `Decimal128` → `str` — the canonical decimal string (no precision loss).
* `RegularExpression` → `str` — formatted as `"//"`.
* `Timestamp` → `int` — the seconds-since-epoch `time` component; the `increment` companion is dropped.
Writes do not produce these BSON-extended types — they emit `String` / `Int64`, so a write+read round-trip preserves the textual/integer value but not the original BSON type tag. See the conversion table in the `pw.io.mongodb` reference for the full list of supported mappings.
**Note:** Specifying a primary key in the schema is not supported. The connector uses MongoDB’s `_id` field as the Pathway Live Data Framework row key, ensuring that document identity is preserved consistently across the initial snapshot and subsequent incremental updates. Using a different primary key could cause mismatches between The Pathway Live Data Framework’s internal state and the actual collection contents. To reindex the resulting table by a different column, use `pw.Table.with_id_from()` after reading.
In `"streaming"` mode (the default), the connector first emits the full collection as an initial snapshot, then subscribes to MongoDB’s change stream to receive incremental inserts, replacements, updates, and deletions in real time. In `"static"` mode, the connector reads the collection once and terminates without continuing to watch for live changes.
**Replica set is required in both modes.** Even in `"static"` mode, the connector briefly opens a change stream to capture the oplog position before and after the initial dump, so that any writes that race with the dump are applied before the pipeline terminates. Because change streams are backed by the oplog, the collection must be part of a [replica set](https://www.mongodb.com/docs/manual/replication/)
or a sharded cluster — a standalone MongoDB instance without replica set configuration does not support this.
When persistence is enabled, the connector saves the oplog position — specifically, the change stream resume token of the last processed event — as its offset. On restart, it resumes from that token and delivers only the changes that occurred since the last checkpoint, so the downstream computation sees only the new delta rather than the full collection again. The `name` parameter is required when using persistence, so that the engine can match the connector to its saved state across restarts.
**Stream-terminating events.** MongoDB change streams end permanently after a `drop` (collection drop), `rename`, `dropDatabase`, or `invalidate` event — the saved resume token cannot be extended past them. When the connector encounters such an event it raises an error asking the user to delete the persistence directory and restart, so that events on a future recreated collection are not silently lost.
**Parallelism.** This connector runs on a single worker thread, even when the The Pathway Live Data Framework program is launched with `pathway spawn -n N` (multiple threads) or `pathway spawn --addresses ...` (multiple processes). MongoDB change streams deliver events in oplog order from a single cursor, so partitioning the input across workers would either drop ordering guarantees or duplicate events. Downstream Pathway Live Data Framework operators still parallelize across all workers; only the initial read from MongoDB is serialized.
* **Parameters**
* **connection\_string** (`str`) – The connection string for the MongoDB deployment. See the [MongoDB documentation](https://www.mongodb.com/docs/manual/reference/connection-string/)
for the details.
* **database** (`str`) – The name of the database to read from.
* **collection** (`str`) – The name of the collection to read.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Schema of the resulting table. Column names must match the field names in the MongoDB documents. Specifying a primary key in the schema is not supported; see above for details.
* **mode** (`Literal`\[`'static'`, `'streaming'`\]) – If set to `"streaming"` (the default), the connector first delivers the initial collection snapshot and then continuously watches for new changes via the change stream. If set to `"static"`, it reads the collection once and terminates without opening a change stream.
* **autocommit\_duration\_ms** (`int` | `None`) – The maximum time between two commits. Every autocommit\_duration\_ms milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
To get started, you need to run MongoDB locally. The connector uses MongoDB’s change stream, which requires a replica set. The easiest way to spin up a single-node replica set with Docker is:
`docker pull mongo docker run -d --name mongo -p 27017:27017 mongo --replSet rs0`
The `--replSet rs0` flag enables replica set mode. After the container starts, initialize the replica set with:
`docker exec -it mongo mongosh --eval "rs.initiate()"`
You only need to do this once. Once the replica set is up, connect to the shell to insert some sample data:
`docker exec -it mongo mongosh`
Inside the shell, create a collection and populate it:
`use shop db.orders.insertMany([ { product: "apple", qty: 10 }, { product: "banana", qty: 5 }, { product: "cherry", qty: 20 }, ])`
With data in place, define a matching schema in the Pathway Live Data Framework. Note that no primary key is declared — the connector derives the row key from each document’s `_id`.
`import pathway as pw class OrderSchema(pw.Schema): product: str qty: int`
**Static mode.** To read the collection once and stop, use `mode="static"`. This is suitable for batch pipelines that process all available documents and then terminate.
`table = pw.io.mongodb.read( "mongodb://127.0.0.1:27017/?replicaSet=rs0", database="shop", collection="orders", schema=OrderSchema, mode="static", ) pw.debug.compute_and_print(table, include_id=False)`
Code Results
**Streaming mode.** When `mode="streaming"` (the default), the connector first delivers the full collection as an initial snapshot and then continues to watch for changes. Every insert, replacement, update, or deletion in MongoDB is forwarded to the Pathway Live Data Framework in real time.
`table = pw.io.mongodb.read( "mongodb://127.0.0.1:27017/?replicaSet=rs0", database="shop", collection="orders", schema=OrderSchema, )`
After the snapshot is delivered, any change made in the MongoDB shell will be reflected in the Pathway Live Data Framework immediately. For example, running the following in `mongosh`:
`db.orders.insertOne({ product: "durian", qty: 2 })`
will cause Pathway Live Data Framework to receive a new row `{ product: "durian", qty: 2 }` with `diff = 1`. Running:
`db.orders.deleteOne({ product: "banana" })`
will cause Pathway Live Data Framework to retract the `banana` row with `diff = -1`.
**Persistence in static mode.** With persistence enabled, the connector records the oplog position after each run. On the next run it resumes from that position and delivers only the documents that changed since the last checkpoint, so the output contains the delta rather than the full collection.
`persistence_config = pw.persistence.Config( backend=pw.persistence.Backend.filesystem("./PStorage") ) table = pw.io.mongodb.read( "mongodb://127.0.0.1:27017/?replicaSet=rs0", database="shop", collection="orders", schema=OrderSchema, mode="static", name="orders_source", ) pw.io.jsonlines.write(table, "output.jsonl") pw.run(persistence_config=persistence_config)`
On the first run, `output.jsonl` will contain all three documents with `diff = 1`. If you then insert a new document into the collection and run the program again with the same `persistence_config`, only the newly inserted document will appear in the output.
**Persistence in streaming mode.** Persistence works the same way in streaming mode. Pass the same `persistence_config` to `pw.run()` and provide the same `name` to `pw.io.mongodb.read()` so the engine can find the saved offset:
`table = pw.io.mongodb.read( "mongodb://127.0.0.1:27017/?replicaSet=rs0", database="shop", collection="orders", schema=OrderSchema, name="orders_source", ) pw.run(persistence_config=persistence_config)`
If the program is restarted, it will resume from the saved oplog position and emit only the changes that arrived after the previous run terminated, without replaying the initial snapshot.
[**write**(table, \*, connection\_string, database, collection, output\_table\_type='stream\_of\_changes', max\_batch\_size=None, name=None, sort\_by=None)](https://pathway.com/developers/api-docs/pathway-io/mongodb#pathway.io.mongodb.write)
--------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/mongodb/__init__.py#L319-L688)
Writes `table` to a MongoDB table.
The output table supports two formats, controlled by the `output_table_type` parameter.
The `stream_of_changes` format provides a complete history of all modifications applied to the table. Each entry contains the full data row along with two additional fields: `time` and `diff`. The `time` field identifies the transactional minibatch in which the change occurred, while `diff` describes the nature of the change: `diff = 1` indicates that the row was inserted into the Pathway Live Data Framework table, and `diff = -1` indicates that the row was removed. Row updates are represented as two events within the same transactional minibatch: first the old version of the row with `diff = -1`, followed by the new version with `diff = 1`. This format is used by default. Because `time` and `diff` are reserved field names in this format, the input table must not contain columns with these names; otherwise a `ValueError` is raised at construction time.
The `snapshot` format maintains the current state of the Pathway Live Data Framework table in the output. The table’s primary key is stored in the `_id` field. When a change occurs, no additional metadata fields are added; instead, the engine locates the corresponding row by `_id` and applies the update directly. As a result, the output table always reflects the latest state of the Pathway Live Data Framework table.
**Reserved column name**: in both formats, the input table must not contain a column named `_id` — MongoDB uses `_id` as the primary key for every document. A `ValueError` is raised at construction time if this column is present.
If the specified database or table doesn’t exist, it will be created during the first write.
**Note:** Since MongoDB [stores DateTime in milliseconds](https://www.mongodb.com/docs/manual/reference/bson-types/#date)
, the [Duration](https://pathway.com/developers/api-docs/pathway/#pathway.Duration)
type is also serialized as an integer number of milliseconds for consistency.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – The table to output.
* **connection\_string** (`str`) – The connection string for the MongoDB database. See the [MongoDB documentation](https://www.mongodb.com/docs/manual/reference/connection-string/)
for the details.
* **database** (`str`) – The name of the database to update.
* **collection** (`str`) – The name of the collection to write to.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – The type of the output table, defining whether a current snapshot or a history of modifications must be maintained.
* **max\_batch\_size** (`int` | `None`) – The maximum number of entries to insert in one batch.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
To get started, you need to run MongoDB locally. The easiest way to do this, if it isn’t already running, is by using Docker. You can set up MongoDB in Docker with the following commands.
`docker pull mongo docker run -d --name mongo -p 27017:27017 mongo`
The first command pulls the latest MongoDB image from Docker. The second command runs MongoDB in the background, naming the container `mongo` and exposing port `27017` for external connections, such as from your Pathway Live Data Framework program.
If the container doesn’t start, check if port `27017` is already in use. If so, you can map it to a different port.
Once MongoDB is running, you can access its shell with:
`docker exec -it mongo mongosh`
There’s no need to create anything in the new instance at this point.
With MongoDB running, you can proceed with a Pathway Live Data Framework program to write data to the database. Start by importing the Pathway Live Data Framework and creating a test table.
`import pathway as pw pet_owners = pw.debug.table_from_markdown(''' age | owner | pet 10 | Alice | dog 9 | Bob | cat 8 | Alice | cat ''')`
Next, write this data to your MongoDB instance with the Pathway Live Data Framework connector.
`pw.io.mongodb.write( pet_owners, connection_string="mongodb://127.0.0.1:27017/", database="pathway-test", collection="pet-owners", )`
If you’ve changed the port, make sure to update the connection string with the correct one.
You can modify the code to change the data source or add more processing steps. Remember to run the program with `pw.run()` to execute it.
After the program runs, you can check that the database and collection were created. Access the MongoDB shell again and run:
`show dbs`
You should see the `pathway-test` database listed, along with some pre-existing databases:
`admin 40.00 KiB config 60.00 KiB local 40.00 KiB pathway-test 40.00 KiB`
Switch to the `pathway-test` database and list its collections:
`use pathway-test show collections`
You should see:
`pet-owners`
Finally, check the data in the `pet-owners` collection with:
`db["pet-owners"].find().pretty()`
This should return the following entries, along with additional `diff` and `time` fields:
`[ { _id: ObjectId('67180150d94db90697c07853'), age: Long('9'), owner: 'Bob', pet: 'cat', diff: Long('1'), time: Long('0') }, { _id: ObjectId('67180150d94db90697c07854'), age: Long('8'), owner: 'Alice', pet: 'cat', diff: Long('1'), time: Long('0') }, { _id: ObjectId('67180150d94db90697c07855'), age: Long('10'), owner: 'Alice', pet: 'dog', diff: Long('1'), time: Long('0') } ]`
For more advanced setups, such as replica sets, authentication, or custom read/write concerns, refer to the official MongoDB documentation on [connection strings](https://www.mongodb.com/docs/manual/reference/connection-string/)
Note that if you do not need the full history of modifications, you can use the `snapshot` output table type. In this case, the connector configuration would look as follows:
`pw.io.mongodb.write( pet_owners, connection_string="mongodb://127.0.0.1:27017/", database="pathway-test", collection="pet-owners", output_table_type="snapshot", )`
The resulting output will look like the following — note that in `snapshot` mode the `_id` field holds the stringified Pathway row key (a `^`\-prefixed hex string), _not_ a MongoDB `ObjectId`. This is what makes it possible to locate and update the same row on subsequent writes rather than inserting a duplicate.
`[ { _id: '^YYY4HABTRW7T8VX2Q429ZYV70W', age: Long('9'), owner: 'Bob', pet: 'cat', }, { _id: '^Z3QWT294JQSHPSR8KTPG9ECE4W', age: Long('8'), owner: 'Alice', pet: 'cat', }, { _id: '^X1MXHYYG4YM0DB900V28XN5T4W', age: Long('10'), owner: 'Alice', pet: 'dog', } ]`
**Writing to MongoDB Atlas.** [MongoDB Atlas](https://www.mongodb.com/atlas)
is the managed, cloud-hosted version of MongoDB and speaks the same wire protocol, so this same connector writes to it directly — there is no separate Atlas connector. Pass the cluster’s `mongodb+srv://` connection string (copy it from the Atlas UI under _Connect → Drivers_); the SRV scheme, TLS, and authentication are handled by the driver with no extra configuration:
`pw.io.mongodb.write( pet_owners, connection_string="mongodb+srv://user:password@cluster0.xxxxx.mongodb.net/?retryWrites=true&w=majority", database="pathway-test", collection="pet-owners", )`
**Writing vector embeddings for Atlas Vector Search.** A `numpy` array column is serialized to a BSON array of numbers, which is exactly the shape [Atlas Vector Search](https://www.mongodb.com/docs/atlas/atlas-vector-search/)
expects — so embeddings can be written with no special handling. Use `output_table_type="snapshot"` so the collection keeps exactly one document per row and never accumulates stale vectors:
`import numpy as np import numpy.typing as npt import pathway as pw class Embeddings(pw.Schema): doc_id: int embedding: npt.NDArray[np.float64] # e.g. a 736-dimensional vector # ``embeddings`` is any table whose ``embedding`` column holds numpy float # vectors, for example the output of an embedder UDF in a RAG pipeline. pw.io.mongodb.write( embeddings, connection_string="mongodb+srv://...", database="vector_db", collection="embeddings", output_table_type="snapshot", )`
Written vectors become searchable once a `vectorSearch` index exists on the embedding field. Pathway does not create that index — it is an Atlas object you create once through the Atlas UI, the Administration API, or the standard MongoDB driver. `numDimensions` must match the length of the vectors Pathway writes:
`from pymongo import MongoClient from pymongo.operations import SearchIndexModel client = MongoClient("mongodb+srv://...") client["vector_db"]["embeddings"].create_search_index( SearchIndexModel( definition={ "fields": [ { "type": "vector", "path": "embedding", "numDimensions": 736, "similarity": "cosine", } ] }, name="pw_vector_index", type="vectorSearch", ) )`
Once the index is queryable, retrieve nearest neighbors with `$vectorSearch`:
`client["vector_db"]["embeddings"].aggregate([ {"$vectorSearch": { "index": "pw_vector_index", "path": "embedding", "queryVector": query_vector, # a list[float] of length 736 "numCandidates": 100, "limit": 5, }}, {"$project": {"_id": 0, "doc_id": 1, "score": {"$meta": "vectorSearchScore"}}}, ])`
**Note on parallelism.** When the program is run with multiple workers (`pathway spawn -n N`), the write is distributed across them, and write throughput grows with the worker count up to the capacity of the target MongoDB/Atlas deployment. Each document is written by a single worker, so the result is the same as with one worker. The exception is `sort_by`: requesting a global order within a minibatch makes the connector write from a single worker, so a sorted output does not benefit from additional workers.
[Pathway Io\
\
pw.io.minio](https://pathway.com/developers/api-docs/pathway-io/minio)
[Pathway Io\
\
pw.io.mqtt](https://pathway.com/developers/api-docs/pathway-io/mqtt)
---
# pw.io.postgres | Pathway
pw.io.postgres
==============
Pathway Live Data Framework provides both **Input** and **Output** connectors for PostgreSQL.
The **Input connector** reads changes by consuming diffs from the PostgreSQL Write-Ahead Log (WAL). This allows the framework to ingest changes in a streaming fashion directly from the database replication stream.
The **Output connector** writes a Live Data Framework table into PostgreSQL. It supports two operating modes:
* **Stream of changes mode** which propagates updates as a stream of changes.
* **Snapshot mode** which maintains an exact copy (replica) of the Live Data Framework table in PostgreSQL.
[TLS Support](https://pathway.com/developers/api-docs/pathway-io/postgres#tls-support)
---------------------------------------------------------------------------------------
TLS is supported in both the Input and Output connectors and behaves identically in each case.
TLS configuration is controlled via the `sslmode` and `sslrootcert` parameters passed inside `postgres_settings` for both connectors.
The `sslmode` parameter follows the official PostgreSQL documentation: [sslmode](https://www.postgresql.org/docs/current/libpq-ssl.html#LIBPQ-SSL-PROTECTION)
. It defines the level of TLS verification performed during connection establishment.
If no TLS-related parameters are provided, the connector defaults to `sslmode="prefer"`. In this mode, the system first attempts to establish a TLS-encrypted connection and falls back to an unencrypted connection if TLS negotiation fails.
[TCP Keepalives](https://pathway.com/developers/api-docs/pathway-io/postgres#tcp-keepalives)
---------------------------------------------------------------------------------------------
Pathway Live Data Framework sets conservative TCP-keepalive parameters on every PostgreSQL connection it opens, so that a stalled or terminated Live Data Framework process is detected by PostgreSQL within minutes rather than the OS-inherited default (≈ 2 hours on Linux). This matters most for the streaming reader: while PostgreSQL still believes the client is alive, it keeps the temporary replication slot active and pins write-ahead log retention on disk.
The defaults apply uniformly across every connection the framework opens — both for snapshot reads/writes and for the streaming WAL reader — so a single set of parameter names and units describes the behavior.
### [Framework-managed connection-string defaults](https://pathway.com/developers/api-docs/pathway-io/postgres#framework-managed-connection-string-defaults)
| Parameter | Default | What it does |
| --- | --- | --- |
| `keepalives` | `1` | Master switch — enables TCP keepalive probes on idle connections. Set to `0` to disable keepalives entirely. |
| `keepalives_idle` | `300` | Seconds of idleness before the first keepalive probe is sent. |
| `keepalives_interval` | `30` | Seconds between subsequent probes after the first. |
| `keepalives_count` | `3` | Number of missed probes the kernel tolerates before declaring the connection dead. |
| `tcp_user_timeout` | `300000` | Milliseconds. Kills connections whose unacknowledged data has been outstanding for this long; complements the keepalive trio by covering the case where the connection is actively sending bytes that the peer isn’t acknowledging. |
With these defaults, an idle connection is declared dead at `keepalives_idle + keepalives_interval × keepalives_count` = `300 + 30 × 3` = `390` seconds (≈ 6.5 minutes), and an actively-streaming connection that stops being acknowledged is killed by `tcp_user_timeout` after 5 minutes. The values are deliberately conservative on the “minimize false positives” axis: short-lived network blips (NAT rebinding, brief routing changes, single-AZ failover events) routinely take under a minute to resolve and should not force a reconnect.
Each of these parameters can be overridden by passing the same key in `postgres_settings`. The connector uses `dict.setdefault()` internally, so any value the user provides is preserved verbatim — Pathway never overrides explicit user choices.
**NOTE**: Parameter names and units follow the standard PostgreSQL connection-string conventions documented in the [PostgreSQL connection documentation](https://www.postgresql.org/docs/current/libpq-connect.html)
. `tcp_user_timeout` is given in milliseconds, not seconds.
[Writer Retries on Transient Errors](https://pathway.com/developers/api-docs/pathway-io/postgres#writer-retries-on-transient-errors)
-------------------------------------------------------------------------------------------------------------------------------------
The output connector automatically retries flushes that fail with a transient error — broken connections, server shutdowns, deadlocks, and serialization failures. Retries use exponential backoff and are capped at three attempts; if every attempt fails, the original error is surfaced to the pipeline. Permanent failures (syntax errors, missing tables, constraint violations, type mismatches) are _not_ retried and propagate on the first attempt so they do not waste backoff latency.
Each retry reconnects to PostgreSQL from scratch and replays the same buffered rows, so a transient failure mid-batch does not lose rows: either all rows in the batch are committed or the error reaches the pipeline.
[Passwordless Authentication](https://pathway.com/developers/api-docs/pathway-io/postgres#passwordless-authentication)
-----------------------------------------------------------------------------------------------------------------------
`postgres_settings` does not require `user`, `password`, or `host` to be set. Any of these keys may be omitted, and PostgreSQL’s normal resolution rules then apply: the OS user is used for `user`, `~/.pgpass` is consulted for `password`, and a local UNIX socket is used for `host`. This makes the connector usable with passwordless `pg_hba.conf` modes such as `trust`, `peer`, `ident`, and `cert` without any extra configuration. The server-side `pg_hba.conf` decides whether the resulting connection is authorized.
[Type Conversion (Input Connector)](https://pathway.com/developers/api-docs/pathway-io/postgres#type-conversion-input-connector)
---------------------------------------------------------------------------------------------------------------------------------
The table below describes how PostgreSQL column types are parsed into Pathway Live Data Framework values, and what type to declare in your `pw.Schema` to receive them correctly.
### [PostgreSQL types parsed by the input connector](https://pathway.com/developers/api-docs/pathway-io/postgres#postgresql-types-parsed-by-the-input-connector)
| PostgreSQL type | Pathway schema type and notes |
| --- | --- |
| `BOOLEAN` | `bool` |
| `SMALLINT` / `INT2` | `int` |
| `INTEGER` / `INT4` | `int` |
| `BIGINT` / `INT8` | `int`. Alternatively, declare as `pw.Duration` to interpret the integer value as **microseconds** — use this when the column was written by the framework’s output connector, which serializes `pw.Duration` as a `BIGINT` microsecond count. |
| `REAL` / `FLOAT4` | `float` |
| `DOUBLE PRECISION` / `FLOAT8` | `float` |
| `NUMERIC` / `DECIMAL` | `float` — parsed as `f64`. Precision loss is possible for values with more than ~15 significant digits. Special values `'NaN'`, `'Infinity'`, and `'-Infinity'` (the latter two available in PostgreSQL 14+) round-trip as their IEEE-754 counterparts. |
| `OID` | `int` — the unsigned 32-bit OID is widened to a signed 64-bit integer. |
| `TEXT` / `VARCHAR` / `CHAR` / `NAME` | `str` |
| User-defined `ENUM` | `str` — the raw label as declared in `CREATE TYPE ... AS ENUM (...)`. |
| `UUID` | `str` — formatted as a standard hyphenated lowercase string, e.g. `"a0eebc99-9c0b-4ef8-bb6d-6bb9bd380a11"`. |
| `INET` | `str` — plain host address when the host prefix equals the maximum for its address family (`"192.168.1.1"`); address with prefix otherwise (`"192.168.1.1/28"`). Supports both IPv4 and IPv6. |
| `CIDR` | `str` — always includes the network prefix, e.g. `"192.168.1.0/24"` or `"2001:db8::/32"`. |
| `MACADDR` | `str` — formatted as `"xx:xx:xx:xx:xx:xx"` with lowercase hex digits. |
| `MACADDR8` | `str` — formatted as `"xx:xx:xx:xx:xx:xx:xx:xx"` (EUI-64) with lowercase hex digits. |
| `BYTEA` | `bytes`. Alternatively, declare as `pw.PyObjectWrapper` when the column was written by the framework’s output connector for a `pw.PyObjectWrapper` column — the binary content will be deserialized. |
| `JSON` / `JSONB` | `pw.Json` |
| `TIMESTAMP` | `pw.DateTimeNaive` |
| `TIMESTAMPTZ` | `pw.DateTimeUtc` |
| `DATE` | `pw.DateTimeNaive` — midnight (`00:00:00`) on the given date. |
| `TIME` | `pw.Duration` — microseconds elapsed since midnight. |
| `TIMETZ` | `pw.Duration` — the timezone offset is applied so that the result represents microseconds since **UTC midnight** (e.g. `12:30:00+02:00` becomes `10.5 h` expressed in microseconds). |
| `INTERVAL` | `pw.Duration` — total microseconds: `months × 30 × 86 400 × 10⁶ + days × 86 400 × 10⁶ + microseconds`. Months are approximated as 30 days. |
| `vector` (pgvector extension) | `np.ndarray` — 1-D array of `float64`. |
| `halfvec` (pgvector extension) | `np.ndarray` — 1-D array of `float64`; each `float16` element is promoted to `float64`. |
| `T ARRAY` (any array type) | `list of ` — multi-dimensional arrays are returned as nested `tuple` values. Arrays must be rectangular; `NULL` elements are represented as `None`. The element type follows the scalar mapping for `T` from the rows above. For `int` and `float` element types, declaring `np.ndarray` with the corresponding element type instead produces a typed ndarray; dimensionality is validated against the schema declaration. |
| Any nullable column | Declare the field as nullable. It will be parsed as `None` if the PostgreSQL value is `NULL`; otherwise the value produced by the mapping for type `T`. If the schema field is **not** declared as nullable and a `NULL` is received, an error is raised. |
[Type Conversion (Output Connector)](https://pathway.com/developers/api-docs/pathway-io/postgres#type-conversion-output-connector)
-----------------------------------------------------------------------------------------------------------------------------------
The table below describes how Live Data Framework types map to PostgreSQL types in the output connector. All types can be round-tripped back via the read connector when the original schema type is specified.
### [Live Data Framework types conversion into Postgres](https://pathway.com/developers/api-docs/pathway-io/postgres#live-data-framework-types-conversion-into-postgres)
| Live Data Framework type | Postgres type |
| --- | --- |
| `bool` | `BOOLEAN` |
| `int` | `BIGINT` is the default. `SMALLINT` and `INTEGER` columns are also accepted — the connector casts at flush time and a value that exceeds the destination width surfaces as a Pathway-level error rather than silently wrapping. PostgreSQL’s internal single-byte `"char"` type (the quoted variant, distinct from SQL standard `CHAR(n)` which is a string type) is also accepted on the same path; this is mostly useful for round-tripping rows read from catalog-style columns. |
| `float` | `DOUBLE PRECISION`. If the field type is `REAL`, the connector will also attempt to cast the value accordingly. |
| `pointer` | `TEXT` |
| `str` | `TEXT` is the default type when the framework creates the table. Pre-existing `UUID`, `INET`, `CIDR`, `MACADDR`, and `MACADDR8` columns are also supported — the string is parsed with the same syntax the input connector emits on read, so round-tripping is exact. Malformed values surface as a Pathway-level error at flush time. |
| `bytes` | `BYTEA` |
| `Naive DateTime` | `TIMESTAMP` is the default type when the framework creates the table itself. Pre-existing `DATE` columns are also supported — non-midnight time components are silently truncated, matching PostgreSQL’s own implicit `TIMESTAMP``→``DATE` cast. |
| `UTC DateTime` | `TIMESTAMPTZ` |
| `Duration` | `BIGINT` (microseconds) is the default type the writer emits when it creates the table itself (`init_mode="replace"` / `"create_if_not_exists"`). Pre-existing `INTERVAL` and `TIME` columns are also supported — for `INTERVAL` the writer packs the total microseconds into the binary layout with zero `days` and `months` (so the round-trip through the input connector is exact); for `TIME` the writer emits the raw microseconds-since-midnight. `SMALLINT` and `INTEGER` columns are accepted as well, with the same microsecond encoding — be aware that microseconds overflow a 32-bit signed range after roughly 36 minutes (`INTEGER`) and a 16-bit signed range after about 33 milliseconds (`SMALLINT`), and the cast surfaces as a framework-level error at flush time, so use these narrow widths only when the duration is bounded by construction. |
| `JSON` | `JSONB`. If the field type is `JSON`, the connector will also attempt to cast the value accordingly. |
| `np.ndarray` | ` ARRAY`. The element type is determined by the PostgreSQL column type. Supports multi-dimensional arrays. Arrays must be rectangular. |
| `tuple` (homogeneous) | ` ARRAY`. Supports multi-dimensional arrays. Arrays must be rectangular. |
| `list` (homogeneous) | ` ARRAY`. Supports multi-dimensional arrays. Arrays must be rectangular. |
| `pw.PyObjectWrapper` | `BYTEA` |
### [Array semantics](https://pathway.com/developers/api-docs/pathway-io/postgres#array-semantics)
* Multi-dimensional arrays are supported.
* Arrays must be rectangular (jagged arrays are rejected).
* `NULL` elements inside arrays are supported.
* The PostgreSQL column type determines the element type.
* Only built-in PostgreSQL scalar element types are supported.
[pgvector (Vector Embeddings)](https://pathway.com/developers/api-docs/pathway-io/postgres#pgvector-vector-embeddings)
-----------------------------------------------------------------------------------------------------------------------
Both connectors natively support the [pgvector](https://github.com/pgvector/pgvector)
extension’s vector column types, so embeddings can be streamed into and out of PostgreSQL without any client-side encoding. A pgvector column is exposed to the framework as a one-dimensional `np.ndarray`.
### [pgvector type support](https://pathway.com/developers/api-docs/pathway-io/postgres#pgvector-type-support)
| pgvector type | Live Data Framework type | Direction |
| --- | --- | --- |
| `vector(n)` (single precision, `float32`) | `np.ndarray` — 1-D array of `float64` | read + write |
| `halfvec(n)` (half precision, `float16`) | `np.ndarray` — 1-D array of `float64`; each `float16` element is promoted to `float64` on read | read + write |
On write, a one-dimensional float `np.ndarray` column is serialized straight into the pgvector column over the binary `COPY` protocol. A few requirements apply:
* Enable the extension once per database: `CREATE EXTENSION vector`.
* The destination column must already be declared `vector(n)` / `halfvec(n)`, sized to the embedding dimension `n`. `init_mode` auto-creation maps an `np.ndarray` to a plain PostgreSQL `ARRAY`, **not** to a pgvector type, so the column type has to be created explicitly (manually, or in a table you create yourself).
* Both output modes are supported: `"stream_of_changes"` (every embedding is appended to the index) and `"snapshot"` (the table is kept in sync with the current set of embeddings, keyed by `primary_key`).
**Current support.** The connectors read and write the `vector` / `halfvec` column _values_. Building and maintaining the approximate-nearest-neighbor index (`ivfflat` / `hnsw`) and running similarity queries stay on the PostgreSQL side — create the index and issue KNN searches with ordinary SQL against the table the framework populates. The other pgvector column types (`sparsevec`, `bit`) are not yet supported.
[PostgreSQL-Compatible Databases (NeonDB)](https://pathway.com/developers/api-docs/pathway-io/postgres#postgresql-compatible-databases-neondb)
-----------------------------------------------------------------------------------------------------------------------------------------------
Because these connectors use the standard PostgreSQL wire protocol, they also work — unchanged — with PostgreSQL-compatible databases such as [NeonDB](https://neon.com/)
, a serverless PostgreSQL offering. No NeonDB-specific connector or configuration is needed: point `postgres_settings` at your Neon endpoint and use an SSL-enabled `sslmode` (Neon requires TLS). To stream changes with the input connector, enable logical replication on the Neon project and connect through its direct (non-pooled) endpoint.
See the [NeonDB connector guide](https://pathway.com/developers/user-guide/connect/connectors/neondb-connector)
for step-by-step setup and examples.
[Performance](https://pathway.com/developers/api-docs/pathway-io/postgres#performance)
---------------------------------------------------------------------------------------
The output connector writes over PostgreSQL’s binary `COPY` protocol and is multi-threaded, so the write stream parallelizes across Pathway workers. Combined with the parallelized filesystem reader, the whole read-plus-write pipeline scales with the worker count.
The numbers below come from an end-to-end benchmark — Pathway reading a CSV dataset, doing basic per-row processing, and writing every row to PostgreSQL via binary `COPY` — so they reflect **Pathway + the input source + PostgreSQL together, out of the box**, not PostgreSQL’s standalone ingestion ceiling (which is considerably higher with a tuned configuration).
**Hardware.** A single-socket **AMD Ryzen 9 5900X** (Zen 3, 12 cores / 24 threads, one NUMA node), 125 GiB of RAM, with an **NVMe SSD** backing the PostgreSQL data directory. PostgreSQL ran as the stock `postgres:15` Docker image at its default configuration (`fsync=on`, `synchronous_commit=on`). The Pathway and PostgreSQL containers were each pinned to their own core-complex die (6 cores with a private 32 MiB L3).
**Throughput.** End-to-end wall-clock time to read a 20 M-row, 64-shard CSV dataset (**≈ 0.93 GB**) and land every row in PostgreSQL, swept over the number of Pathway workers (median of 3 runs):
### [PostgreSQL write throughput by worker count](https://pathway.com/developers/api-docs/pathway-io/postgres#postgresql-write-throughput-by-worker-count)
| Pathway workers | End-to-end time | Throughput | Speedup |
| --- | --- | --- | --- |
| 1 | 35.7 s | ≈ 561 000 rows/s | 1.00× |
| 2 | 27.9 s | ≈ 717 000 rows/s | 1.28× |
| 4 | 17.9 s | ≈ 1 115 000 rows/s | 1.99× |
| 8 | 14.4 s | ≈ 1 394 000 rows/s | 2.48× |
Throughput scales with the worker count, peaking at **~1.4 M rows/s** on 8 workers, and every run passed the data-integrity checks. A tuned PostgreSQL configuration would push the ceiling higher still.
For the full methodology, dataset generator, and reproduction steps, see the [Pathway benchmarks repository](https://github.com/pathwaycom/pathway-benchmarks/tree/main/connectors/postgres-bulk-write)
.
[**read**(postgres\_settings, table\_name, schema, \*, mode='streaming', is\_append\_only=False, publication\_name=None, schema\_name='public', autocommit\_duration\_ms=1500, name=None, max\_backlog\_size=None, debug\_data=None)](https://pathway.com/developers/api-docs/pathway-io/postgres#pathway.io.postgres.read)
----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/postgres/__init__.py#L282-L600)
**This module is available when using one of the following licenses only:**[Pathway Live Data Framework Scale, Pathway Live Data Framework Enterprise](https://pathway.com/pricing)
.
Reads a table from a PostgreSQL database.
This connector provides a lightweight alternative to `pw.io.debezium.read`. It supports two modes: `"static"` and `"streaming"`.
In `"static"` mode, the table is read once and the connector stops afterward.
In `"streaming"` mode, a _temporary_ replication slot is created using the `pgoutput` logical decoding plugin, which is bundled with PostgreSQL and requires no additional installation. The slot is created with the `export snapshot` option, ensuring a consistent initial read. On startup, the connector first performs a snapshot of the table as it existed at the moment the replication slot was created, and then begins consuming the PostgreSQL write-ahead log (WAL), applying incremental changes on top of that snapshot. Because the replication slot is temporary, PostgreSQL will automatically drop it once the connection is closed (i.e., when the program terminates).
To enable replication, a publication must be created in the database beforehand:
`CREATE PUBLICATION {publication_name} FOR TABLE {table_name};`
* **Parameters**
* **postgres\_settings** (`dict`) – Connection parameters for PostgreSQL, provided as a dictionary of key-value pairs. The connection string is assembled by joining all pairs with spaces, each formatted as `key=value`. Keys must be strings; values of other types are converted via Python’s `str()`. The Pathway Live Data Framework injects conservative TCP-keepalive defaults (`keepalives`, `keepalives_idle=300`, `keepalives_interval=30`, `keepalives_count=3`, and `tcp_user_timeout=300000`) so that an unreachable the Pathway Live Data Framework process is detected by PostgreSQL within minutes rather than the OS-inherited ~2-hour default; any of these can be overridden by passing the same key in `postgres_settings`.
* **table\_name** (`str`) – Name of the PostgreSQL table to read from. Any PostgreSQL identifier is accepted — the connector quotes the name before interpolating it into generated SQL, so hyphens, mixed case, and reserved words round-trip as-is.
* **schema** (`type`\[[`Schema`](https://pathway.com/developers/api-docs/pathway#pathway.Schema)\
\]) – Pathway Live Data Framework schema describing the table’s columns and their types. Column names may be any PostgreSQL identifier for the same reason as `table_name`.
* **mode** (`Literal`\[`'streaming'`, `'static'`\]) – Polling mode for the connector. Accepted values are `"streaming"` (default) and `"static"`. In `"streaming"` mode, the connector tracks changes in the table via the WAL, reflecting insertions, updates, deletions, and truncations in real time; requires `publication_name` to be specified. In `"static"` mode, the connector reads all currently available rows in a single commit and then stops.
* **is\_append\_only** (`bool`) – Used in streaming mode. Specifies whether the input table is append-only. If the table is not append-only, it must have a primary key, and all primary key columns must be declared as such in the schema. This is required because when reading diffs from the log, update and delete records only expose the primary key columns of the affected rows. If the table is declared as append-only but a deletion, truncation or modification is encountered, an error is raised.
* **publication\_name** (`str` | `None`) – Name of the PostgreSQL publication that covers the target table. Required when `mode="streaming"`.
* **schema\_name** (`str` | `None`) – Name of the PostgreSQL schema in which the table resides. Defaults to `"public"`; only needs to be changed when using a non-default schema.
* **autocommit\_duration\_ms** (`int` | `None`) – the maximum time between two commits. Every `autocommit_duration_ms` milliseconds, the updates received by the connector are committed and pushed into Pathway Live Data Framework’s computation graph.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. Additionally, if persistence is enabled, it will be used as the name for the snapshot that stores the connector’s progress. It is also surfaced to PostgreSQL as part of the connection’s `application_name` (`pathway:`), so operators can filter `pg_stat_activity` and server logs by connector.
* **max\_backlog\_size** (`int` | `None`) – Limit on the number of entries read from the input source and kept in processing at any moment. Reading pauses when the limit is reached and resumes as processing of some entries completes. Useful with large sources that emit an initial burst of data to avoid memory spikes.
* **debug\_data** (`Any`) – Static data replacing original one when debug mode is active.
* **Returns**
_Table_ – The table read.
Example:
Suppose you have a `users` table with the following columns: `id` (an auto-incremented integer serving as the primary key), `login` (a string), and `last_seen_at` (a unix timestamp). To read this table with the Pathway Live Data Framework, start by declaring the corresponding schema:
`import pathway as pw class UsersSchema(pw.Schema): id: int = pw.column_definition(primary_key=True) login: str last_seen_at: int`
To perform a one-time read of the table, no additional database configuration is required. Simply provide the connection parameters and use `"static"` mode:
`connection_string_parts = { "host": "localhost", "port": "5432", "dbname": "database", "user": "user", "password": "pass", }`
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="users", schema=UsersSchema, mode="static", )`
The resulting `table` object supports all Pathway Live Data Framework transformations and can be passed to any output connector for further processing or storage.
To go beyond a one-time snapshot and perform Change Data Capture (CDC), continuously tracking insertions, updates, deletions, and truncations as they happen, you need to switch to `"streaming"` mode. This requires the PostgreSQL server to have logical replication enabled (`wal_level = logical`) and a publication to be created for the target table:
`CREATE PUBLICATION users_pub FOR TABLE users;`
With the publication in place, the streaming connector can be configured as follows:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="users", schema=UsersSchema, mode="streaming", publication_name="users_pub", )`
There is no need to create a replication slot manually, and doing so is strongly discouraged. A replication slot causes PostgreSQL to retain WAL segments until all changes have been acknowledged by the consumer. If a slot is created but its LSN position is not advanced regularly, unacknowledged WAL can accumulate and eventually exhaust disk space on the database server. To prevent this, the Pathway Live Data Framework manages the replication slot internally: it uses a temporary slot that is automatically dropped when the session ends, and continuously acknowledges processed LSN positions while the program is running.
The examples above use an integer primary key, but other primary key types are supported as well.
Suppose you have a `products` table where each row is identified by a string product code such as `"SKU-001"`, alongside a `name` column and a `price` column. The schema in this case is:
`class ProductsSchema(pw.Schema): sku: str = pw.column_definition(primary_key=True) name: str price: float`
Both `"static"` and `"streaming"` modes are supported, set up in exactly the same way as for an integer primary key. For a one-time snapshot:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="products", schema=ProductsSchema, mode="static", )`
For continuous CDC, create a publication first:
`CREATE PUBLICATION products_pub FOR TABLE products;`
Then configure the streaming connector:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="products", schema=ProductsSchema, mode="streaming", publication_name="products_pub", )`
PostgreSQL’s `UUID` type is also supported. Because Pathway Live Data Framework represents UUID values as strings, the corresponding schema field must be declared as `str`. Suppose you have a `messages` table whose primary key is a UUID column `id`, alongside a string `body` column:
`class MessagesSchema(pw.Schema): id: str = pw.column_definition(primary_key=True) body: str`
The Pathway Live Data Framework will read the UUID values as standard hyphenated strings, for example `"a0eebc99-9c0b-4ef8-bb6d-6bb9bd380a11"`. Both modes are supported. For a one-time snapshot:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="messages", schema=MessagesSchema, mode="static", )`
For continuous CDC, create a publication first:
`CREATE PUBLICATION messages_pub FOR TABLE messages;`
Then configure the streaming connector:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="messages", schema=MessagesSchema, mode="streaming", publication_name="messages_pub", )`
Tables with composite primary keys — where the primary key spans multiple columns — are supported as well. To declare a composite primary key in the Pathway Live Data Framework, mark every participating column with `pw.column_definition(primary_key=True)`. Suppose you have an `order_items` table where each row is uniquely identified by the combination of `order_id` and `product_id`, both integers, alongside a `quantity` column:
`class OrderItemsSchema(pw.Schema): order_id: int = pw.column_definition(primary_key=True) product_id: int = pw.column_definition(primary_key=True) quantity: int`
Both `order_id` and `product_id` are marked as primary key columns, matching the `PRIMARY KEY (order_id, product_id)` constraint on the PostgreSQL side. In streaming mode, this is especially important: when an update or delete event arrives in the WAL, PostgreSQL only exposes the primary key columns of the affected row, so all primary key columns must be declared as such in the schema.
Both modes are supported. For a one-time snapshot:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="order_items", schema=OrderItemsSchema, mode="static", )`
For continuous CDC, create a publication first:
`CREATE PUBLICATION order_items_pub FOR TABLE order_items;`
Then configure the streaming connector:
`table = pw.io.postgres.read( postgres_settings=connection_string_parts, table_name="order_items", schema=OrderItemsSchema, mode="streaming", publication_name="order_items_pub", )`
[**write**(table, postgres\_settings, table\_name, \*, schema\_name='public', max\_batch\_size=None, init\_mode='default', output\_table\_type='stream\_of\_changes', primary\_key=None, name=None, sort\_by=None, )](https://pathway.com/developers/api-docs/pathway-io/postgres#pathway.io.postgres.write)
-------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/postgres/__init__.py#L603-L964)
Writes `table` to a Postgres table. Two types of output tables are supported: **stream of changes** and **snapshot**.
When using **stream of changes**, the output table contains a log of all changes that occurred in the Pathway Live Data Framework table. In this case, it is expected to have two additional columns, `time` and `diff`, both of integer type. `time` indicates the transactional minibatch time in which the row change occurred. `diff` can be either `1` for row insertion or `-1` for row deletion.
When using **snapshot**, the set of columns in the output table matches the set of columns in the table you are writing. No additional columns are created.
* **Parameters**
* **table** ([`Table`](https://pathway.com/developers/api-docs/pathway-table#pathway.Table)
) – Table to be written.
* **postgres\_settings** (`dict`) – Components for the connection string for Postgres. The string is formed by joining key-value pairs from the given dictionary with spaces, with each pair formatted as key=value. Keys must be strings. Values can be of any type; if a value is not a string, it will be converted using Python’s str() function. The Pathway Live Data Framework injects conservative TCP-keepalive defaults (`keepalives`, `keepalives_idle=300`, `keepalives_interval=30`, `keepalives_count=3`, and `tcp_user_timeout=300000`) so that an unreachable the Pathway Live Data Framework process is detected by PostgreSQL within minutes rather than the OS-inherited ~2-hour default; any of these can be overridden by passing the same key in `postgres_settings`.
* **table\_name** (`str`) – Name of the target table. Any PostgreSQL identifier is accepted — the connector quotes the name before interpolating it into generated SQL, so hyphens, mixed case, and reserved words round-trip as-is. Column names in `table` and in `primary_key` are quoted the same way.
* **schema\_name** (`str` | `None`) – Name of the PostgreSQL schema that owns the target table. Defaults to `"public"`. Set this when writing to a non-default schema; the name is quoted identically to `table_name`.
* **max\_batch\_size** (`int` | `None`) – Maximum number of entries allowed to be committed within a single transaction.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – “default”: The default initialization mode; “create\_if\_not\_exists”: initializes the SQL writer by creating the necessary table if they do not already exist; “replace”: Initializes the SQL writer by replacing any existing table.
* **output\_table\_type** (`Literal`\[`'stream_of_changes'`, `'snapshot'`\]) – Defines how the output table manages its data. If set to `"stream_of_changes"` (the default), the system outputs a stream of modifications to the target table. This stream includes two additional integer columns: `time`, representing the computation minibatch, and `diff`, indicating the type of change (`1` for row addition and `-1` for row deletion). If set to `"snapshot"`, the table maintains the current state of the data, updated atomically with each minibatch and ensuring that no partial minibatch updates are visible.
* **primary\_key** (`list`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\] | `None`) – When using snapshot mode, one or more columns that form the primary key in the target Postgres table.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards. It is also surfaced to PostgreSQL as part of the connection’s `application_name` (`pathway:`), so operators can filter `pg_stat_activity` and server logs by connector.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
Consider there’s a need to output a stream of updates from a table in the Pathway Live Data Framework to a table in Postgres. Let’s see how this can be done with the connector.
First of all, one needs to provide the required credentials for Postgres [connection string](https://www.postgresql.org/docs/current/libpq-connect.html)
. While the connection string can include a wide variety of settings, such as SSL or connection timeouts, in this example we will keep it simple and provide the smallest example possible. Suppose that the database is running locally on the standard port 5432, that it has the name `database` and is accessible under the username `user` with a password `pass`.
It gives us the following content for the connection string:
`connection_string_parts = { "host": "localhost", "port": "5432", "dbname": "database", "user": "user", "password": "pass", }`
Now let’s load a table, which we will output to the database:
`import pathway as pw t = pw.debug.table_from_markdown("age owner pet \n 1 10 Alice 1 \n 2 9 Bob 1 \n 3 8 Alice 2")`
In order to output the table, we will need to create a new table in the database. The table would need to have all the columns that the output data has. Moreover it will need a `time` column of type `BIGINT` (Pathway Live Data Framework timestamps are milliseconds since epoch and routinely exceed the 32-bit range) and a `diff` column of type `SMALLINT`. Finally, it is also a good idea to create the sequential primary key for our changes so that we know the updates’ order.
To sum things up, the table creation boils down to the following SQL command:
`CREATE TABLE pets ( id SERIAL PRIMARY KEY, time BIGINT NOT NULL, diff SMALLINT NOT NULL, age BIGINT, owner TEXT, pet TEXT );`
Now, having done all the preparation, one can simply call:
`pw.io.postgres.write( t, connection_string_parts, "pets", )`
Consider another scenario: the `pets` table is updated and you need to keep only the latest record for each pet, identified by the `pet` field in this table. In this case, you need the output table type to be `"snapshot"`. The table can be created automatically in the database if you set `init_mode` to `"replace"` or `"create_if_not_exists"`. If you create it manually, the command can look like this:
`CREATE TABLE pets ( pet TEXT PRIMARY KEY, age INTEGER, owner TEXT );`
The primary key in the target table is the `pet` field. Therefore, the `primary_key` parameter for the command should be `[t.pet]`. You can write this table as follows:
`pw.io.postgres.write( t, connection_string_parts, "pets", output_table_type="snapshot", primary_key=[t.pet], )`
**Indexing vectors with pgvector.** Columns holding one-dimensional float arrays (`np.ndarray`) are written natively into [pgvector](https://github.com/pgvector/pgvector)
columns: declare the destination column as `vector(n)` (single precision) or `halfvec(n)` (half precision), sized to the embedding dimension `n`, and the array is serialized straight into it over the binary `COPY` protocol. The `vector` extension must be enabled (`CREATE EXTENSION vector`) and the column must already have the pgvector type — `init_mode` auto-creation maps an `np.ndarray` to a plain PostgreSQL `ARRAY`, not to a pgvector type, so create the column yourself.
Suppose you embed incoming documents and store the embeddings in a pgvector-backed table to serve similarity search. The embeddings are produced as:
`import numpy as np documents = pw.debug.table_from_markdown( ''' doc_id 1 2 3 ''' ) @pw.udf def embed(doc_id: int) -> np.ndarray: return np.ones(3) * doc_id embeddings = documents.select(pw.this.doc_id, vector=embed(pw.this.doc_id))`
When the collection is **append-only** — embeddings are only ever added — use `"stream_of_changes"` so every new vector is appended to the index. The destination table carries the embedding column plus the `time` / `diff` bookkeeping columns:
`CREATE EXTENSION IF NOT EXISTS vector; CREATE TABLE document_embeddings ( doc_id BIGINT, vector VECTOR(3), time BIGINT NOT NULL, diff SMALLINT NOT NULL );`
`pw.io.postgres.write( embeddings, connection_string_parts, "document_embeddings", )`
When documents come and go — a document leaving the collection must drop its vector from the index, and a re-embedded document must replace it — use `"snapshot"` keyed by the document id, so the table always mirrors the current set of embeddings (no `time` / `diff` columns are added):
`CREATE EXTENSION IF NOT EXISTS vector; CREATE TABLE document_index ( doc_id BIGINT PRIMARY KEY, vector VECTOR(3) );`
`pw.io.postgres.write( embeddings, connection_string_parts, "document_index", output_table_type="snapshot", primary_key=[embeddings.doc_id], )`
[**write\_snapshot**(table, postgres\_settings, table\_name, primary\_key, \*, max\_batch\_size=None, init\_mode='default', name=None, sort\_by=None, )](https://pathway.com/developers/api-docs/pathway-io/postgres#pathway.io.postgres.write_snapshot)
---------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------
[source](https://github.com/pathwaycom/pathway/tree/main/python/pathway/io/postgres/__init__.py#L967-L1122)
**WARNING**: This method is deprecated. Please use `pw.io.postgres.write` with the parameter `output_table_type="snapshot"` instead. Note that the new version does not create the `time` and `diff` columns and maintains a current snapshot of the table you are writing.
Maintains a snapshot of a table within a Postgres table.
In order for write to be successful, it is required that the table contains `time` and `diff` columns of the integer type.
* **Parameters**
* **postgres\_settings** (`dict`) – Components of the connection string for Postgres.
* **table\_name** (`str`) – Name of the target table.
* **primary\_key** (`list`\[`str`\]) – Names of the fields which serve as a primary key in the Postgres table.
* **max\_batch\_size** (`int` | `None`) – Maximum number of entries allowed to be committed within a single transaction.
* **init\_mode** (`Literal`\[`'default'`, `'create_if_not_exists'`, `'replace'`\]) – “default”: The default initialization mode; “create\_if\_not\_exists”: initializes the SQL writer by creating the necessary table if they do not already exist; “replace”: Initializes the SQL writer by replacing any existing table.
* **name** (`str` | `None`) – A unique name for the connector. If provided, this name will be used in logs and monitoring dashboards.
* **sort\_by** (`Optional`\[`Iterable`\[[`ColumnReference`](https://pathway.com/developers/api-docs/pathway#pathway.ColumnReference)\
\]\]) – If specified, the output will be sorted in ascending order based on the values of the given columns within each minibatch. When multiple columns are provided, the corresponding value tuples will be compared lexicographically.
* **Returns**
None
Example:
Consider there is a table `stats` in the Pathway Live Data Framework, containing the average number of requests to some service or operation per user, over some period of time. The number of requests can be large, so we decide not to store the whole stream of changes, but to only store a snapshot of the data, which can be actualized by the Pathway Live Data Framework.
The minimum set-up would require us to have a Postgres table with two columns: the ID of the user `user_id` and the number of requests across some period of time `number_of_requests`. In order to maintain consistency, we also need two extra columns: `time` and `diff`.
The SQL for the creation of such table would look as follows:
`CREATE TABLE user_stats ( user_id TEXT PRIMARY KEY, number_of_requests BIGINT, time BIGINT NOT NULL, diff SMALLINT NOT NULL );`
After the table is created, all you need is just to set up the output connector:
`import pathway as pw pw.io.postgres.write_snapshot( stats, { "host": "localhost", "port": "5432", "dbname": "database", "user": "user", "password": "pass", }, "user_stats", ["user_id"], )`
[Pathway Io\
\
pw.io.plaintext](https://pathway.com/developers/api-docs/pathway-io/plaintext)
[Pathway Io\
\
pw.io.pubsub](https://pathway.com/developers/api-docs/pathway-io/pubsub)
---